OpenMOSS Releases MOSS-Image Under Apache 2.0
The academic team behind the MOSS project moves into text-to-image generation with a permissively licensed model and a fine-tuned SFT variant.
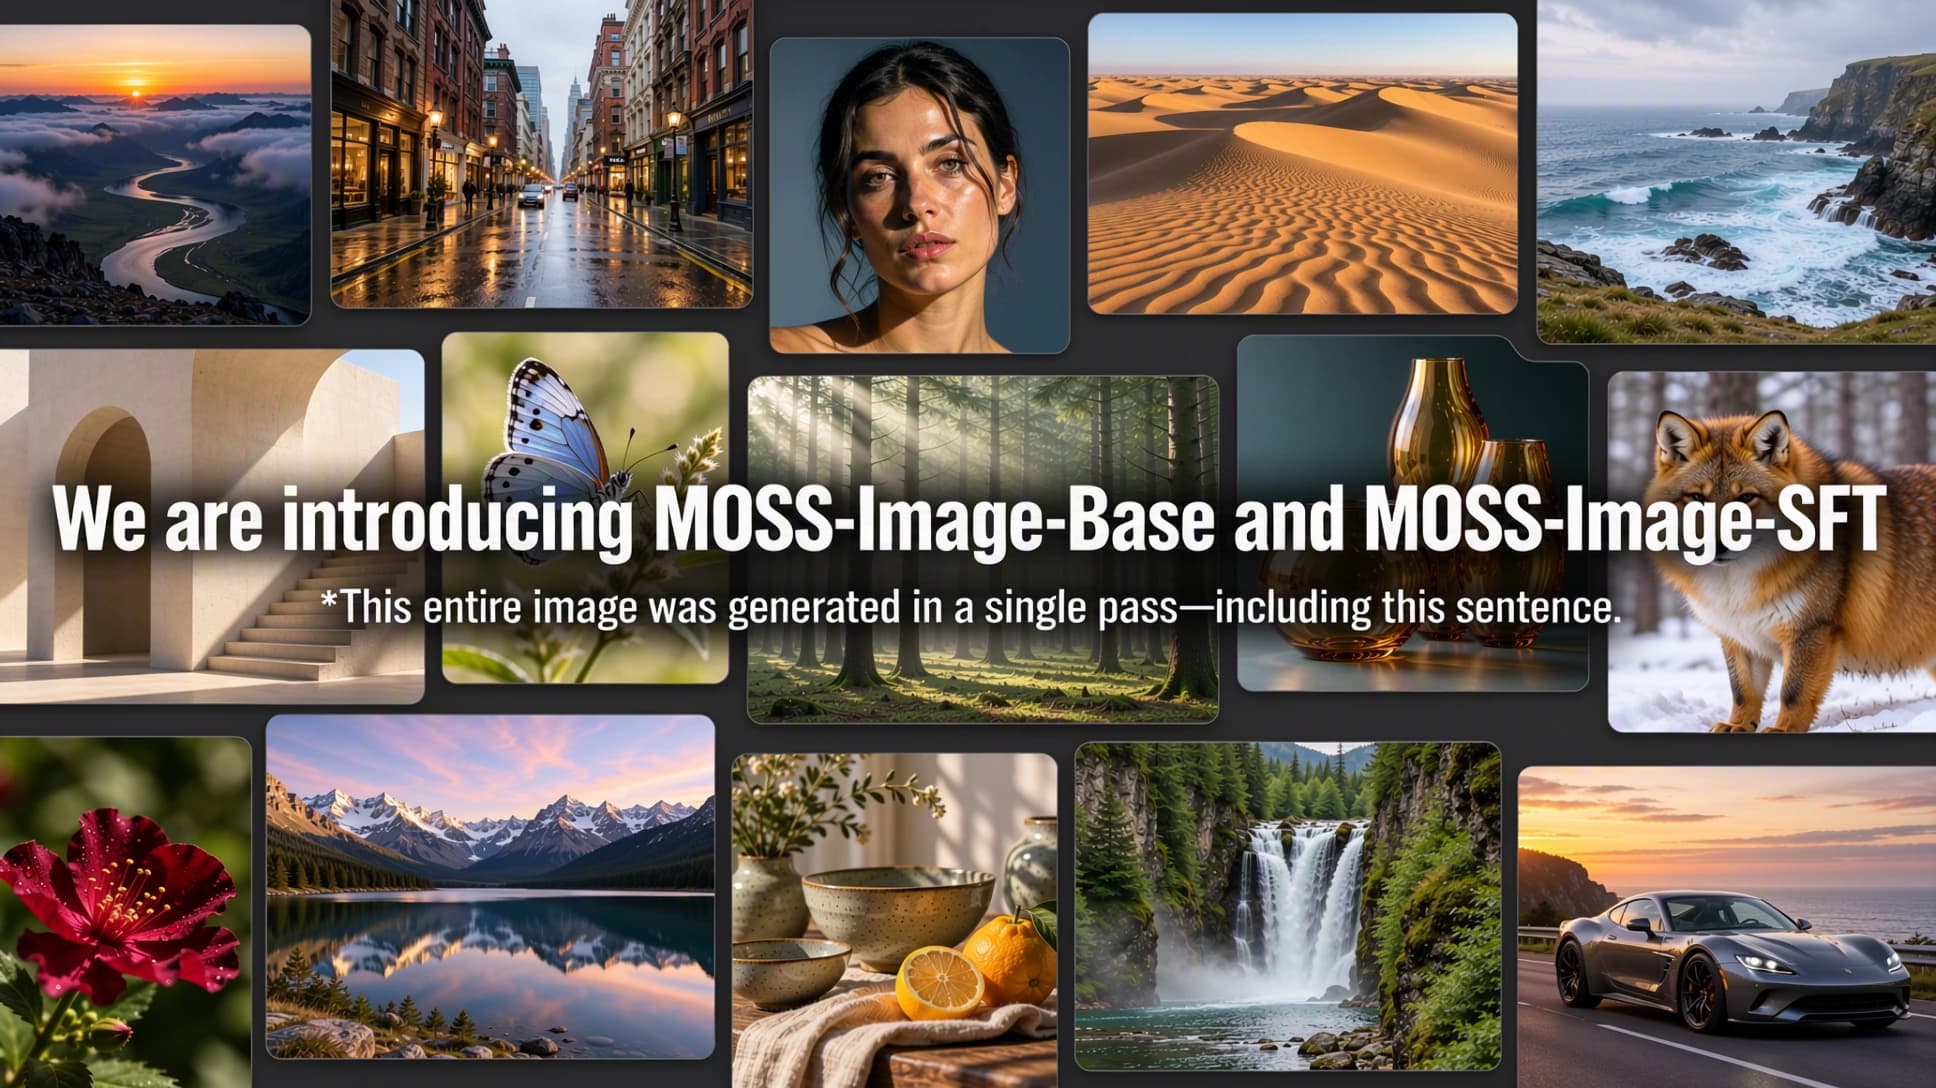
OpenMOSS has released MOSS-Image, a text-to-image model distributed under the permissive Apache 2.0 license. The release includes a base model alongside a supervised fine-tuned (SFT) variant, now available on Hugging Face.
The SFT edition is the instruction-tuned flavor of the family, typically trained to follow prompts more faithfully and produce cleaner outputs than a raw base checkpoint. Pairing a base model with a fine-tuned version gives researchers a starting point for their own experiments while offering a more usable artifact out of the box.
Why it matters
OpenMOSS is best known for its earlier conversational MOSS work, so a move into image generation marks a notable expansion of scope. The choice of Apache 2.0 is significant for adopters:
- Commercial use is permitted without restrictive clauses
- Weights can be redistributed and built upon freely
- No separate research-only carve-outs to navigate
That licensing posture sets MOSS-Image apart from many image models that ship with custom or non-commercial terms. For teams evaluating open text-to-image options, the release adds another genuinely permissive candidate to the mix. Full details, including intended usage and any benchmark results, are on the model's Hugging Face page.
Sources
- Visit
OpenMOSS-Team/MOSS-Image-SFT
Hugging Face
More from OpenMOSS
All OpenMOSS releases →
OpenMOSS Releases Apache-2.0 Bilingual Image Model
MOSS-Image Base arrives as a permissively licensed text-to-image foundation with English and Chinese support.
OpenMOSS Debuts MOSS-VL for Real-Time Vision Interaction
A new open vision-language model family uses gated cross-attention to enable streaming, low-latency multimodal exchanges.
MameLoshnLM Brings Yiddish Into the Open LLM Era
OpenMOSS releases what it calls the first open-source 8B language model built specifically for Yiddish, paired with an evaluation benchmark.
More in Text → Image
All Text → Image →
Black Forest Labs ships FLUX.3 Image Klein
The latest open image model from the FLUX team handles both text-to-image generation and editing, and arrives ready to run in Diffusers.
Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.
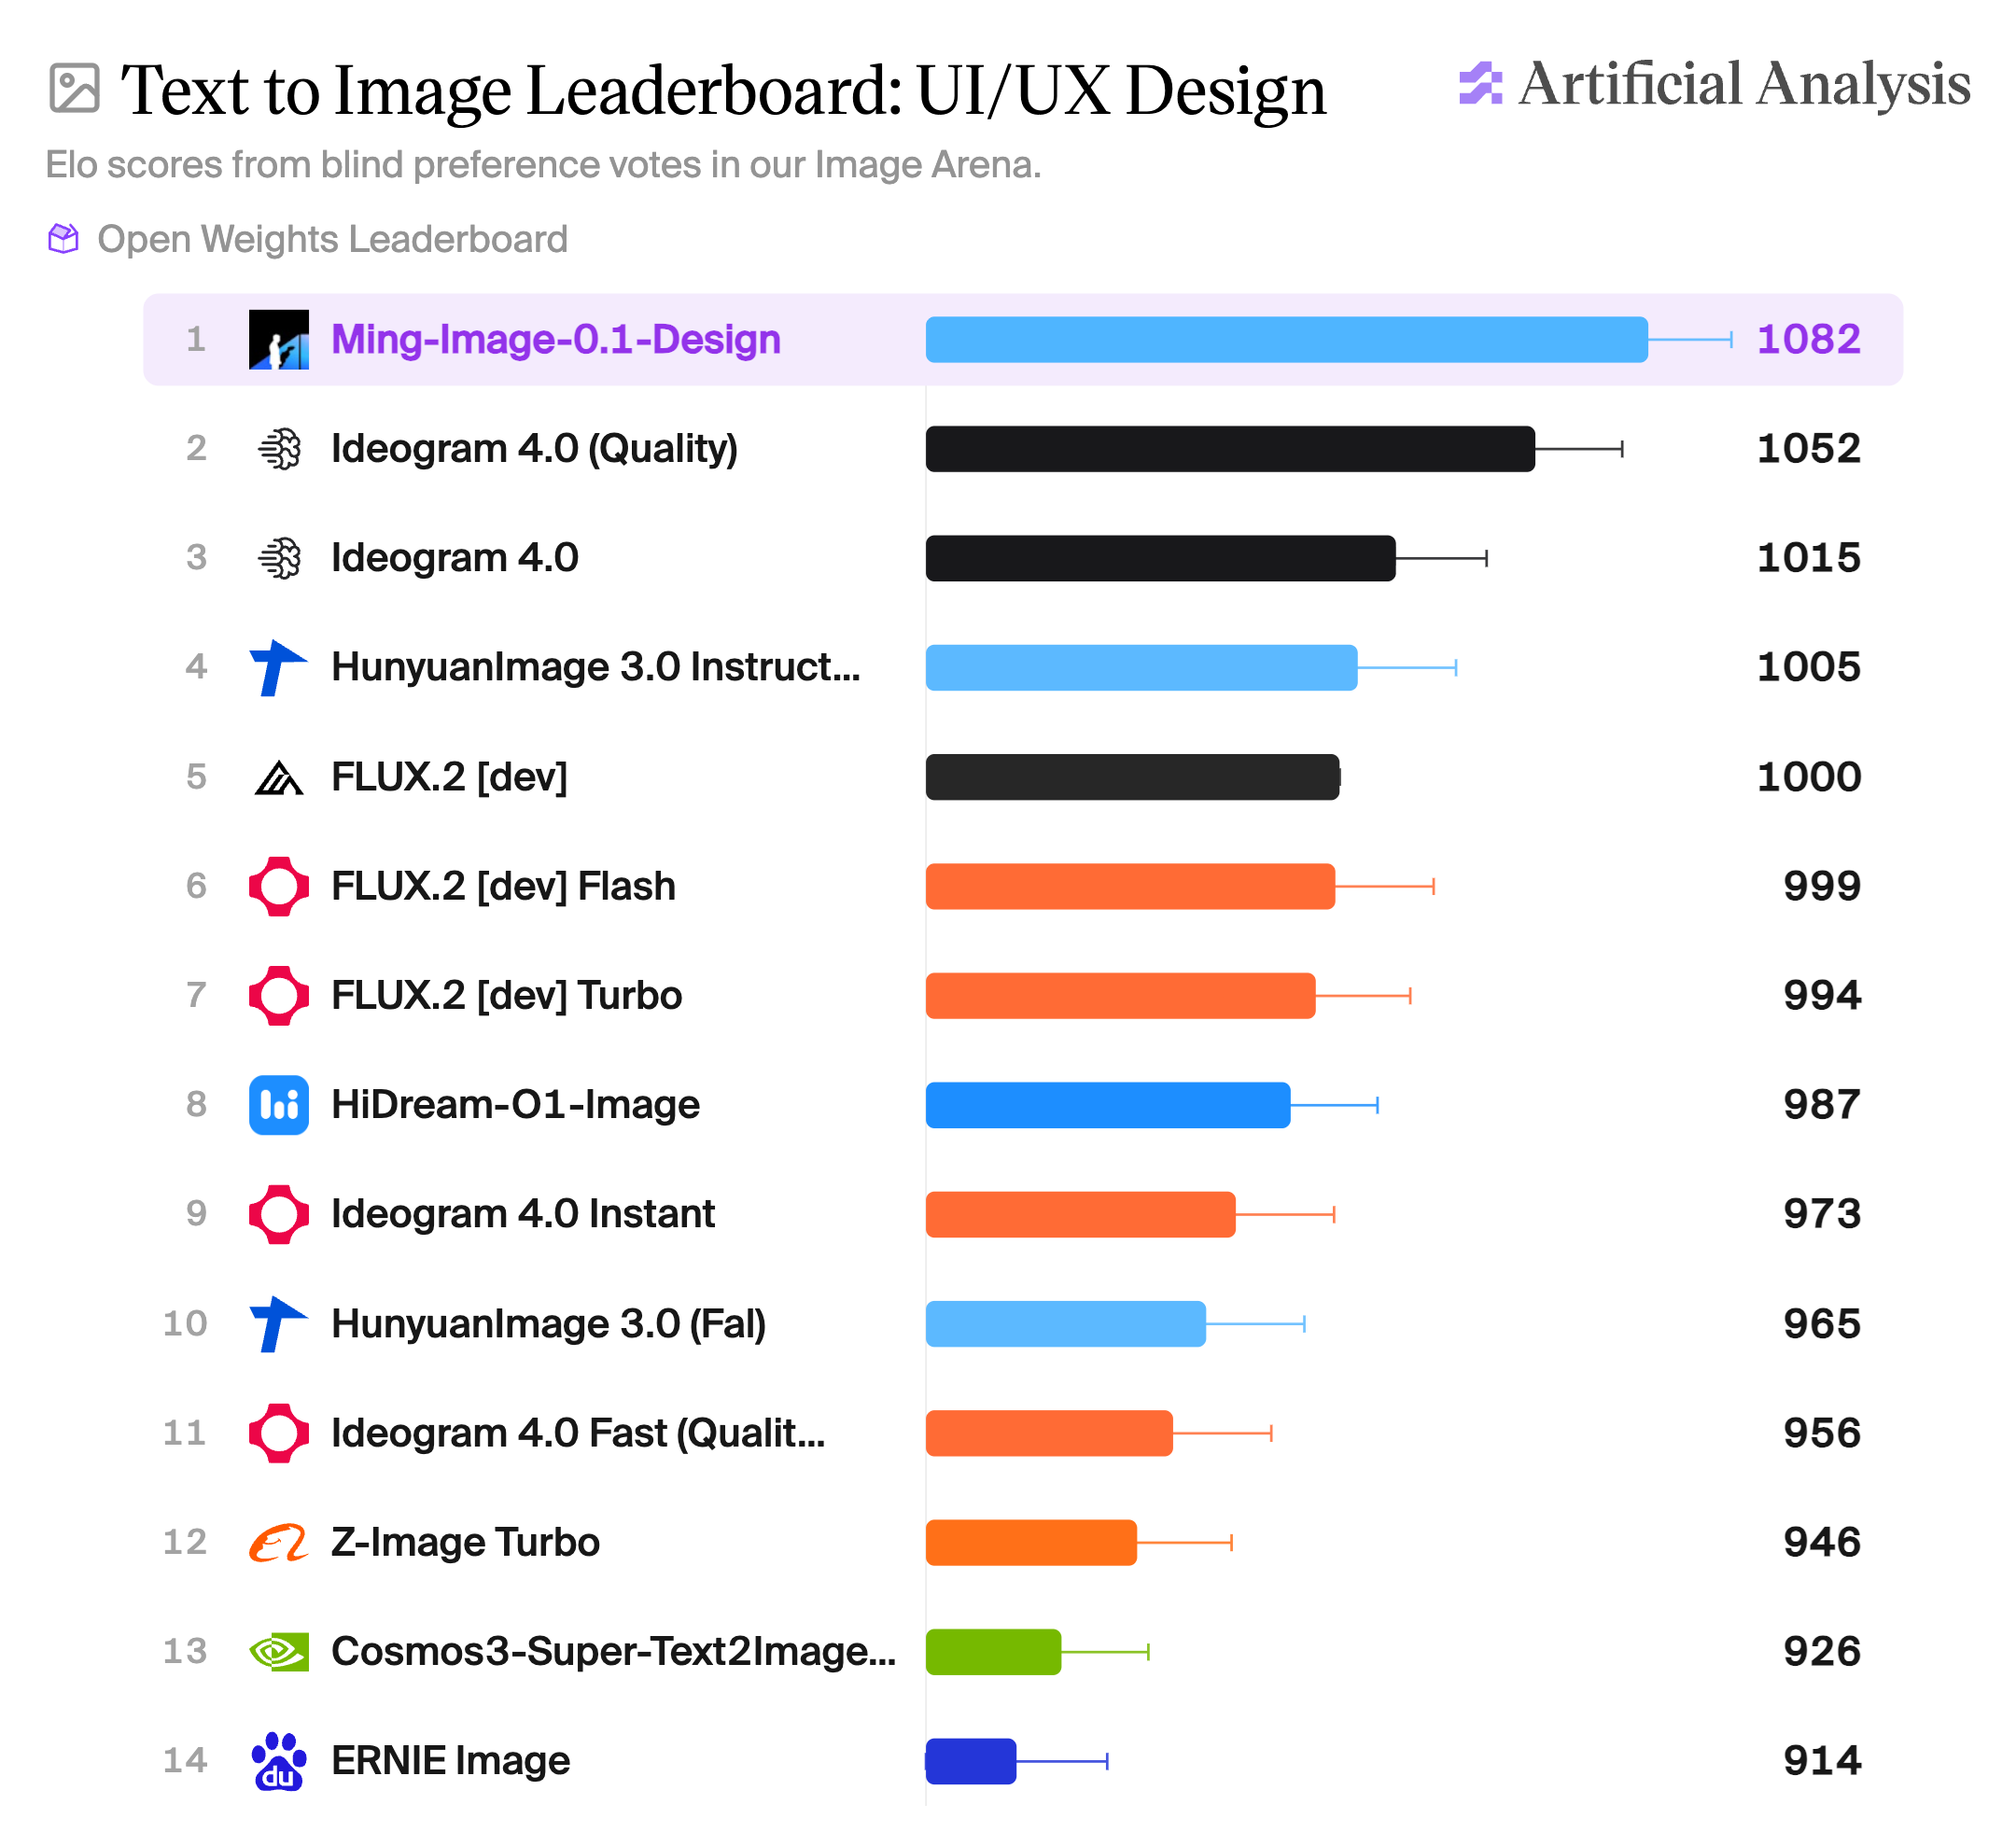
inclusionAI's Ming-Image targets graphic design
A new MIT-licensed text-to-image model leans into legible text rendering and transparent RGBA output for design work.
0 comments
No comments yet. Be the first to weigh in.