The Open Weights
LatestModelsLeaderboardsCompanies
Subscribe
The Open Weights

The daily record of open-source AI. New model releases, leaderboards, and what's coming next — written for people who ship.

Refreshed every 12 hours

Discover

  • Latest releases
  • New today
  • Trending models

Browse

  • All models
  • Companies
  • Categories
  • Leaderboards

About

  • About
  • Editorial policy
  • Hardware estimates
  • RSS feed
  • llms.txt
  • Newsletter

© 2026 The Open Weights. An independent publication.

PrivacyTermsSMSAggregated by Claude · curated by humans.
T

Company

Tencent

21 models
CategoriesText → VideoText / LLMVision-LanguageReasoningEmbeddingsText → SpeechImage EditingImage → VideoText → Image

Releases

Tencent/Text → Video

Tencent Releases Hy-Nomas, an Interactive Video World Model

The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.

Oct 21, 2026
Text → VideoImage → Video
Hy-Nomas
Tencent/Text / LLMConsumer GPU

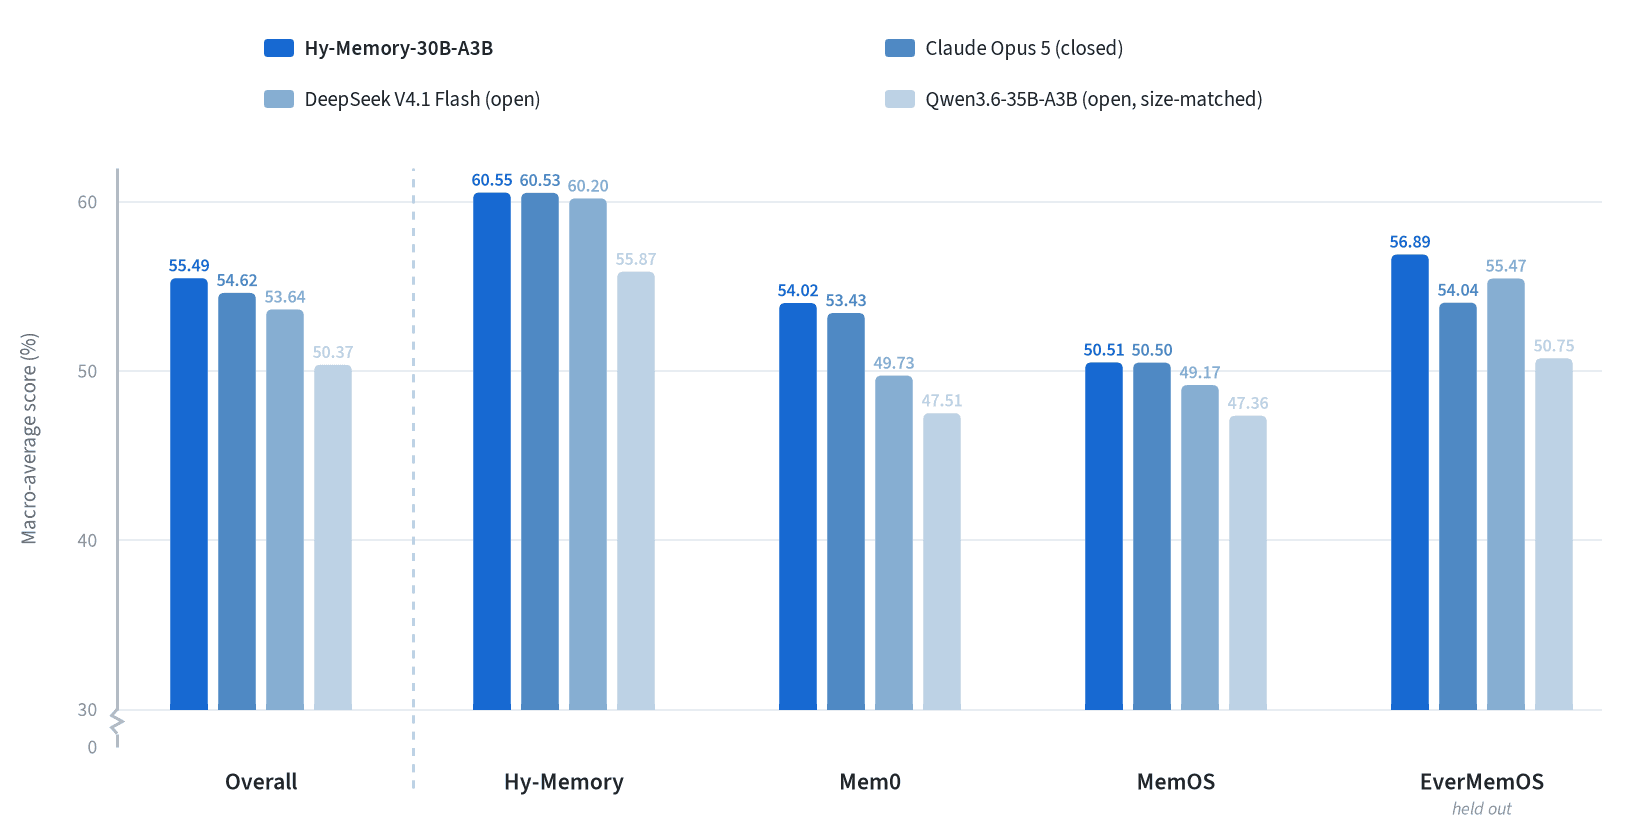
Tencent releases Hy-Memory 30B-A3B under Apache 2.0

A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.

Oct 15, 2026
Text / LLM
Hy-Memory 30B-A3B
Tencent/Vision-LanguageRuns on a laptop

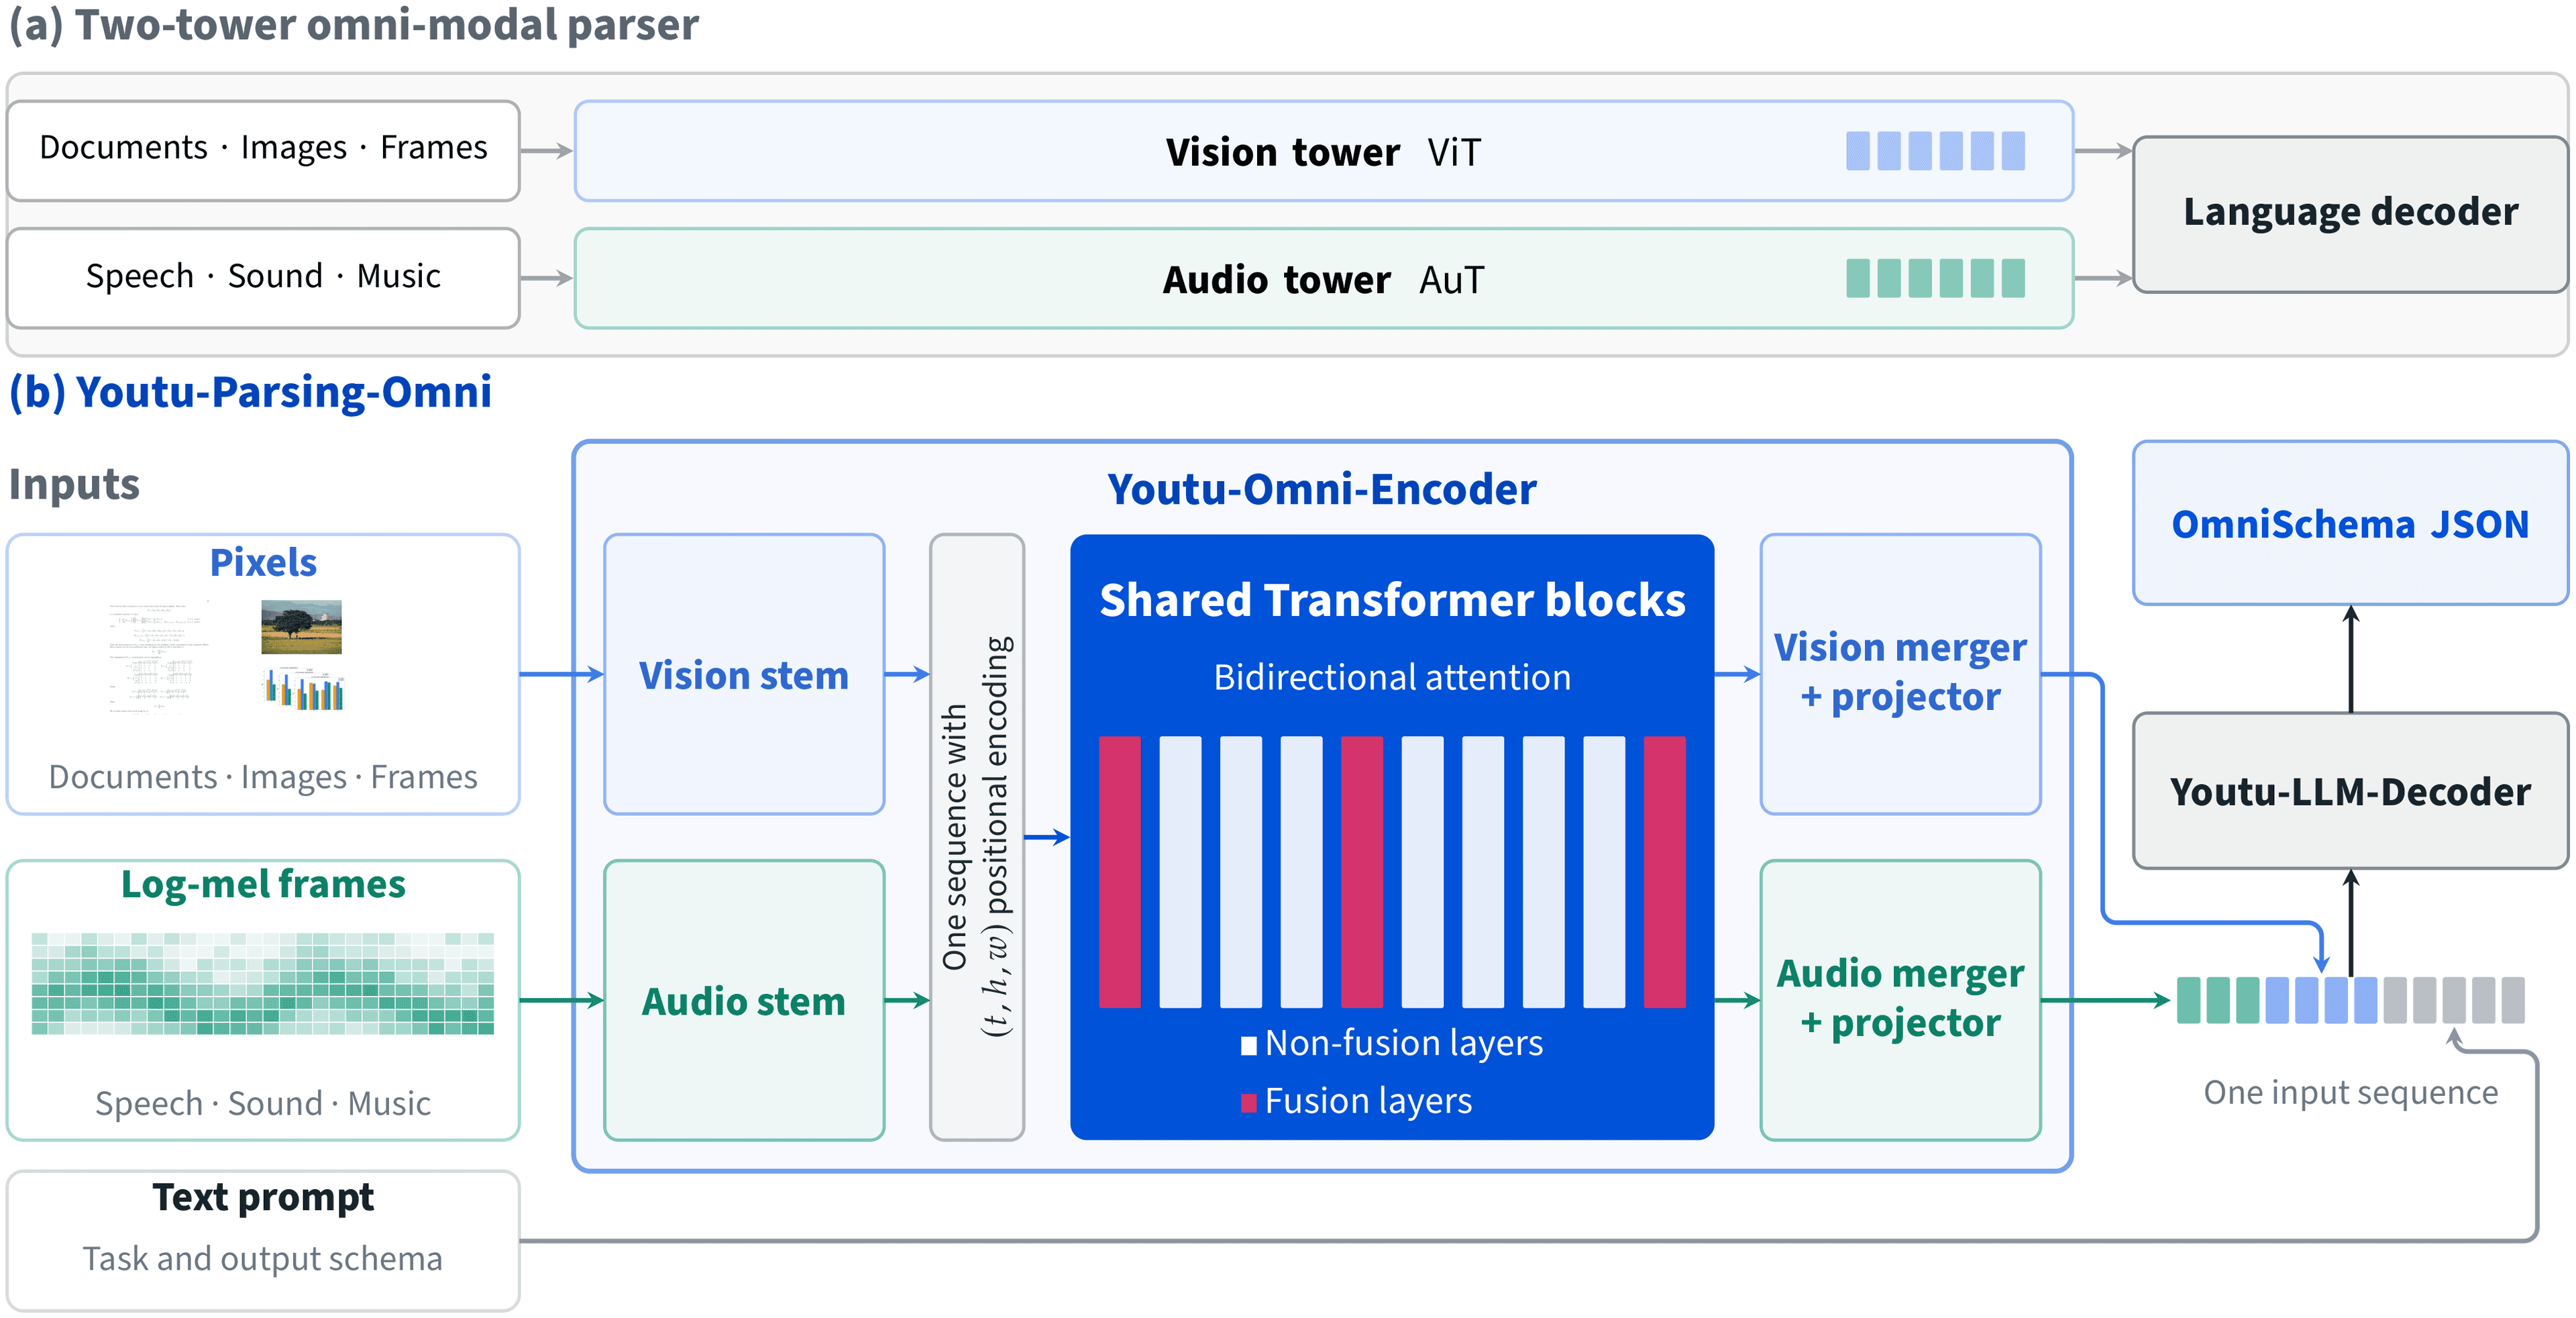
Tencent's Youtu-Parsing-Omni tackles docs, audio, video

A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.

Oct 9, 2026
Vision-LanguageAny-to-Any
Youtu-Parsing-Omni
Tencent/ReasoningWorkstation GPU

Tencent's T1 Targets Long-Horizon Terminal Work

A 122B mixture-of-experts model trained with reinforcement learning claims state-of-the-art results on Terminal-Bench.

Sep 9, 2026
ReasoningCode
Tencent/Text / LLMDatacenter

Tencent Previews Hunyuan Hy4, an Apache MoE Model

The company's next-generation Hunyuan language model arrives as an early preview with a permissive license and a mixture-of-experts design.

Aug 27, 2026
Text / LLMReasoning
Hunyuan Hy4 (preview)
Tencent/EmbeddingsRuns on a laptop

Tencent's WeMM-Embedding-9B Unifies Text, Image and Video

The WeChat team releases a 9-billion-parameter multimodal embedding model that maps three modalities into one shared vector space.

Aug 25, 2026
EmbeddingsVision-Language
WeMM
Tencent/Text → Speech

Tencent's AuK Bundles Voice Cloning and Speech Editing

The new open-weights model handles zero-shot TTS alongside enhancement and separation, aiming to be a broad speech toolkit rather than a single-purpose voice engine.

Aug 18, 2026
Text → Speech
AuK
Tencent/Vision-LanguageConsumer GPU

Tencent's UI-Mate-27B targets desktop automation

A 27B vision-language model built to see and operate graphical interfaces, tested on OSWorld and WindowsAgentArena.

Aug 14, 2026
Vision-Language
UI-Mate-27B
Tencent/Text / LLMMulti-GPU server

Tencent releases Hunyuan Hy3 under Apache 2.0

The company's latest mixture-of-experts model arrives as an openly licensed conversational LLM on Hugging Face.

Jul 2, 2026
Text / LLM
Hunyuan Hy3
Tencent/Image EditingRuns anywhere

Tencent's Moebius packs inpainting into 0.2B params

A lightweight image-editing framework claims results rivaling 10B-scale models, and it's already running in the browser.

Jun 22, 2026
Image Editing
Tencent/Text / LLMRuns anywhere

Tencent Releases 1.8B Model for Multilingual Translation

The 1.8 billion-parameter model from the Chinese tech giant is designed for high-quality translation across a wide range of language pairs.

May 11, 2026
Text / LLM
Hunyuan-MT2 1.8B
Tencent/Vision-LanguageRuns anywhere

Tencent Releases 2B Vision Model for Robotics

The new HY-Embodied 0.5 is a vision-language model designed specifically for multi-object tracking in dynamic, real-world environments.

Apr 2, 2026
Vision-Language
HY-Embodied 0.5
Tencent/Image → Video

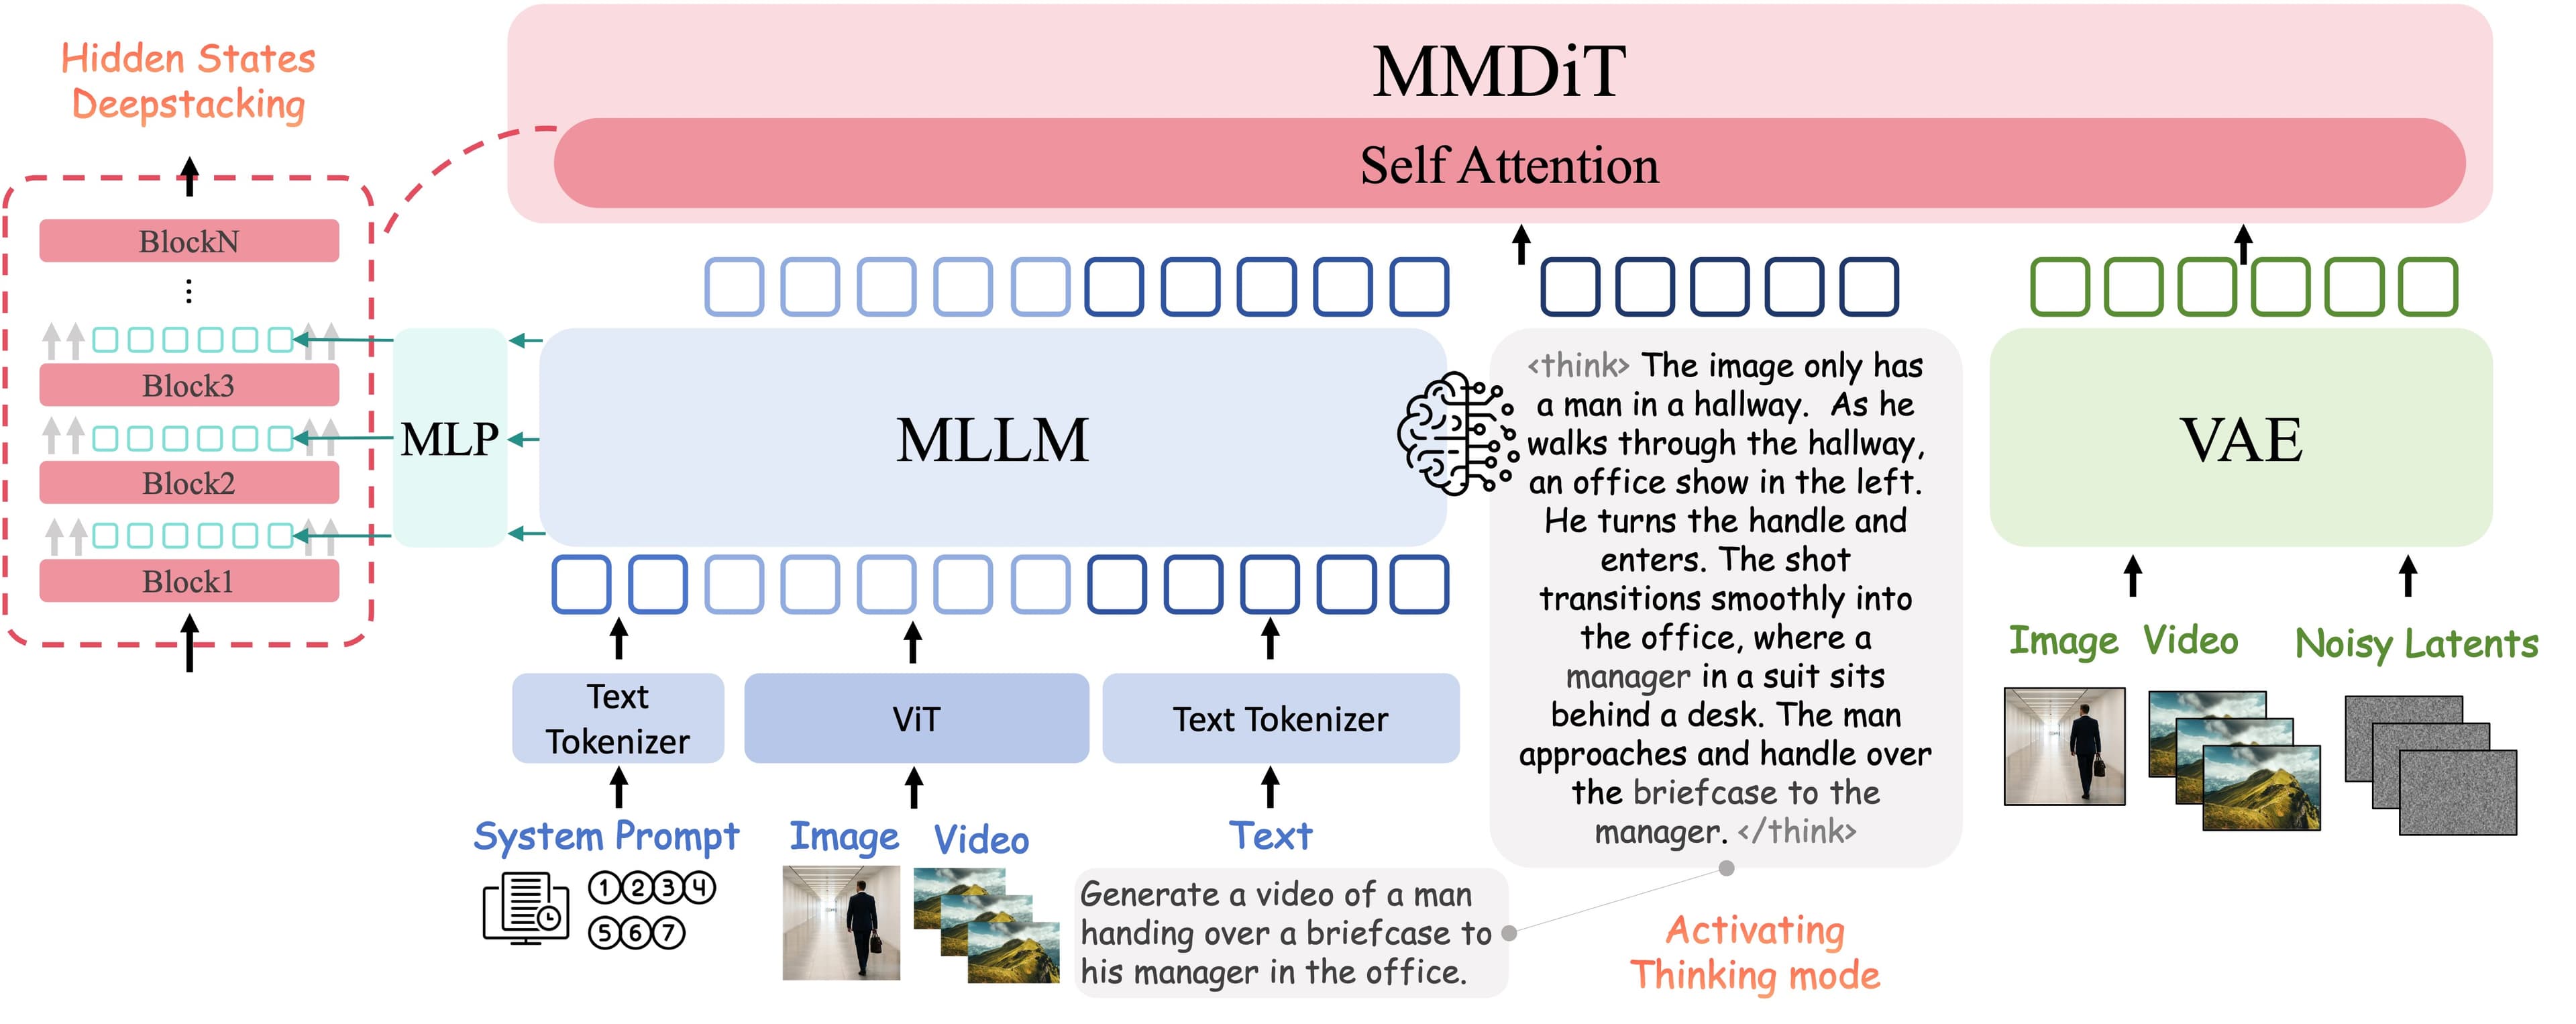
Tencent Releases HY-OmniWeaving for Multi-Image Video

Built on their HunyuanVideo-1.5 architecture, the new model synthesizes video by combining multiple static images and text prompts into a cohesive narrative.

Mar 31, 2026
Image → VideoText → Video
HY-OmniWeaving
Tencent/Image → Video

Tencent's HY-WorldPlay Creates 3D Scenes from One Image

The new model from Tencent's Hunyuan team generates dynamic video and reconstructs 3D environments using a single static picture.

Dec 12, 2025
Image → VideoText → 3D
HY-WorldPlay
Tencent/Text → VideoMajor release

Tencent Releases HunyuanVideo 1.5 Generation Model

The new diffusion model generates short video clips from text and image prompts, adding another major player to the open video space.

Nov 18, 2025
Text → VideoImage → Video
HunyuanVideo 1.5
Tencent/Vision-LanguageRuns anywhere

Tencent Releases 1B Parameter HunyuanOCR Model

The new vision-language model from Tencent Hunyuan offers a compact, end-to-end solution for optical character recognition.

Nov 18, 2025
Vision-Language
HunyuanOCR
Tencent/Text → ImageWorkstation GPU

Tencent Debuts HunyuanImage 3.0 with MoE Design

The new text-to-image generator from the Chinese tech giant uses a Mixture-of-Experts architecture for more efficient and detailed image creation.

Sep 25, 2025
Text → Image
HunyuanImage 3.0 Instruct
Tencent/Text → ImageMajor releaseWorkstation GPU

Tencent Releases HunyuanImage 3.0 Text-to-Image Model

The new text-to-image generator from the Chinese tech giant uses a Mixture-of-Experts architecture for improved efficiency and output quality.

Sep 25, 2025
Text → Image
HunyuanImage 3.0 Instruct
Tencent/Text → ImageRuns on a laptop

Tencent SRPO Fine-Tunes SDXL with Preference Optimization

The new text-to-image model uses a novel rejection sampling technique to align Stable Diffusion XL more closely with human aesthetic preferences.

Sep 8, 2025
Text → Image
SRPO
Tencent/Text → Image

Tencent Releases HunyuanImage 2.1 for Bilingual AI Art

The new text-to-image model from the Chinese tech giant is designed to understand both Chinese and English prompts at high resolutions.

Sep 5, 2025
Text → Image
HunyuanImage 2.1
Tencent/Image → Video

Tencent's Voyager Model Turns Images into 3D Worlds

The new model from Tencent AI Lab generates temporally and spatially consistent video sequences from a single image, enabling virtual exploration of static scenes.

Aug 27, 2025
Image → VideoText → 3D
HunyuanWorld-Voyager
Tencent/Image → Video

Tencent Releases Controllable Game Video Model

The new Hunyuan-GameCraft 1.0 is an open image-to-video model that generates interactive game-like scenes with precise camera control.

Aug 13, 2025
Image → Video
Hunyuan-GameCraft 1.0
Tencent/Text → VideoRuns on a laptop

Tencent Releases Wan2.2, a 14B MoE Video Model

The new Apache 2.0-licensed generator uses a Mixture-of-Experts architecture and is available in the popular Diffusers library format for easier integration.

Jul 28, 2025
Text → Video
Wan2.2 T2V A14B