Tencent Releases 1B Parameter HunyuanOCR Model
The new vision-language model from Tencent Hunyuan offers a compact, end-to-end solution for optical character recognition.
Tencent has released HunyuanOCR, a new vision-language model specialized for reading text in images. At a relatively compact one billion parameters, the model provides an efficient, open-source tool for developers working on optical character recognition (OCR) tasks.
HunyuanOCR uses an end-to-end architecture, which simplifies the traditional OCR pipeline. Instead of first detecting text boxes and then separately recognizing the characters inside them, the model processes the entire task in a single step. This integrated approach can improve performance on challenging inputs like dense documents or text in natural scenes.
The model's capabilities are suited for a range of applications, including document digitization, extracting information from forms, and reading text from real-world photos like street signs or product labels. All model assets are available on the Hugging Face Hub under a permissive Apache 2.0 license, encouraging both research and commercial use.
This release from the Tencent Hunyuan team reflects a growing industry trend of releasing smaller, specialized models. While massive general-purpose models attract headlines, focused tools like HunyuanOCR provide a practical and efficient solution for developers needing to solve a specific, common problem.
Sources
- Visit
tencent/HunyuanOCR
Hugging Face
More from Tencent
All Tencent releases →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
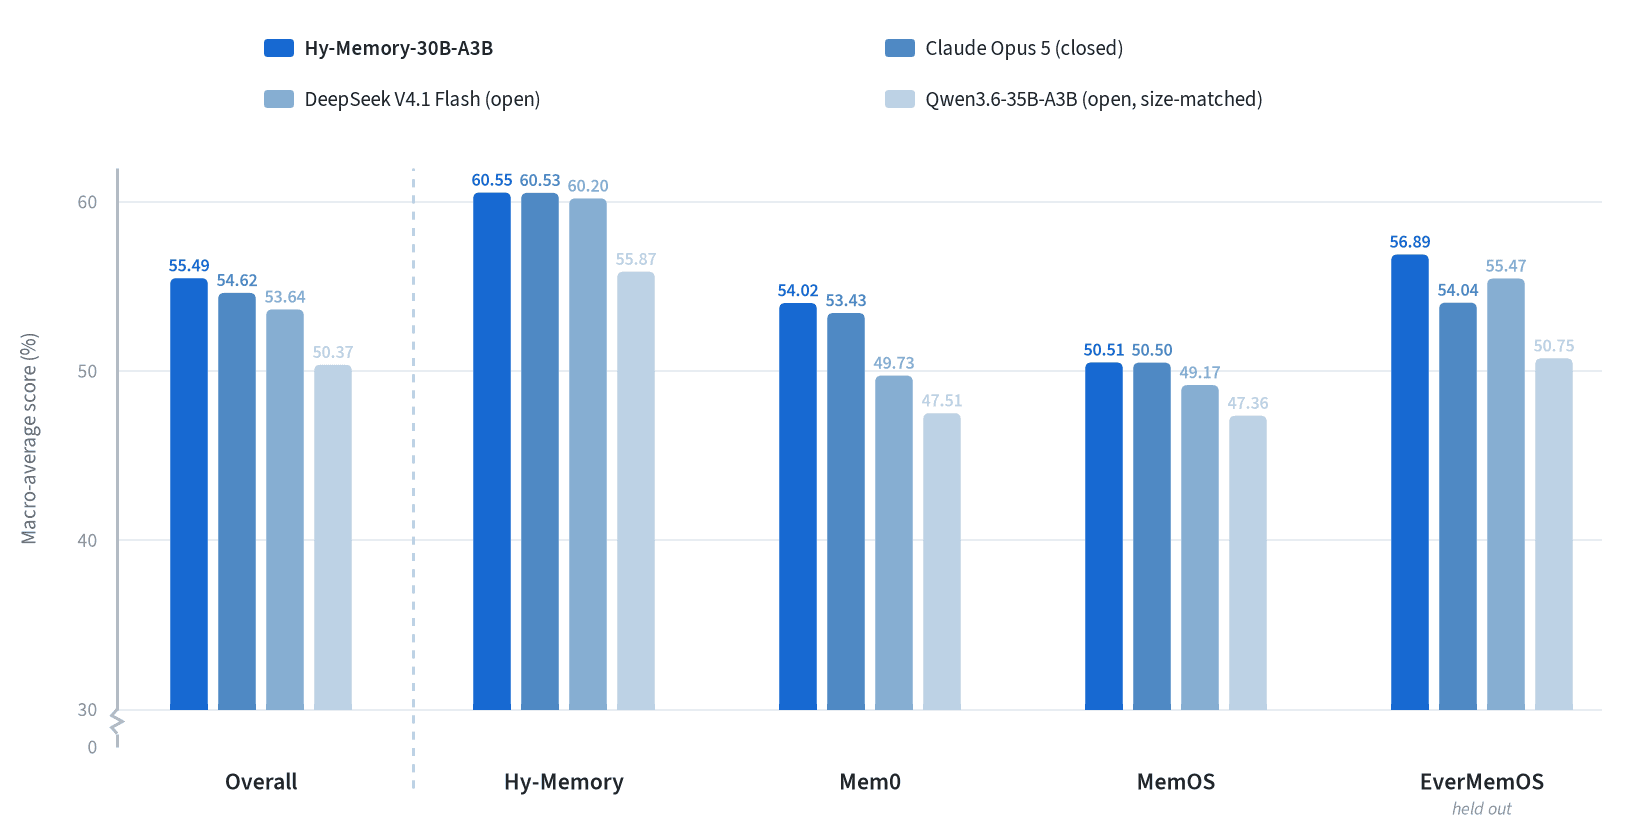
Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
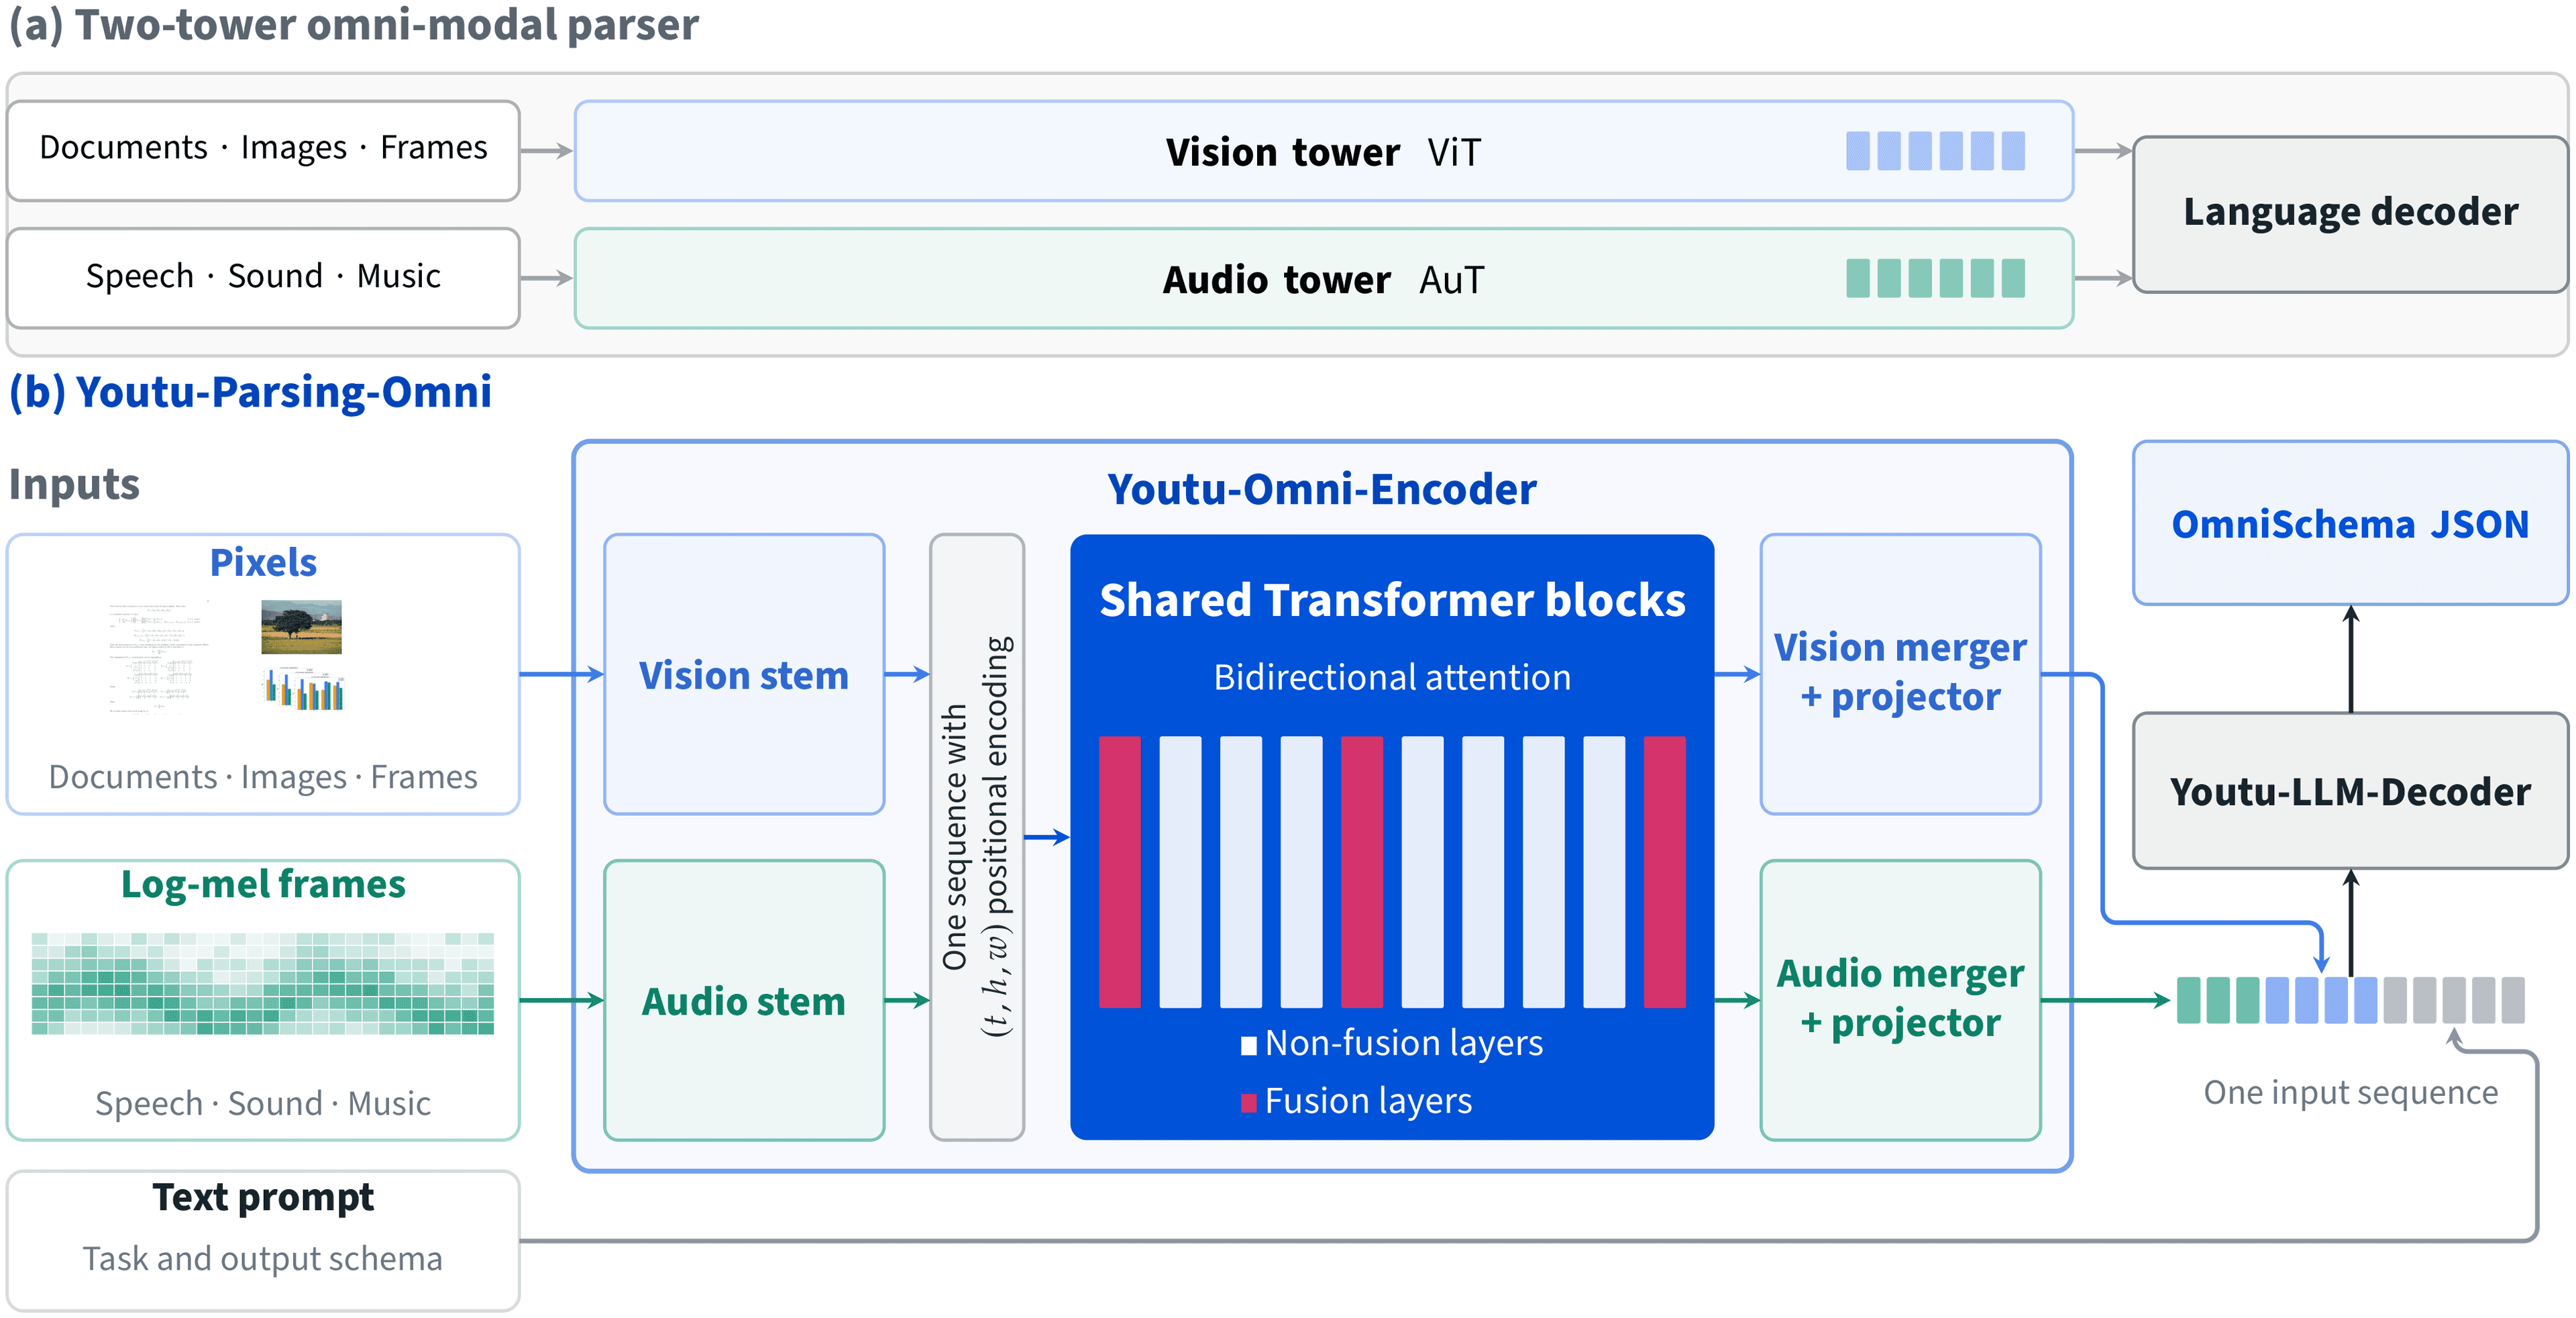
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
More in Vision-Language
All Vision-Language →
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.

Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
0 comments
No comments yet. Be the first to weigh in.