Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
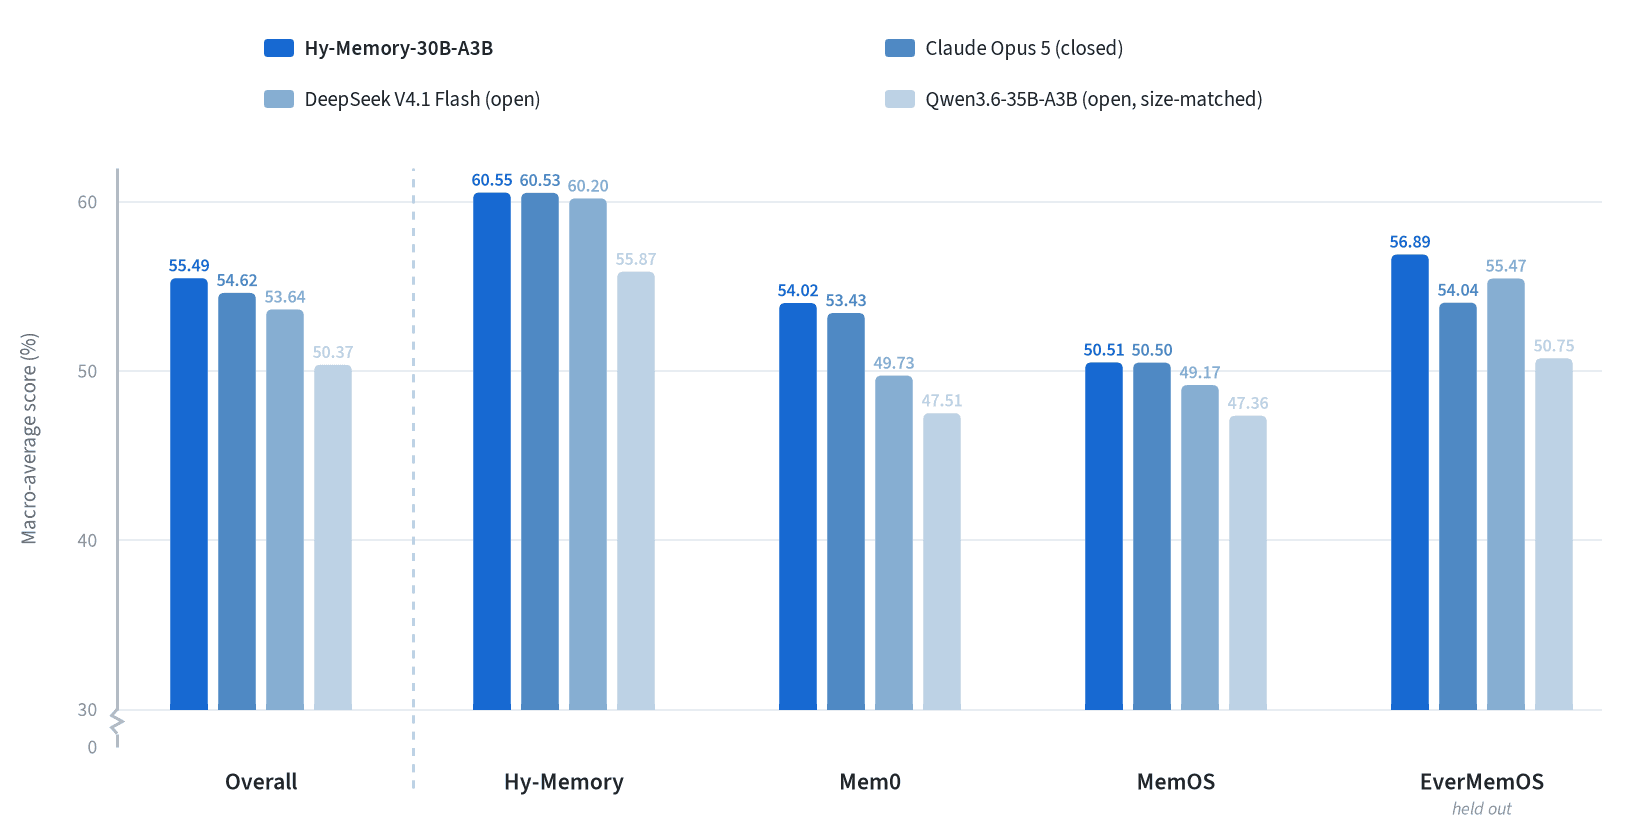
Tencent has published Hy-Memory 30B-A3B, a text-generation language model built around a mixture-of-experts (MoE) design. According to the model's Hugging Face repository, it carries 30 billion total parameters but activates only about 3 billion per token — the "A3B" in its name — a configuration meant to deliver the capacity of a larger model at a fraction of the inference cost.
The standout framing here is memory. As the name suggests, the model is positioned around memory-centric capabilities, a growing area of interest as developers look to build assistants that retain context across longer interactions rather than treating every exchange in isolation.
Why it matters
Sparse MoE architectures have become the default strategy for teams trying to balance quality and serving cost, and a 30B/3B split puts Hy-Memory in a practical range for self-hosting.
- Open license: Apache 2.0, which permits commercial use and modification.
- Efficient inference: roughly 3B active parameters per token keeps compute requirements modest.
- Focused design: the model emphasizes memory rather than general-purpose breadth.
Tencent has steadily expanded its open-weights footprint, and an Apache-licensed release lowers the barrier for researchers and companies that want to experiment without restrictive terms. Full details on context length, benchmarks, and recommended usage are available on the official repository.
Sources
- Visit
tencent/Hy-Memory-30B-A3B
Hugging Face
More from Tencent
All Tencent releases →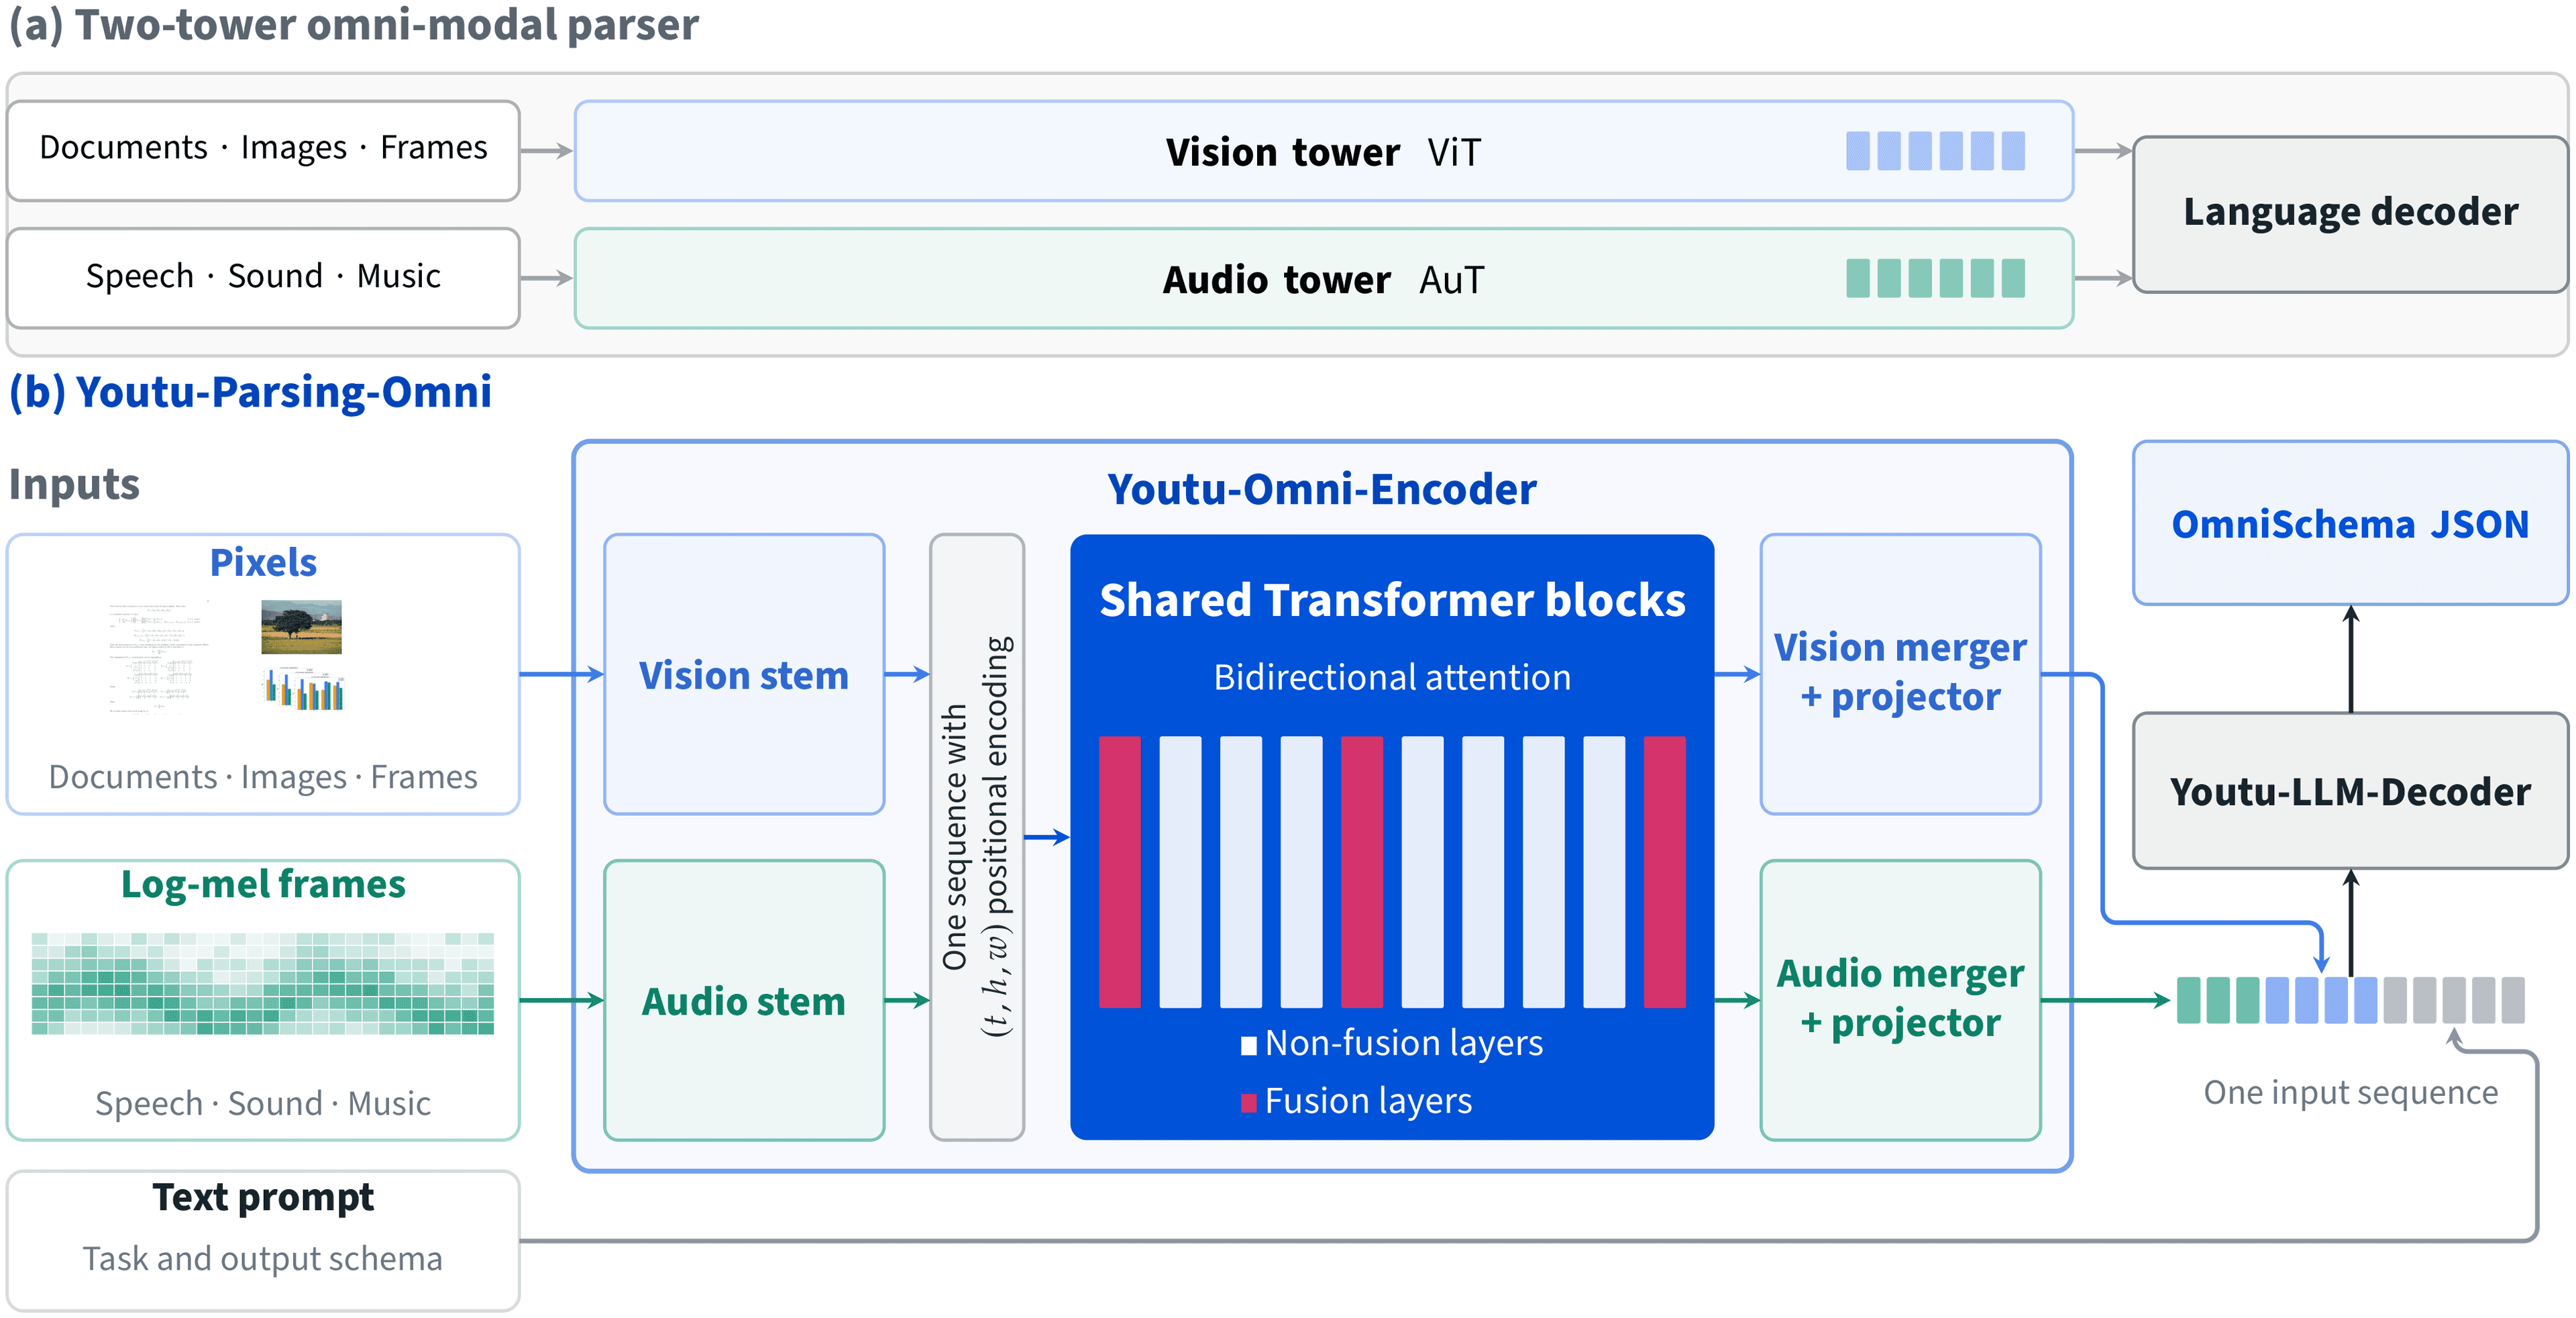
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
Tencent's T1 Targets Long-Horizon Terminal Work
A 122B mixture-of-experts model trained with reinforcement learning claims state-of-the-art results on Terminal-Bench.

Tencent Previews Hunyuan Hy4, an Apache MoE Model
The company's next-generation Hunyuan language model arrives as an early preview with a permissive license and a mixture-of-experts design.
More in Text / LLM
All Text / LLM →IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
inclusionAI releases Ling-3.1-flash under MIT license
A new hybrid mixture-of-experts text model arrives on Hugging Face with permissive licensing and a focus on fast inference.
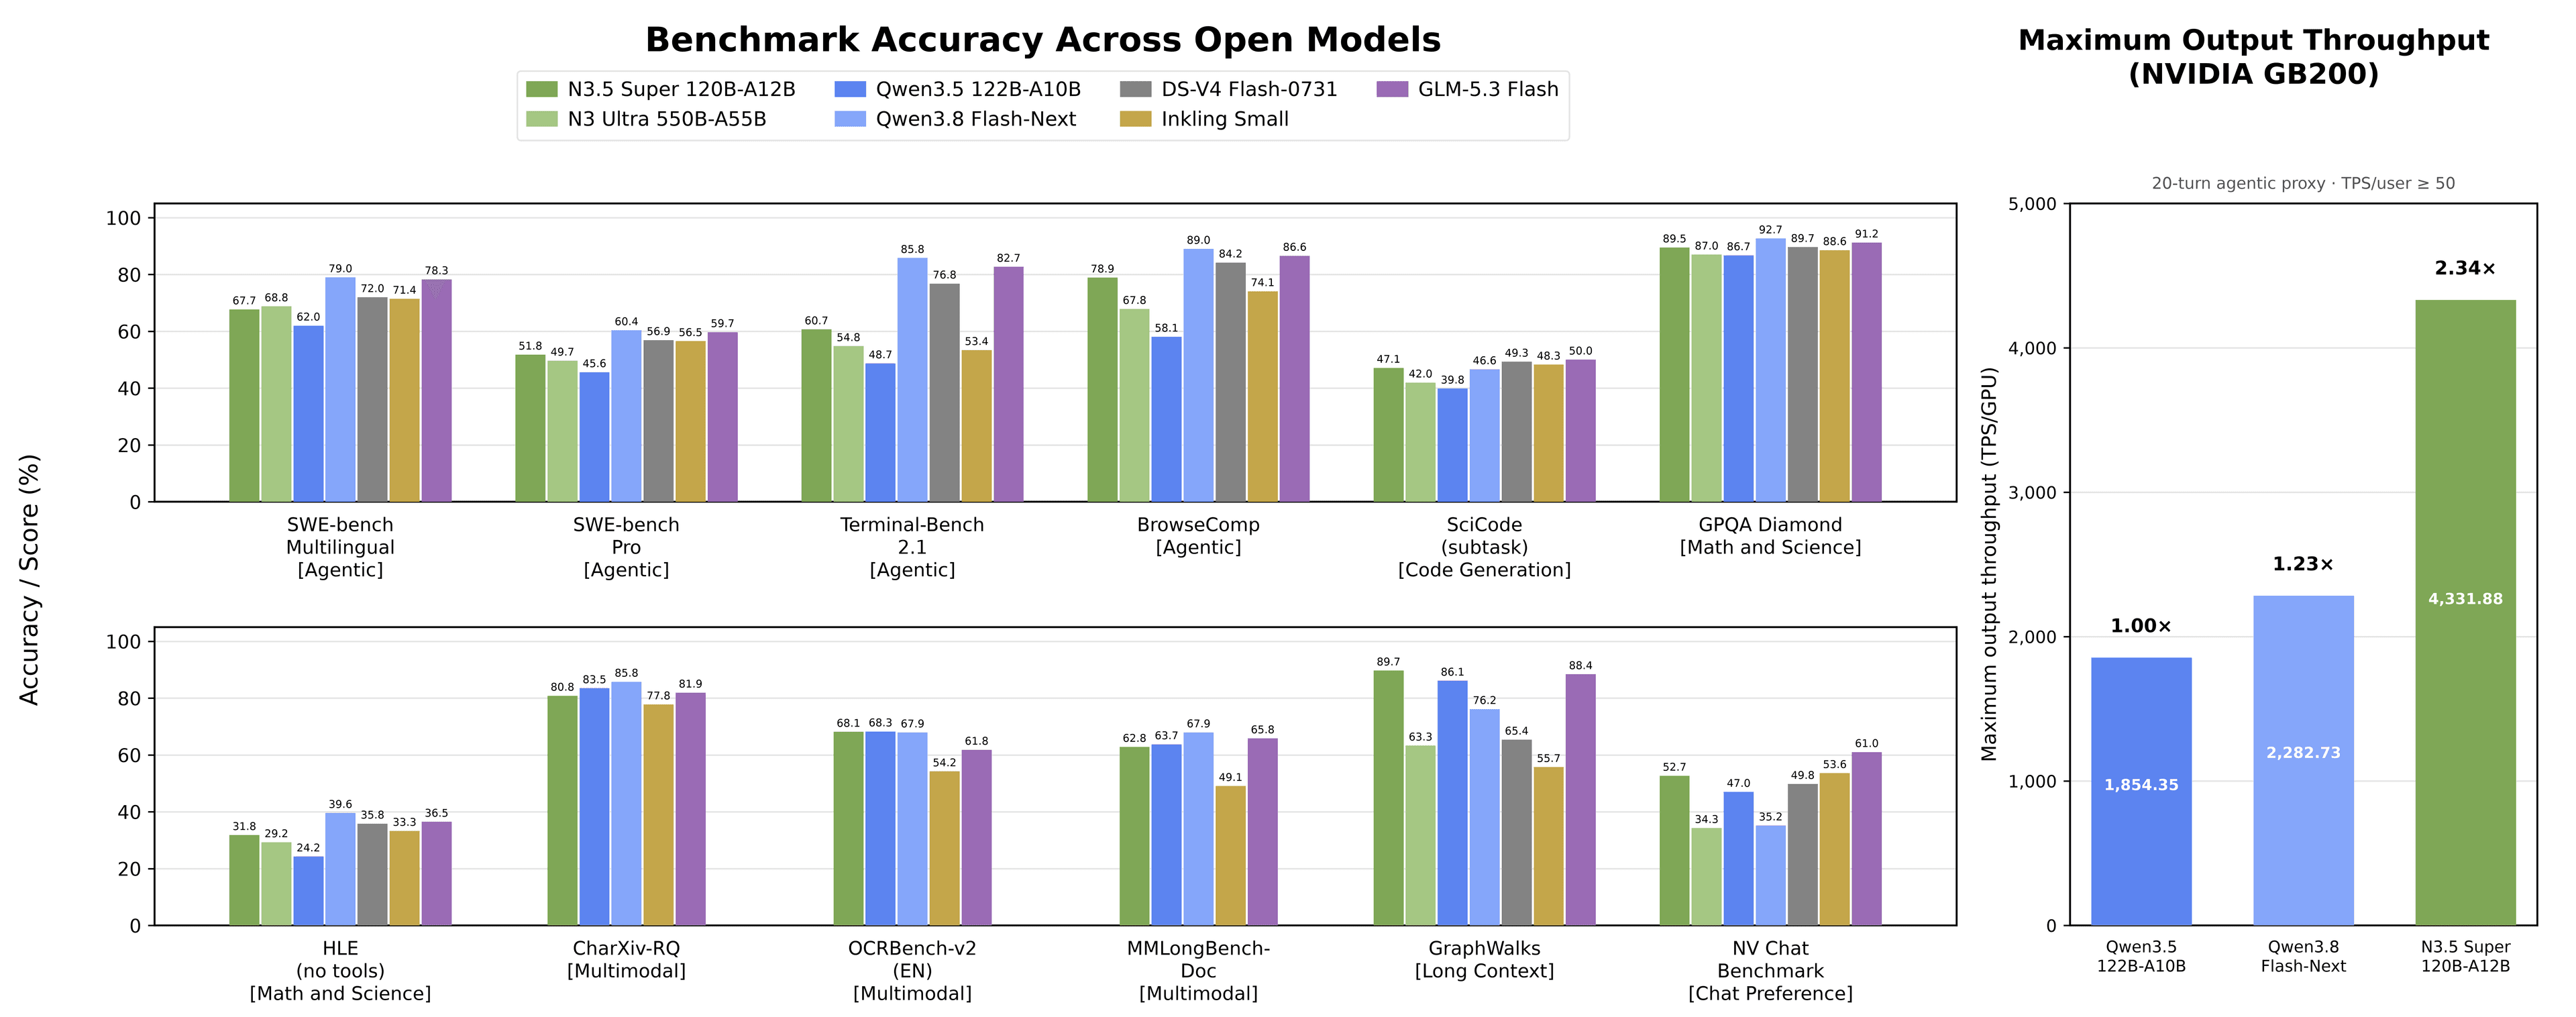
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
0 comments
No comments yet. Be the first to weigh in.