Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.

Tencent has released Hy-Nomas, an interactive video world model that generates video from both text and image prompts. Unlike standard clip generators, Hy-Nomas is designed to respond to actions and camera movement as it unfolds a scene, positioning it closer to the emerging class of "world models" than to one-shot video synthesis tools.
The model's defining feature is action-aware causal attention, a design that lets each generated frame depend on prior frames and on user-supplied inputs in a time-ordered way. Paired with explicit camera control, that approach is meant to produce footage you can steer — adjusting viewpoint and prompting behavior — rather than simply rendering a fixed sequence end to end.
Why it matters
Interactive and controllable video generation is quickly becoming the next frontier beyond text-to-video, with applications in simulation, game-like environments, and embodied AI research. Open releases in this space remain comparatively rare, so a model from a major lab that ships weights publicly gives researchers and developers something concrete to build on.
A few things to keep in mind:
- Hy-Nomas supports both text-to-video and image-to-video workflows.
- It is distributed under a custom ("other") license, so teams should review the terms before commercial use.
- Tencent has not published parameter counts, resolution, or duration specs in the release record.
As an initial release, Hy-Nomas establishes a baseline for Tencent's interactive video work. The full model card and any usage details are available on Hugging Face.
Sources
- Visit
tencent/Hy-Nomas
Hugging Face
More from Tencent
All Tencent releases →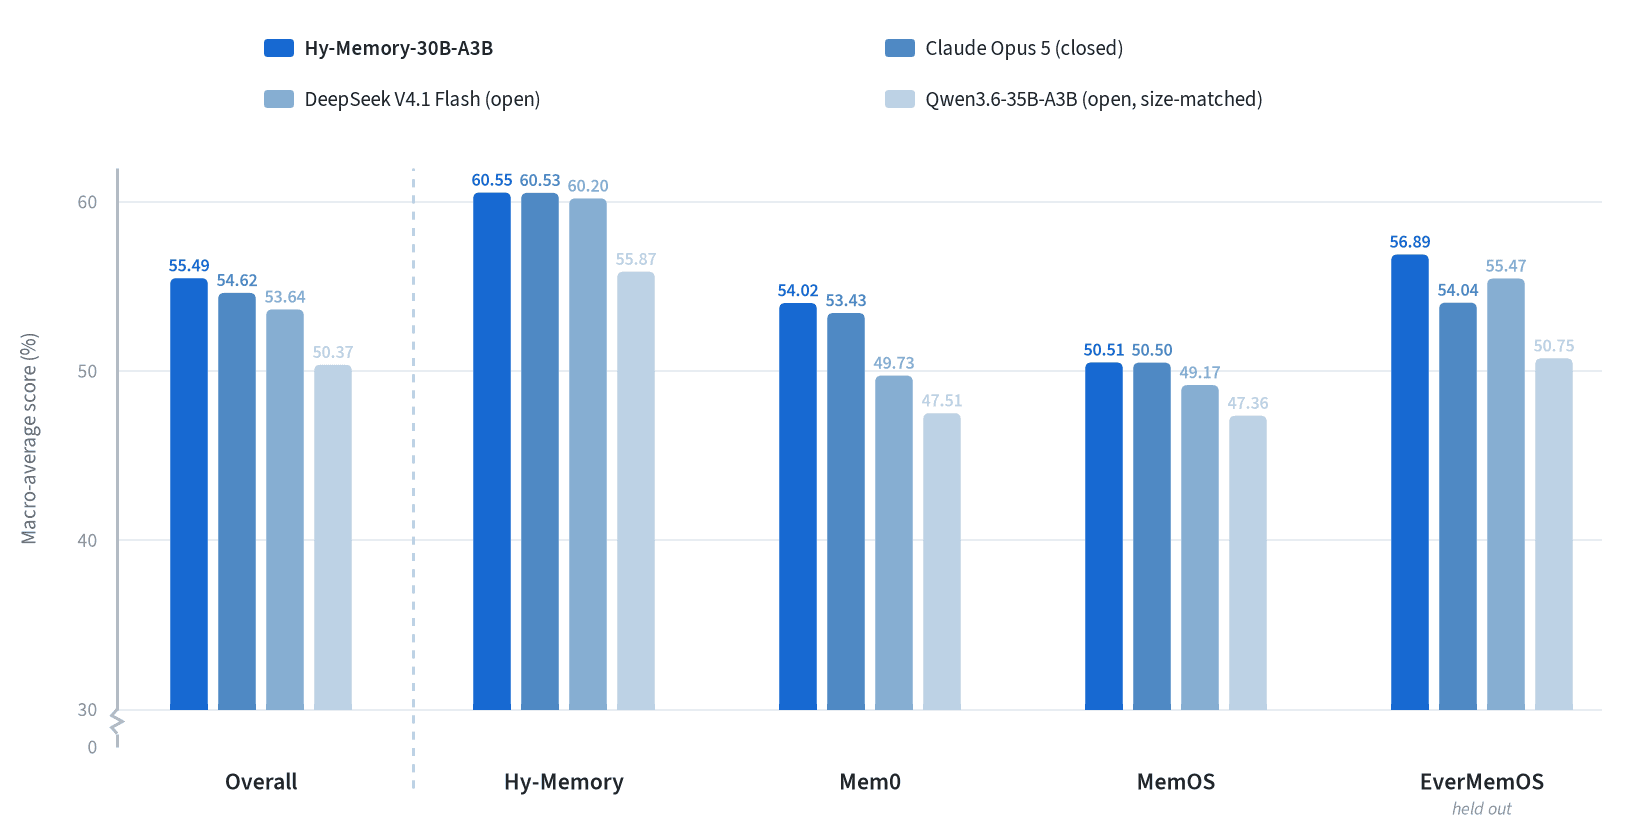
Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
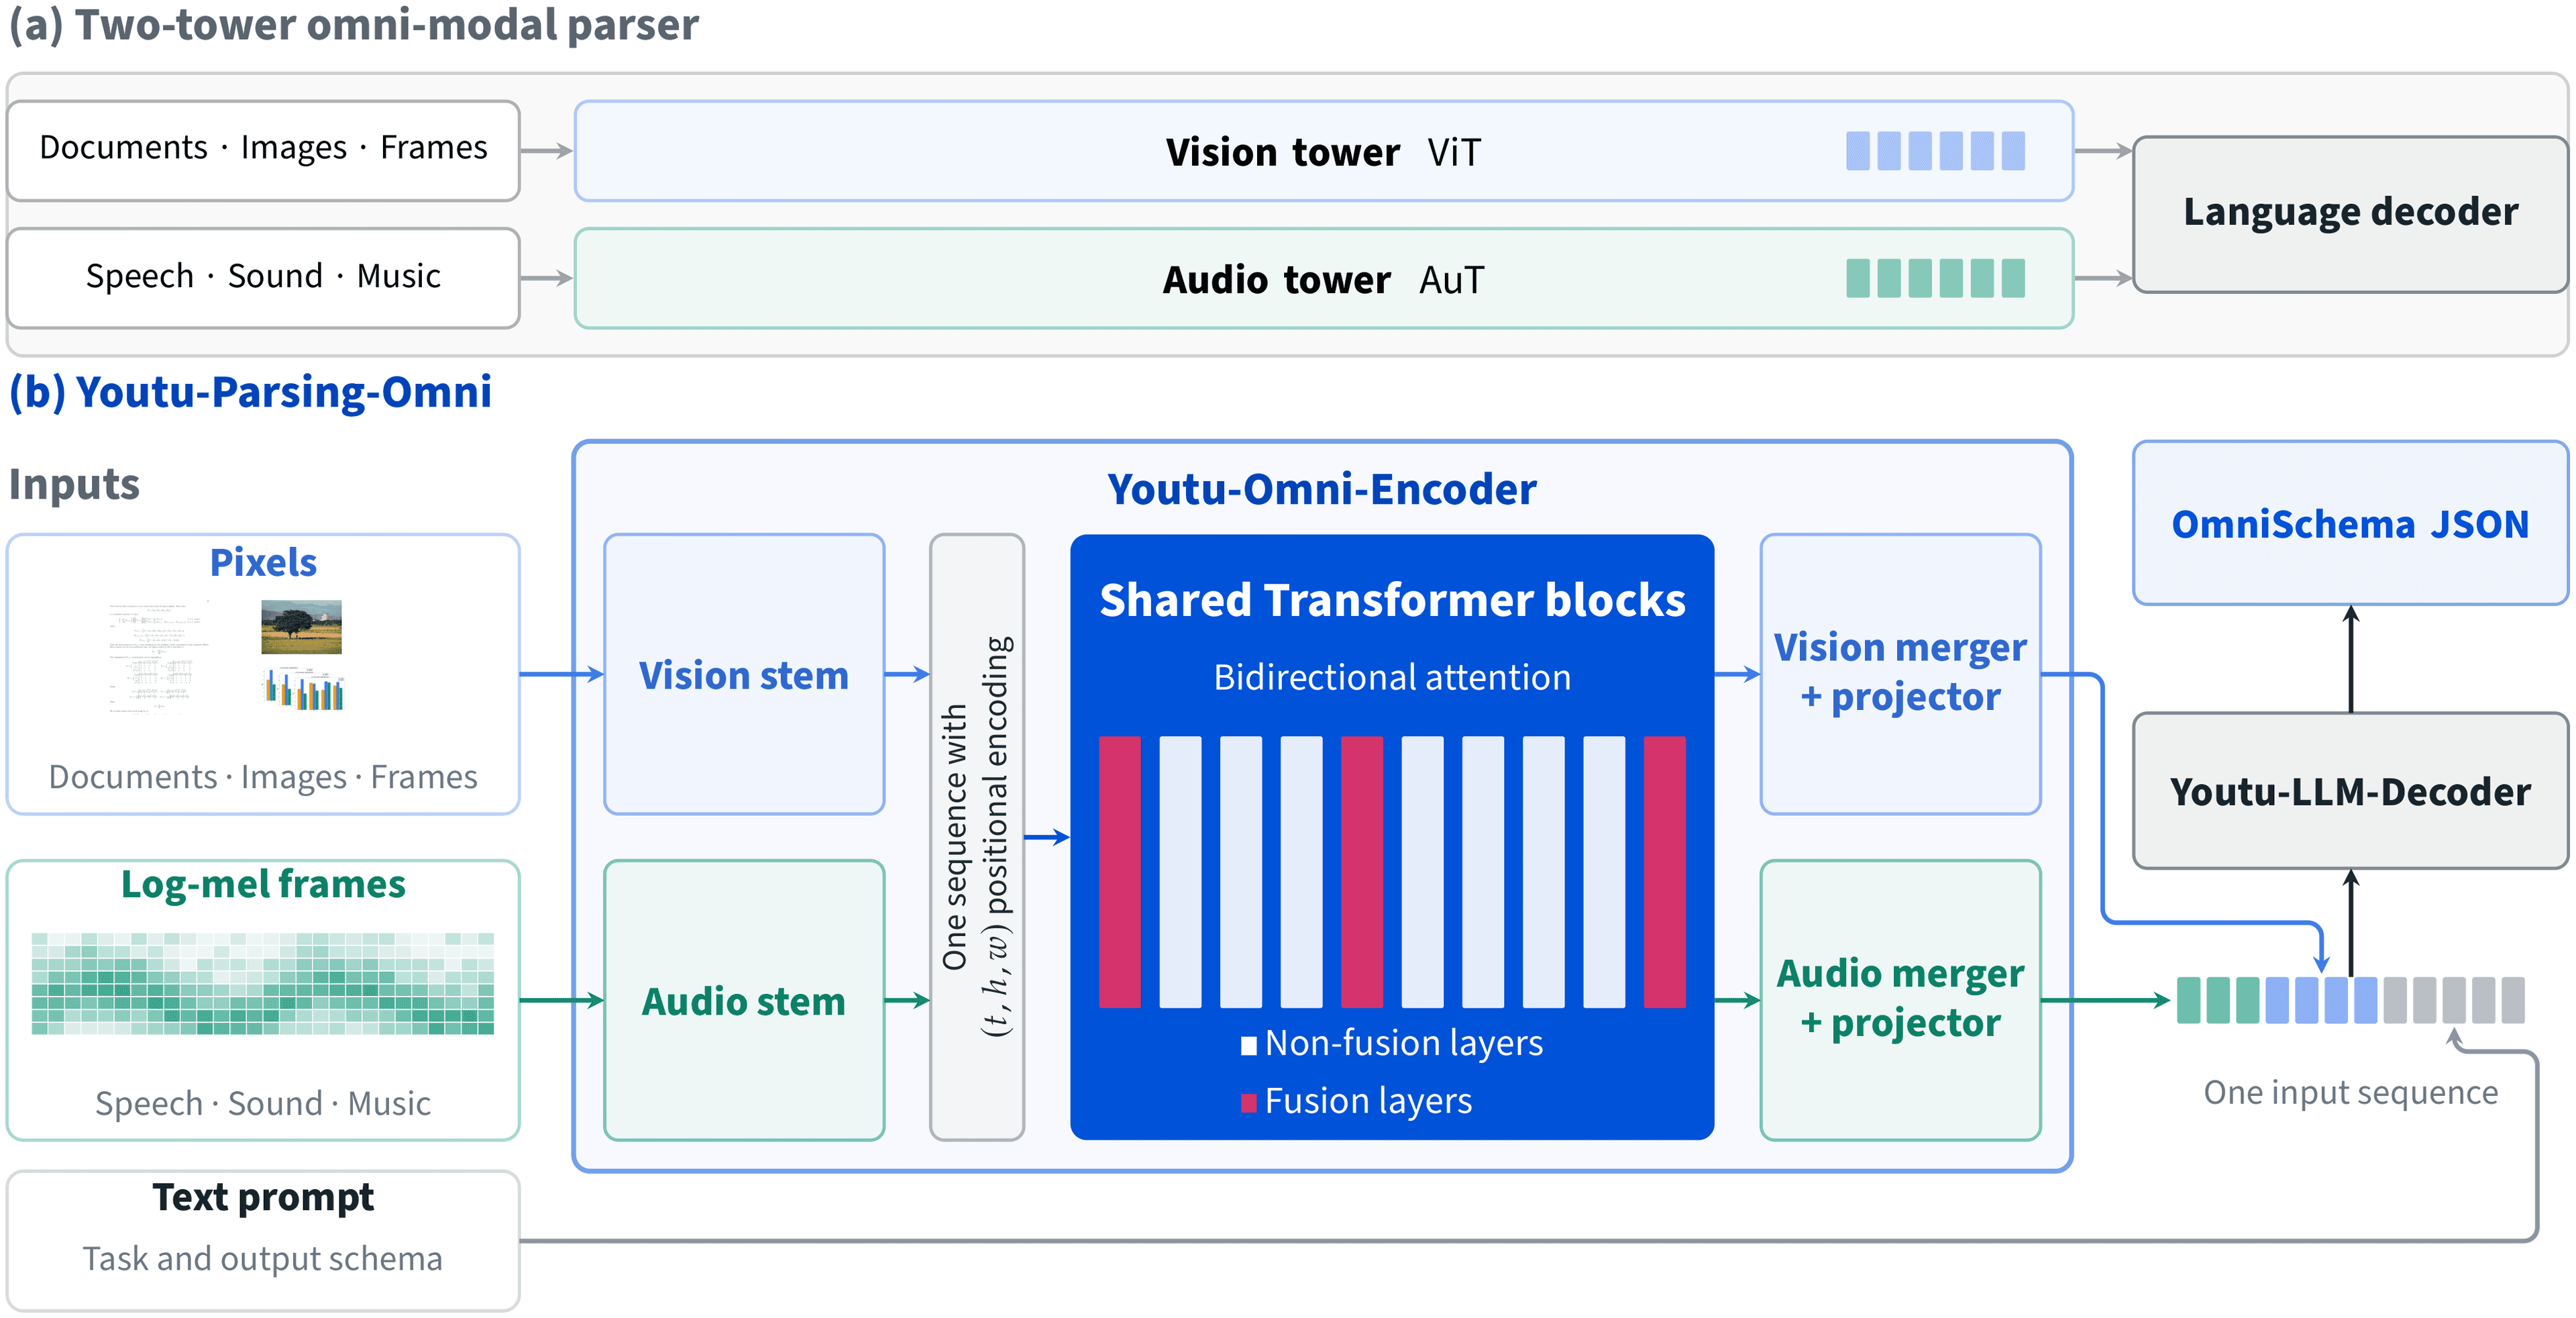
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
Tencent's T1 Targets Long-Horizon Terminal Work
A 122B mixture-of-experts model trained with reinforcement learning claims state-of-the-art results on Terminal-Bench.
More in Text → Video
All Text → Video →Kandinsky 6.0 Generates Video and Audio Together
Kandinsky Lab's new foundation models produce synchronized sound and motion from a text prompt, in 3B and 29B sizes.
MiniMax Releases H3 Video Model on Hugging Face
The company's new diffusion model handles text-to-video and image-to-video, with support for joint audio-video generation.
Lightricks Releases LTX-2.5 Video Model
The latest LTX generator handles text-to-video, image-to-video, and audio-video pipelines in one open release.
0 comments
No comments yet. Be the first to weigh in.