Lightricks Releases LTX-2.5 Video Model
The latest LTX generator handles text-to-video, image-to-video, and audio-video pipelines in one open release.
Lightricks has published LTX-2.5, the newest version of its LTX video generation family, on Hugging Face. The model handles both text-to-video and image-to-video generation, and the release notes an audio-video pipeline alongside the core visual synthesis capabilities.
LTX has been one of the more visible efforts to bring capable video generation into openly available weights, an area still dominated by closed, API-only systems. By packaging multiple input modalities into a single release, Lightricks is positioning LTX-2.5 as a general-purpose creative tool rather than a narrow research artifact.
Why it matters
Video generation remains one of the most compute-hungry and least open corners of the current AI landscape. Models that ship with weights let developers, studios, and researchers experiment locally, fine-tune for specific styles, and build products without depending on a single vendor's endpoint.
A few things worth noting about this release:
- It covers text-to-video and image-to-video in one model, easing the jump between prompt-driven and reference-driven workflows.
- It references an audio-video pipeline, hinting at synchronized sound-and-motion generation.
- It ships under a custom license, so teams should review the terms on the model page before commercial use.
As with any video model, the practical test will be output quality, speed, and how well the weights hold up against closed competitors once the community starts running them. For now, LTX-2.5 adds another credible option to the short list of open video generators.
Sources
- Visit
Lightricks/LTX-2.5
Hugging Face
More from Lightricks
All Lightricks releases →
Lightricks Releases LoRA for AI Lip-Dubbing
The new 'Identity-Control' adapter fine-tunes the company's LTX-2.3 video model to create realistic lip-syncing for dubbing workflows.
Lightricks LTX-2.3 Generates Video and Audio Together
The new model, based on Stable Video Diffusion, can create video and a corresponding soundtrack simultaneously from text, image, or audio prompts.
Lightricks Releases LTX-2 Multimodal Video Generator
The new diffusion model from the creative app company can generate short video clips from text, images, audio, and even other videos.
More in Image → Video
All Image → Video →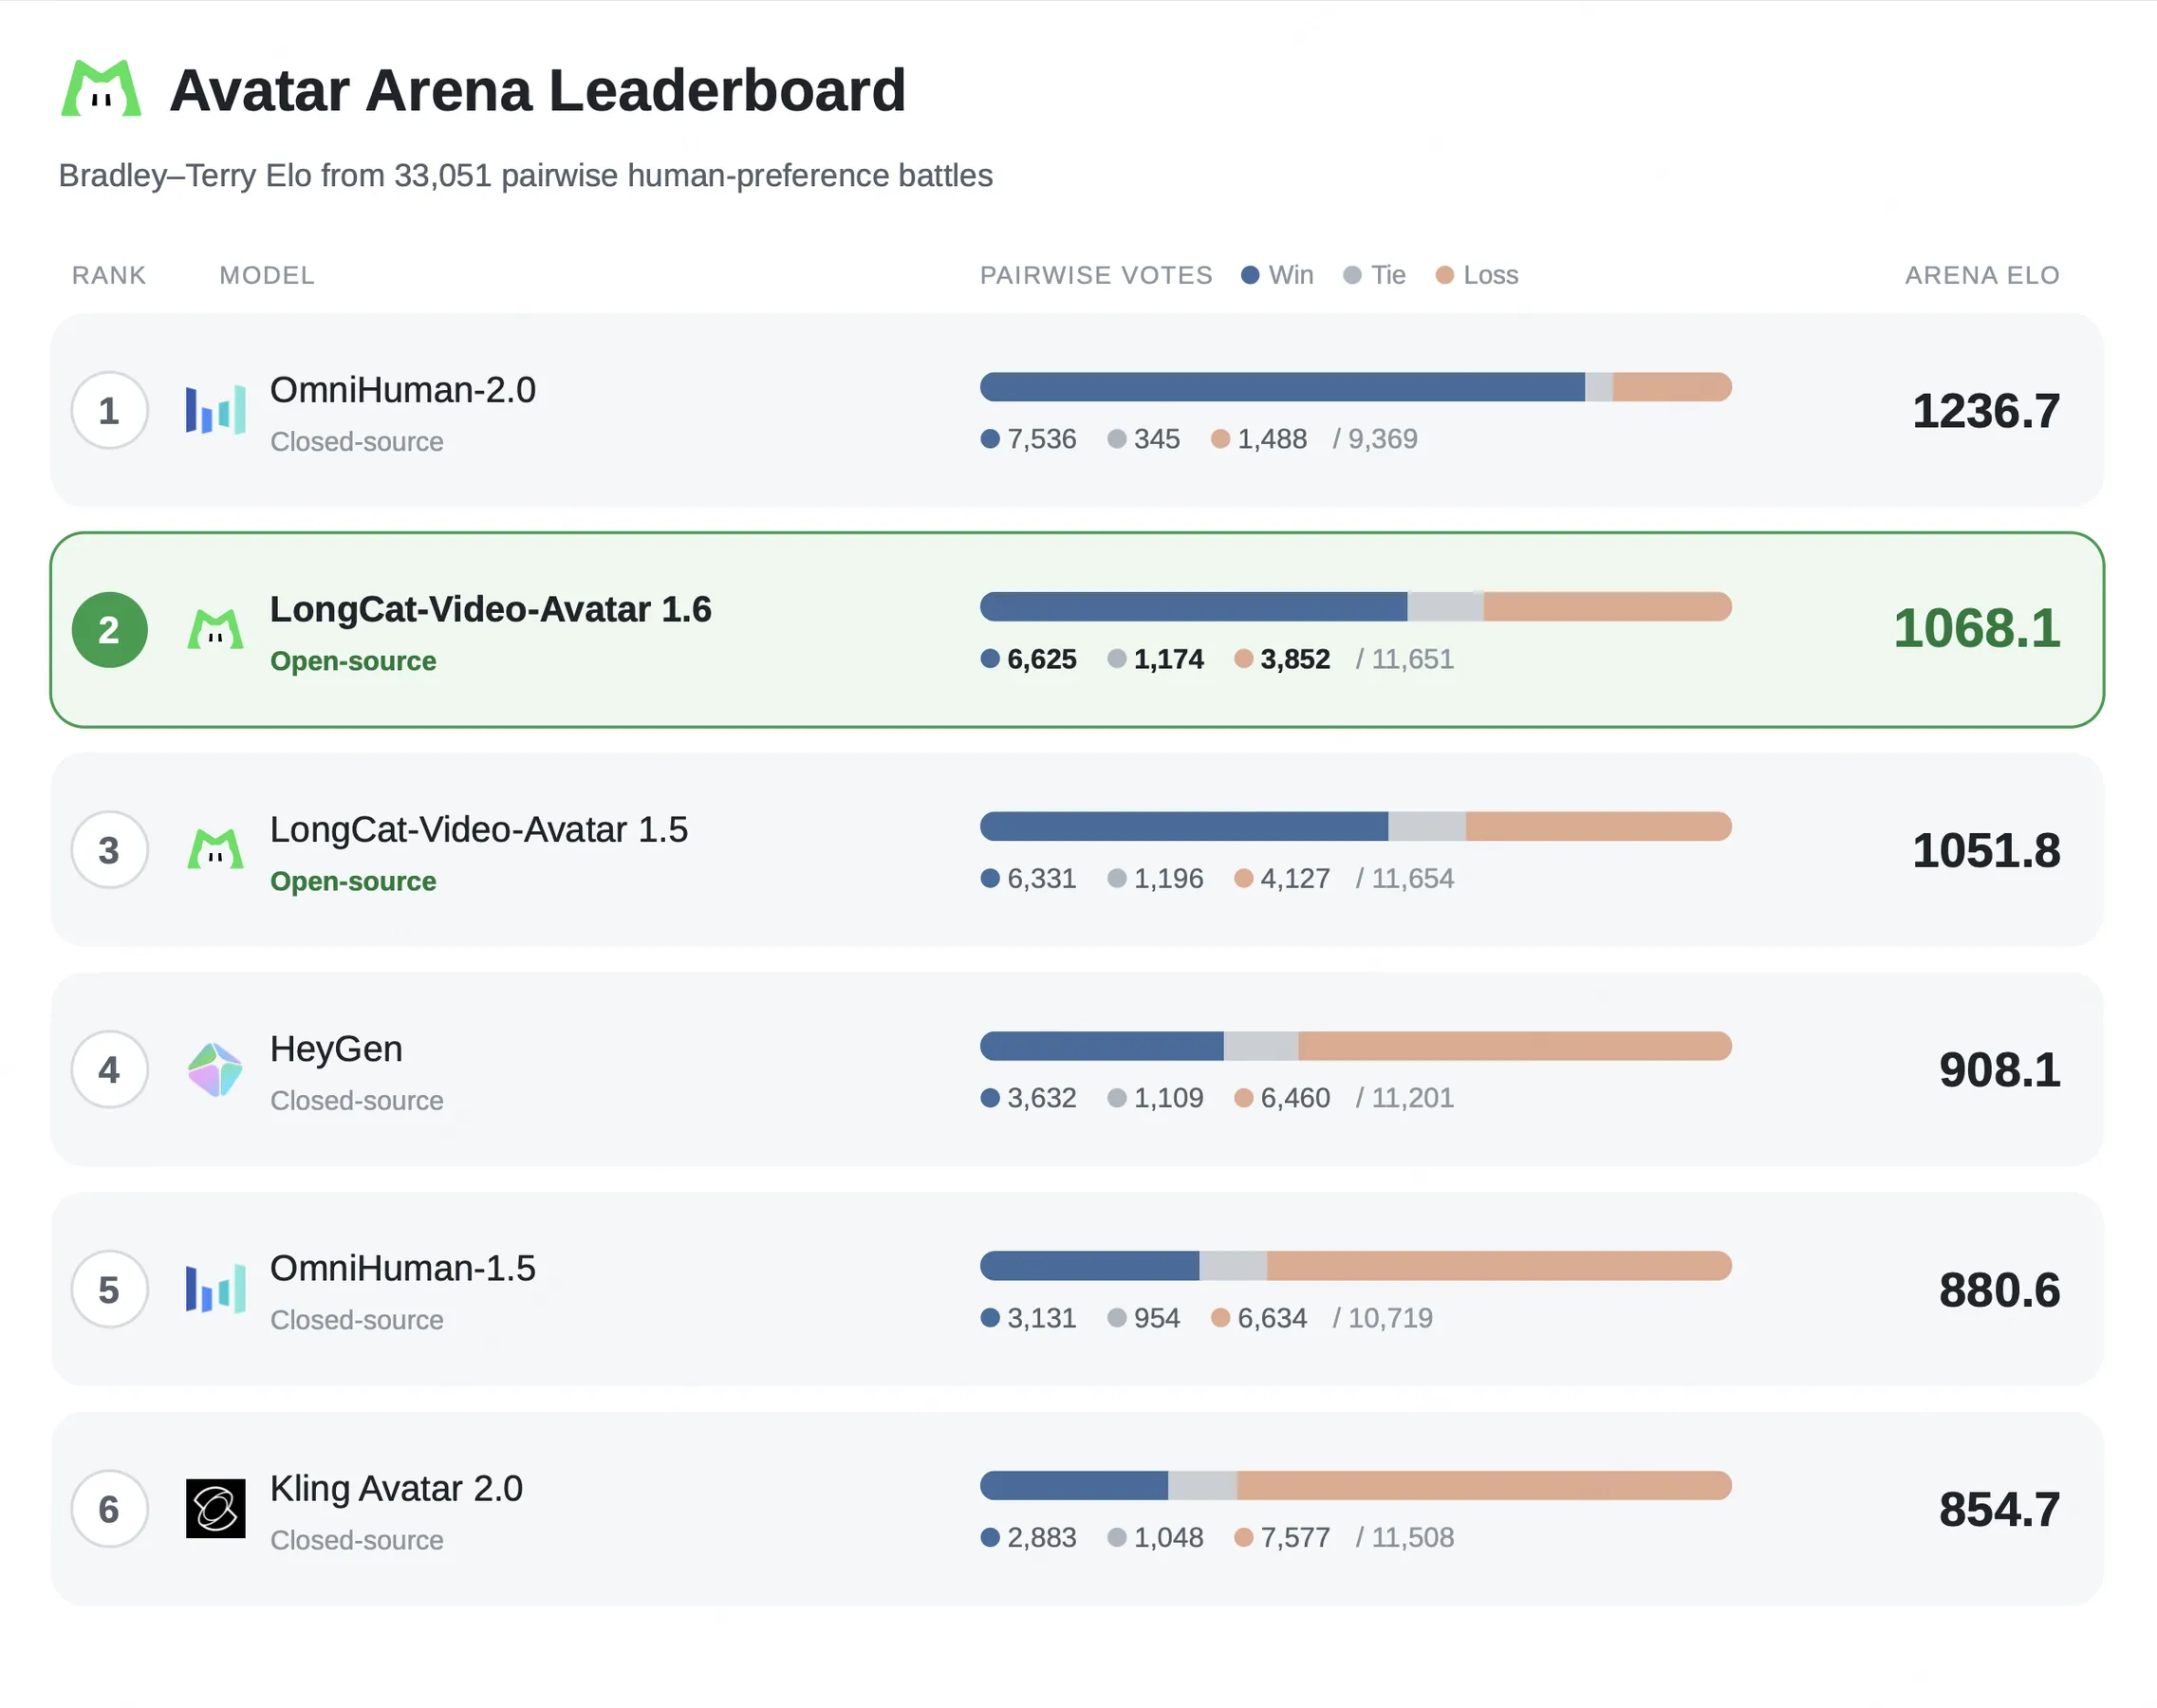
Meituan's LongCat Adds Audio-Driven Avatar Video
The LongCat team releases an image-to-video model that animates still portraits from audio input.
NVIDIA Releases Cosmos 3 for World Simulation
The new open models push NVIDIA's world-foundation effort toward interactive, real-time video generation.
NVIDIA's Cosmos 3 Brings Open Interactive World Models
The new open release pushes beyond passive video generation toward simulated worlds that respond to input.
0 comments
No comments yet. Be the first to weigh in.