Lightricks Releases LoRA for AI Lip-Dubbing
The new 'Identity-Control' adapter fine-tunes the company's LTX-2.3 video model to create realistic lip-syncing for dubbing workflows.

Lightricks, the company behind several popular creative apps, has released a new specialized tool for AI-powered video editing. The release is not a full foundation model, but rather a Low-Rank Adaptation (LoRA) module—a small, efficient network that plugs into a larger model to modify its behavior for a specific task.
Identity-Preserving Dubbing
This new adapter, called an "Identity-Control LoRA" (IC-LoRA), is designed to work with the company's LTX-2.3 22B video model. According to the release notes on its Hugging Face repository, its sole purpose is to enable realistic video lip-dubbing. The technique allows the model to alter a subject's mouth movements to match a new audio track while carefully preserving the person's original facial identity, preventing the uncanny valley effect common in digital alterations.
By releasing a targeted LoRA instead of a fully fine-tuned model, Lightricks makes a sophisticated capability more accessible. Developers and creators can apply this lightweight adapter to the base video model to achieve convincing lip-sync effects without the immense computational overhead of training a large model from scratch. This could significantly lower the barrier for localizing video content into different languages or for other creative dubbing applications.
The adapter is available under the custom Lightricks Research License. While this makes it available for community evaluation and research, it carries different permissions and restrictions than a permissive open-source license like MIT or Apache 2.0, particularly concerning commercial use.
Sources
- Visit
Lightricks/LTX-2.3-22b-IC-LoRA-LipDub
Hugging Face
More from Lightricks
All Lightricks releases →
Lightricks Releases LTX-2.5 Video Model
The latest LTX generator handles text-to-video, image-to-video, and audio-video pipelines in one open release.
Lightricks LTX-2.3 Generates Video and Audio Together
The new model, based on Stable Video Diffusion, can create video and a corresponding soundtrack simultaneously from text, image, or audio prompts.
Lightricks Releases LTX-2 Multimodal Video Generator
The new diffusion model from the creative app company can generate short video clips from text, images, audio, and even other videos.
More in Image → Video
All Image → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
Prism Brings Joint Video-Audio Generation to Diffusion
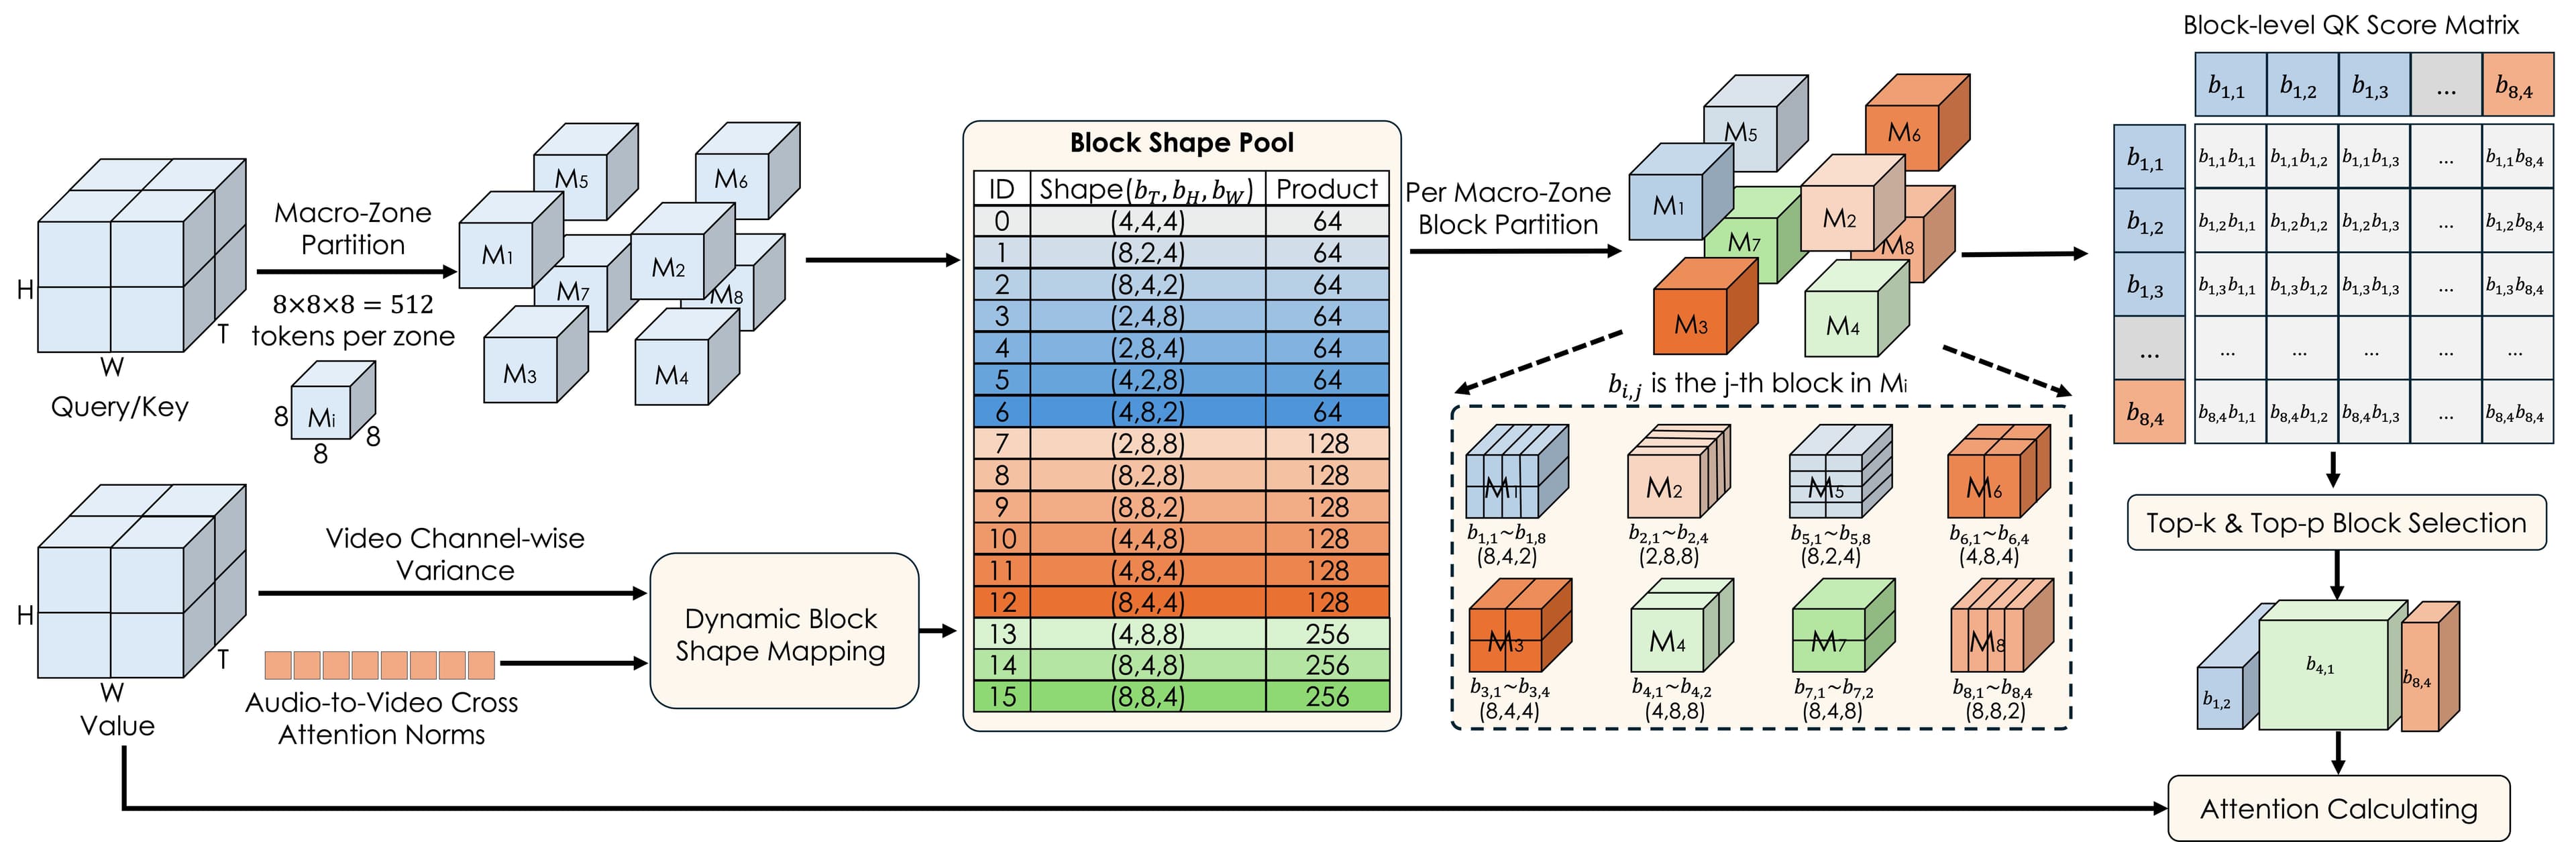
A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.
Viggle Releases Viggle-Animate for Character Swaps
The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.
0 comments
No comments yet. Be the first to weigh in.