NVIDIA's Cosmos 3 Edge Brings World Models Closer
A new edge-optimized variant of NVIDIA's Cosmos world-model line aims to run generative video where the compute lives.
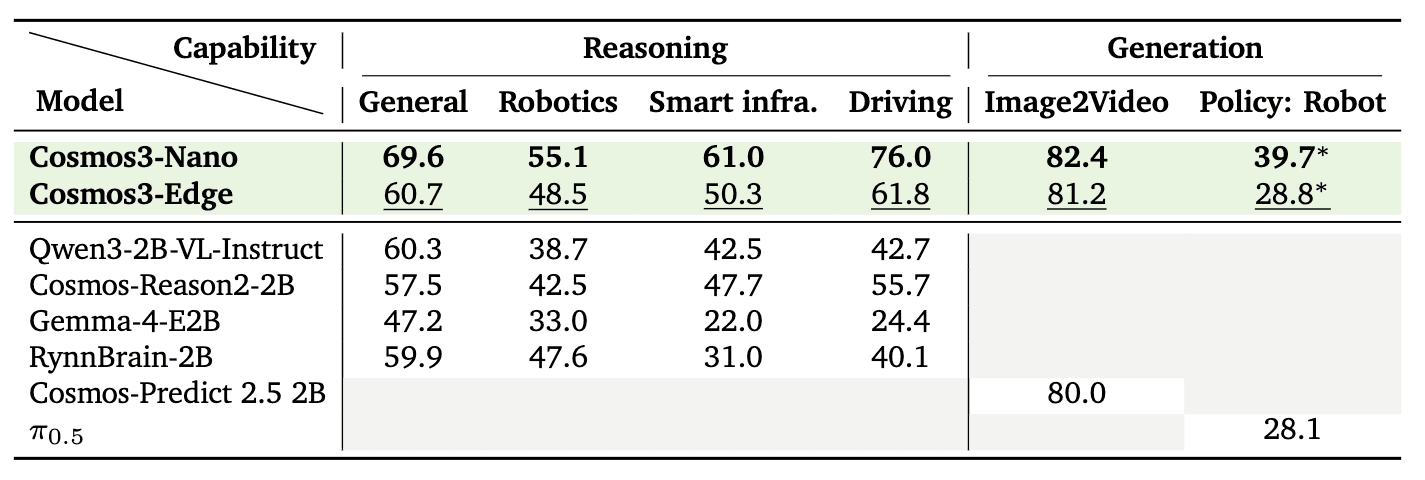
NVIDIA has released Cosmos 3 Edge, a variant of its Cosmos world-model line built specifically for deployment closer to where data is generated. The model supports both text-to-video and image-to-video generation, extending Cosmos into scenarios where sending frames to a distant data center isn't practical.
Cosmos is NVIDIA's family of "world models"—systems designed to simulate and predict physical environments rather than just produce standalone clips. That framing matters for robotics, autonomous vehicles, and industrial simulation, where a model that understands how scenes evolve over time is more useful than one that simply generates pretty footage.
Why it matters
The "Edge" designation is the headline here. Running video-generation and world-simulation workloads on constrained hardware is a persistent bottleneck, and an edge-tuned build points at use cases that need low latency or offline operation:
- On-device or on-premise generation without a round trip to the cloud
- Robotics and autonomy pipelines that need synthetic data locally
- Deployments where connectivity or privacy rules limit cloud use
NVIDIA has not published parameter counts, resolution, or frame-rate details in this record, so the practical performance envelope will become clearer as developers test the weights. The model ships under a custom license, so teams should review the terms on the model page before building on it.
As the first Cosmos 3 entry to surface publicly, Edge sets an early marker for where the line is heading: not just bigger generative video, but models sized to run in the field.
Sources
- Visit
nvidia/Cosmos3-Edge
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
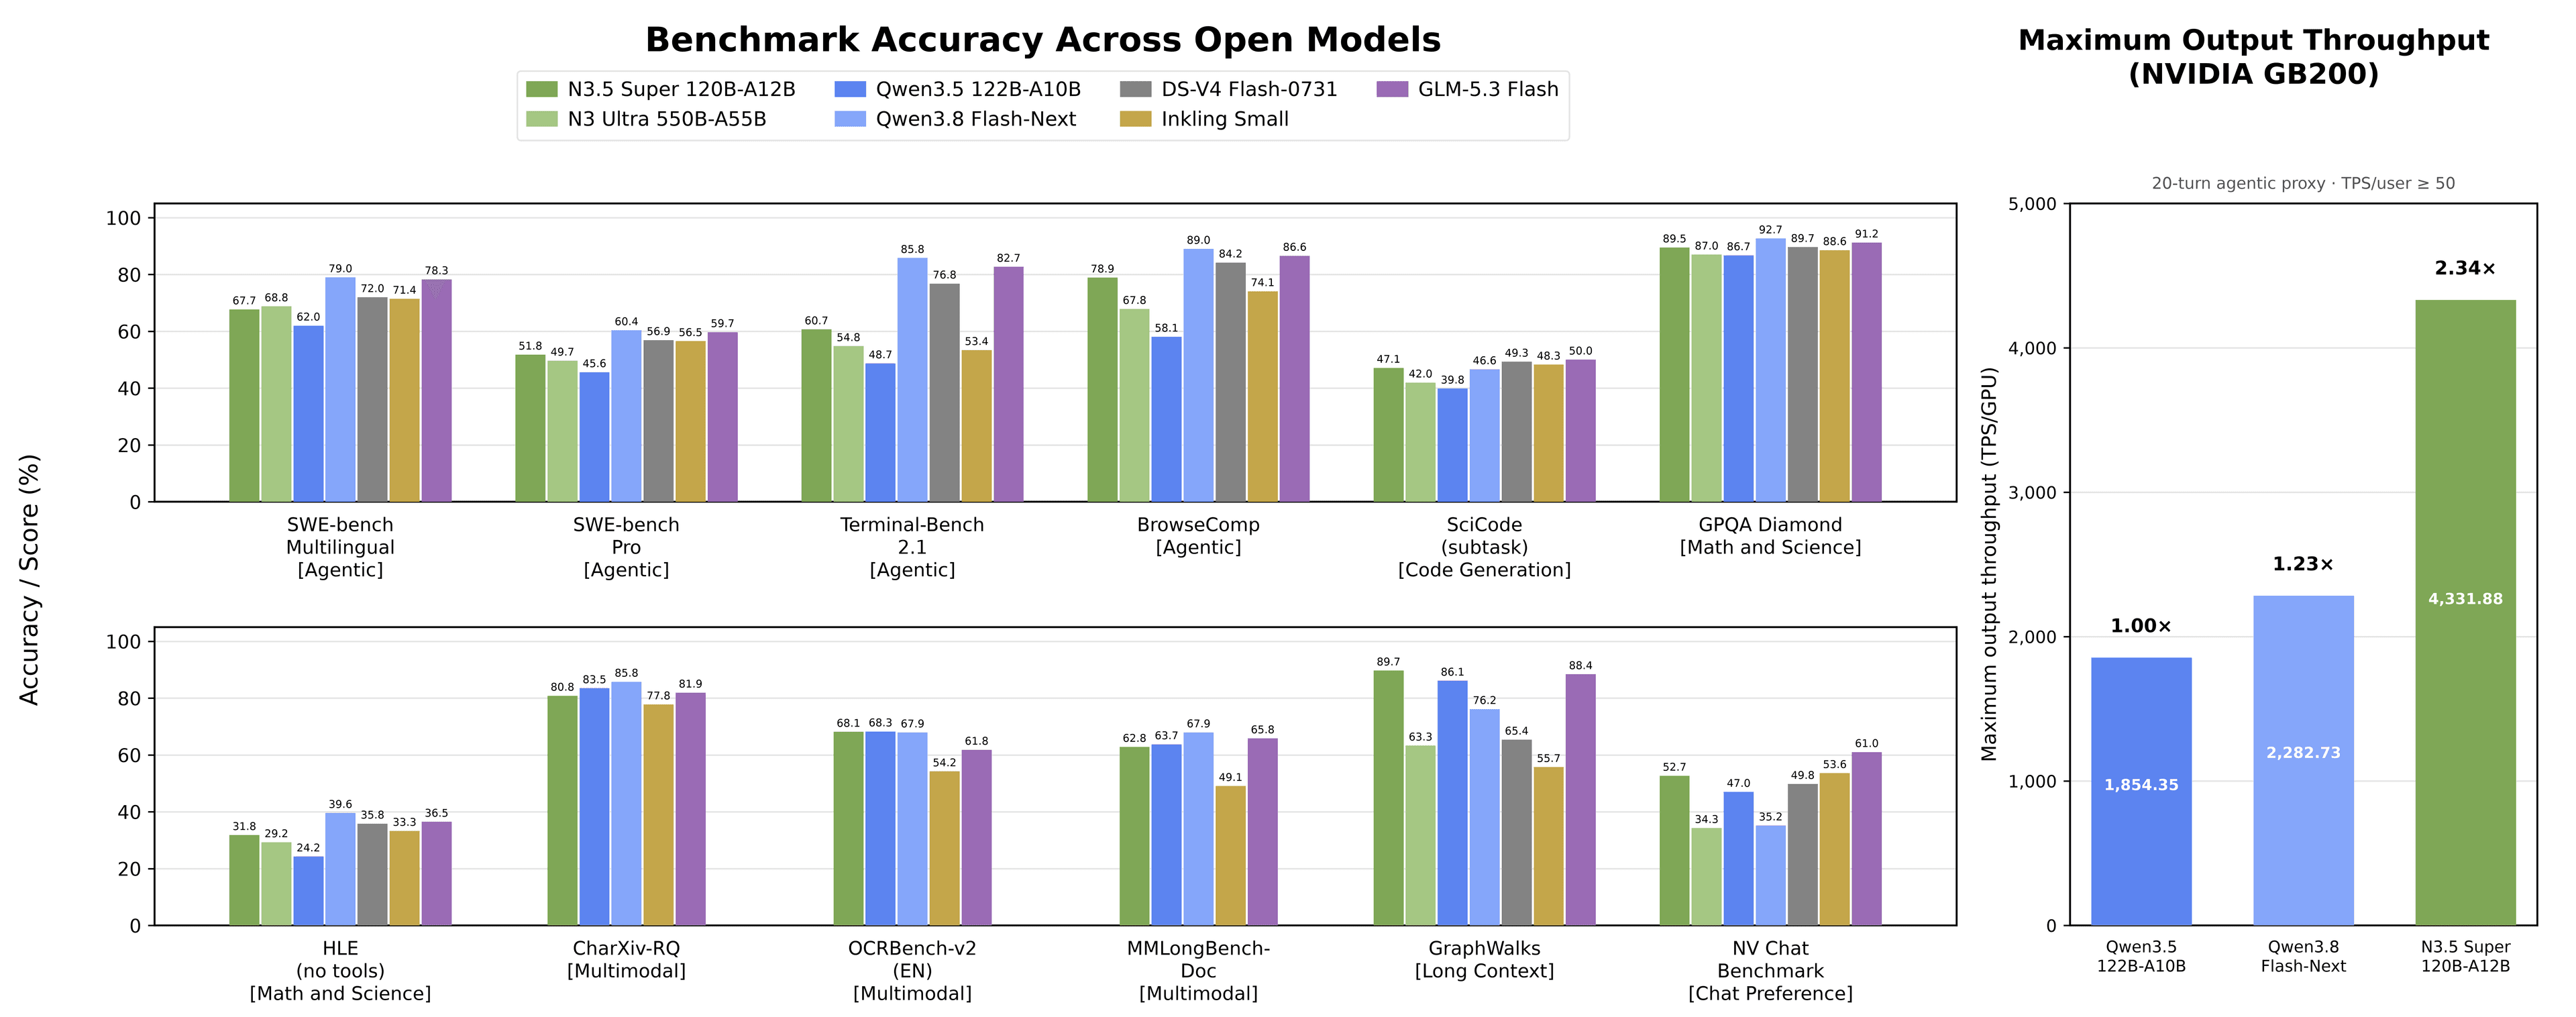
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
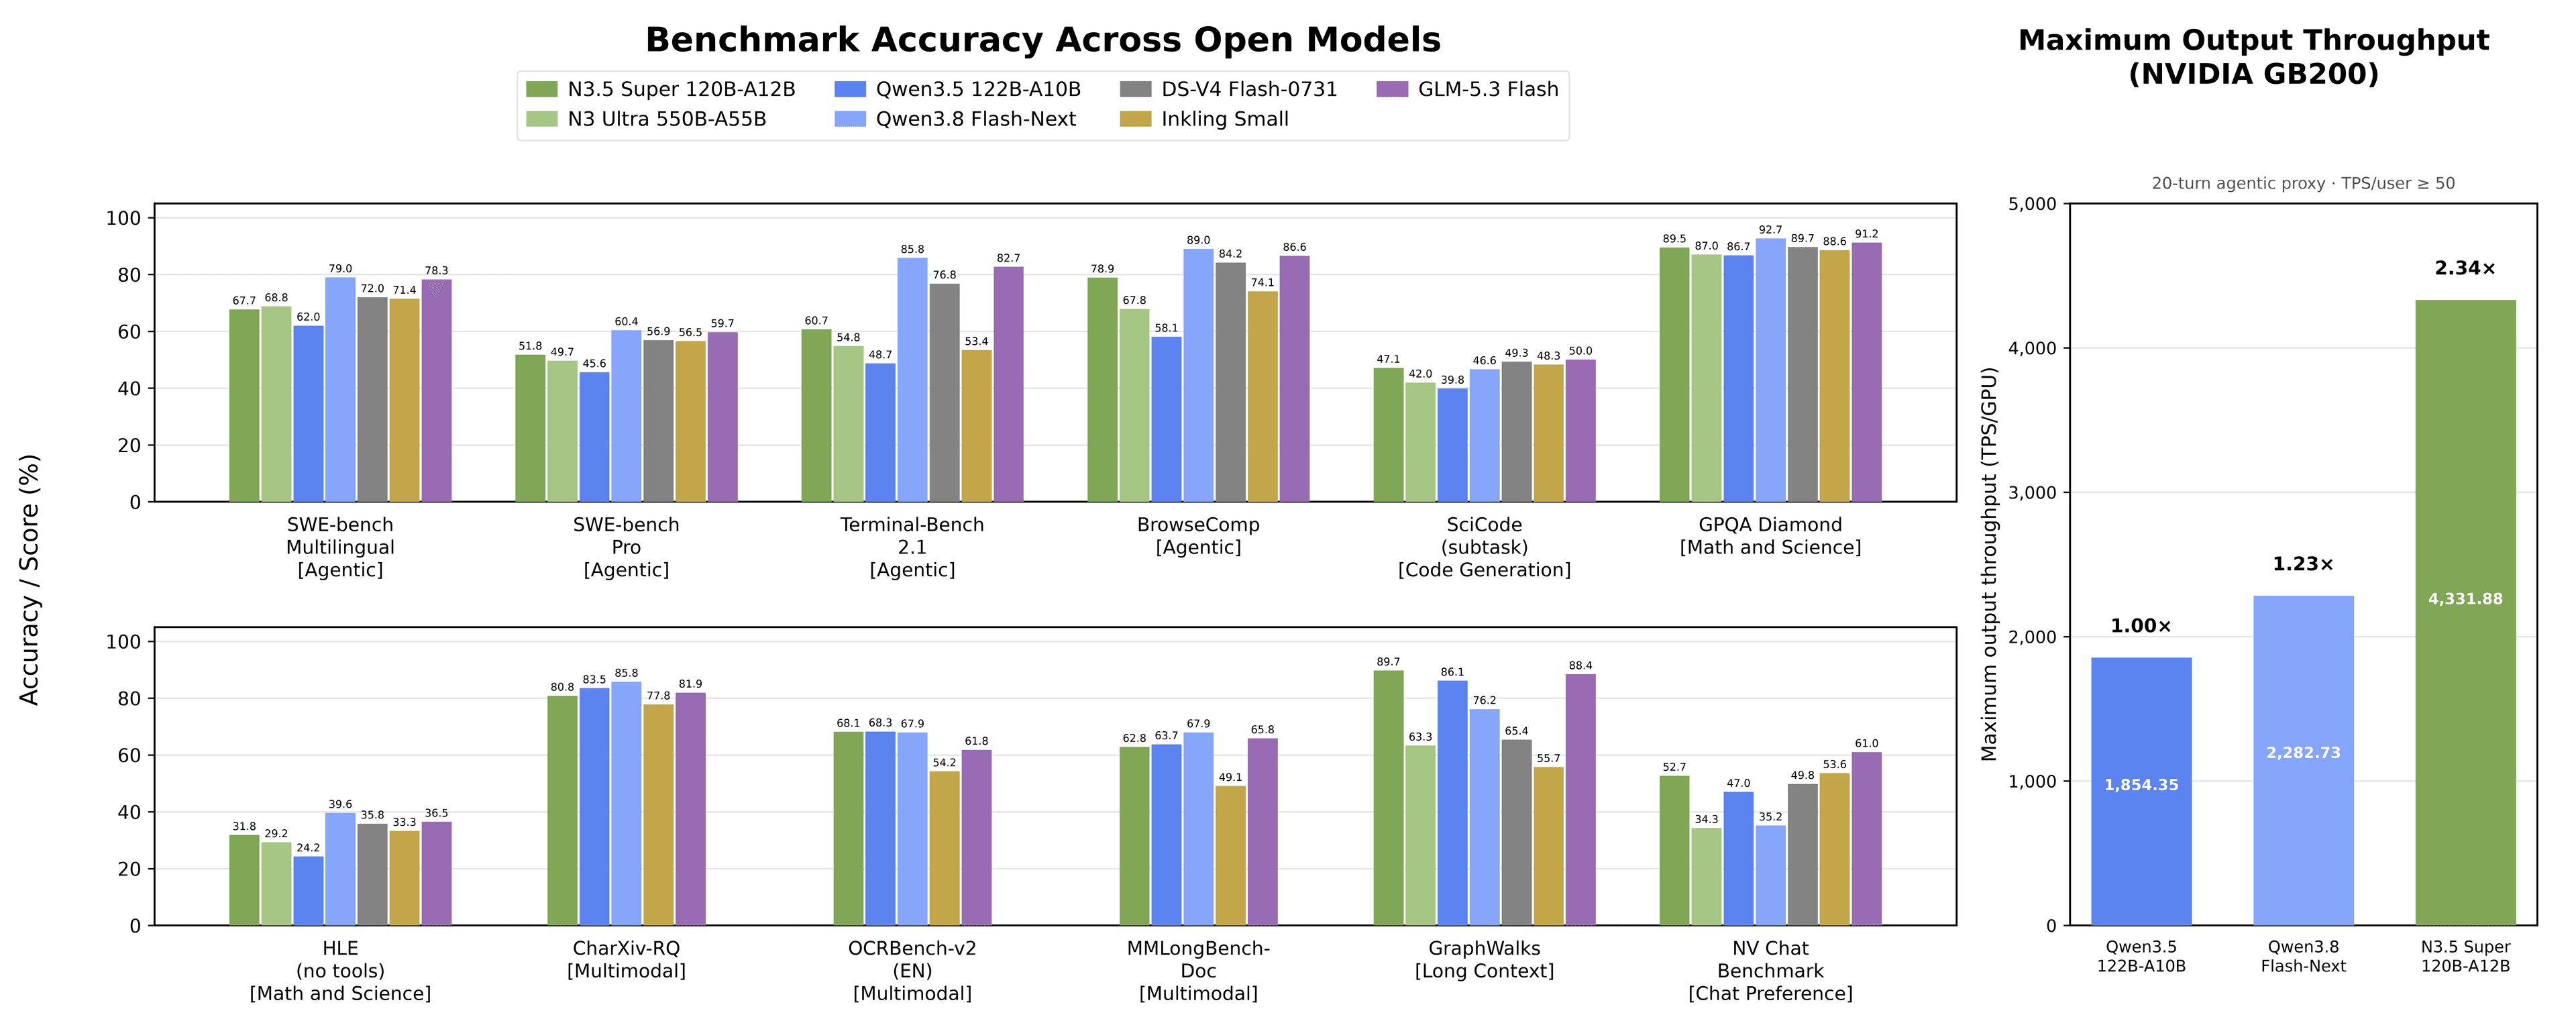
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Text → Video
All Text → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
Kandinsky 6.0 Generates Video and Audio Together
Kandinsky Lab's new foundation models produce synchronized sound and motion from a text prompt, in 3B and 29B sizes.
MiniMax Releases H3 Video Model on Hugging Face
The company's new diffusion model handles text-to-video and image-to-video, with support for joint audio-video generation.
0 comments
No comments yet. Be the first to weigh in.