NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
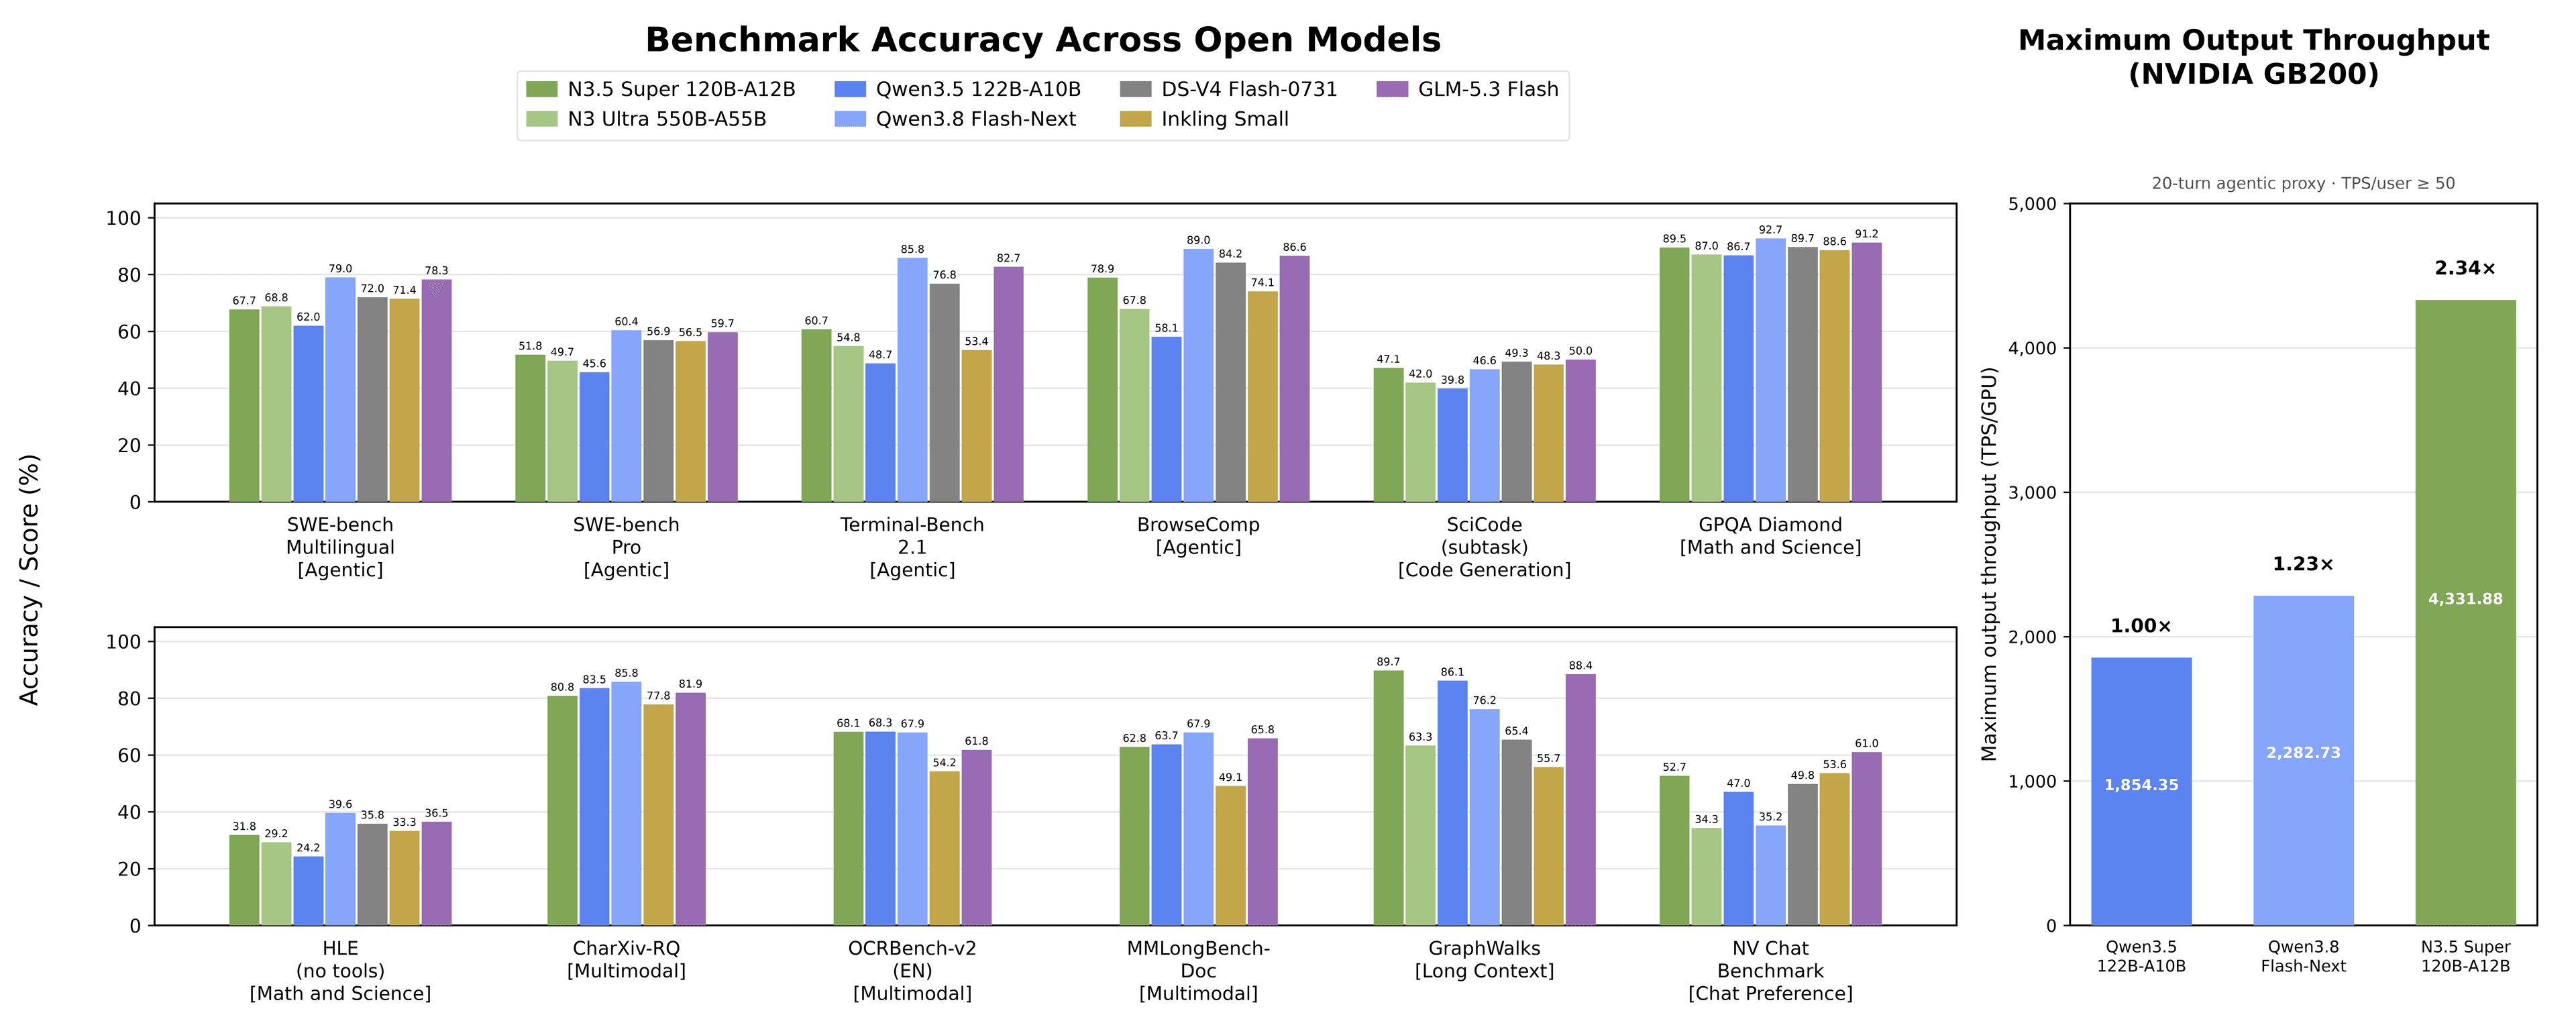
NVIDIA has published Nemotron 3.5 Super VL, a vision-language model built on a mixture-of-experts design, to Hugging Face. The release weighs in at 120 billion total parameters but activates only about 12 billion per token, a configuration NVIDIA labels "120B-A12B."
The model handles both image and text inputs and is described as multilingual, positioning it for document understanding, visual question answering, and other multimodal tasks where broad language coverage matters. It is distributed in BF16 format under a custom NVIDIA license rather than a standard permissive one, so teams should check the terms before deploying.
Why it matters
The appeal of a sparse MoE for vision-language work is cost. By routing each token through a small fraction of its experts, Nemotron 3.5 Super VL can offer the capacity of a large model while keeping the compute footprint closer to that of a 12B dense network.
- 120B total / 12B active: large capacity, lean per-token compute
- Vision + text: multimodal inputs for document and image reasoning
- Multilingual: aimed at use beyond English
As the first entry in the Nemotron 3.5 Super VL line, the model extends NVIDIA's push to supply open-weight building blocks for enterprise AI. Details on context length and benchmark results will be worth watching as the model card and community evaluations mature.
Sources
- Visit
nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
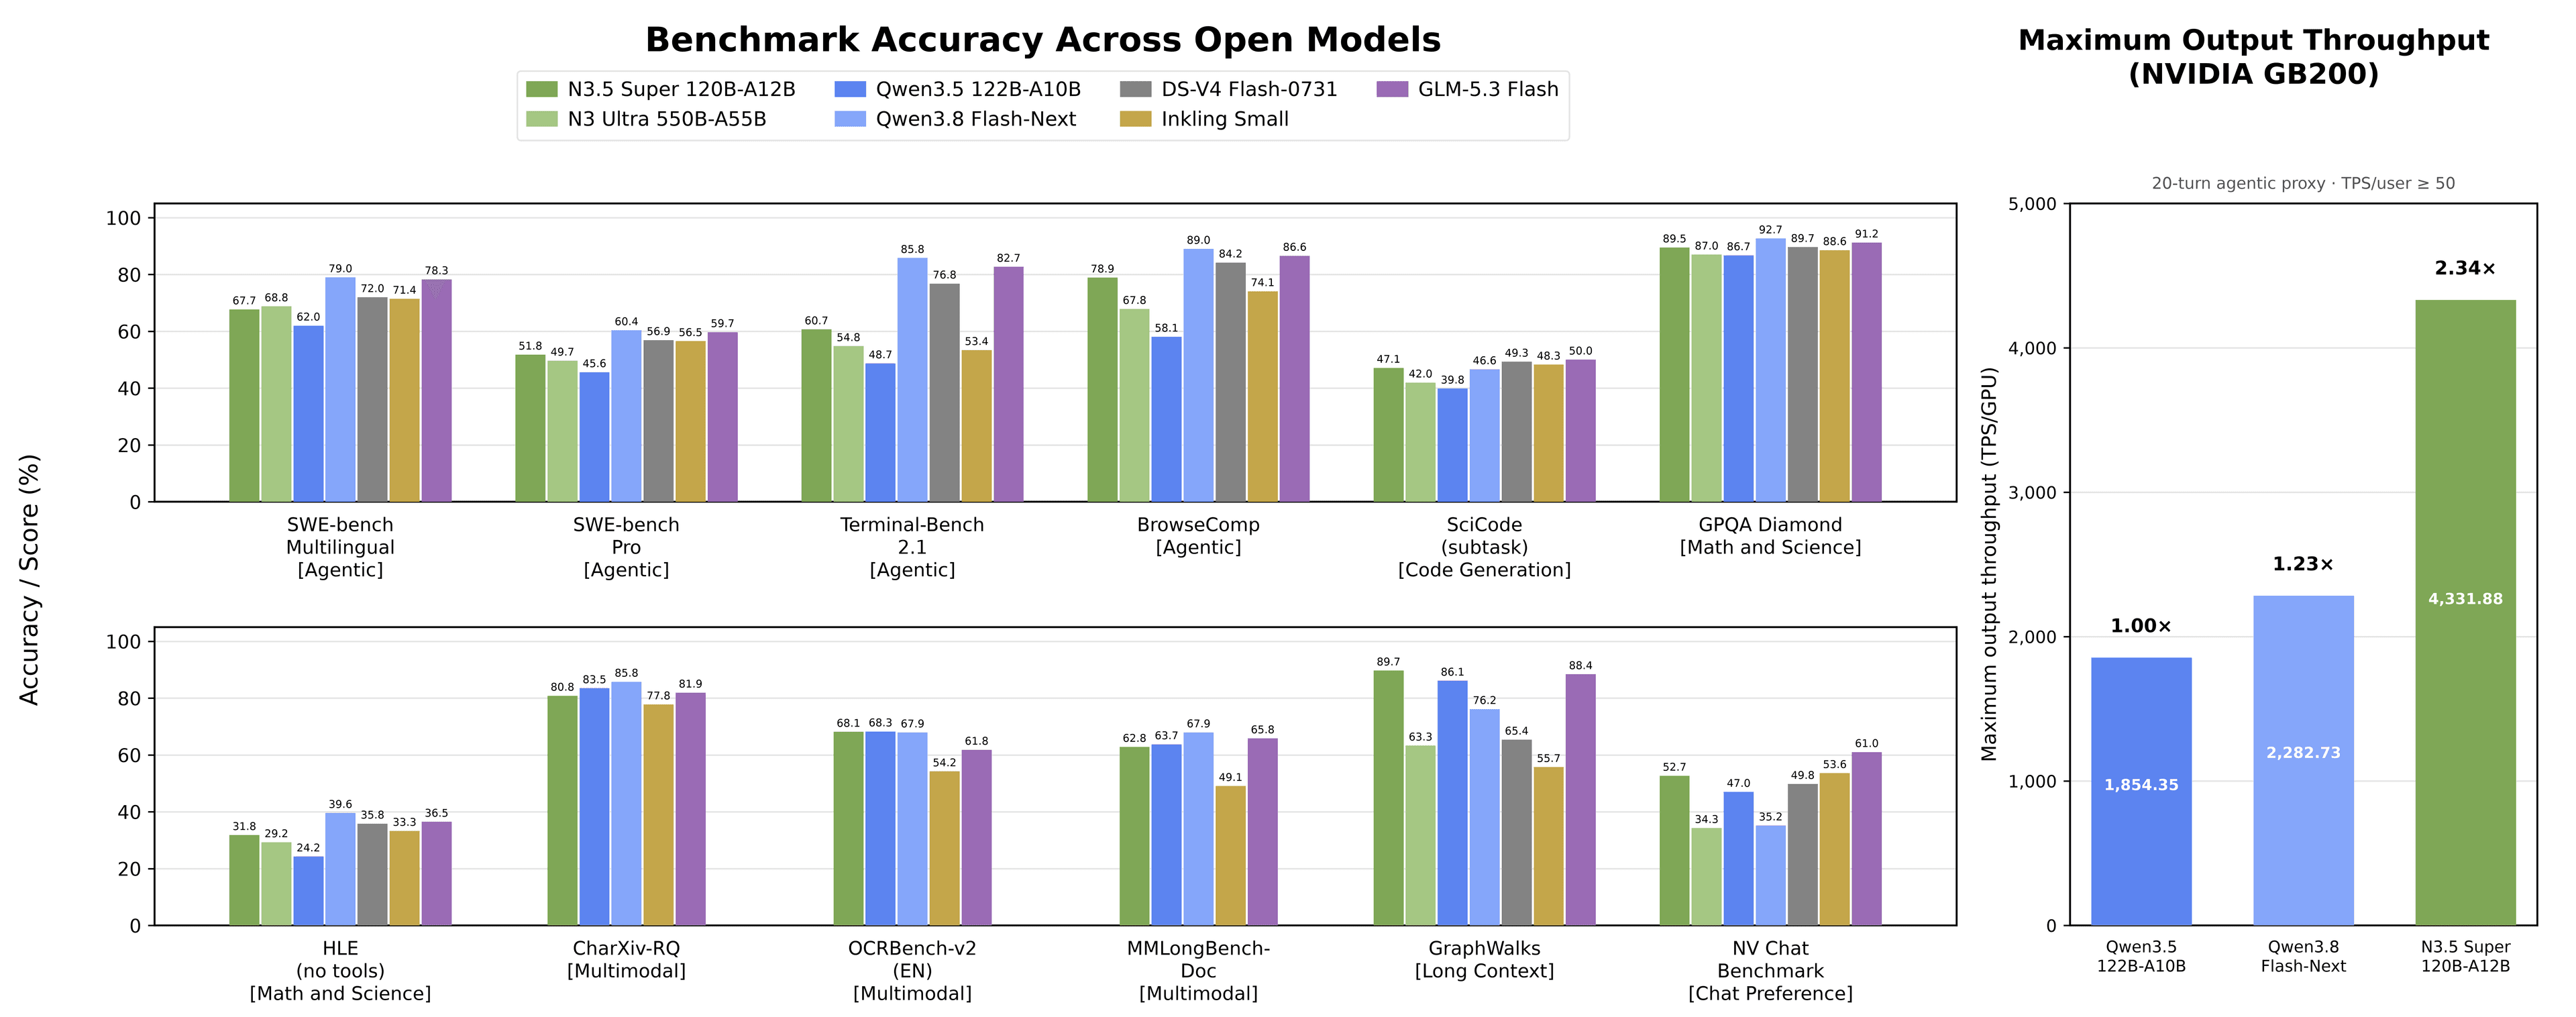
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
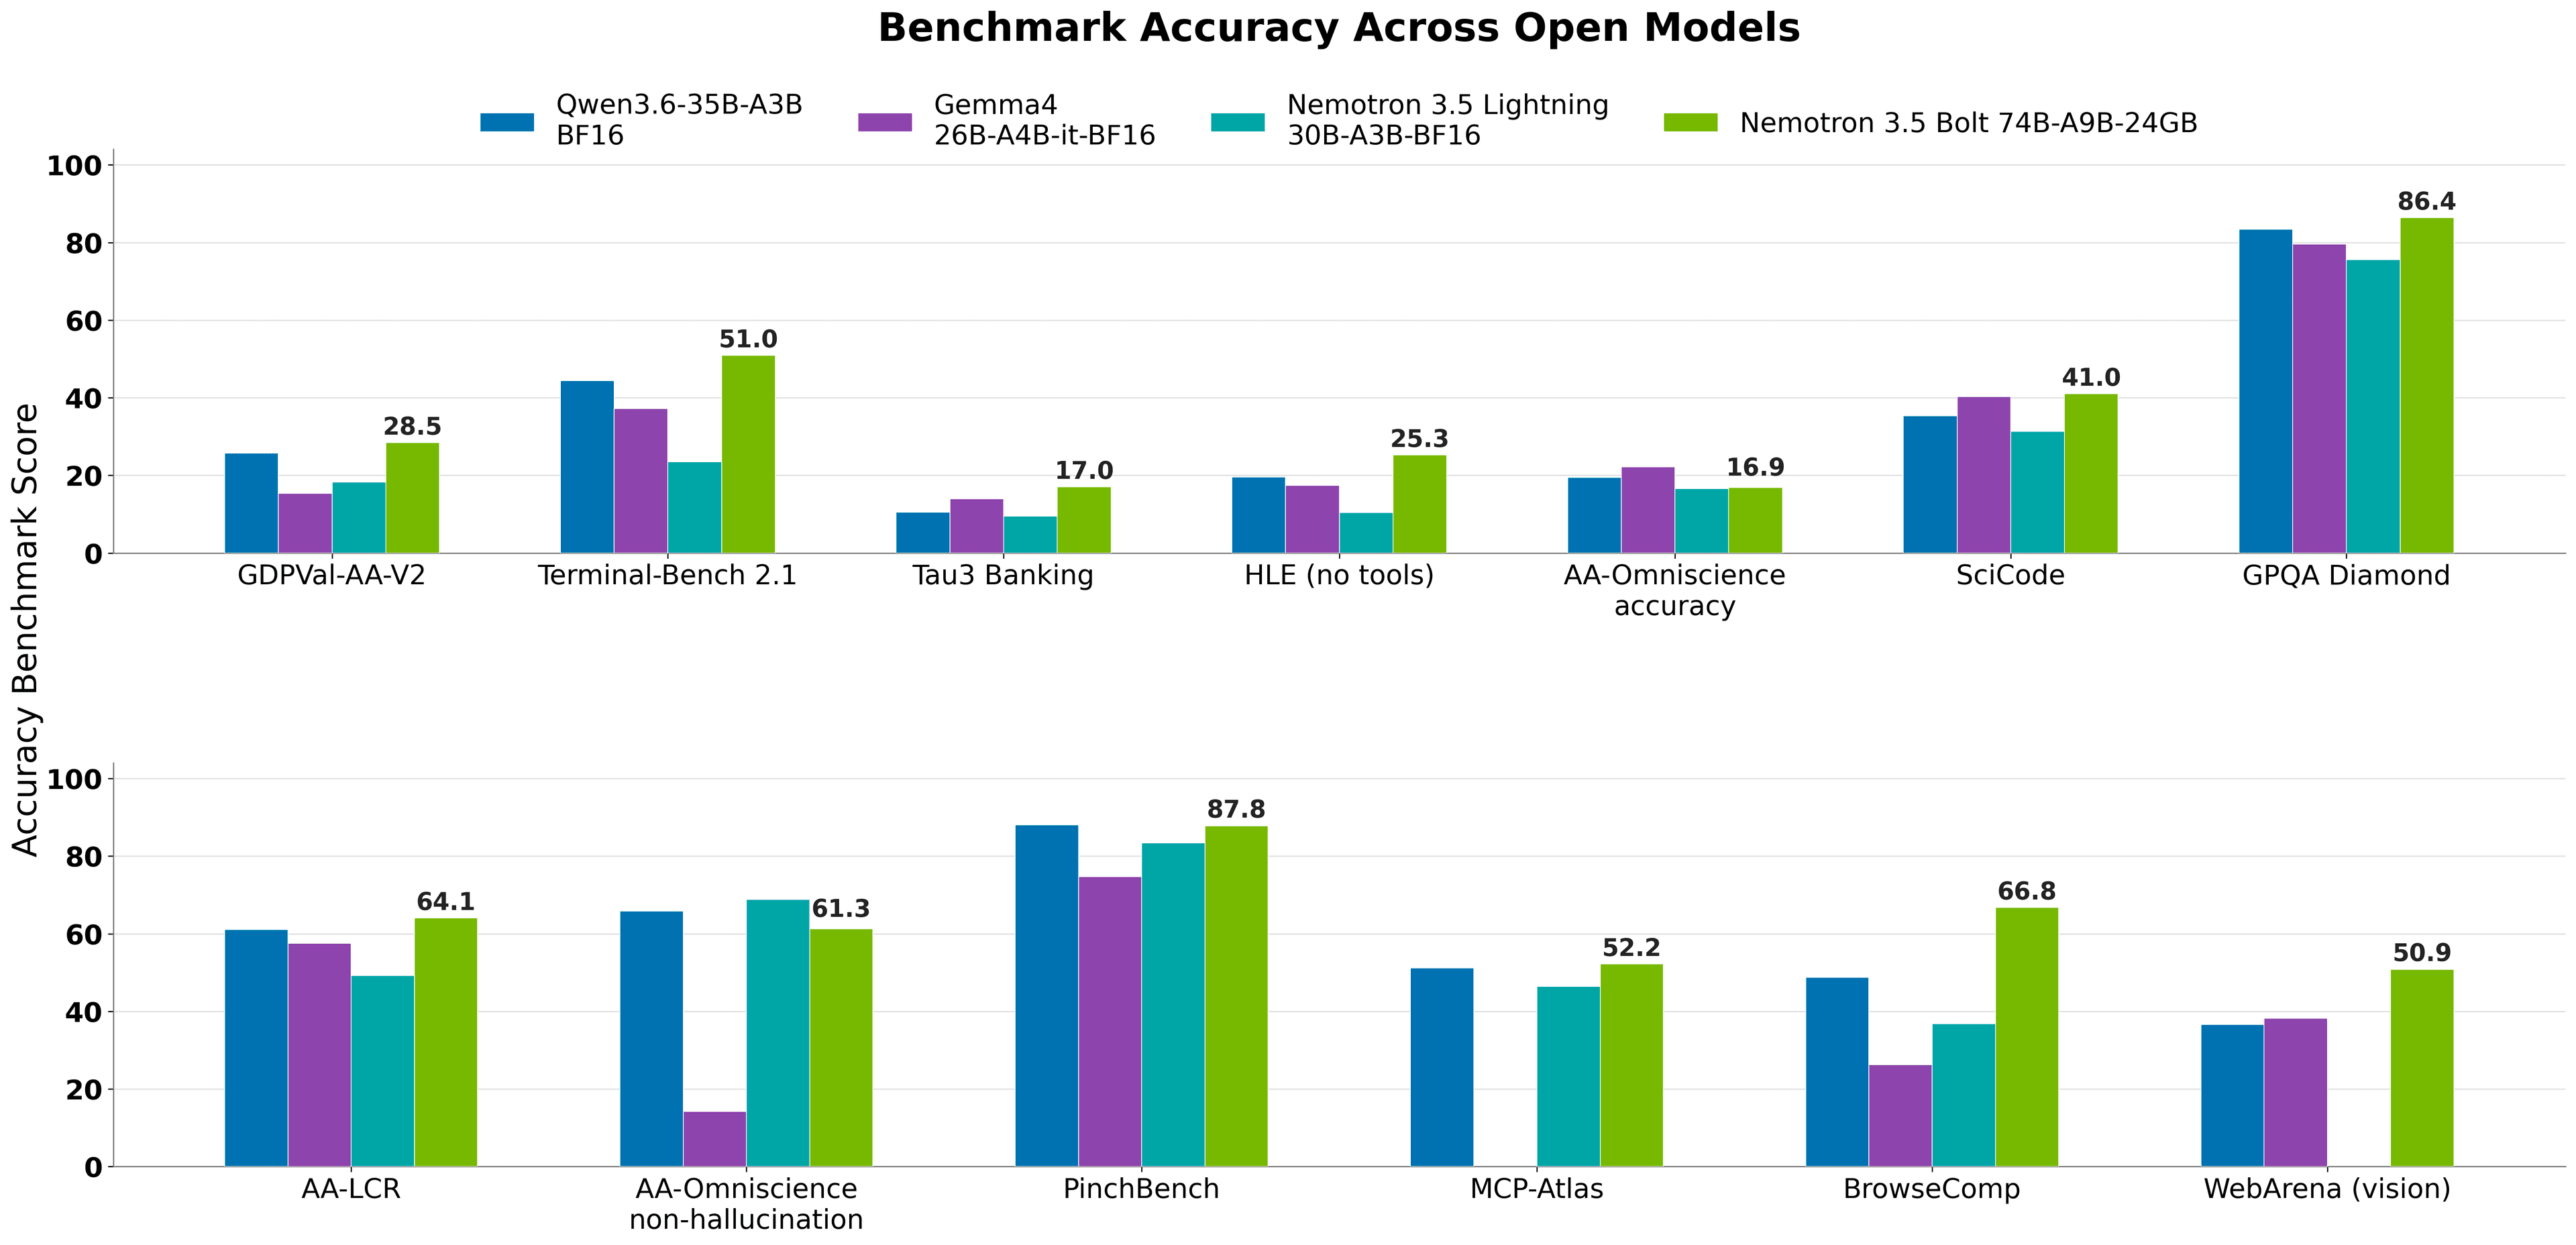
NVIDIA's Nemotron-3.5 Bolt targets 24GB GPUs
A multimodal mixture-of-experts model with 74B total parameters but just 9B active, tuned to fit consumer-class hardware.
More in Vision-Language
All Vision-Language →
DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
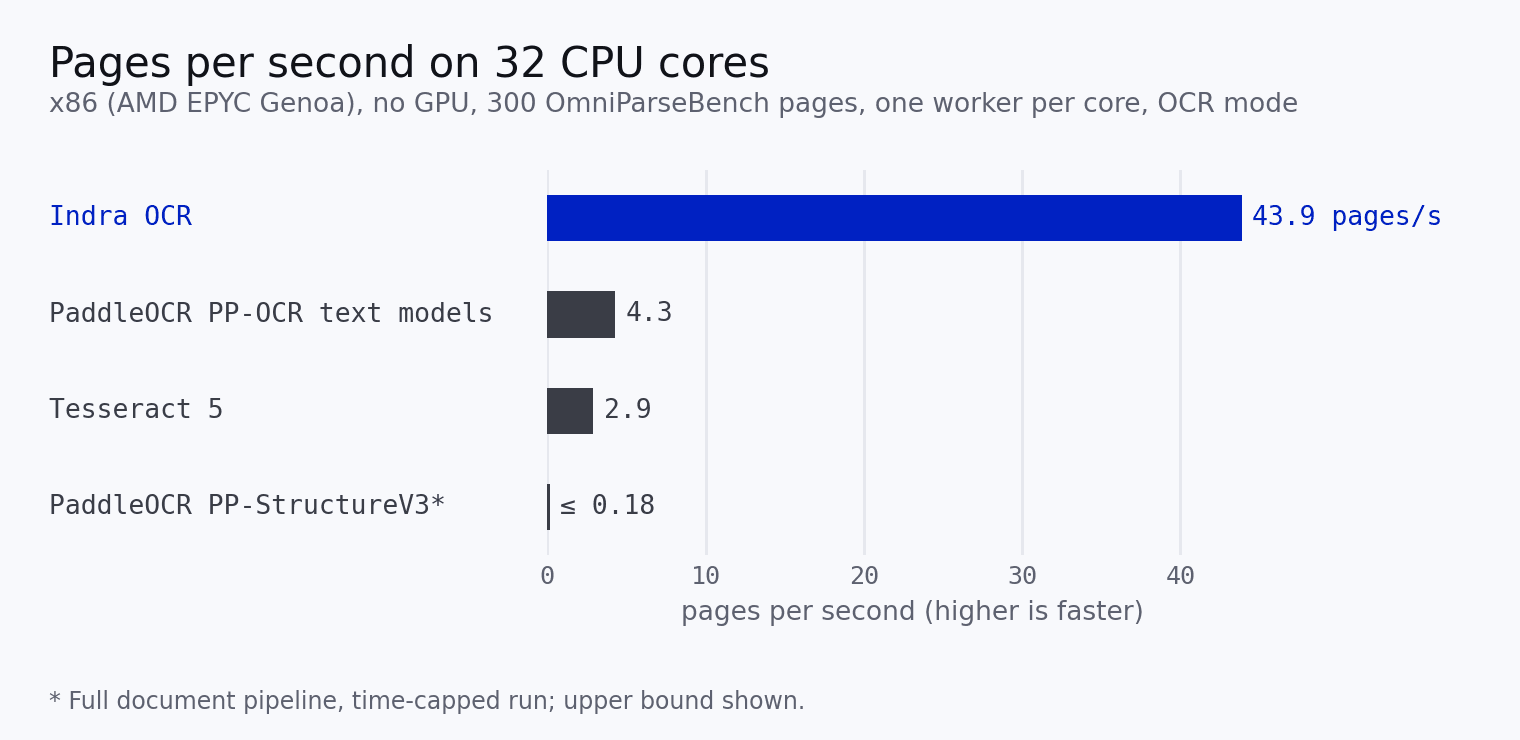
Indra OCR brings CPU-friendly document parsing
A new open vision-language model targets layout, handwriting and multilingual text extraction without a GPU.
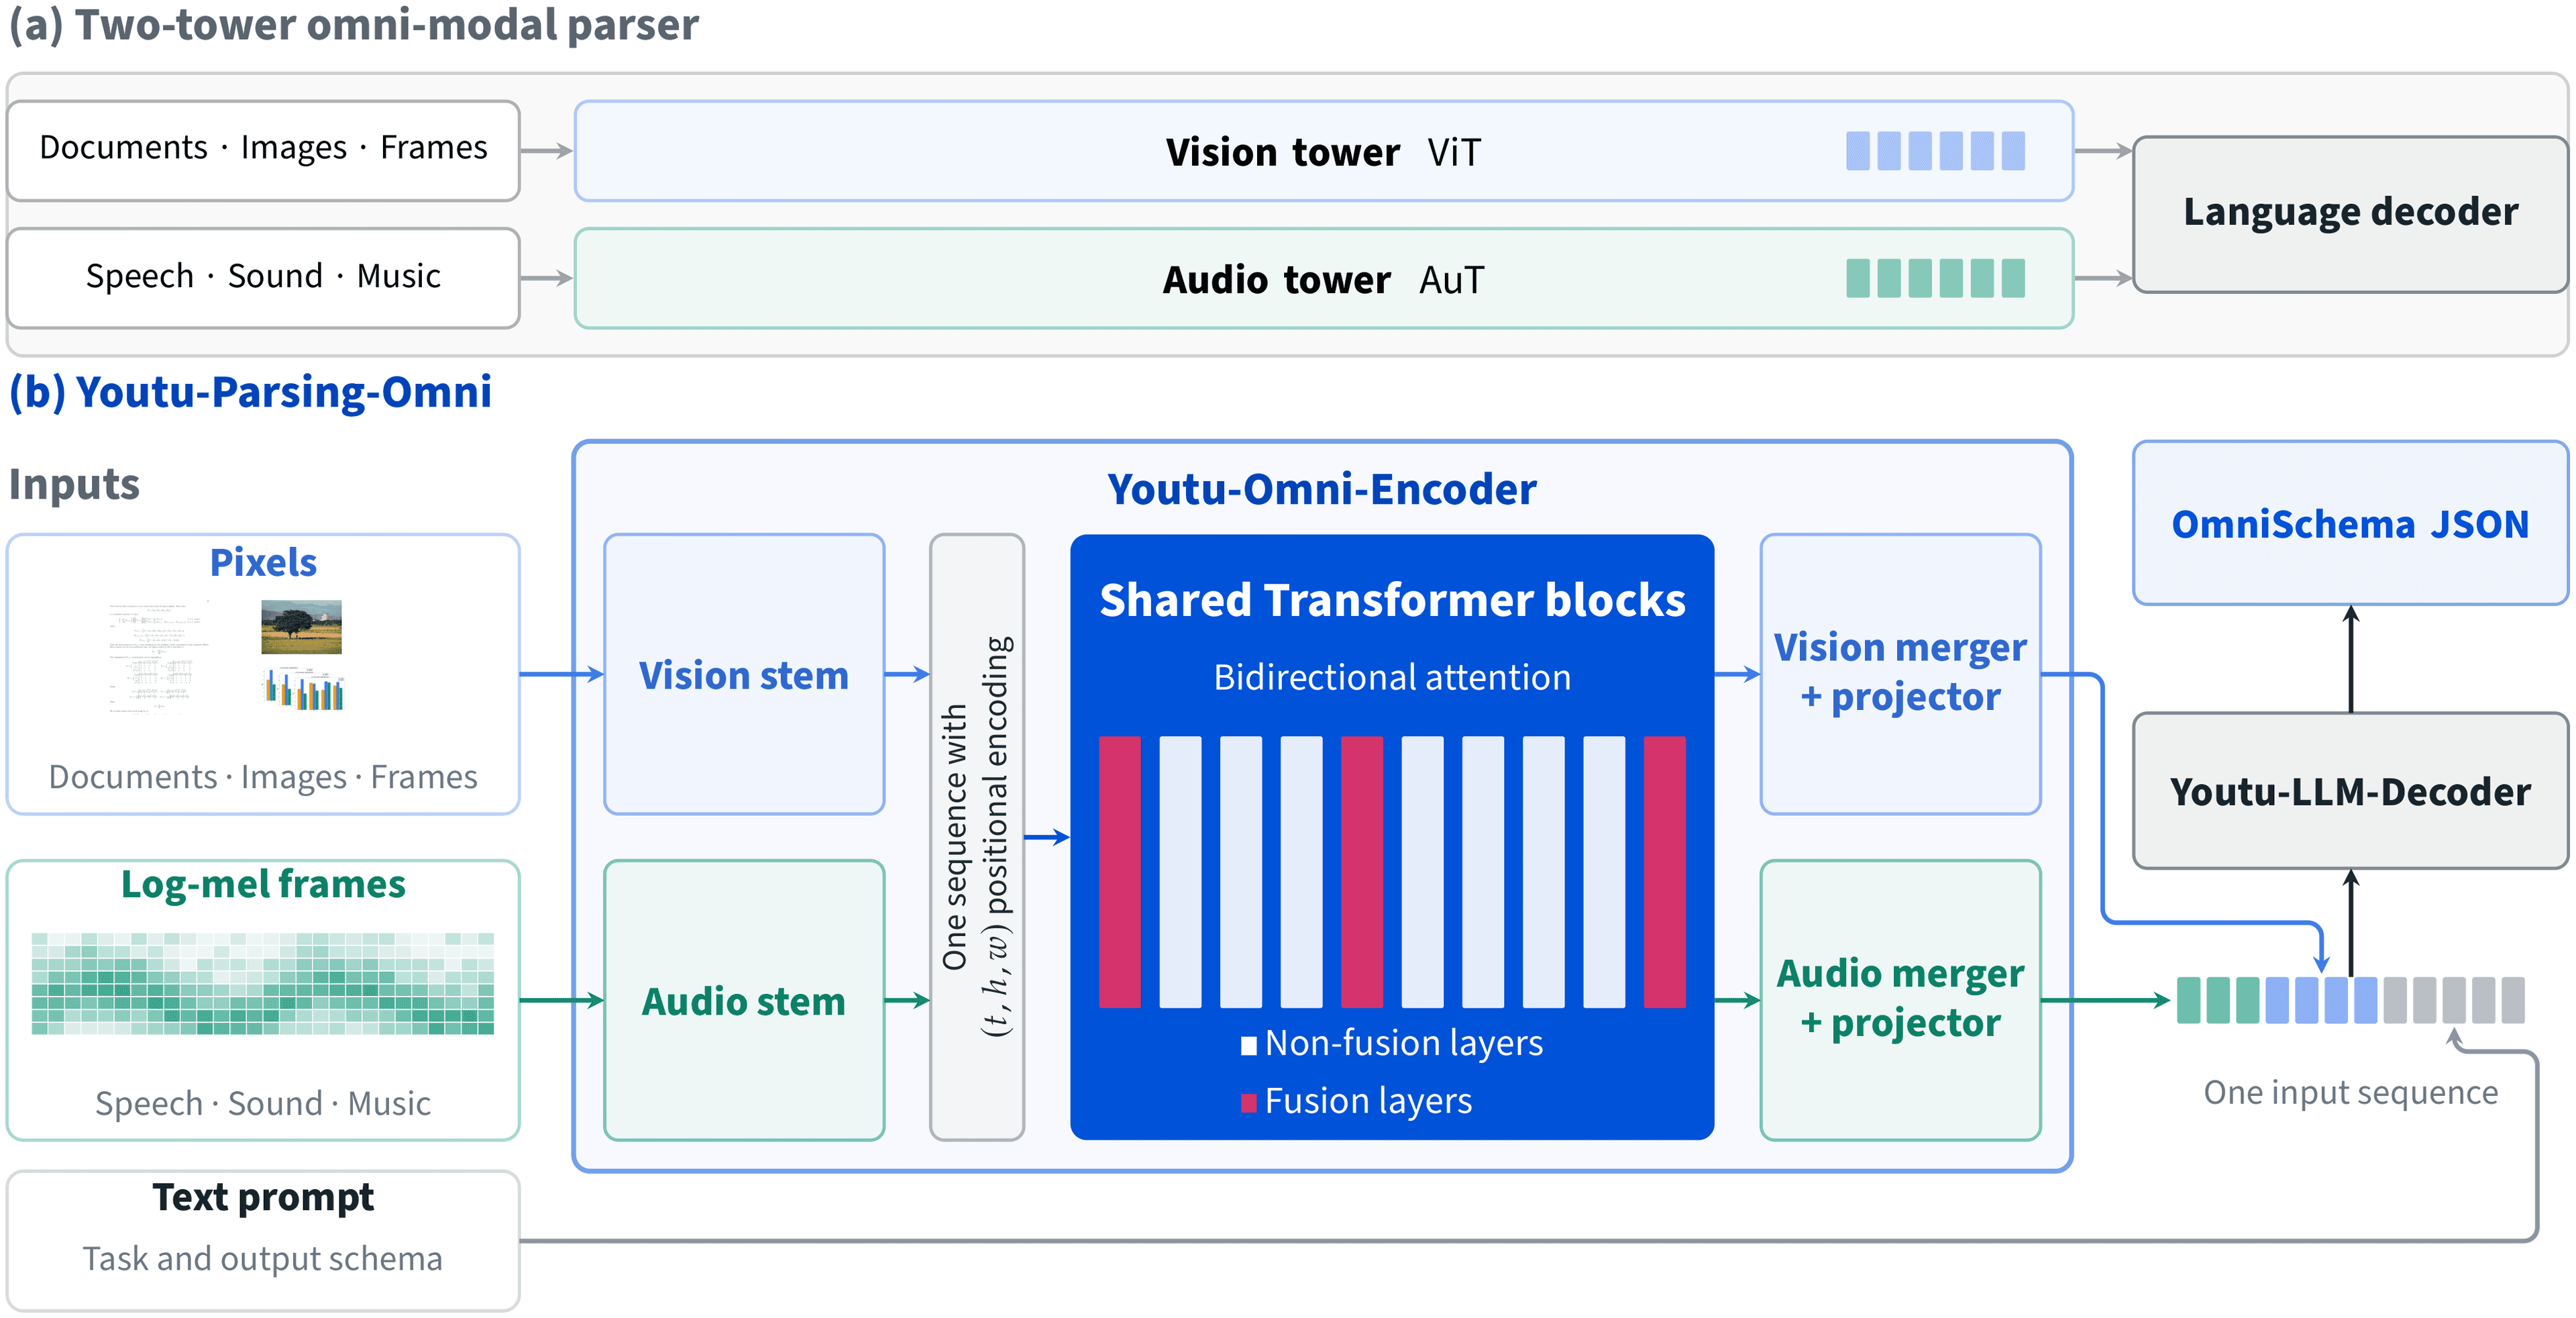
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
0 comments
No comments yet. Be the first to weigh in.