The Open Weights
LatestModelsLeaderboardsCompanies
Subscribe
The Open Weights

The daily record of open-source AI. New model releases, leaderboards, and what's coming next — written for people who ship.

Refreshed every 12 hours

Discover

  • Latest releases
  • New today
  • Trending models

Browse

  • All models
  • Companies
  • Categories
  • Leaderboards

About

  • About
  • Editorial policy
  • Hardware estimates
  • RSS feed
  • llms.txt
  • Newsletter

© 2026 The Open Weights. An independent publication.

PrivacyTermsSMSAggregated by Claude · curated by humans.
NVIDIA logo

Company

NVIDIA

36 modelsUS
CategoriesText / LLMVision-LanguageSpeech → TextAny-to-AnyText → SpeechEmbeddingsText → VideoText → ImageImage → VideoImage Editing

Releases

NVIDIA/Text / LLMRuns on a laptop

NVIDIA releases compact Dory 1.0 4B text model

The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.

Oct 16, 2026
Text / LLM
Nemotron Labs Dory 1.0 4B
NVIDIA/Vision-LanguageWorkstation GPU

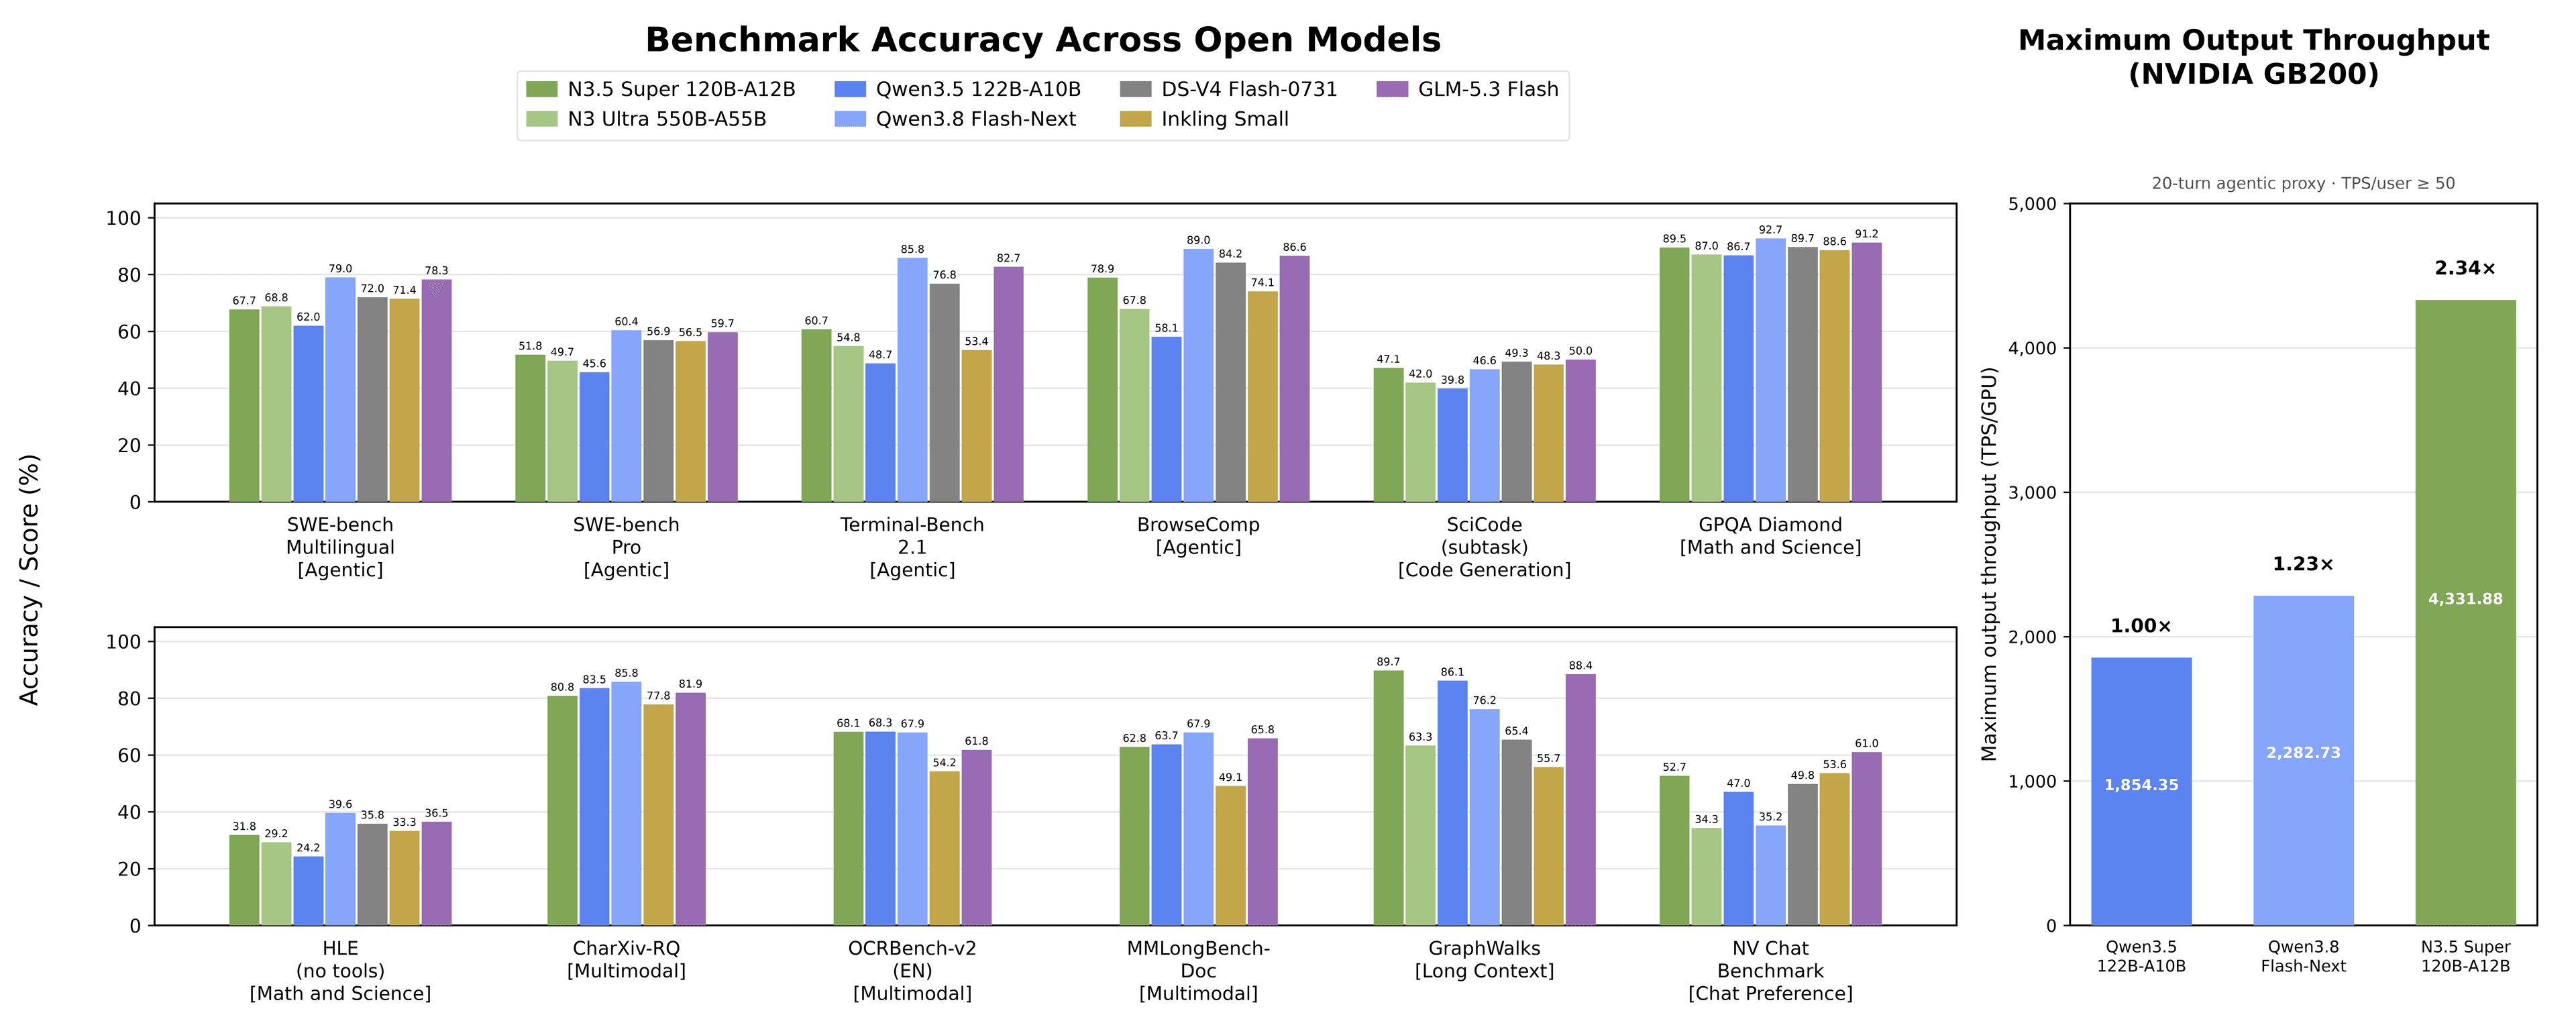
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency

The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.

Oct 12, 2026
Vision-LanguageText / LLM
Nemotron-3.5-Super-VL-120B-A12B
NVIDIA/Vision-LanguageWorkstation GPU

NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE

The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.

Oct 12, 2026
Vision-LanguageText / LLM
Nemotron-3.5-Super-VL-120B-A12B
NVIDIA/Speech → TextWorkstation GPU

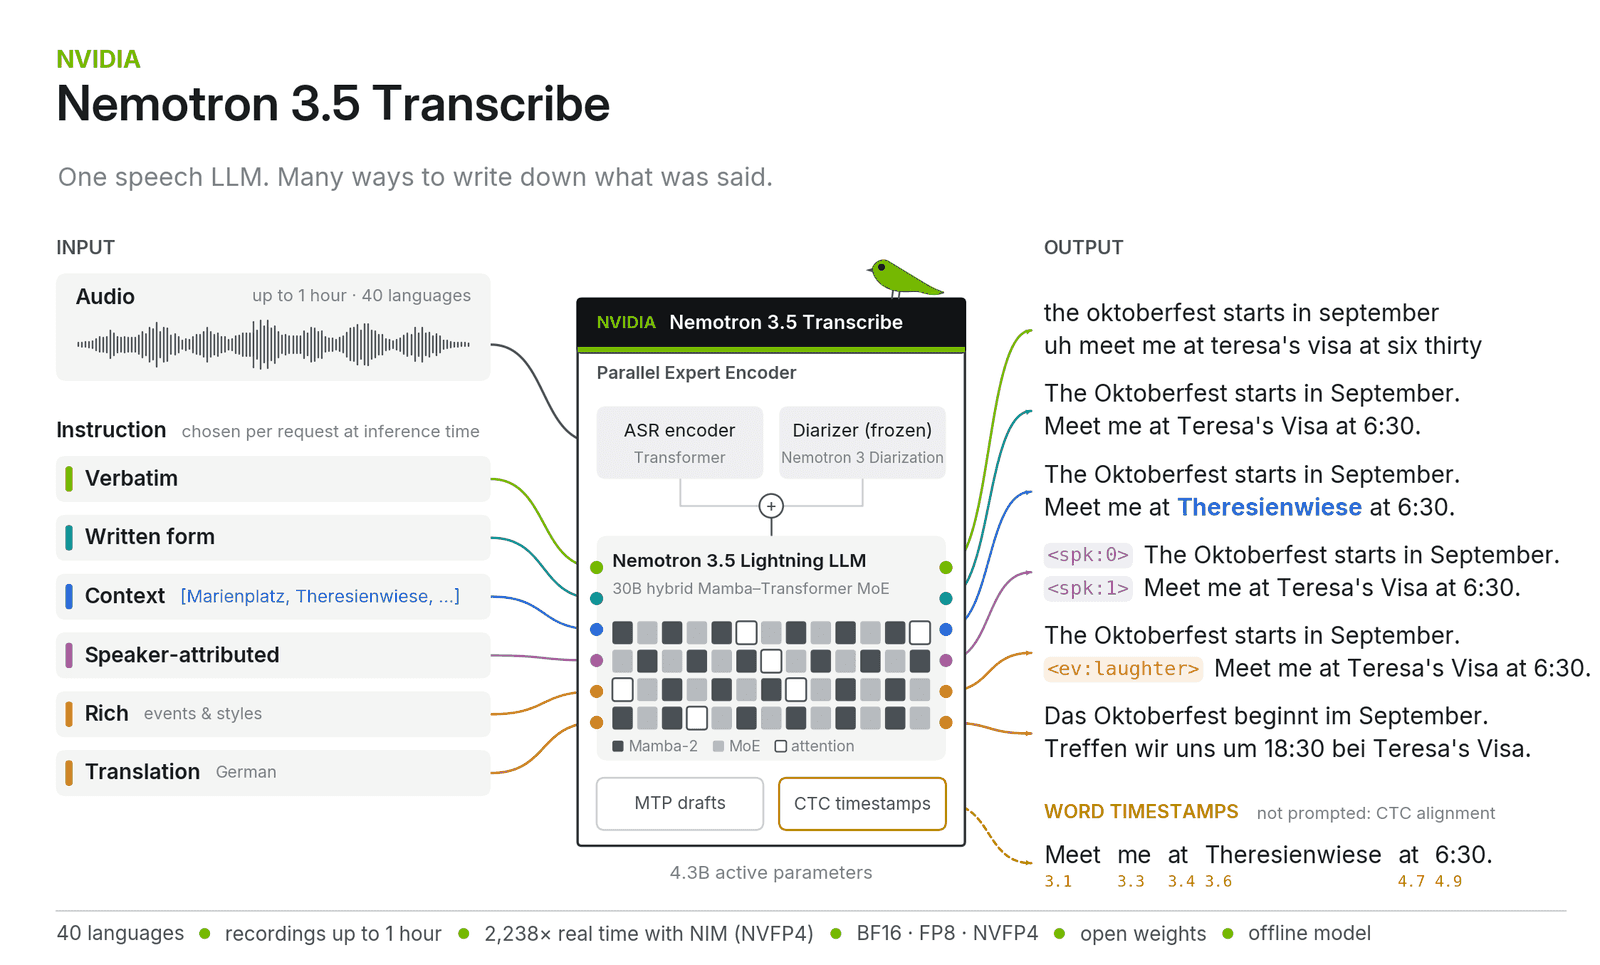
NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR

A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.

Oct 7, 2026
Speech → Text
Nemotron 3.5 Transcribe 30B-A4B
NVIDIA/Vision-LanguageWorkstation GPU

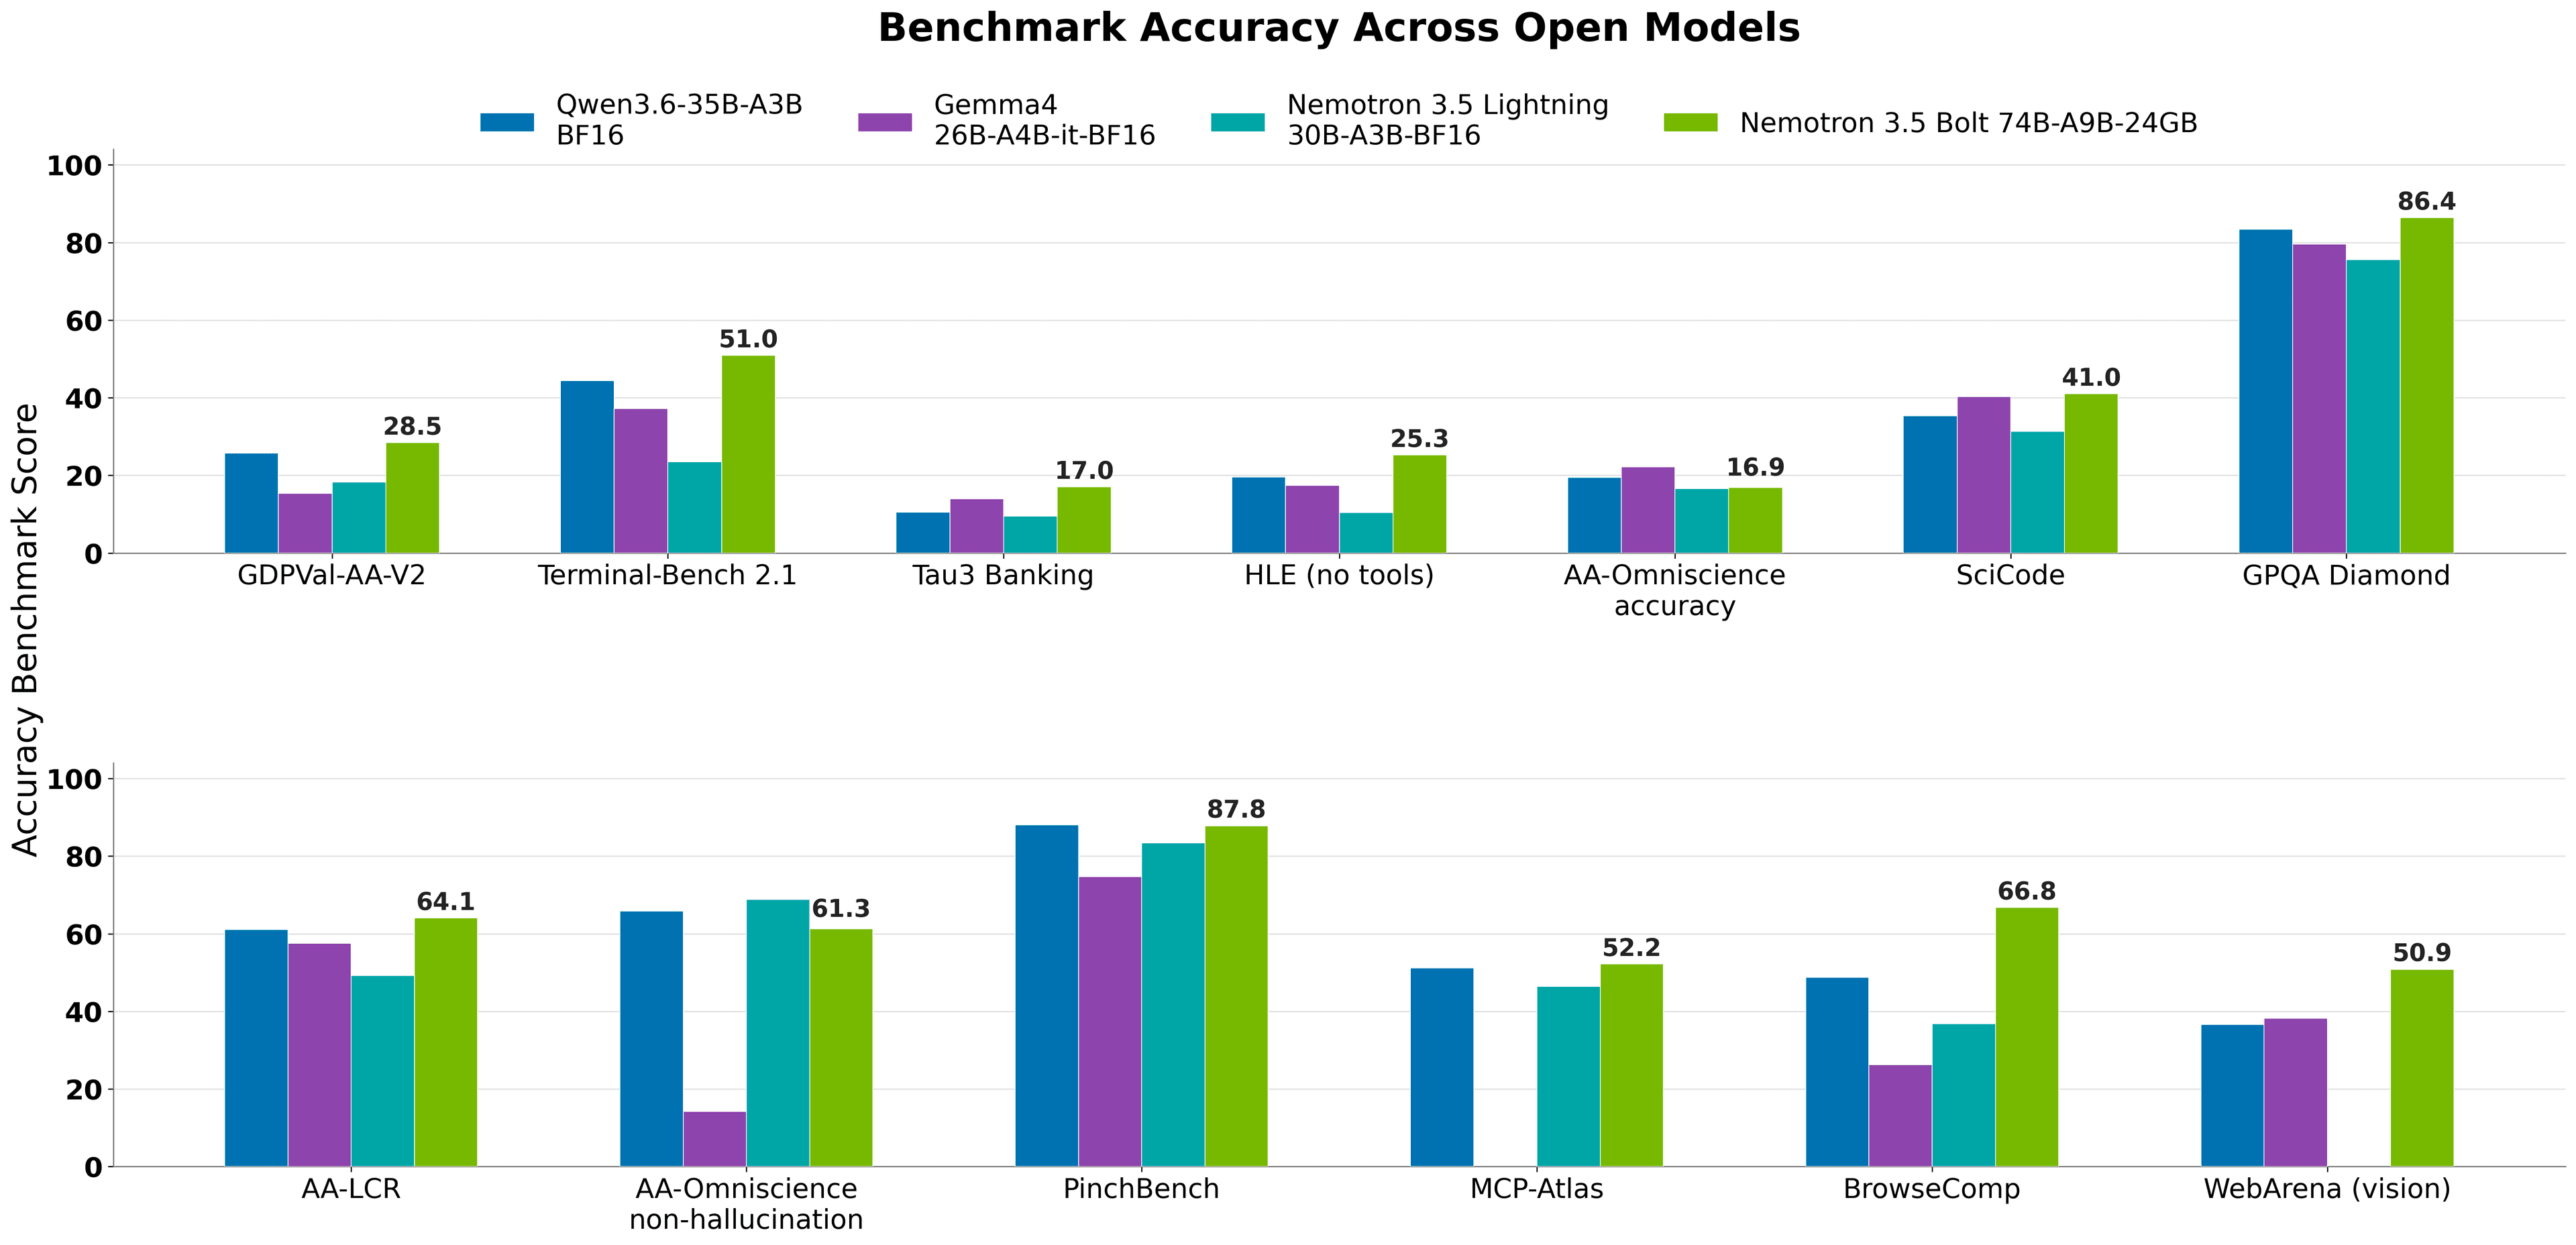
NVIDIA's Nemotron-3.5 Bolt targets 24GB GPUs

A multimodal mixture-of-experts model with 74B total parameters but just 9B active, tuned to fit consumer-class hardware.

Oct 7, 2026
Vision-LanguageText / LLM
Nemotron-3.5 Bolt 74B-A9B
NVIDIA/Speech → Text

TII Brings Falcon to Speech With New ASR Model

The team behind the Falcon language models expands into speech-to-text with its first automatic speech recognition release.

Oct 7, 2026
Speech → Text
NVIDIA/Text / LLM

Falcon-Emirati tunes an LLM for local dialect

TII's Falcon family gets a variant built around Emirati Arabic, aiming at culture and nuance rather than generic Gulf Arabic.

Oct 6, 2026
Text / LLM
NVIDIA/Text / LLMRuns on a laptop

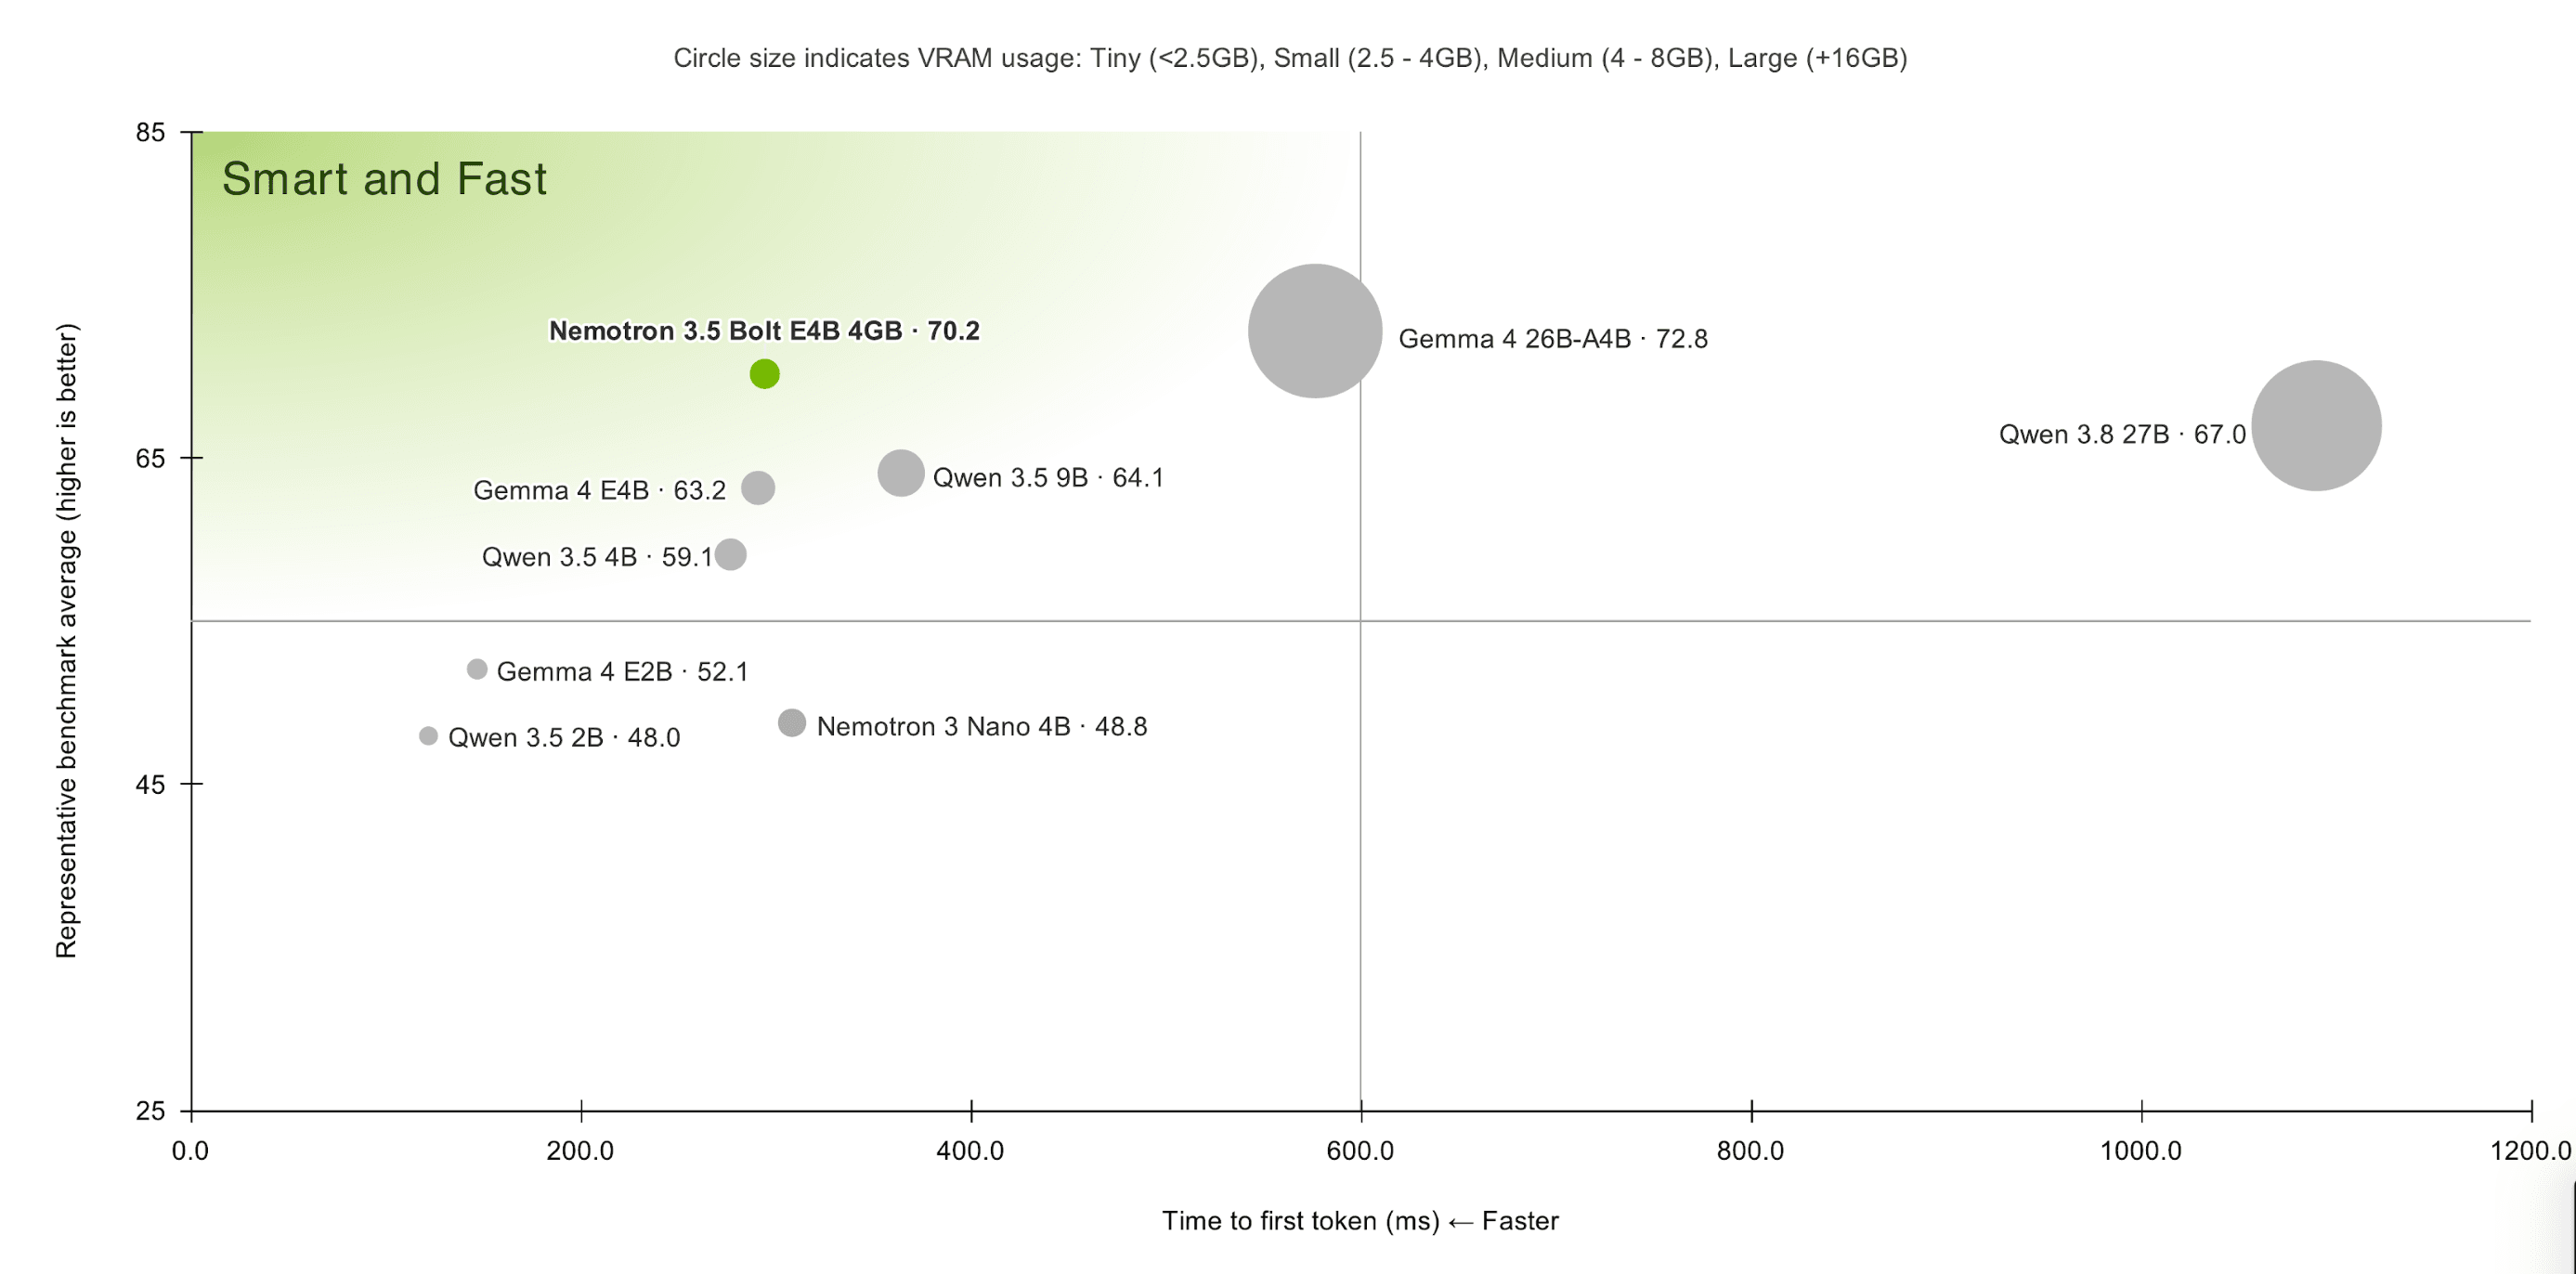
NVIDIA's Nemotron 3.5 Bolt Targets 4GB Devices

The compact 4-billion-parameter text model is tuned for multilingual work on memory-constrained hardware.

Oct 5, 2026
Text / LLM
Nemotron 3.5 Bolt E4B
NVIDIA/Vision-LanguageRuns anywhere

NVIDIA's Nemotron 3.5 Parse Targets Document OCR

A new vision-language model from NVIDIA is tuned specifically for reading and structuring documents rather than general chat.

Sep 3, 2026
Vision-Language
Nemotron 3.5 Parse
NVIDIA/Speech → TextRuns anywhere

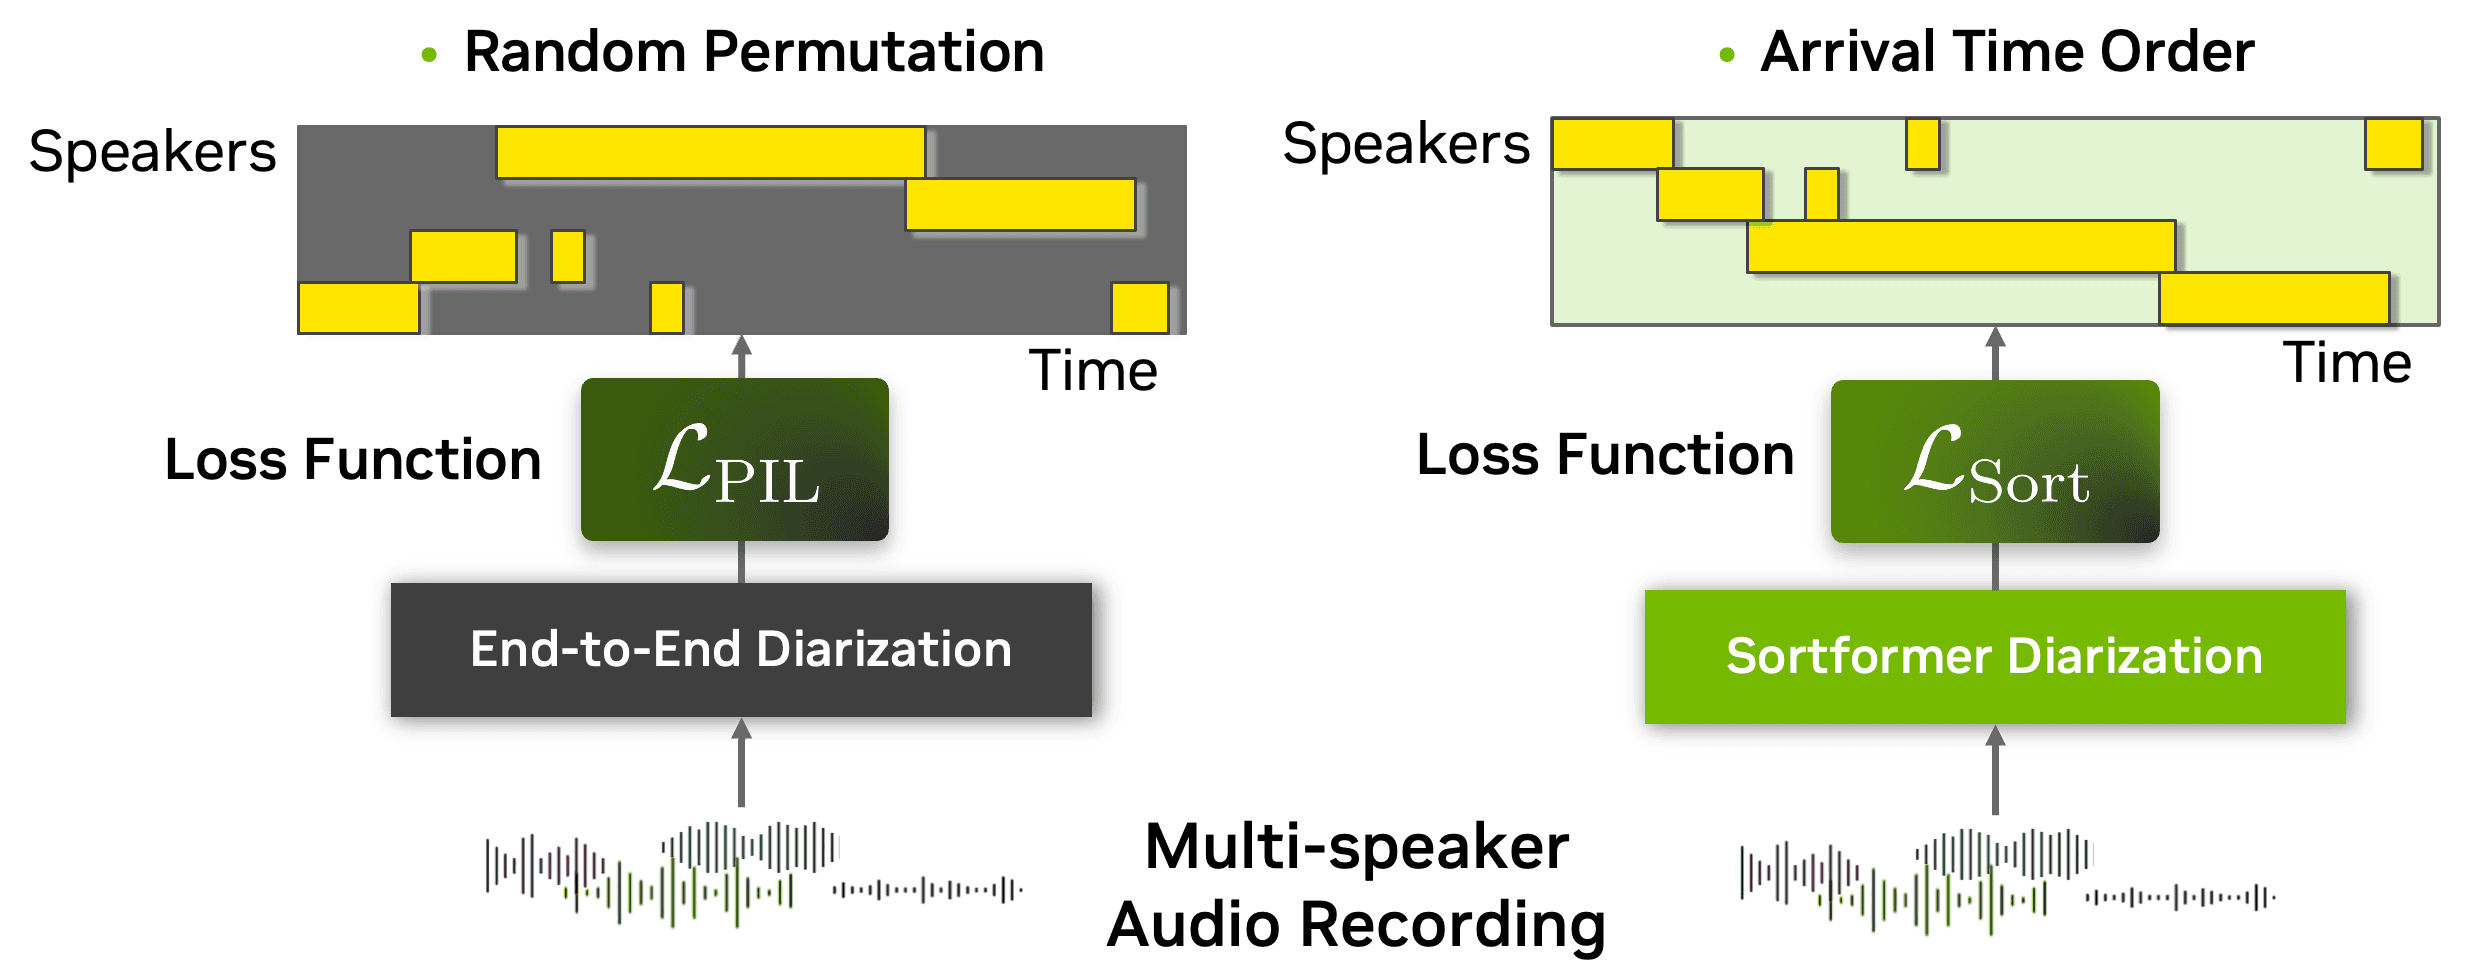
NVIDIA's Nemotron-3 Brings Streaming Speaker Diarization

The new open model applies NVIDIA's Sortformer approach to identify who's speaking, in real time.

Sep 1, 2026
Speech → Text
Nemotron-3-Diarization
NVIDIA/Any-to-Any

NVIDIA's Kumo Takes Aim at Tabular Prediction

A new foundation model targets structured data, where spreadsheets and databases still dominate real-world machine learning.

Sep 1, 2026
Any-to-Any
Kumo Tabular
NVIDIA/Text / LLM

Liquid AI's LFM2.5-DSpark targets faster inference

The new efficient language model claims up to 3.2x faster inference, extending Liquid AI's push toward lean, deployable models.

Aug 20, 2026
Text / LLM
NVIDIA/Text → Speech

NVIDIA Opens Magpie TTS for Multilingual Voice Agents

The open-weights text-to-speech model targets low-latency, deployable voice agents across multiple languages.

Aug 10, 2026
Text → Speech
NVIDIA/Text → Speech

NVIDIA opens Magpie TTS for multilingual voice agents

The company releases open weights for a low-latency, multilingual text-to-speech model aimed at real-time conversational systems.

Aug 10, 2026
Text → Speech
NVIDIA/Text → Speech

NVIDIA Opens Magpie TTS for Multilingual Voice Agents

The open-weights text-to-speech model targets low-latency speech synthesis with full control over deployment.

Aug 10, 2026
Text → Speech
NVIDIA/Text / LLMRuns on a laptop

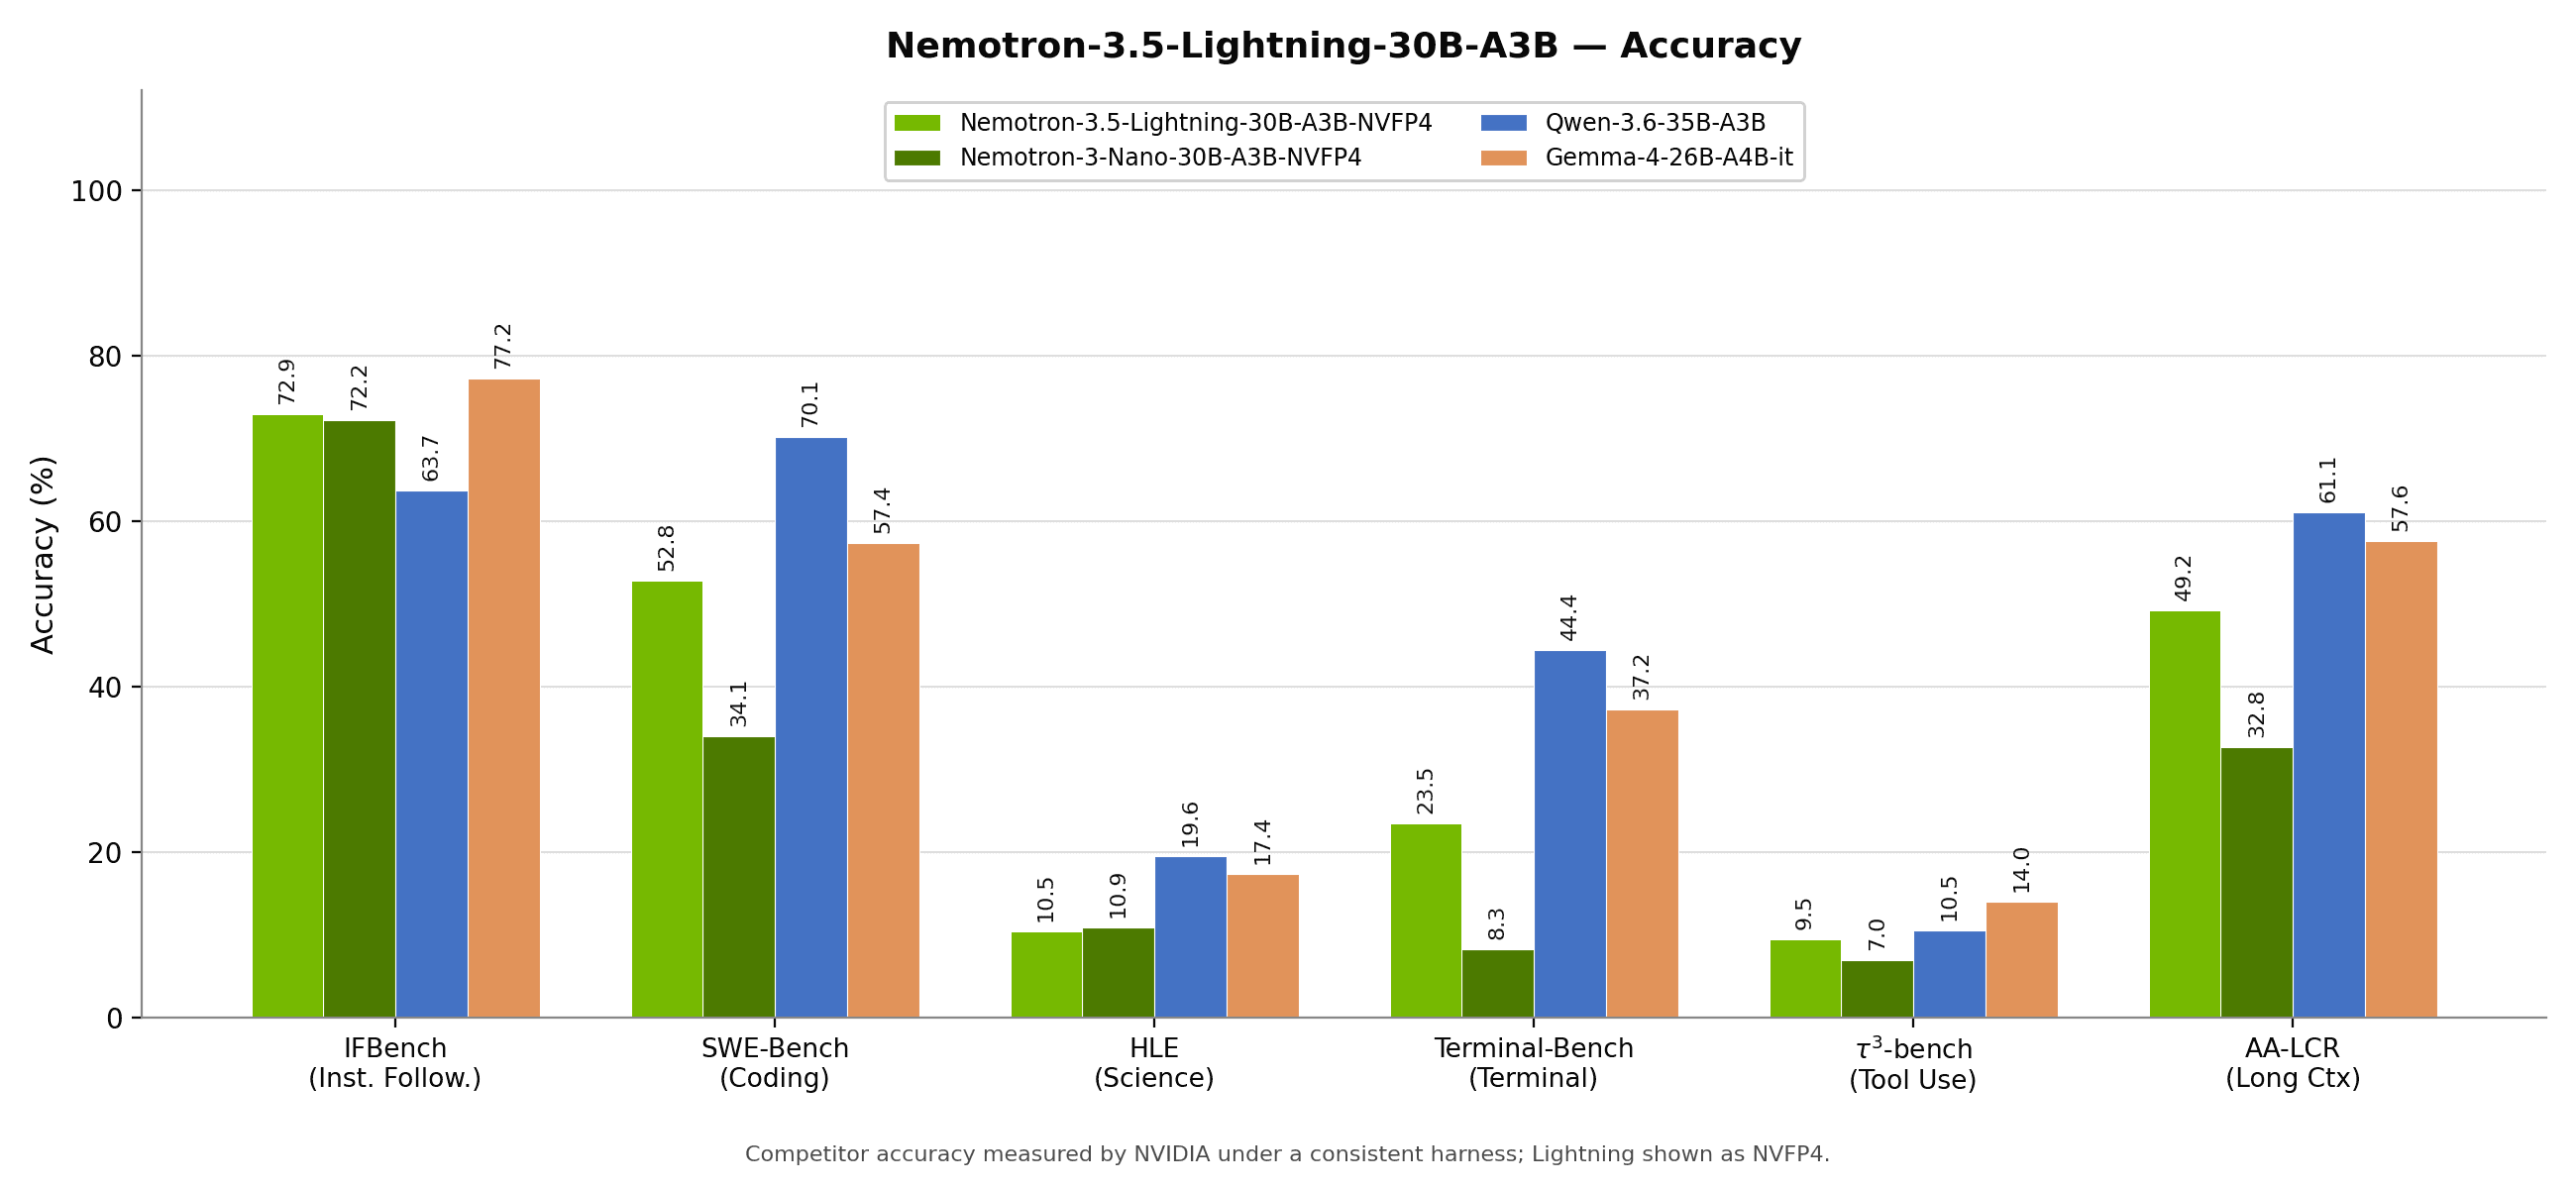
NVIDIA's Nemotron 3.5 Lightning trims MoE for speed

A 30-billion-parameter mixture-of-experts model activates just 3 billion parameters per token, using a hybrid Mamba design to keep inference fast.

Aug 4, 2026
Text / LLMReasoning
Nemotron-3.5-Lightning-30B-A3B
NVIDIA/Text / LLMConsumer GPU

NVIDIA's Nemotron 3.5 Lightning Blends Mamba and MoE

A 30B mixture-of-experts model with just 3B active parameters aims at fast, agentic coding workloads.

Aug 1, 2026
Text / LLMReasoning
Nemotron-3.5-Lightning-30B-A3B
NVIDIA/Text → SpeechRuns on a laptop

NVIDIA's Nemotron VoiceChat 11B Targets Spoken AI

An 11-billion-parameter voice conversation model built atop Nemotron Nano 9B v2 arrives on Hugging Face.

Jul 29, 2026
Text → SpeechAny-to-Any
Nemotron VoiceChat 11B
NVIDIA/Any-to-Any

NVIDIA's Audio-Visual Flamingo Fuses Sound and Sight

A fully open multimodal model aims to reason jointly across audio, images, and long-form video.

Jul 16, 2026
Any-to-AnyVision-Language
NVIDIA/EmbeddingsRuns on a laptop

NVIDIA's Nemotron-3-Embed 8B tops RTEB retrieval test

The 8-billion-parameter text embedding model claims the number one overall spot on the RTEB benchmark, with an eye toward agentic retrieval.

Jul 16, 2026
Embeddings
Nemotron-3-Embed 8B
NVIDIA/EmbeddingsRuns anywhere

NVIDIA's Nemotron 3 Embed tops the RTEB leaderboard

A compact 1B-parameter text embedding model claims the top overall spot on a retrieval benchmark aimed at reflecting real-world use.

Jul 14, 2026
Embeddings
Nemotron-3-Embed 8B
NVIDIA/Any-to-AnyConsumer GPU

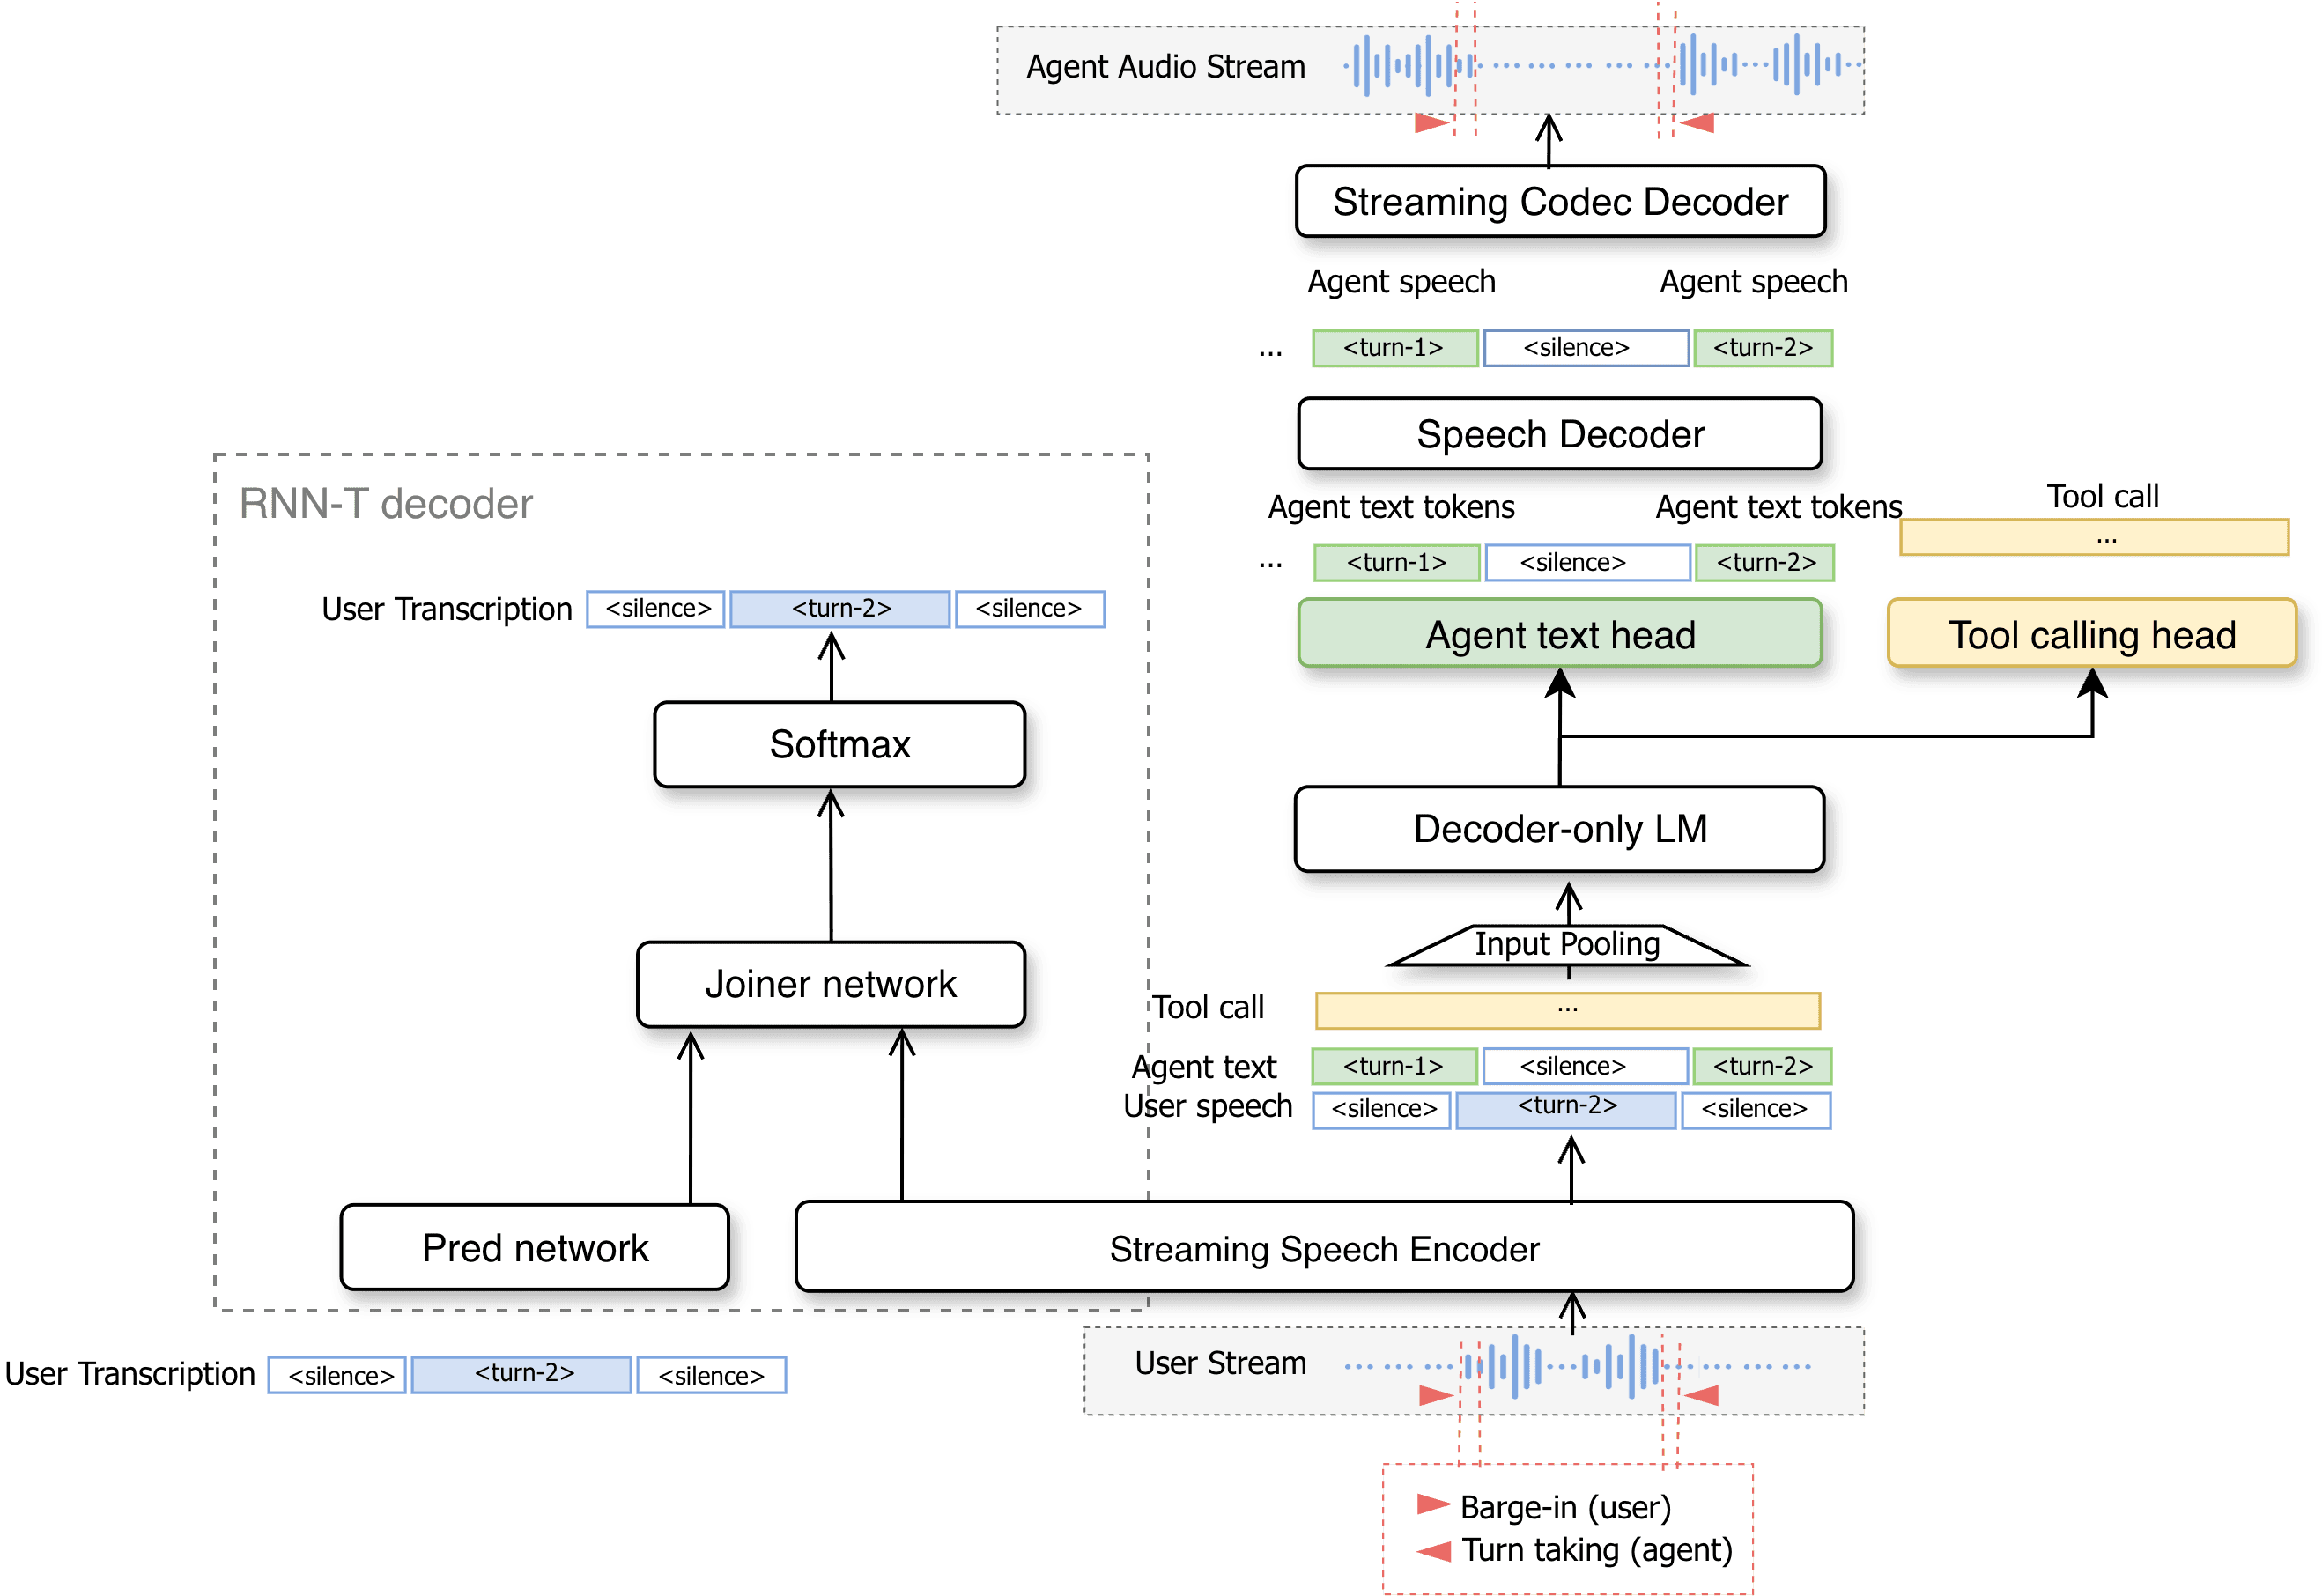
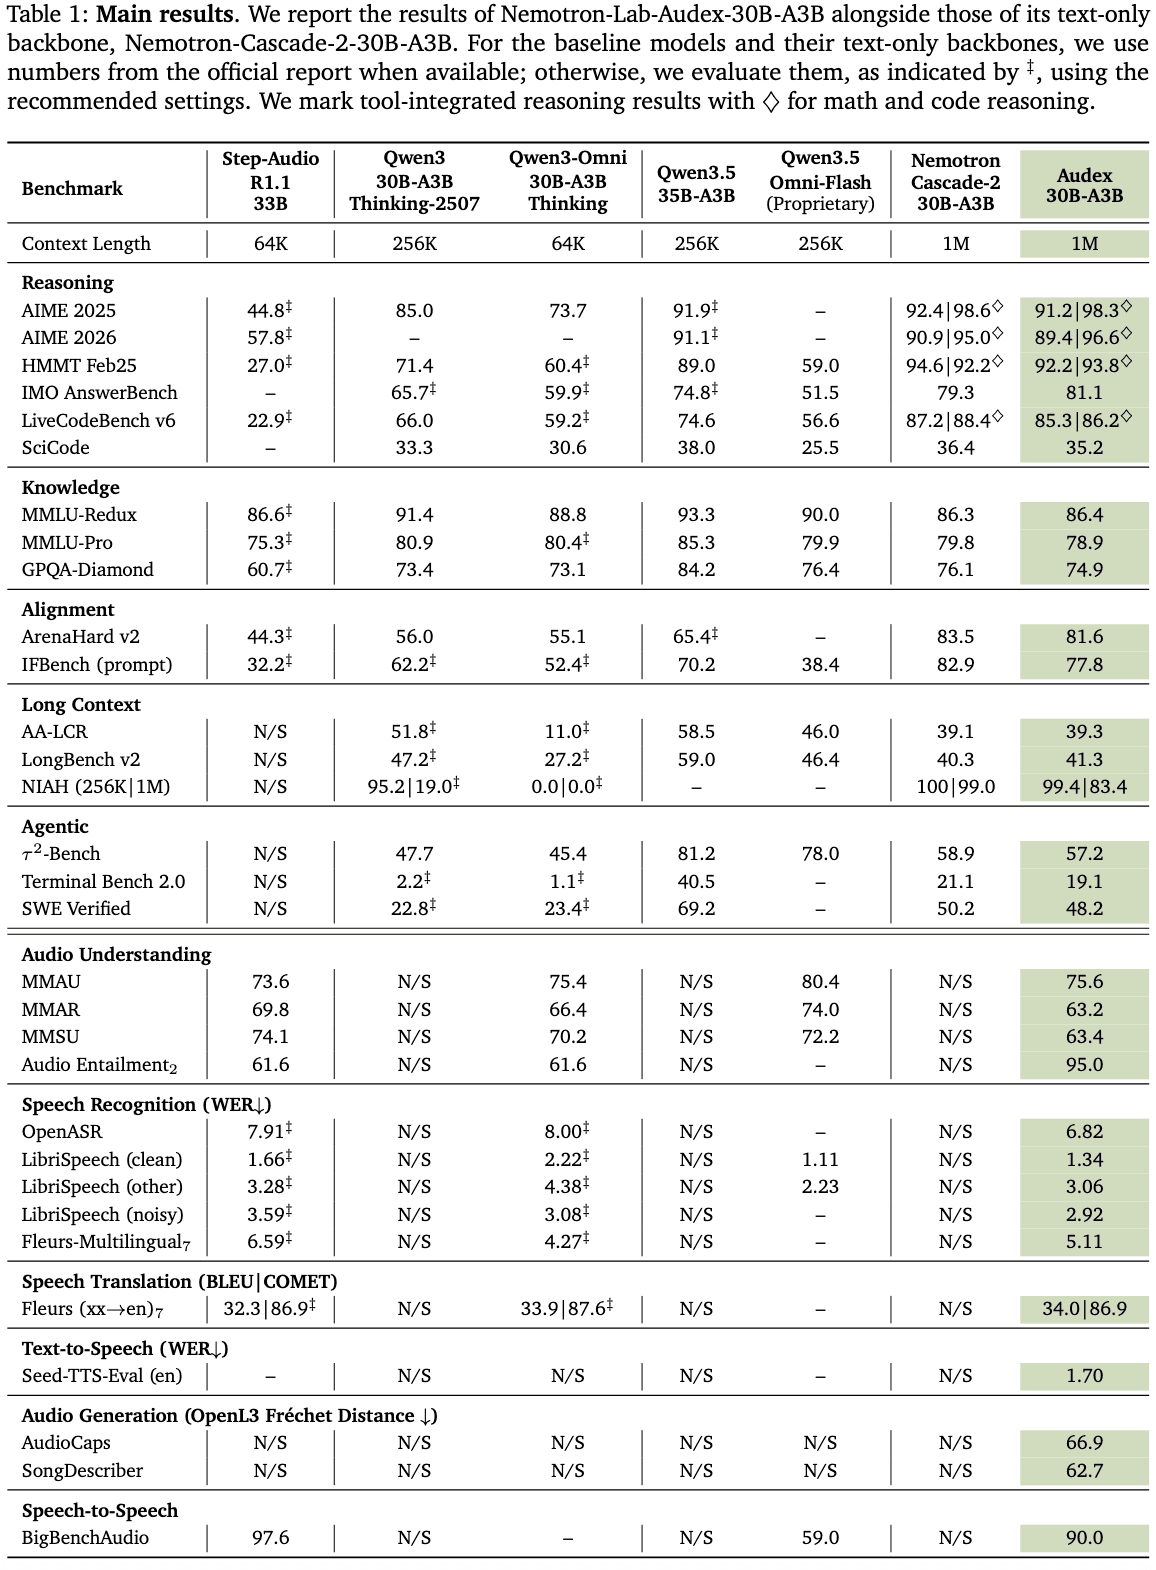
NVIDIA's Audex Unifies Audio Understanding and Speech

A new 30B mixture-of-experts model from NVIDIA handles both listening and speaking within a single audio-text architecture.

Jul 6, 2026
Any-to-AnyText → Speech
Nemotron-Labs-Audex-30B-A3B
NVIDIA/Text → VideoRuns on a laptop

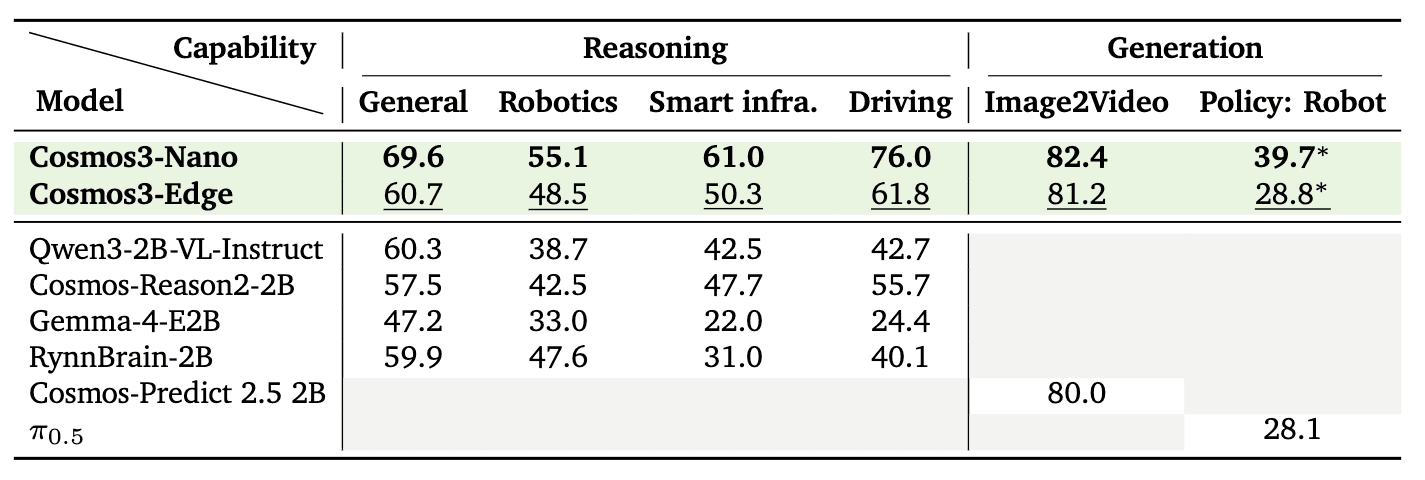
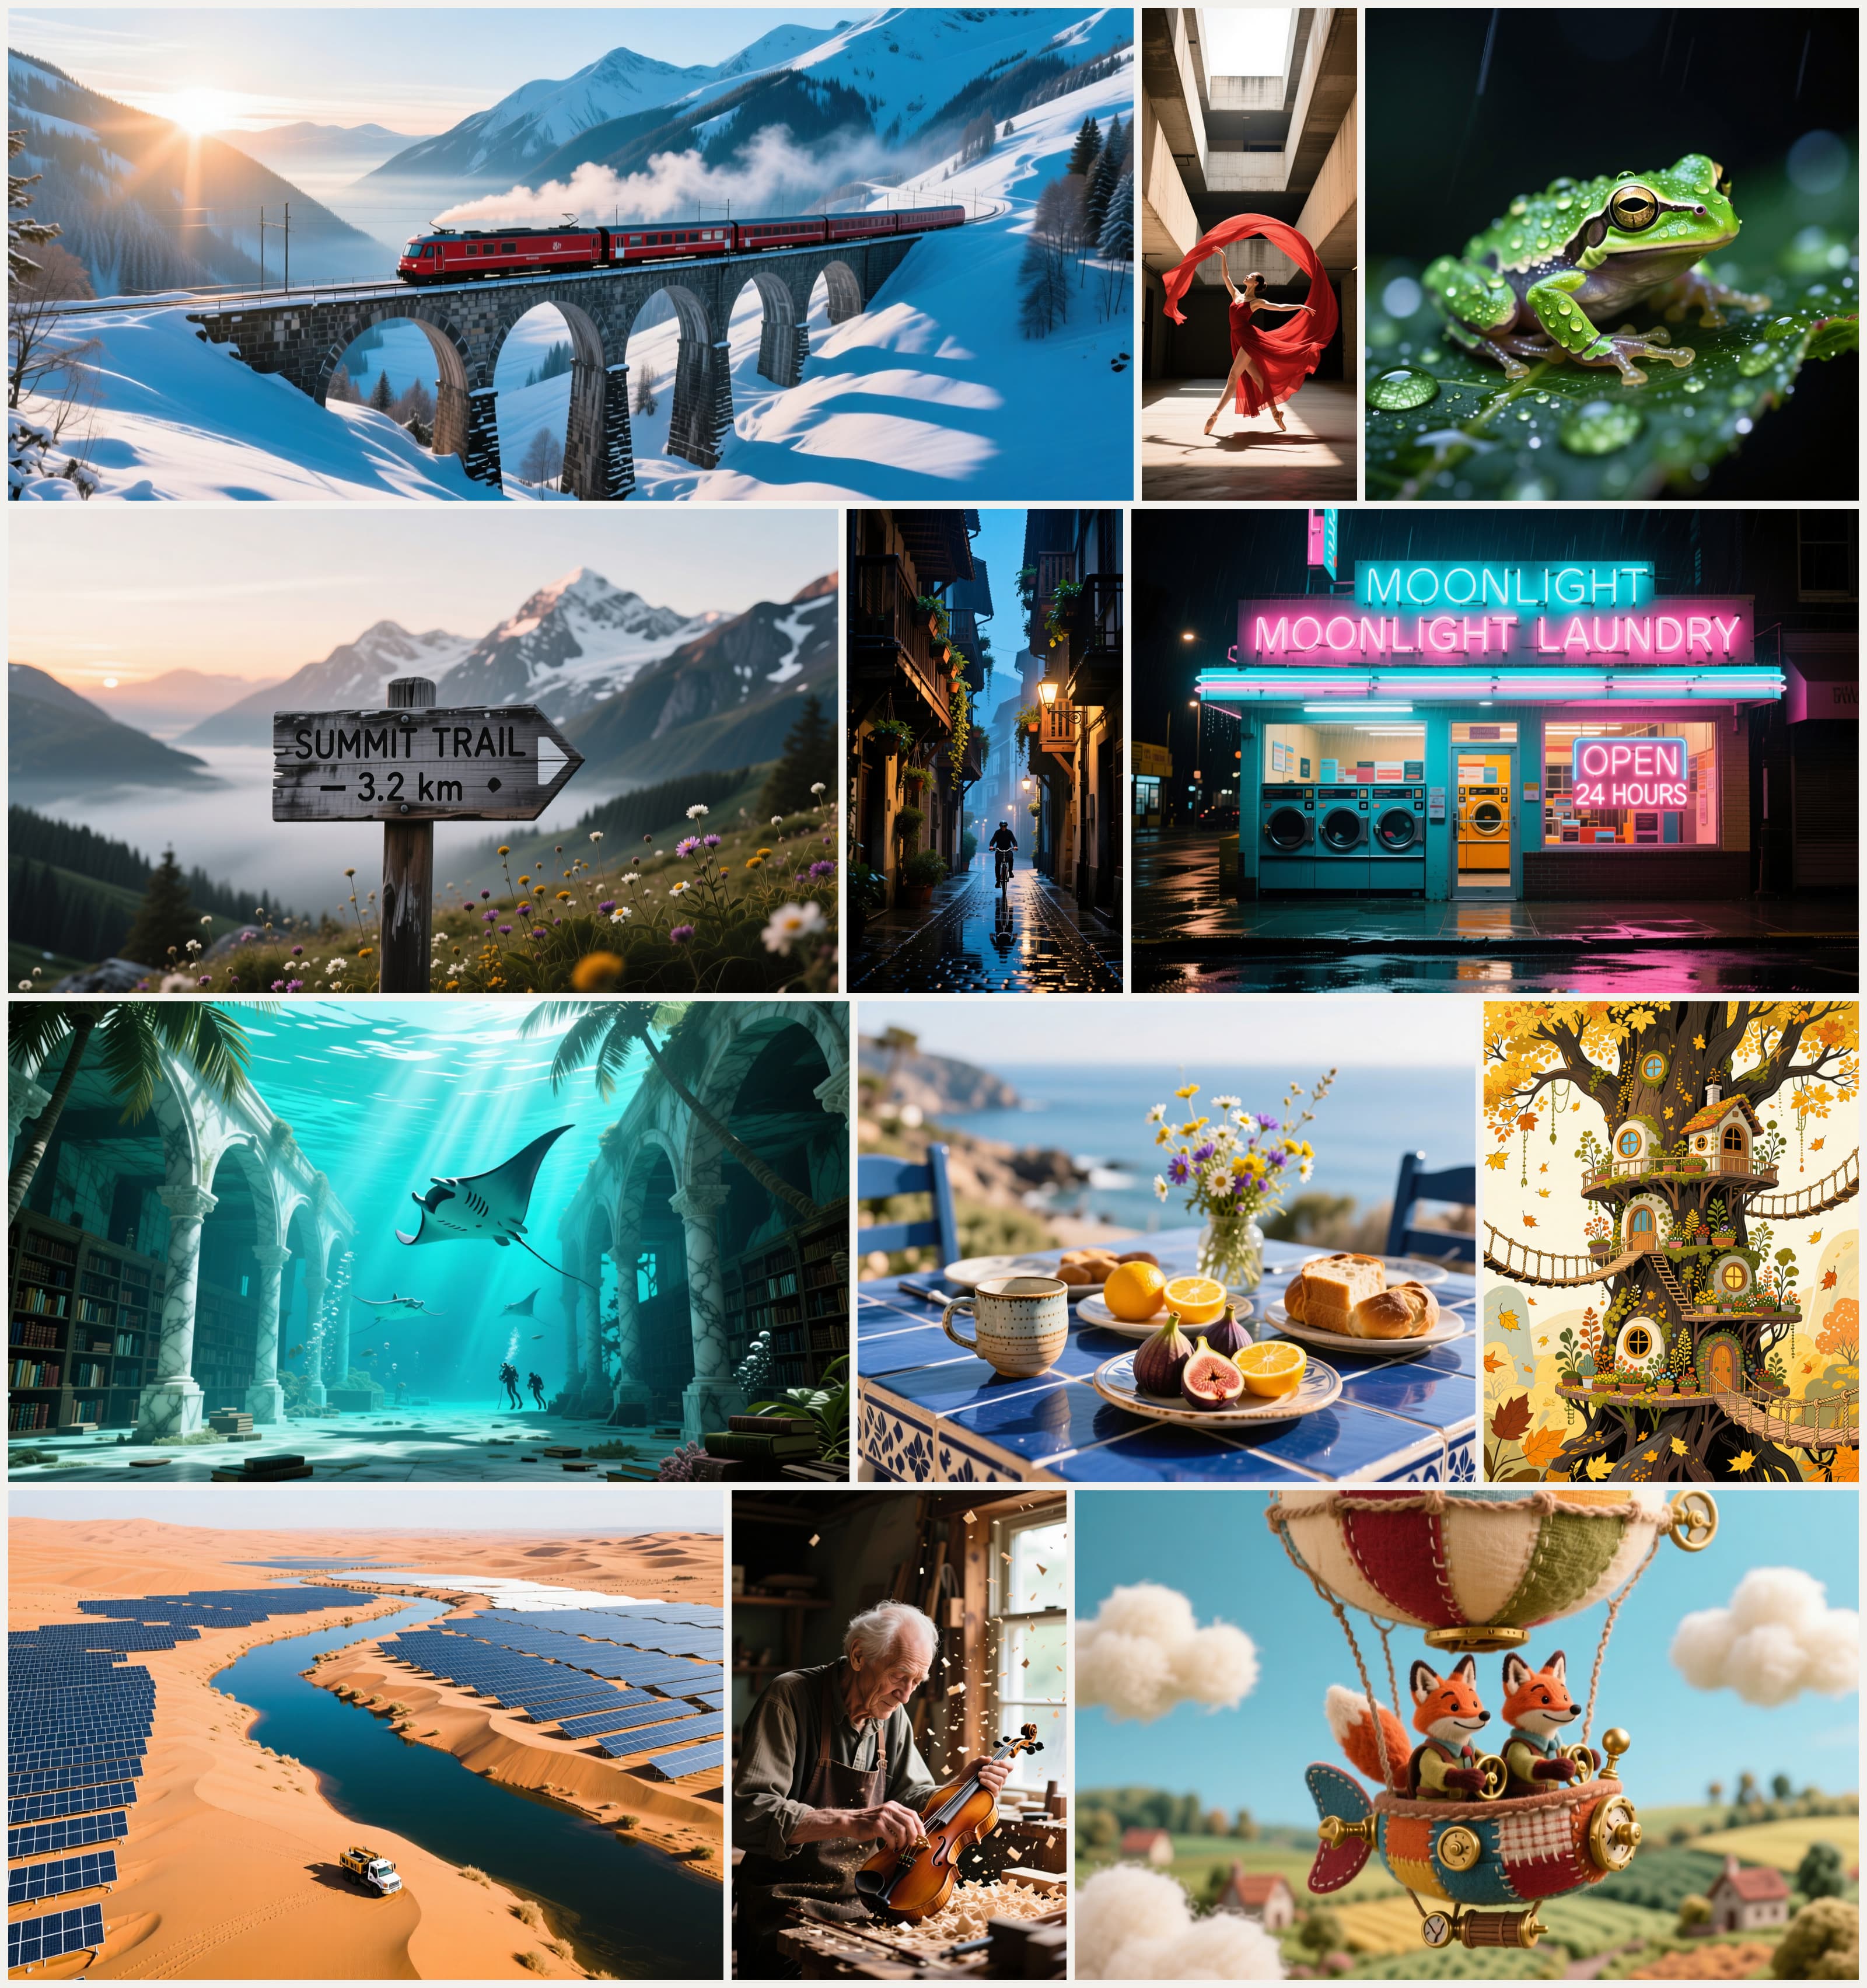
NVIDIA's Cosmos 3 Edge Brings World Models Closer

A new edge-optimized variant of NVIDIA's Cosmos world-model line aims to run generative video where the compute lives.

Jul 1, 2026
Text → VideoImage → Video
Cosmos 3 Edge
NVIDIA/Text → ImageConsumer GPU

NVIDIA distills Qwen-Image for few-step generation

A DMD2-distilled build of Qwen-Image trades sampling steps for speed while keeping the original model's output profile.

Jul 1, 2026
Text → Image
Qwen-Image-Flash
NVIDIA/Text / LLMRuns anywhere

Liquid AI's LFM2.5-230M targets phones and robots

A 230-million-parameter language model built to run on hardware as modest as a Raspberry Pi.

Jul 1, 2026
Text / LLM
NVIDIA/Vision-LanguageRuns anywhere

NVIDIA's Nemotron-Parse 2.0 targets document OCR

A compact vision-language model built to turn scanned pages and complex layouts into structured, machine-readable text.

Jun 30, 2026
Vision-Language
Nemotron-Parse-2.0
NVIDIA/Text / LLMWorkstation GPU

NVIDIA's Nemotron 3 Puzzle Runs Big on a Lean Budget

A 75-billion-parameter mixture-of-experts reasoning model that activates just 9 billion parameters per token.

Jun 24, 2026
Text / LLMReasoning
Nemotron-Labs-3-Puzzle-75B-A9B
NVIDIA/Text / LLMWorkstation GPU

NVIDIA's Nemotron-3 Puzzle Brings a Lean MoE to Reasoning

The 75B-parameter model activates just 9B per token and ships in NVIDIA's NVFP4 format for efficient inference.

Jun 24, 2026
Text / LLMReasoning
Nemotron-3 Puzzle 75B-A9B
NVIDIA/Image → VideoWorkstation GPU

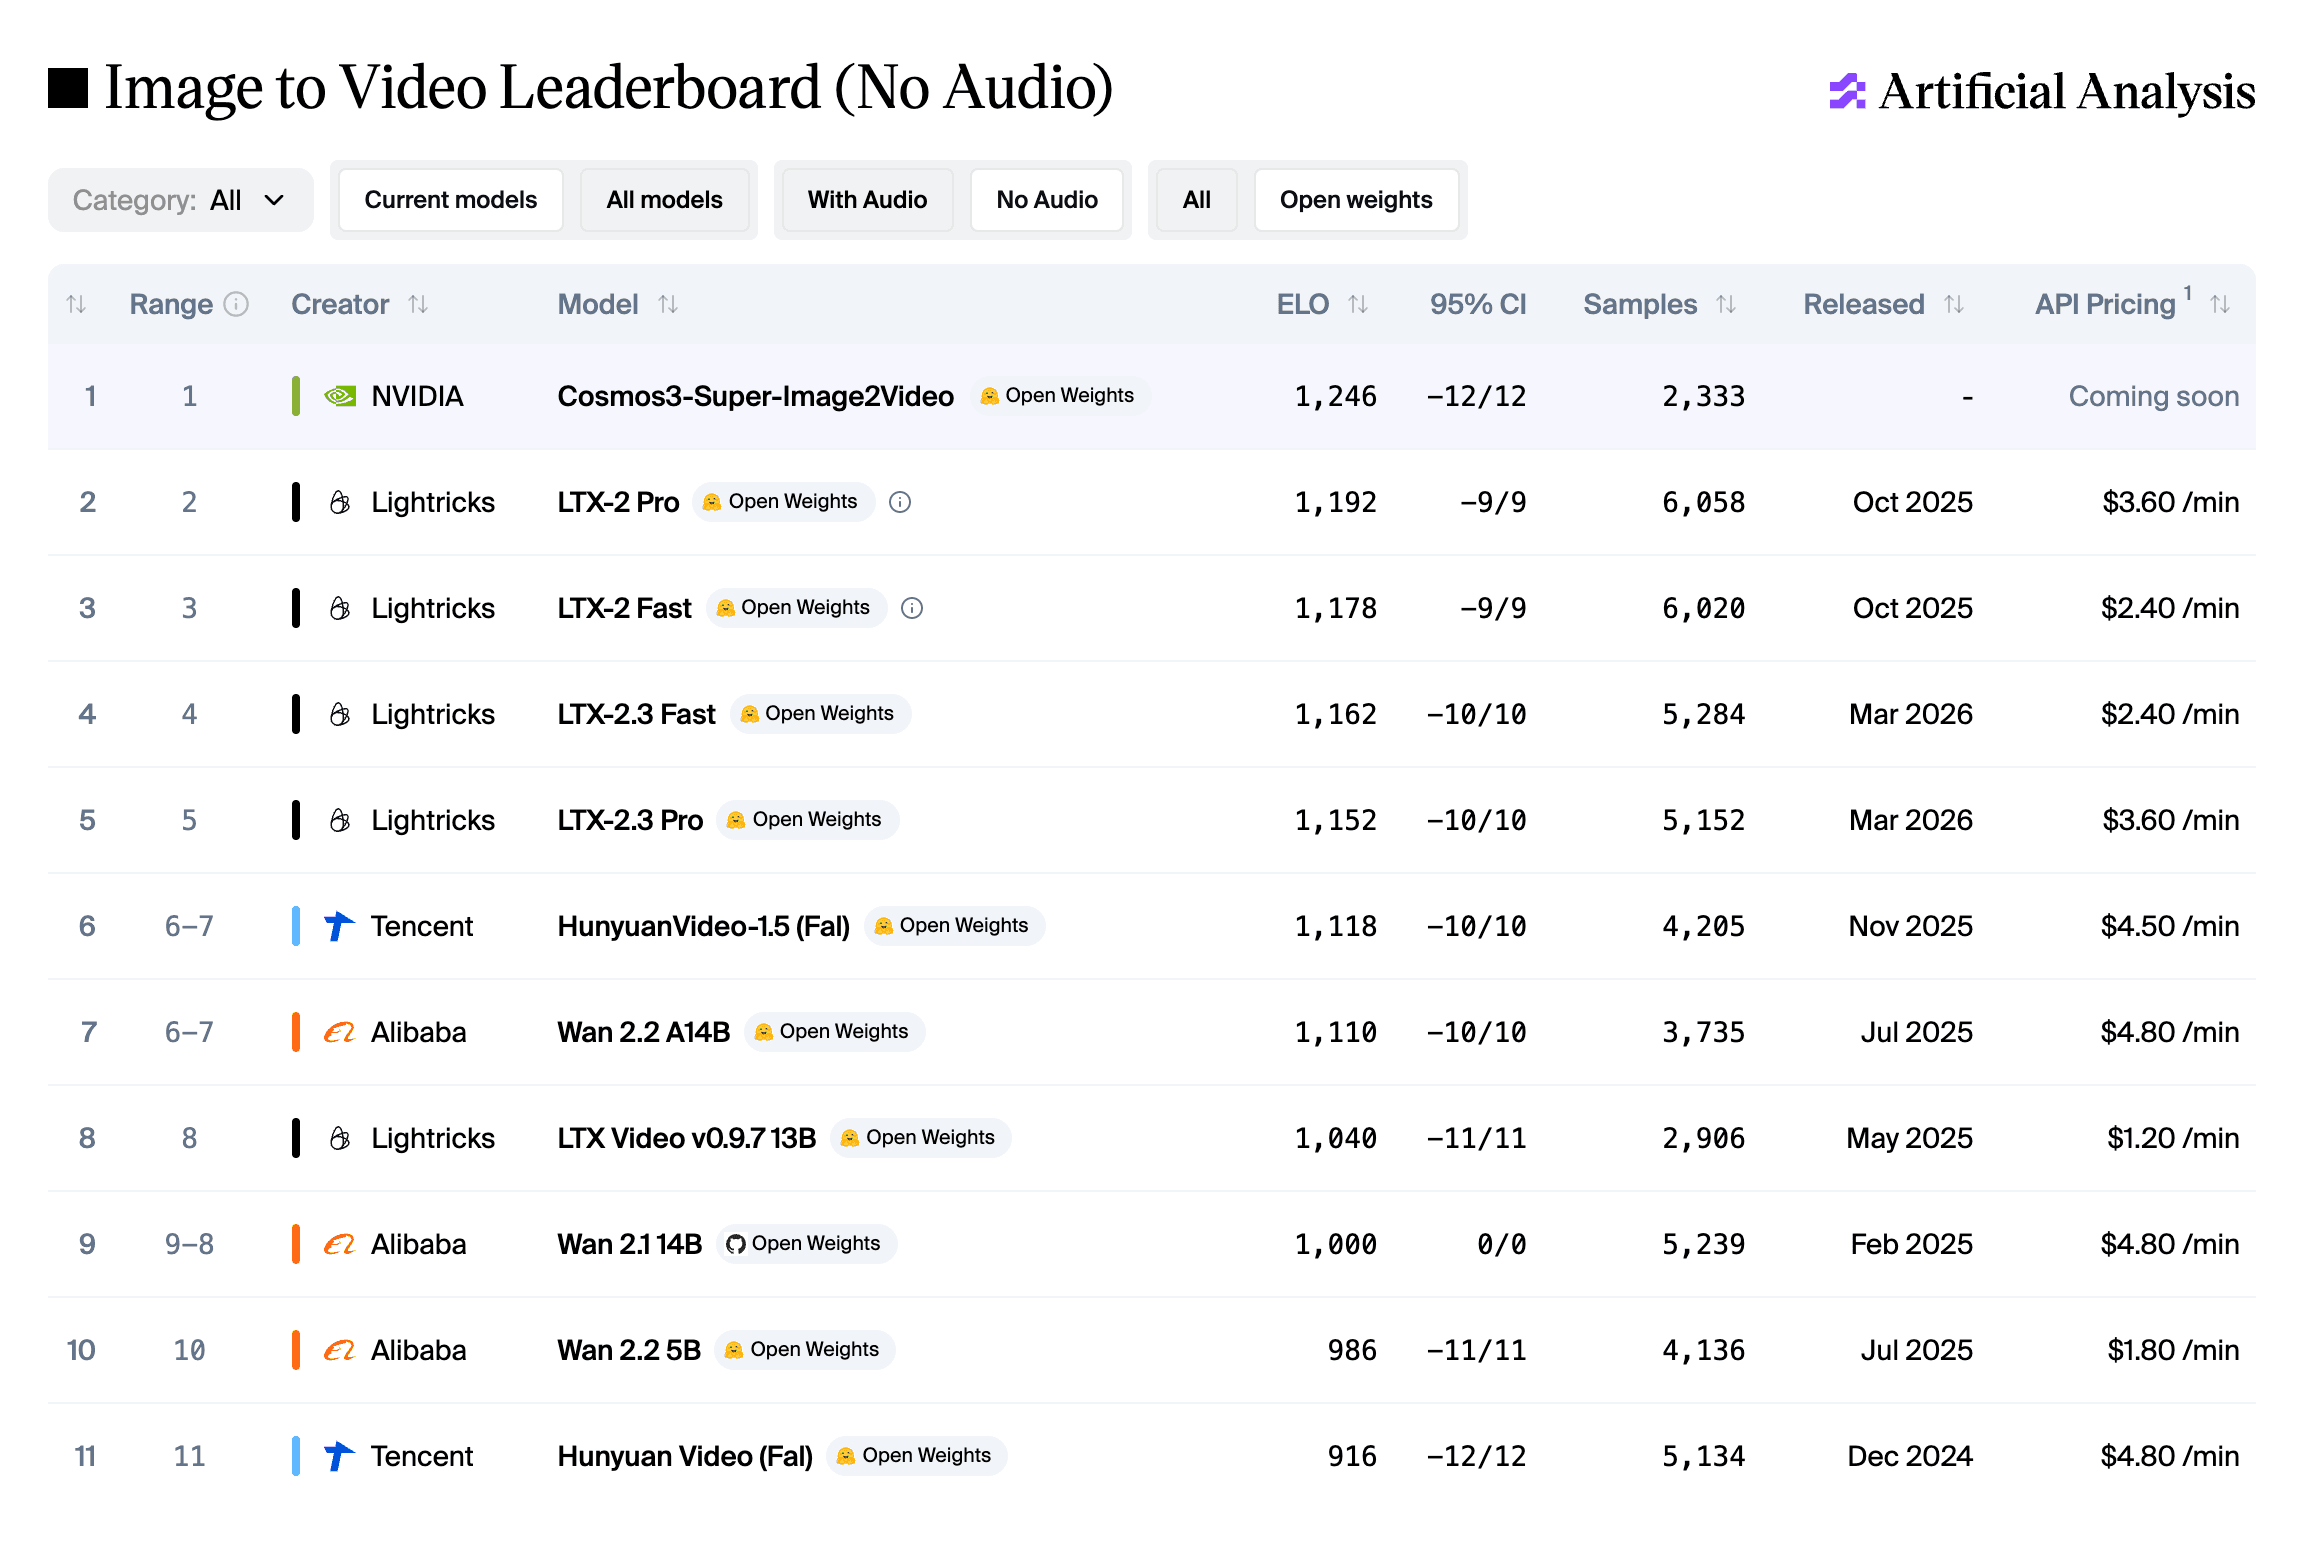
NVIDIA Releases Cosmos3 Image-to-Video World Model

The latest release in NVIDIA's 'world model' research family aims to generate coherent and realistic video from a single static image.

May 21, 2026
Image → Video
Cosmos3 Super Image2Video
NVIDIA/Image → Video

NVIDIA Releases SANA, a Camera-Controllable Video Model

The new model, SANA-WM, uses a bidirectional diffusion process to give creators fine-grained control over camera movement and video editing.

May 18, 2026
Image → VideoText → Video
SANA-WM Bidirectional
NVIDIA/Speech → TextRuns anywhere

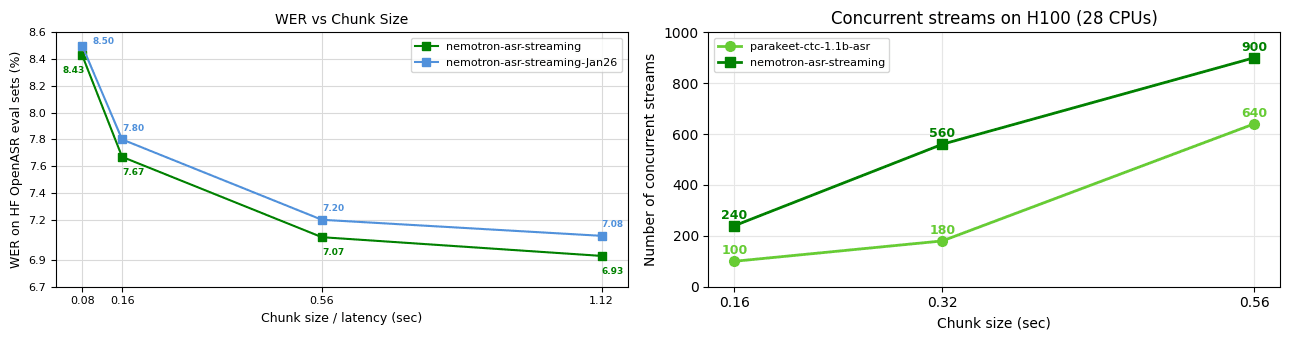
NVIDIA Releases Nemotron-3.5 Streaming ASR Model

The 600-million-parameter model uses a FastConformer architecture for real-time, multilingual speech-to-text applications.

May 15, 2026
Speech → Text
Nemotron 3.5 ASR Streaming 0.6B
NVIDIA/Image Editing

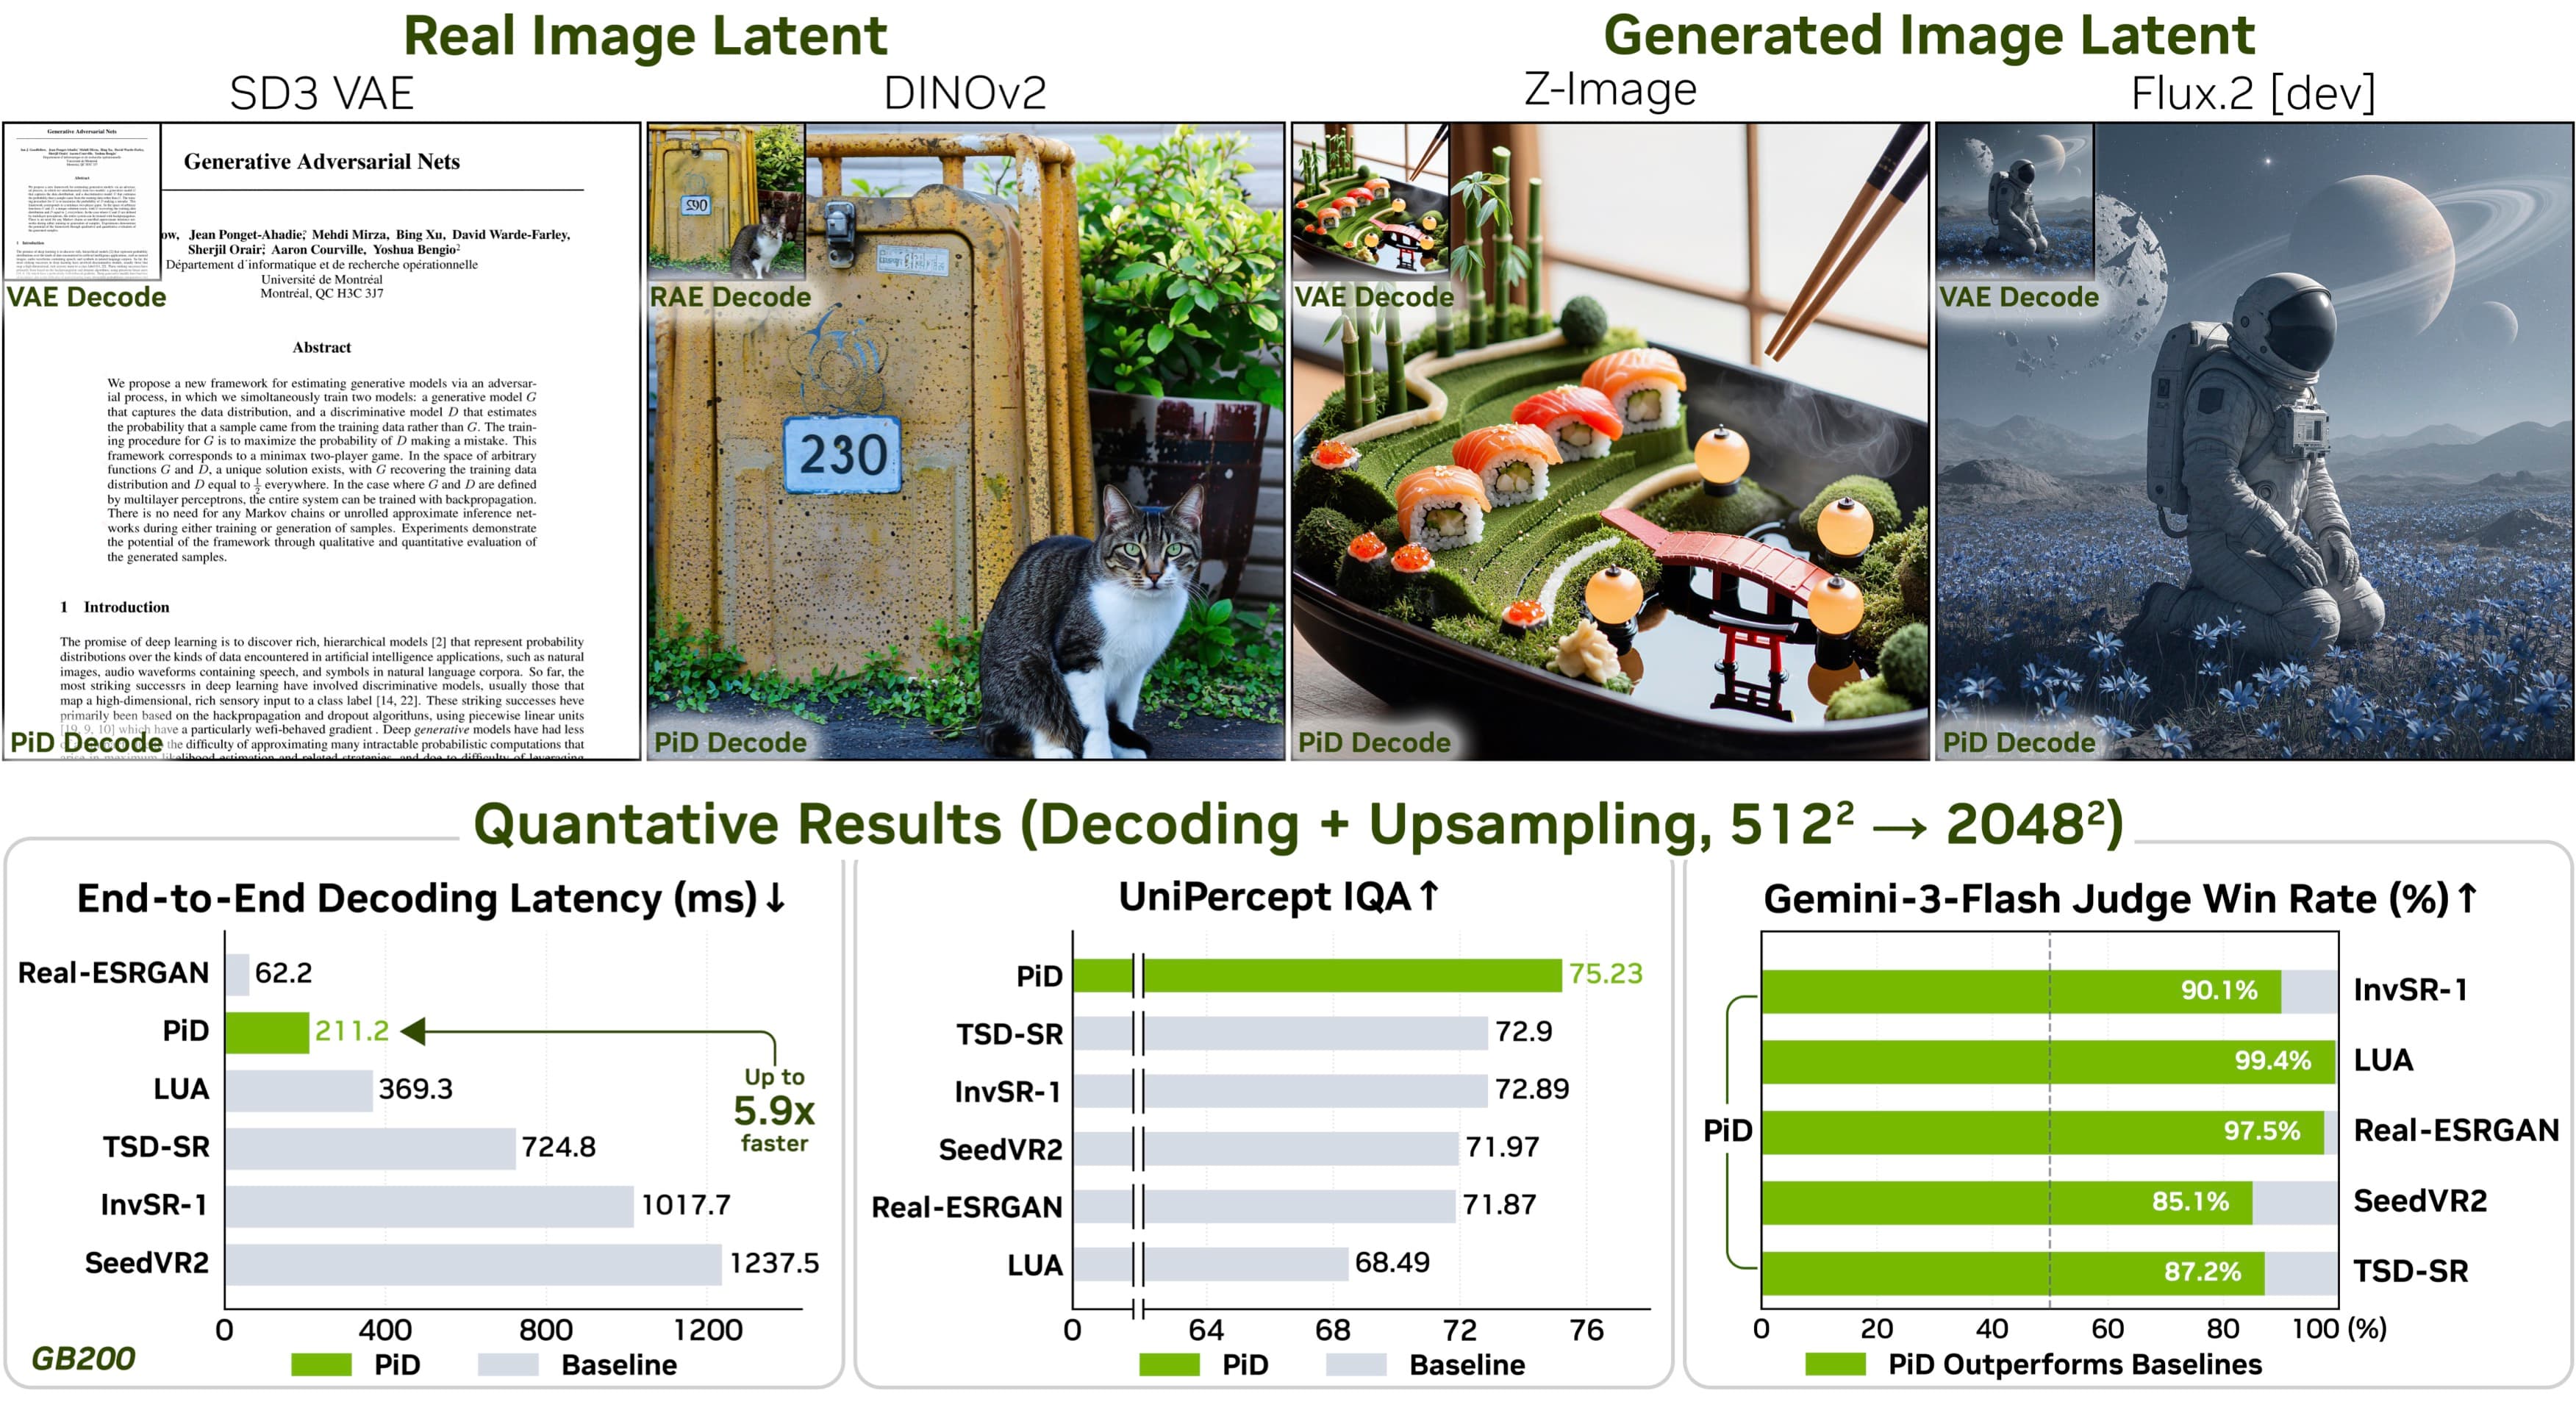
NVIDIA Releases PiD for High-Quality Image Upscaling

The new component is a specialized VAE decoder that works with Stability AI's Z-Image model to enhance super-resolution tasks.

Apr 28, 2026
Image Editing
NVIDIA PiD (Pixel Diffusion Decoder)
NVIDIA/Any-to-AnyRuns on a laptop

NVIDIA Releases Efficient Nemotron-3 Multimodal MoE

The new 30-billion parameter Mixture-of-Experts model handles text and images while using only 3 billion active parameters for inference.

Apr 24, 2026
Any-to-AnyReasoning
Nemotron-3 Nano Omni 30B-A3B Reasoning
NVIDIA/Any-to-AnyConsumer GPU

NVIDIA Releases Nemotron-3-Nano Omni-Modal MoE

The new 30-billion-parameter Mixture-of-Experts model handles any combination of modalities with just 3 billion active parameters.

Apr 20, 2026
Any-to-AnyReasoning
Nemotron-3 Nano Omni 30B-A3B Reasoning
NVIDIA/Text / LLMConsumer GPU

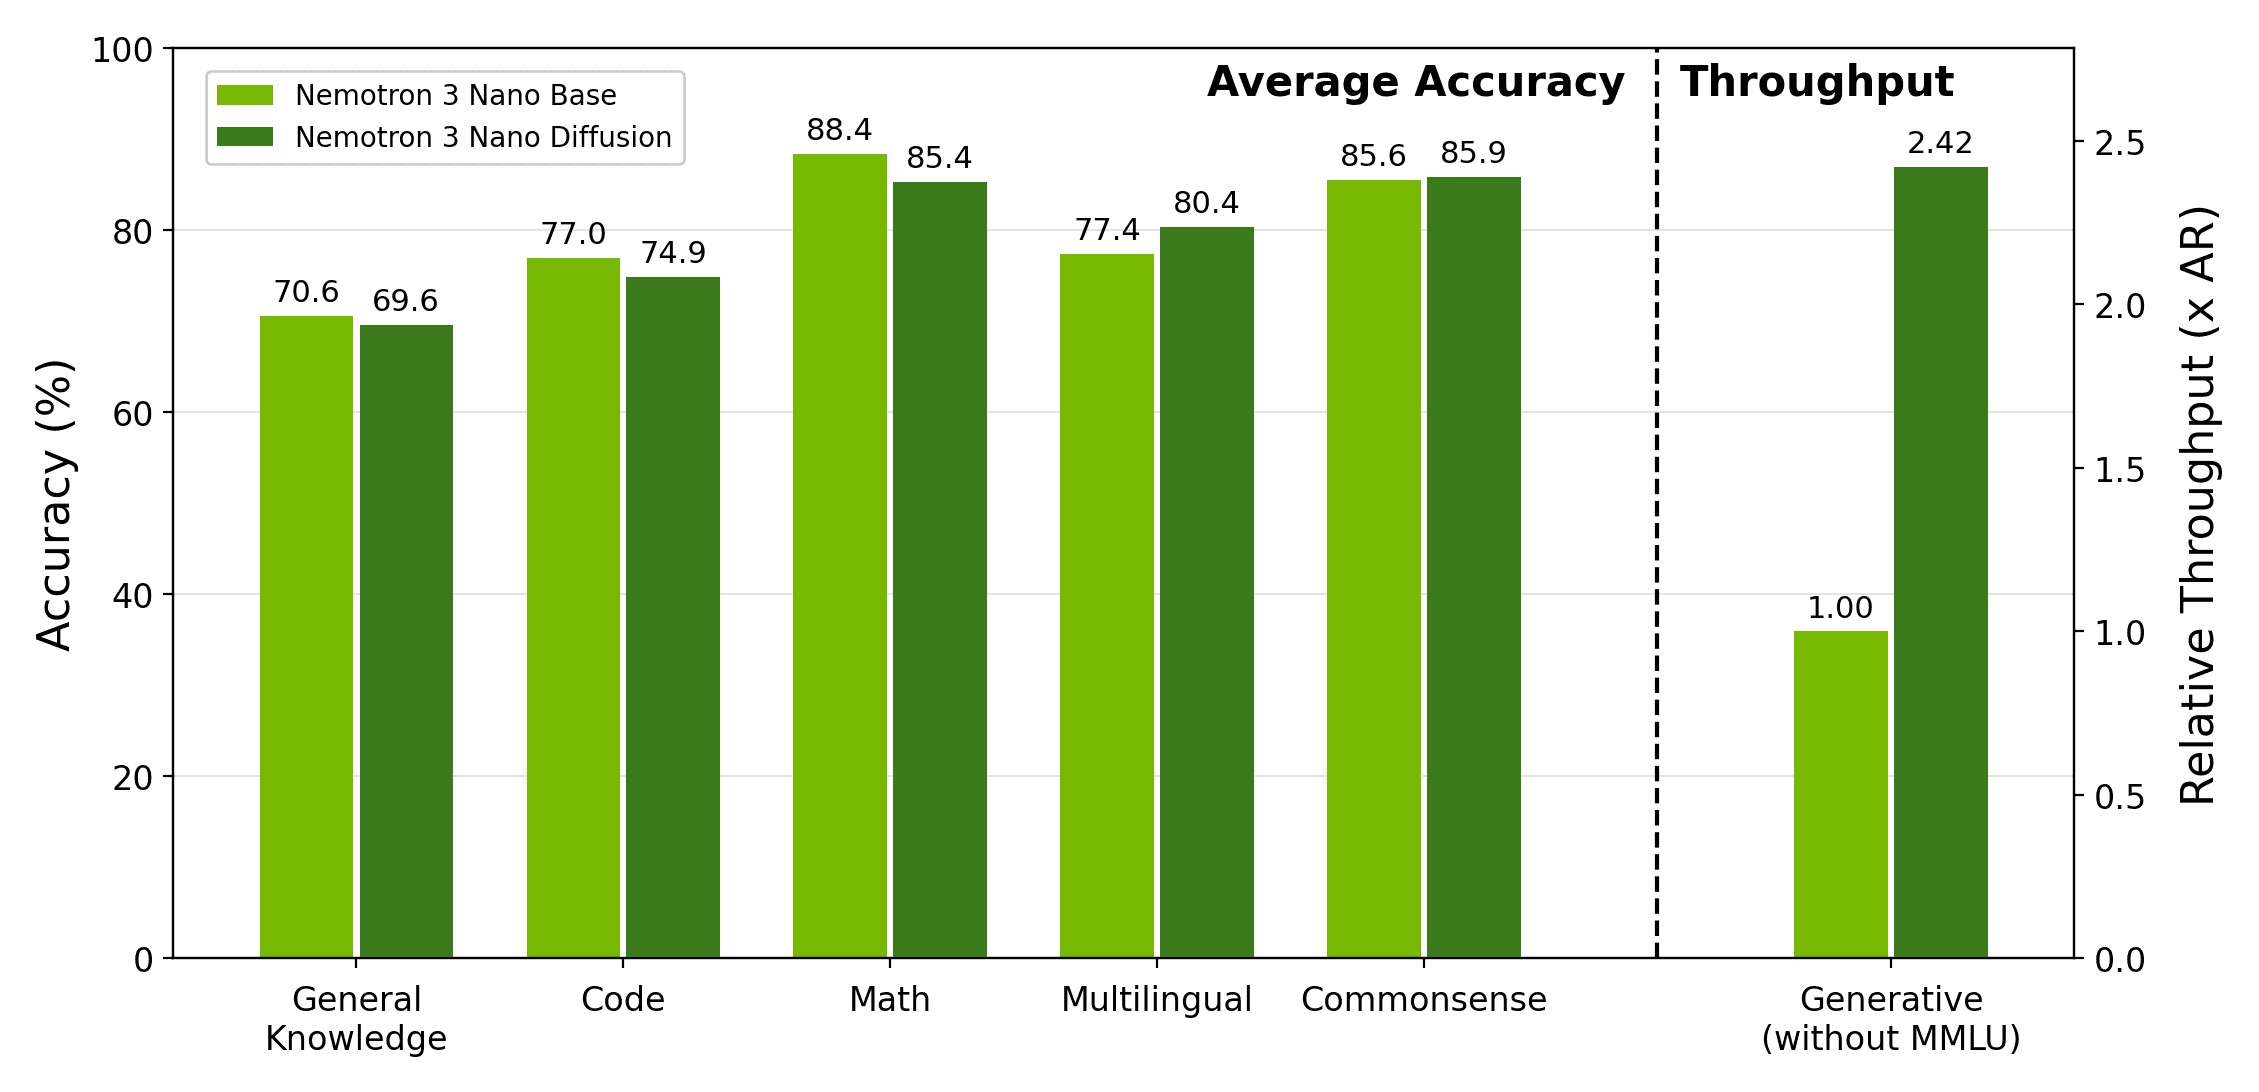
NVIDIA's Nemotron TwoTower is a MoE experiment

An experimental 30B mixture-of-experts base model blends diffusion and Mamba ideas under a two-tower design.

Apr 11, 2026
Text / LLM
Nemotron TwoTower 30B-A3B Base
NVIDIA/Text / LLMConsumer GPU

NVIDIA's Nemotron TwoTower mixes diffusion and Mamba

A new 30B mixture-of-experts base model activates just 3B parameters per token and pairs a hybrid diffusion/Mamba design.

Apr 11, 2026
Text / LLM
Nemotron TwoTower 30B-A3B Base
NVIDIA/Vision-LanguageRuns anywhere

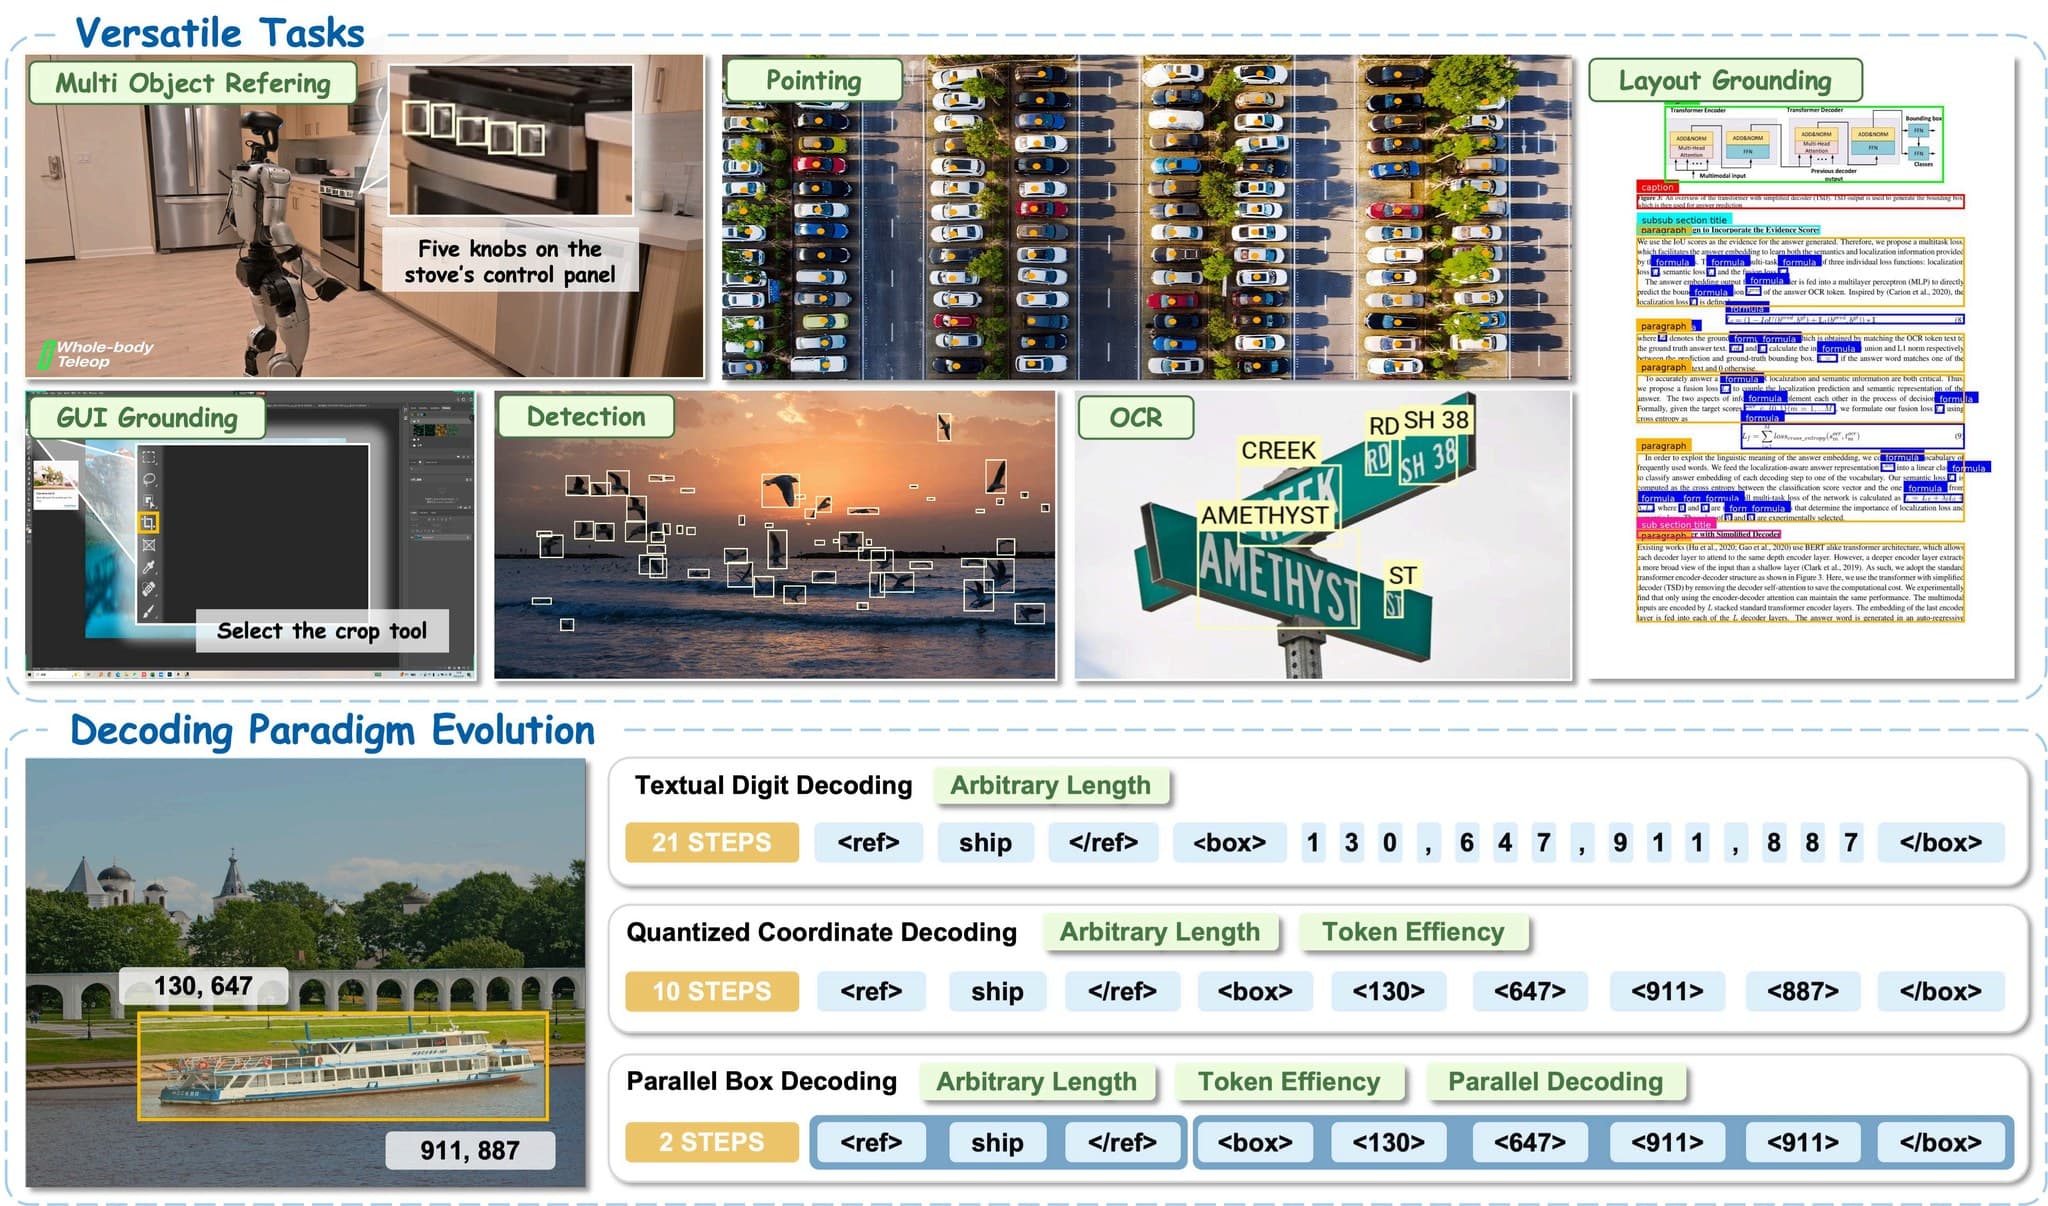
NVIDIA's New 3B VLM Pinpoints Objects in Images

The new 3-billion-parameter model, based on the company's Eagle architecture, is designed for high-precision visual grounding tasks.

Mar 2, 2026
Vision-Language
LocateAnything-3B
NVIDIA/Speech → TextRuns anywhere

NVIDIA Releases Streaming Speech-to-Text Model

The 600-million-parameter Nemotron model is designed for real-time English transcription using a cache-aware FastConformer architecture.

Dec 17, 2025
Speech → Text
Nemotron Speech Streaming EN 0.6B
NVIDIA/Speech → Text

NVIDIA Releases Real-Time Speaker Diarization Model

The new Sortformer-based model is designed for streaming audio, identifying up to four distinct speakers in real time.

Oct 22, 2025
Speech → Text
Streaming Sortformer Diarization 4spk v2.1
NVIDIA/Speech → TextRuns anywhere

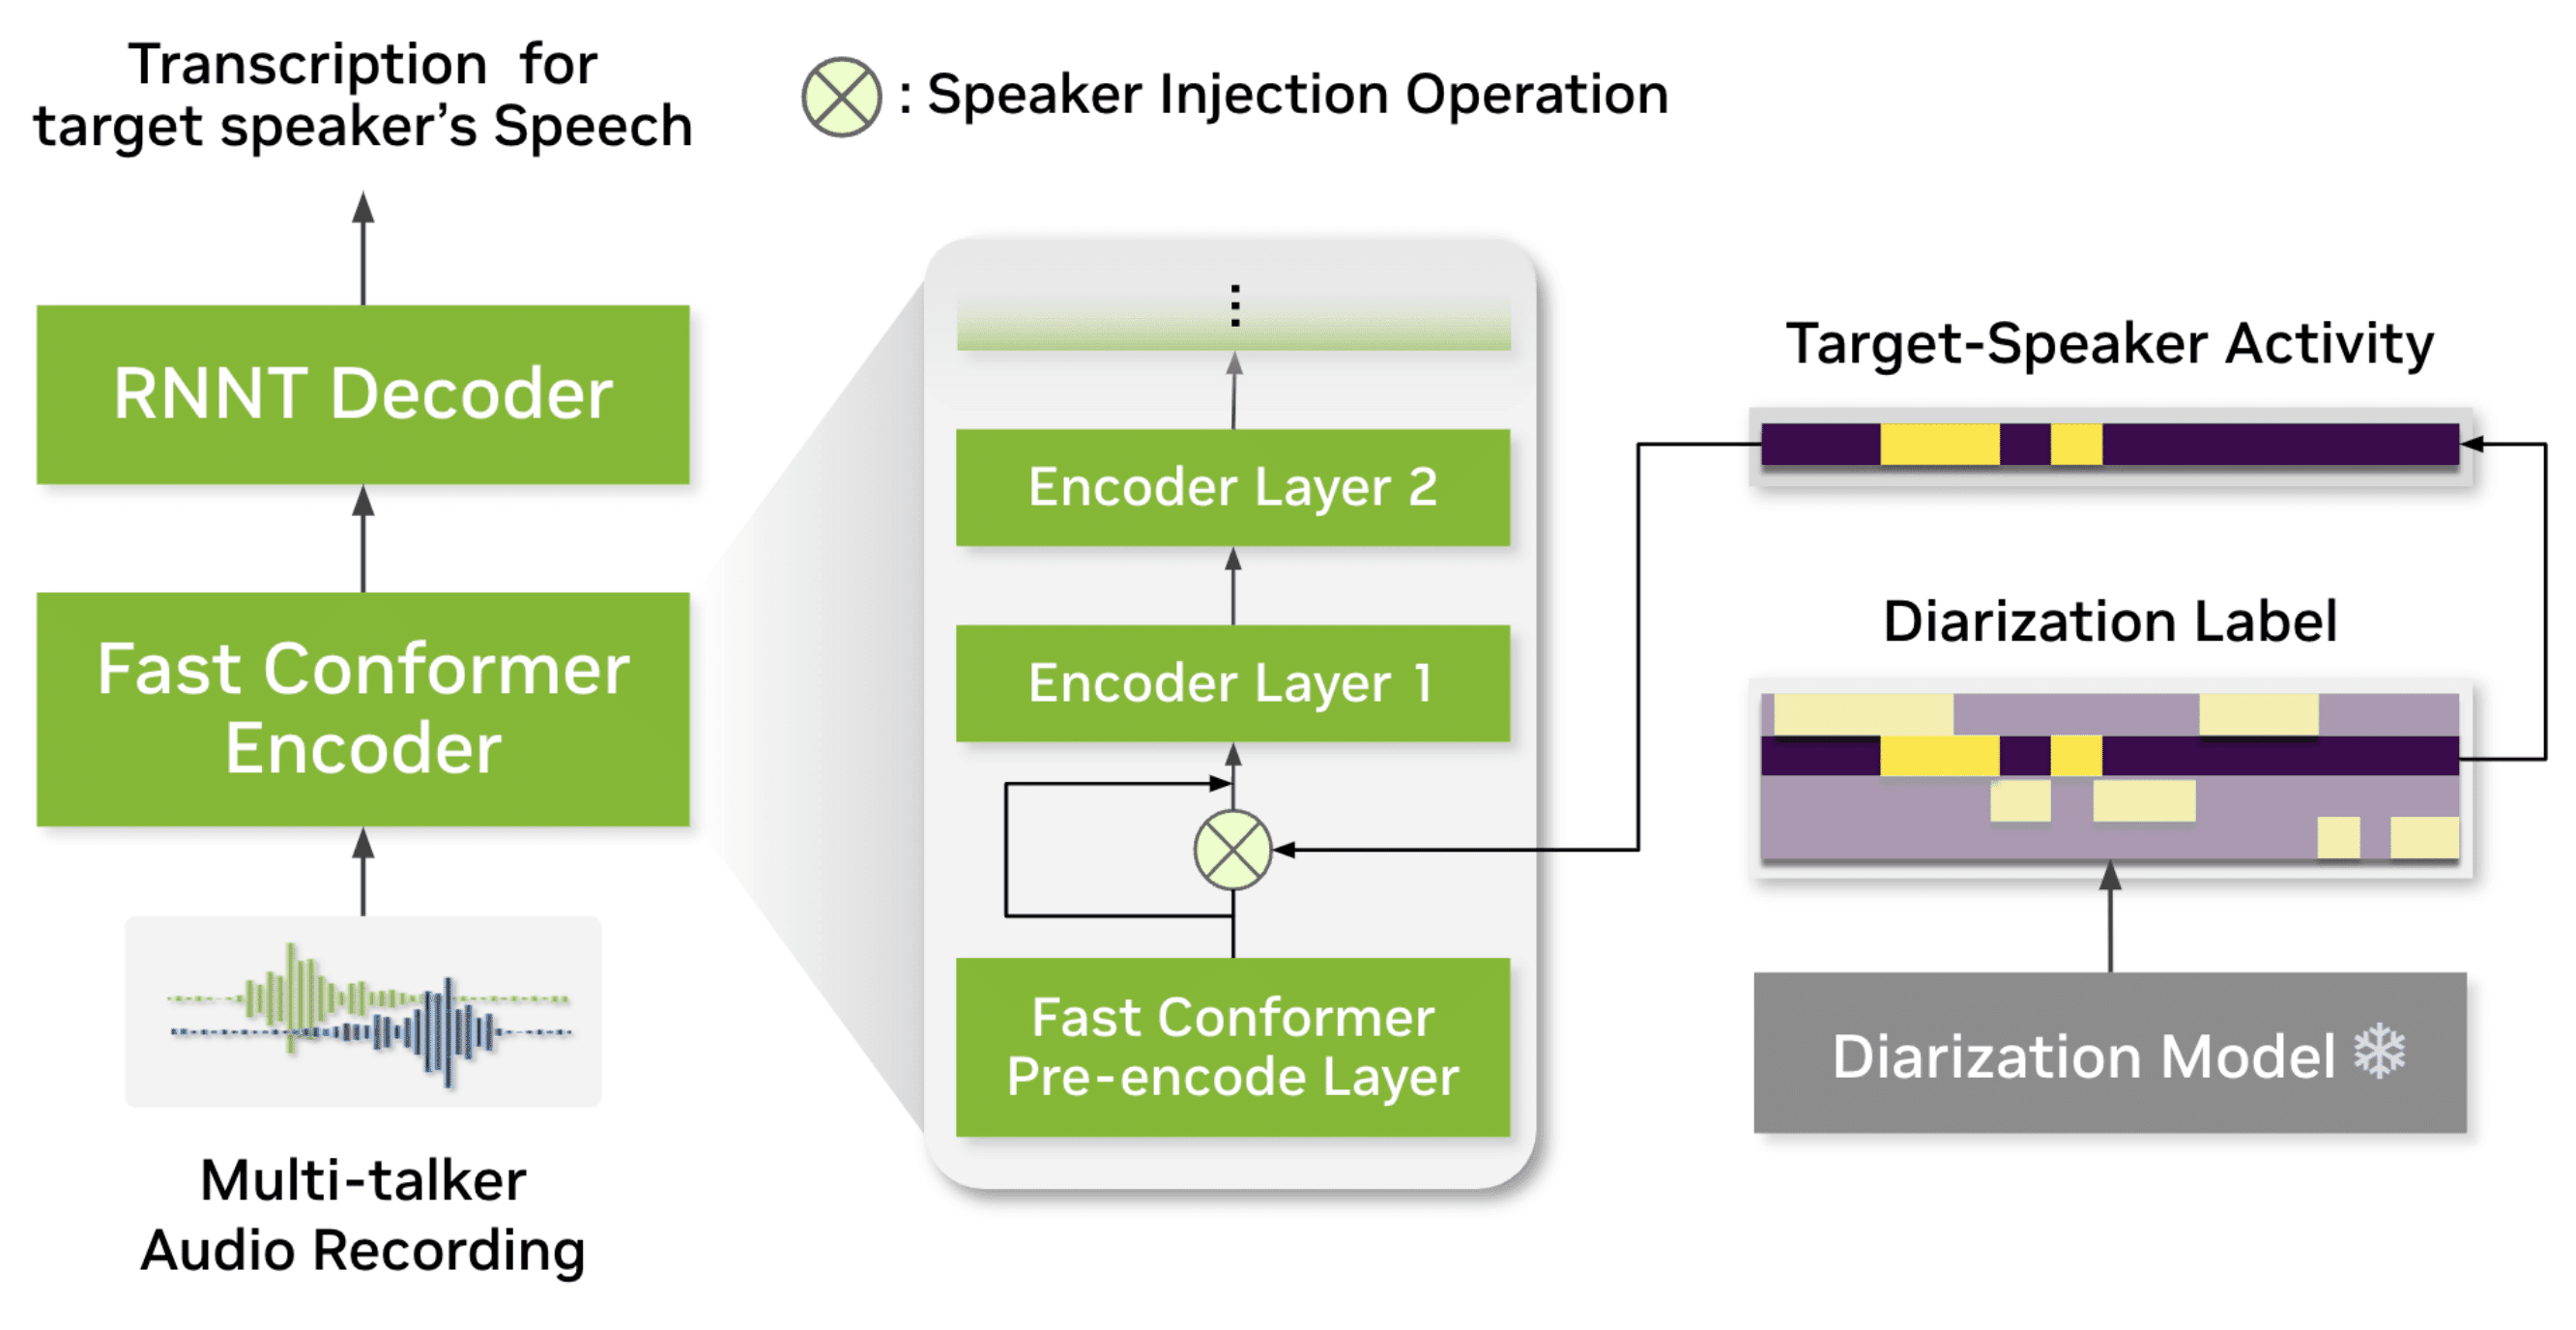
NVIDIA's Parakeet ASR Tackles Multi-Speaker Audio

The 600-million-parameter model offers real-time speech-to-text with speaker diarization, built on the efficient FastConformer architecture.

Oct 15, 2025
Speech → Text
Multitalker Parakeet Streaming 0.6B
NVIDIA/Speech → TextRuns anywhere

NVIDIA Releases Canary 1B v2 Multilingual Speech Model

The new 1-billion-parameter model handles both transcription and translation across five languages using the company's efficient FastConformer architecture.

Aug 4, 2025
Speech → Text
Canary 1B v2
NVIDIA/Speech → TextRuns anywhere

NVIDIA Releases 600M Parakeet for Speech Recognition

The new FastConformer model uses a specialized training technique to improve transcription accuracy in noisy, real-world environments.

Aug 4, 2025
Speech → Text
Parakeet TDT 0.6B v3
NVIDIA/Speech → TextRuns anywhere

NVIDIA Fuses LLM and ASR in Canary-Qwen 2.5B Model

The 2.5 billion-parameter speech model combines a FastConformer encoder with a Qwen LLM decoder, a hybrid approach to transcription.
Jun 26, 2025
Speech → Text
Canary-Qwen 2.5B