Liquid AI's LFM2.5-230M targets phones and robots
A 230-million-parameter language model built to run on hardware as modest as a Raspberry Pi.
Liquid AI has released LFM2.5-230M, a compact language model with roughly 230 million parameters designed to run directly on constrained hardware rather than in the cloud. The company frames it for phones, Raspberry Pi boards, and robotics, where memory and power budgets rule out larger models.
At this size, the appeal is less about topping leaderboards and more about placement. A model small enough to fit comfortably on-device can respond without a network round trip, keep data local, and operate in environments where connectivity is unreliable — the exact conditions faced by embedded systems and mobile applications.
Why it matters
The industry's attention tends to follow ever-larger frontier models, but a parallel push toward sub-billion-parameter systems is opening up new deployment targets. LFM2.5-230M is squarely part of that trend.
- Runs locally on phones, single-board computers, and robots
- Text-focused, at about 230M parameters
- Aimed at low-latency, privacy-sensitive, and offline use cases
As always with a model this small, the practical question is how much capability survives the compression. Liquid AI's pitch is that a well-tuned tiny model can be good enough for a wide class of on-device tasks — and cheap enough to run almost anywhere. Full details are in the company's announcement.
Sources
More from NVIDIA
All NVIDIA releases →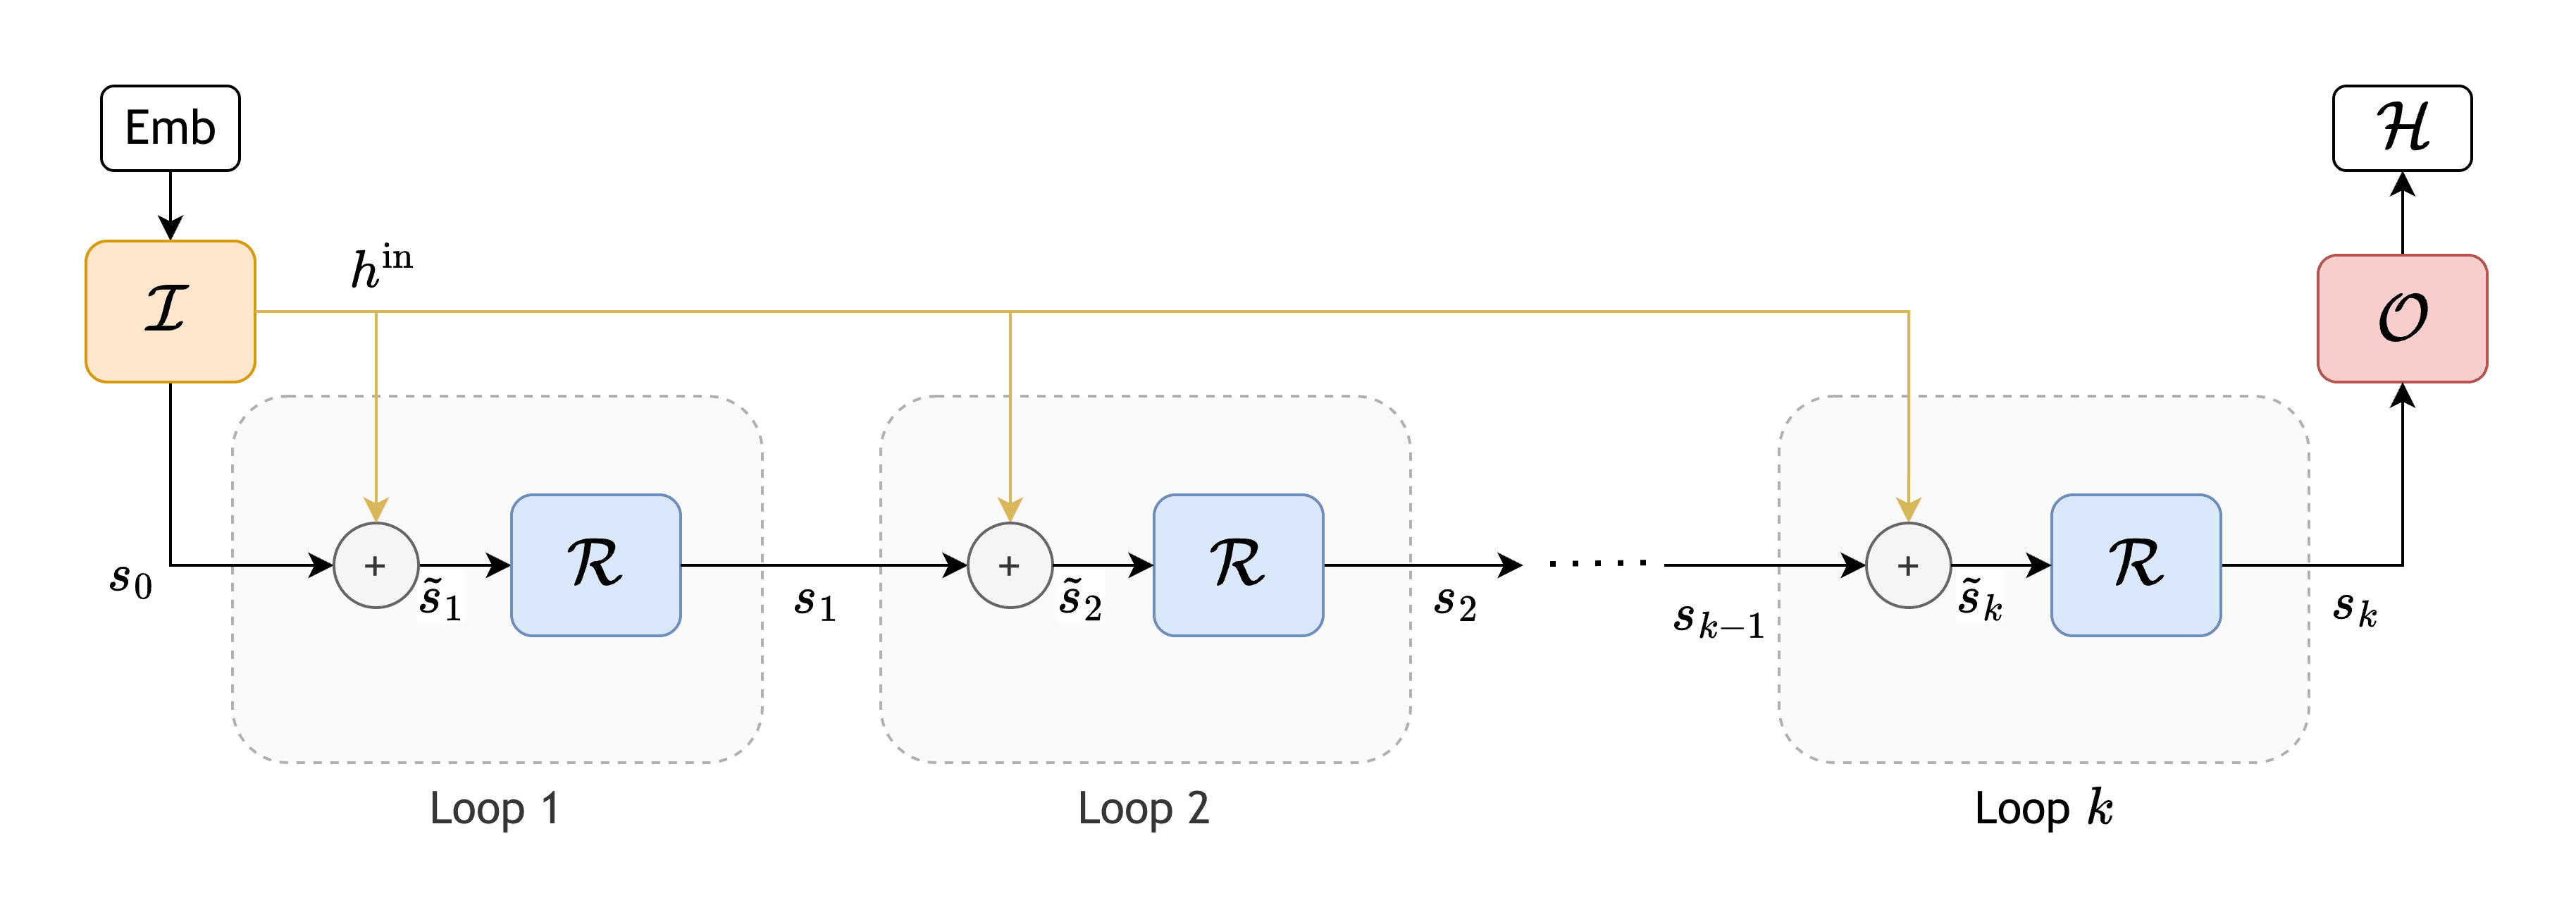
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
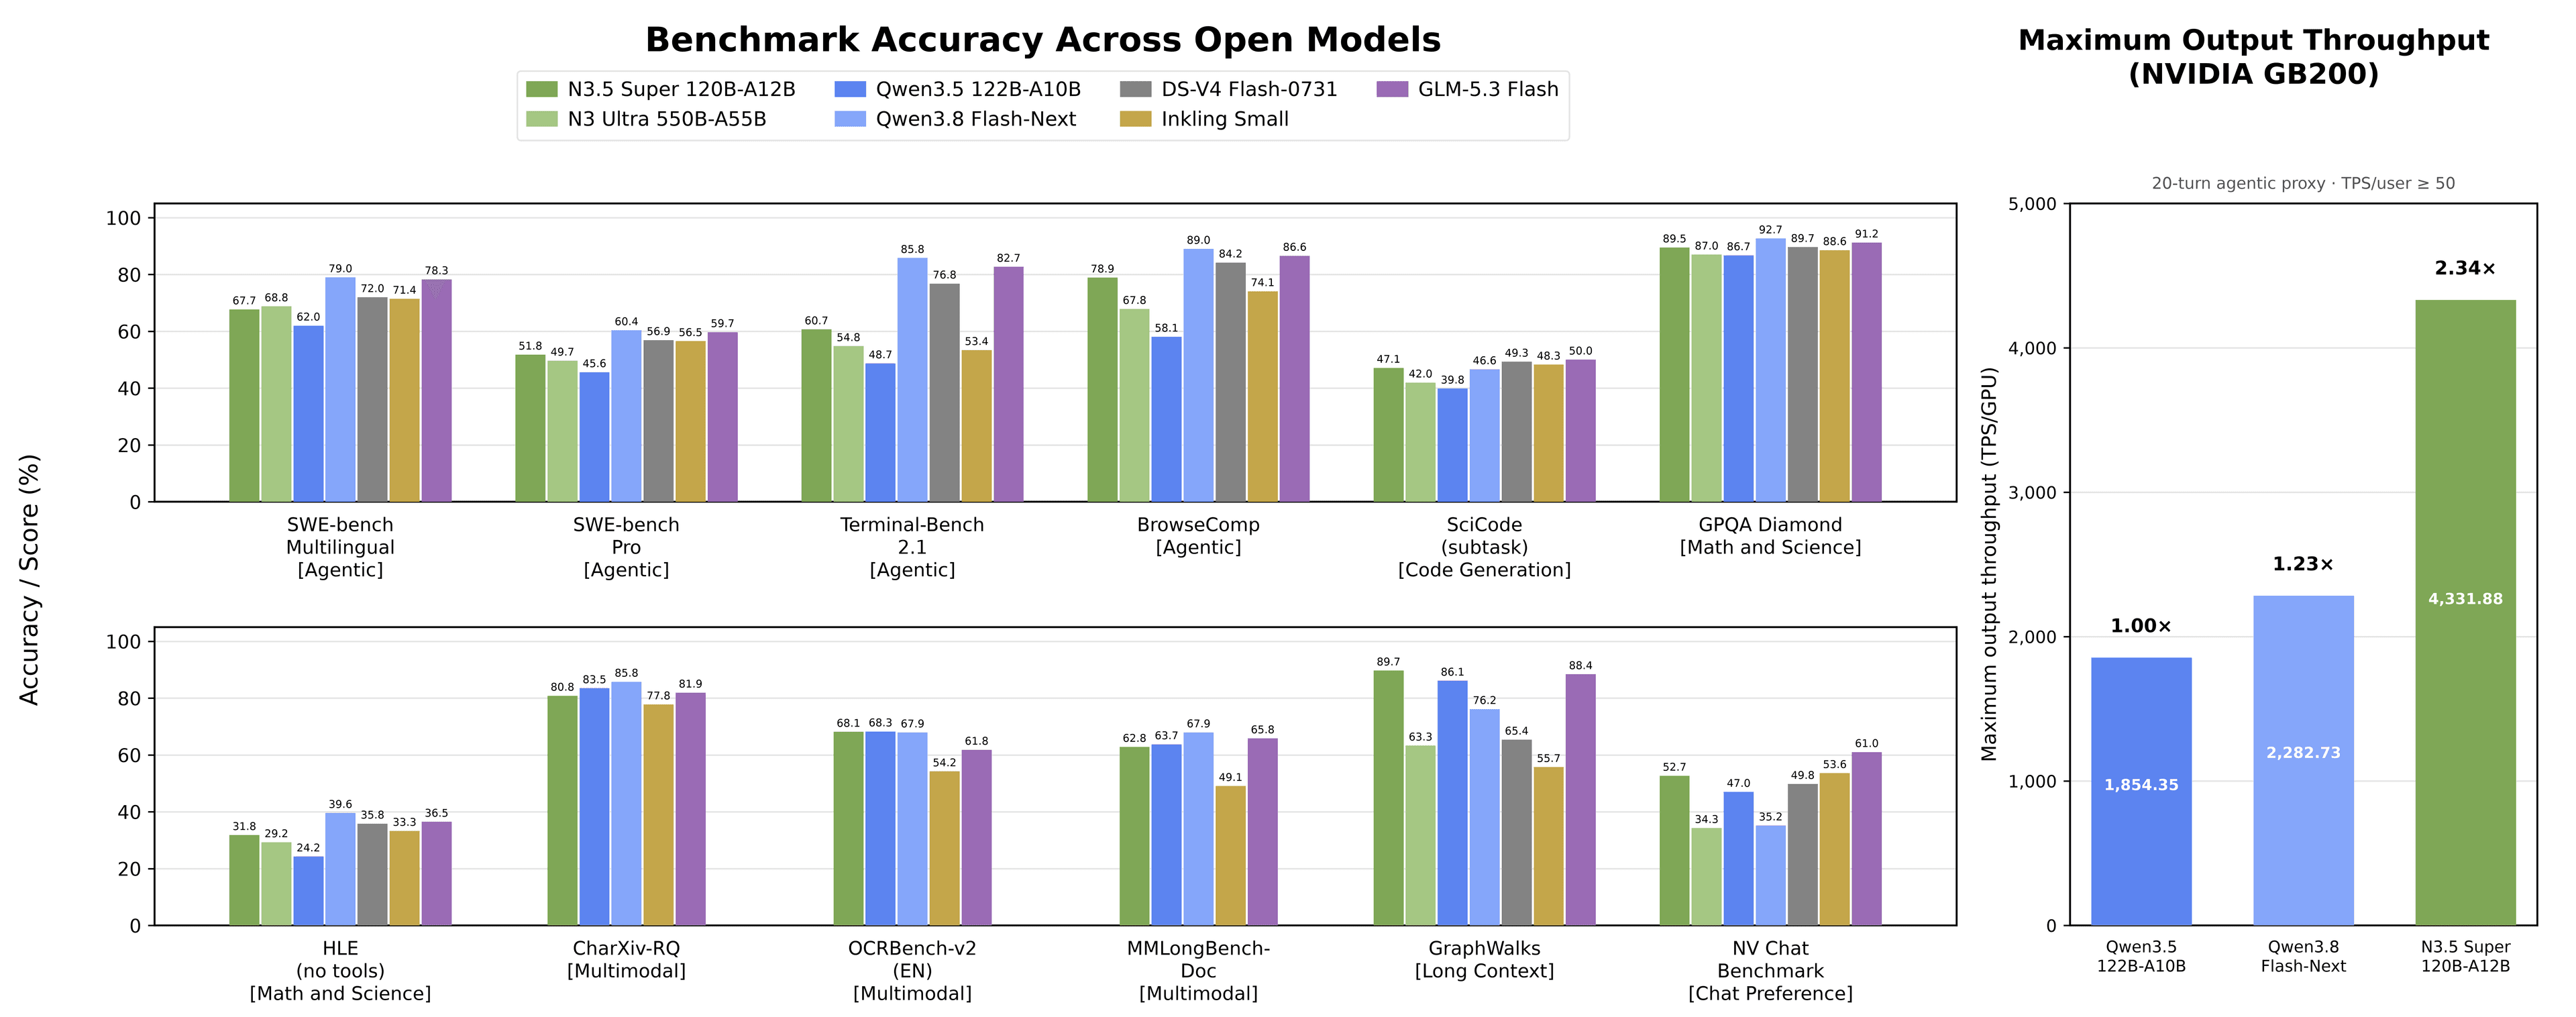
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
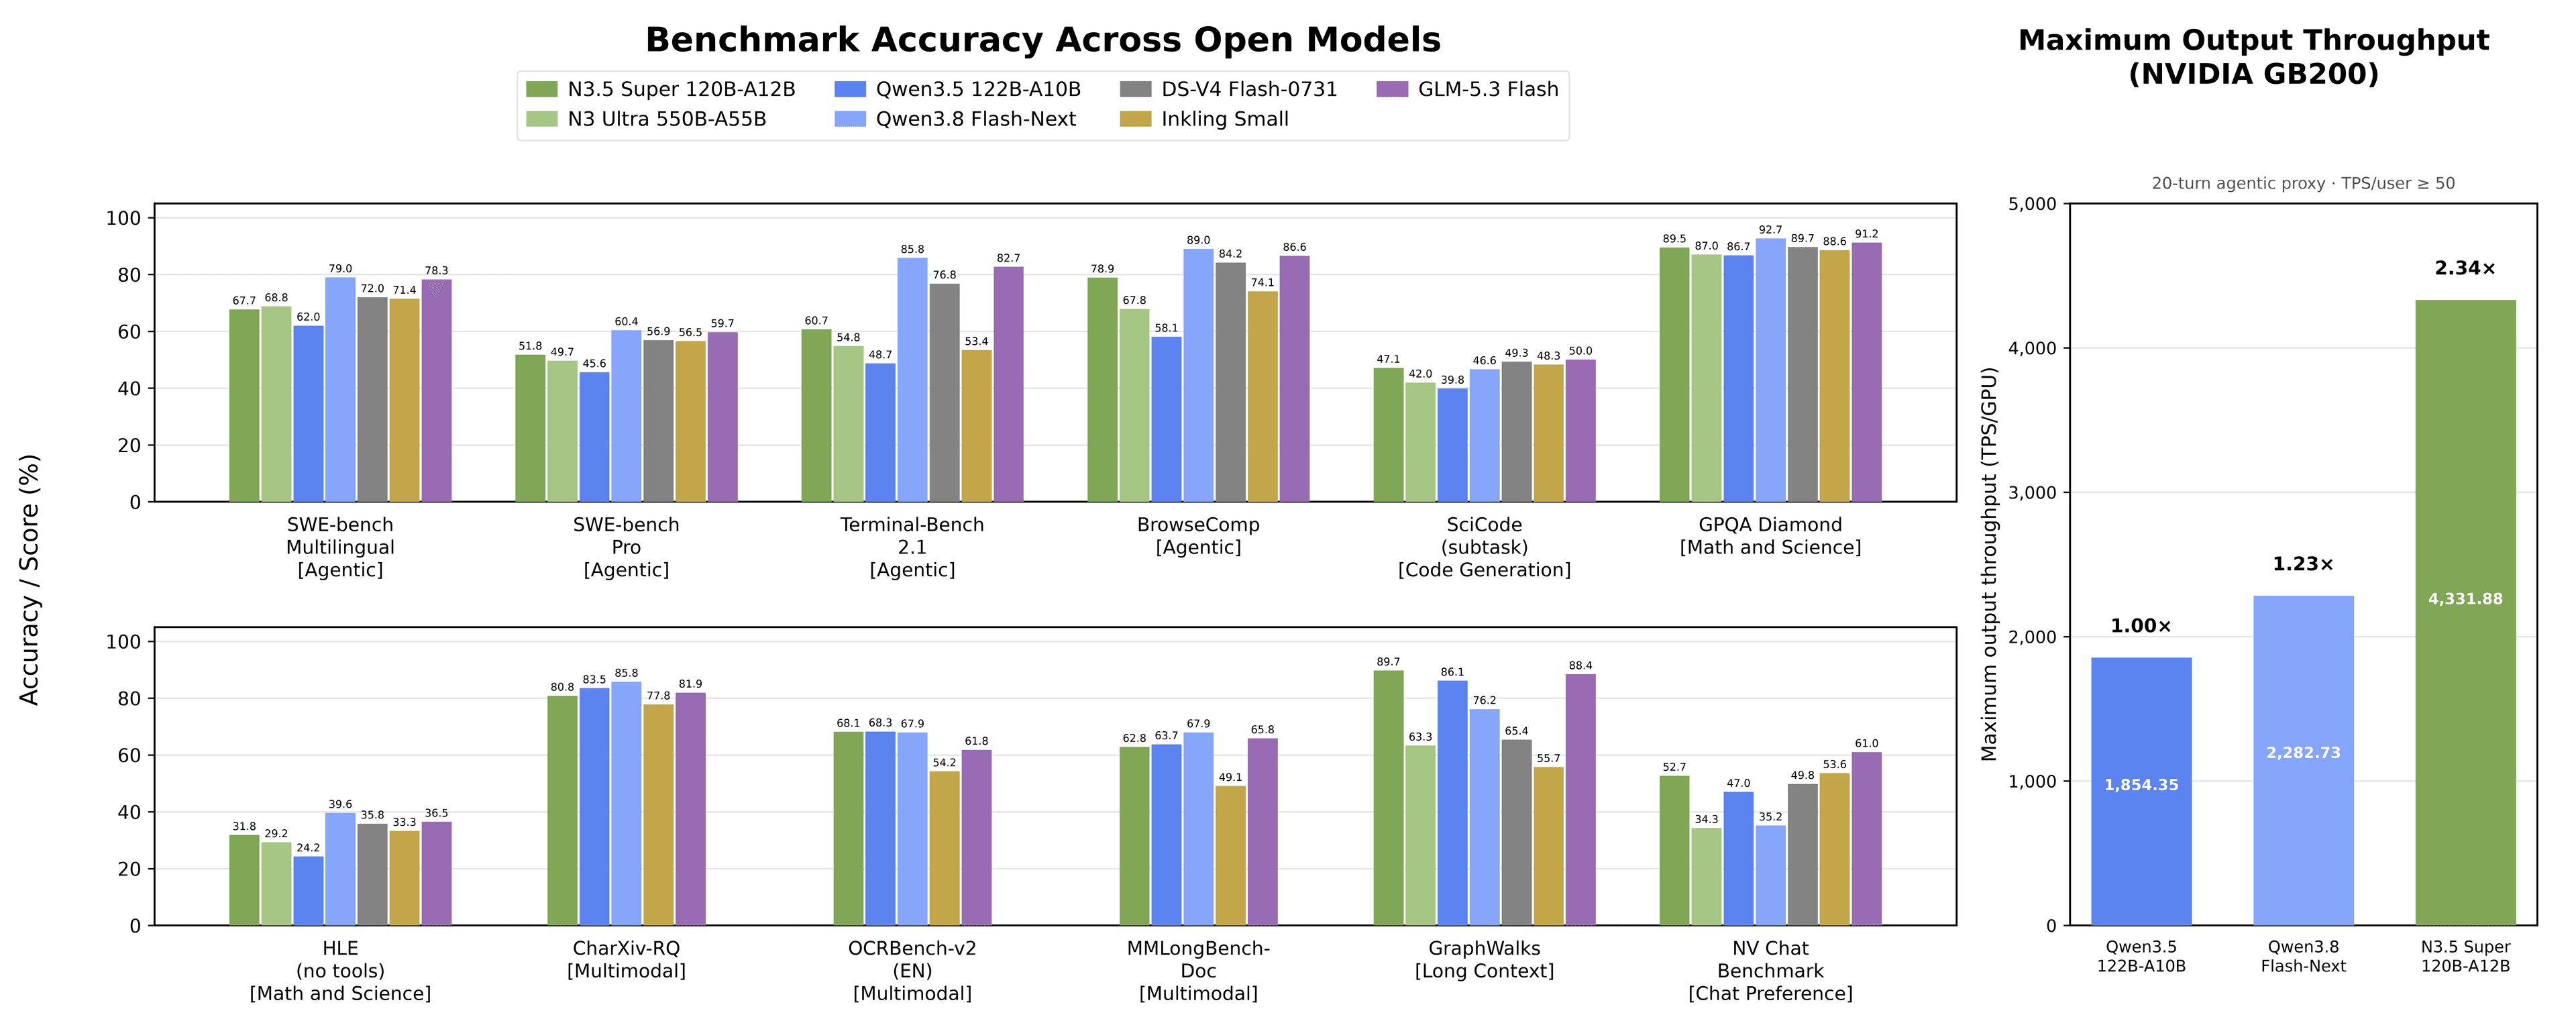
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.