NVIDIA Releases Nemotron-3.5 Streaming ASR Model
The 600-million-parameter model uses a FastConformer architecture for real-time, multilingual speech-to-text applications.
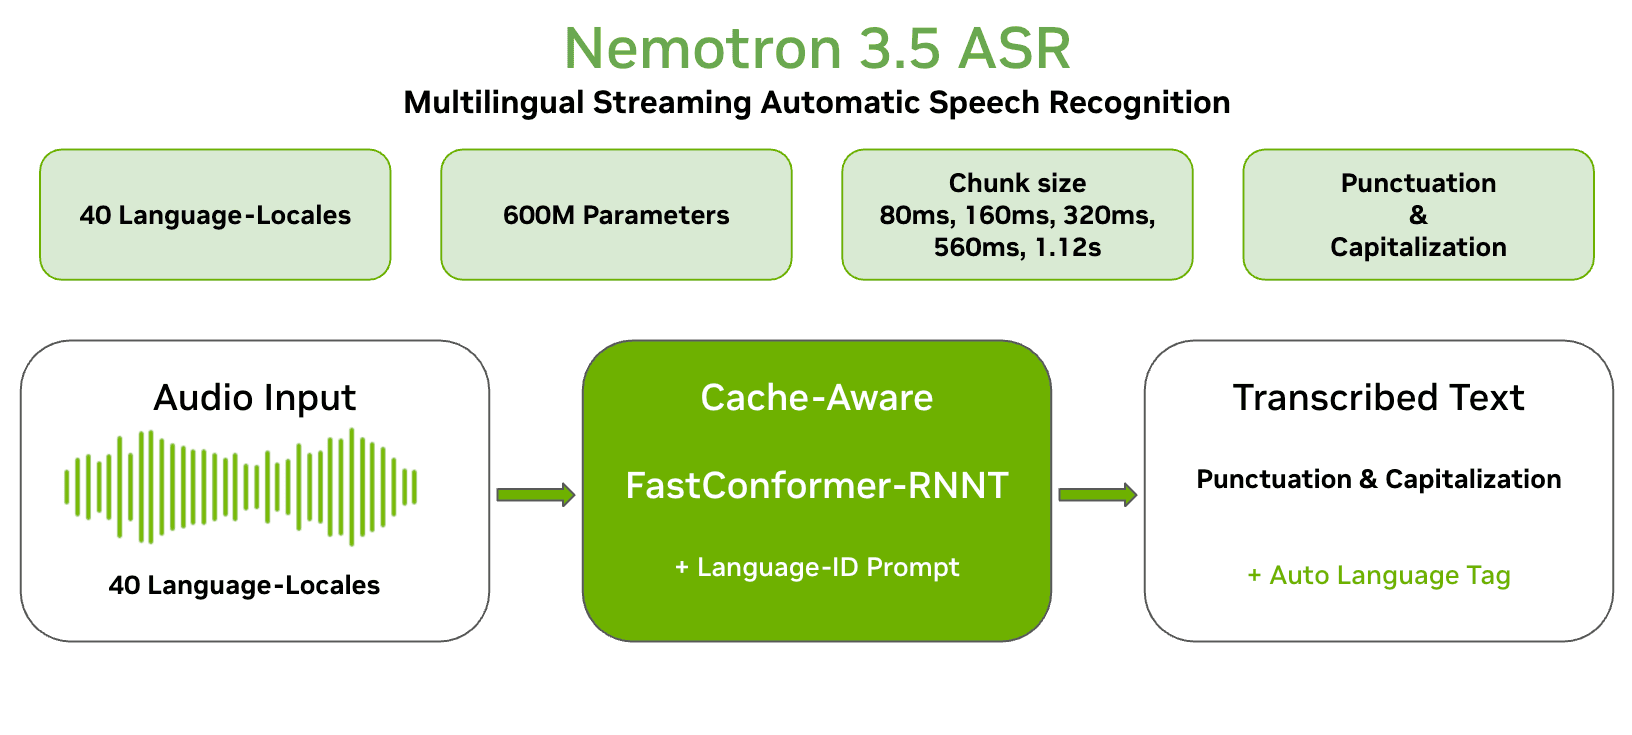
NVIDIA has released Nemotron-3.5 ASR Streaming, a new 600-million-parameter model specialized for automatic speech recognition. Designed for low-latency performance, the model targets applications that require real-time transcription of multilingual audio.
At its core, the model employs a FastConformer architecture paired with a Recurrent Neural Network Transducer (RNN-T) decoder. This design is particularly effective for streaming use cases, as it can process audio in small chunks as it arrives rather than waiting for an entire clip. NVIDIA notes that the model is "cache-aware," an optimization that helps maintain efficiency and speed during continuous audio processing.
This release provides developers with a powerful tool for building features like live captioning, voice command systems, and in-meeting transcription services. While not a general-purpose language model, its specialization makes it a significant addition to the open-source toolkit for speech-based AI.
The model is available on the Hugging Face Hub for download and use. It is released under the NVIDIA Open Model License Agreement, which permits distribution and the creation of derivative works.
Sources
- Visit
nvidia/nemotron-3.5-asr-streaming-0.6b
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
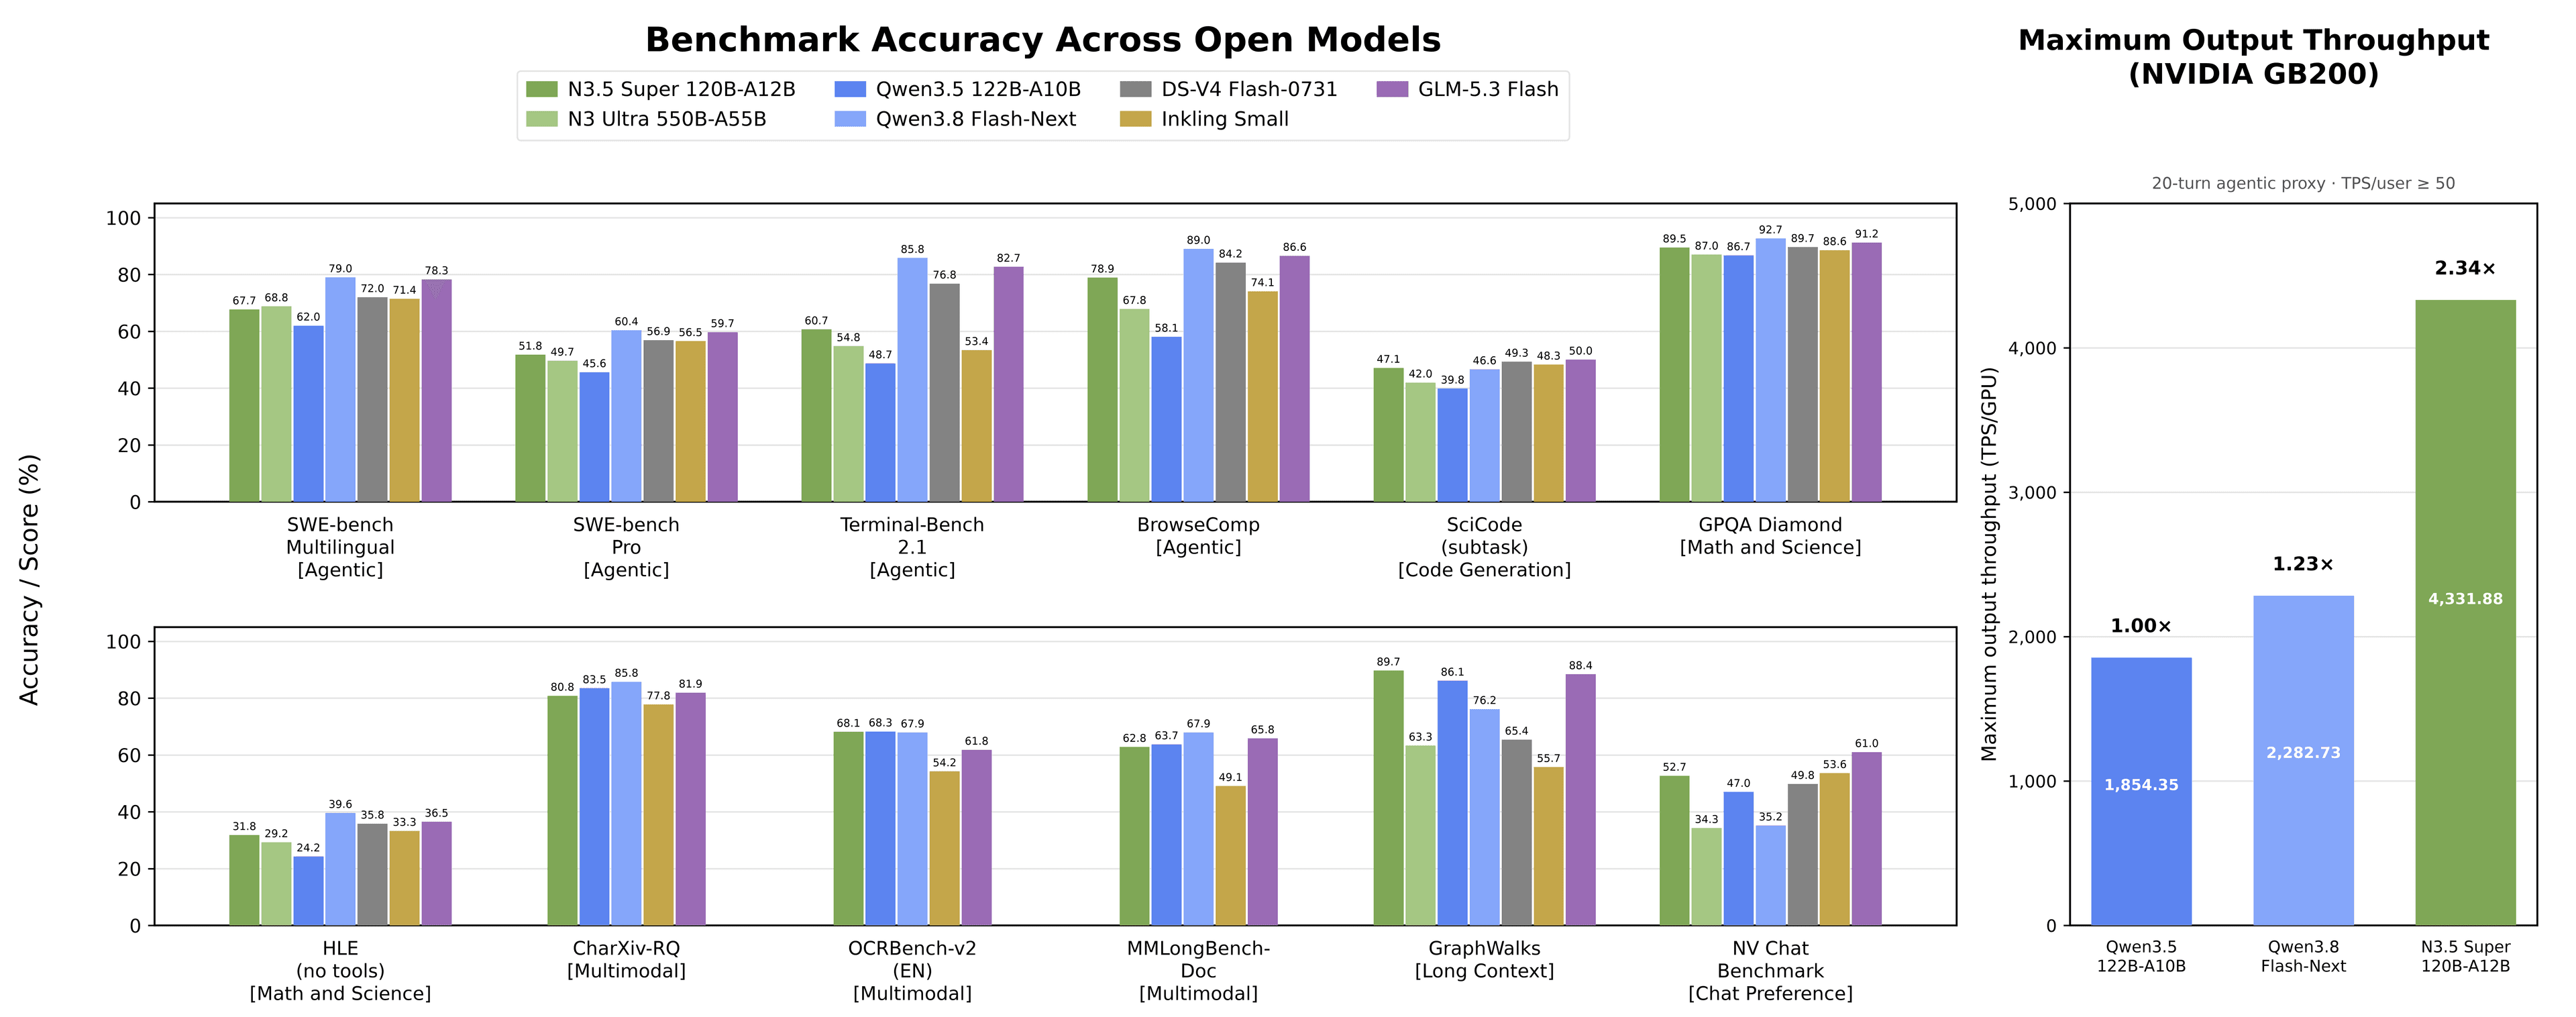
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
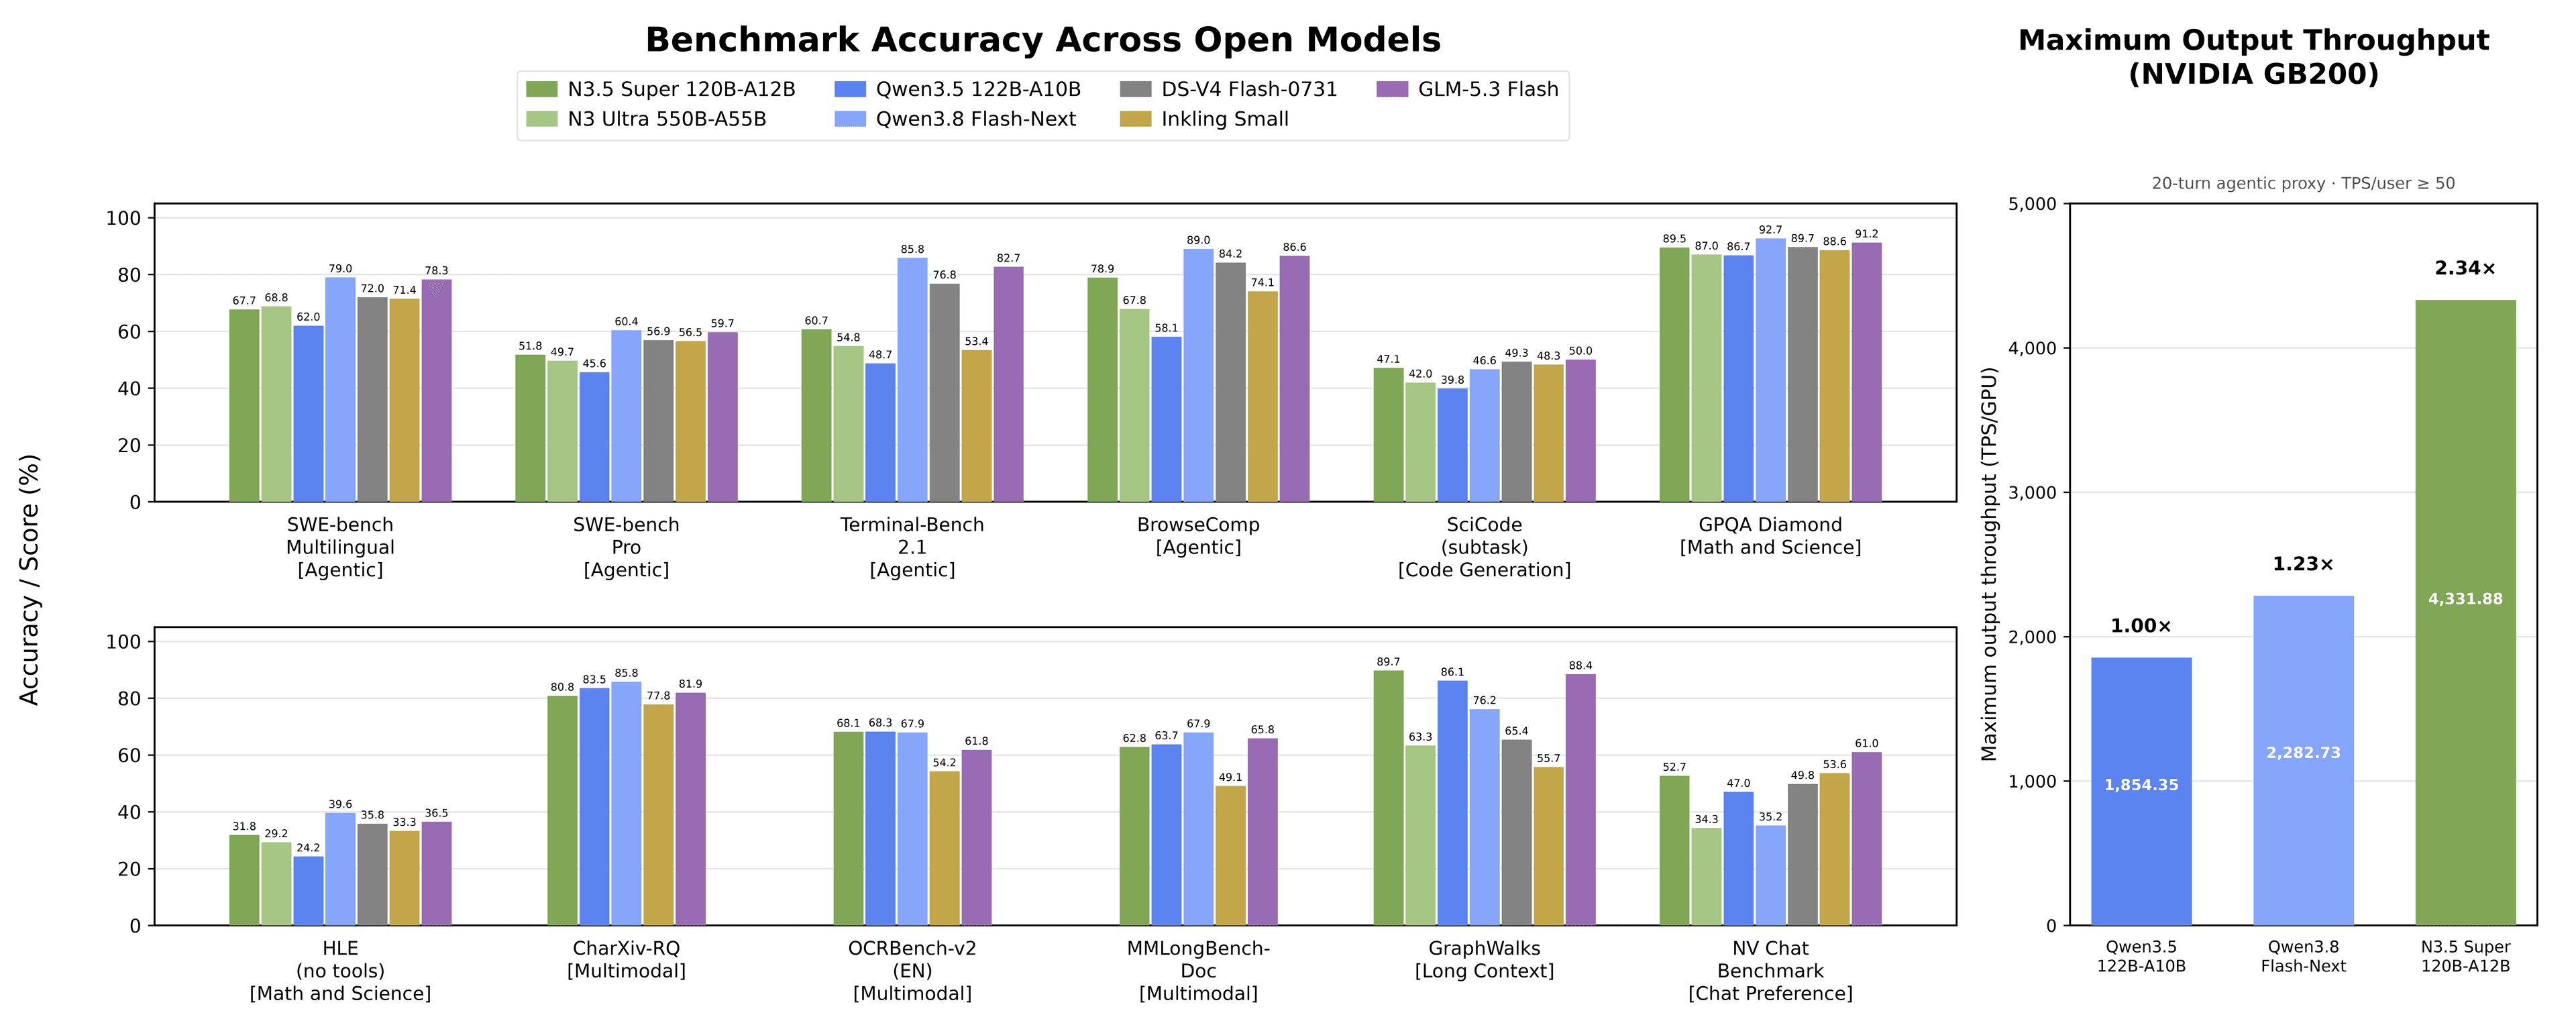
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Speech → Text
All Speech → Text →IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
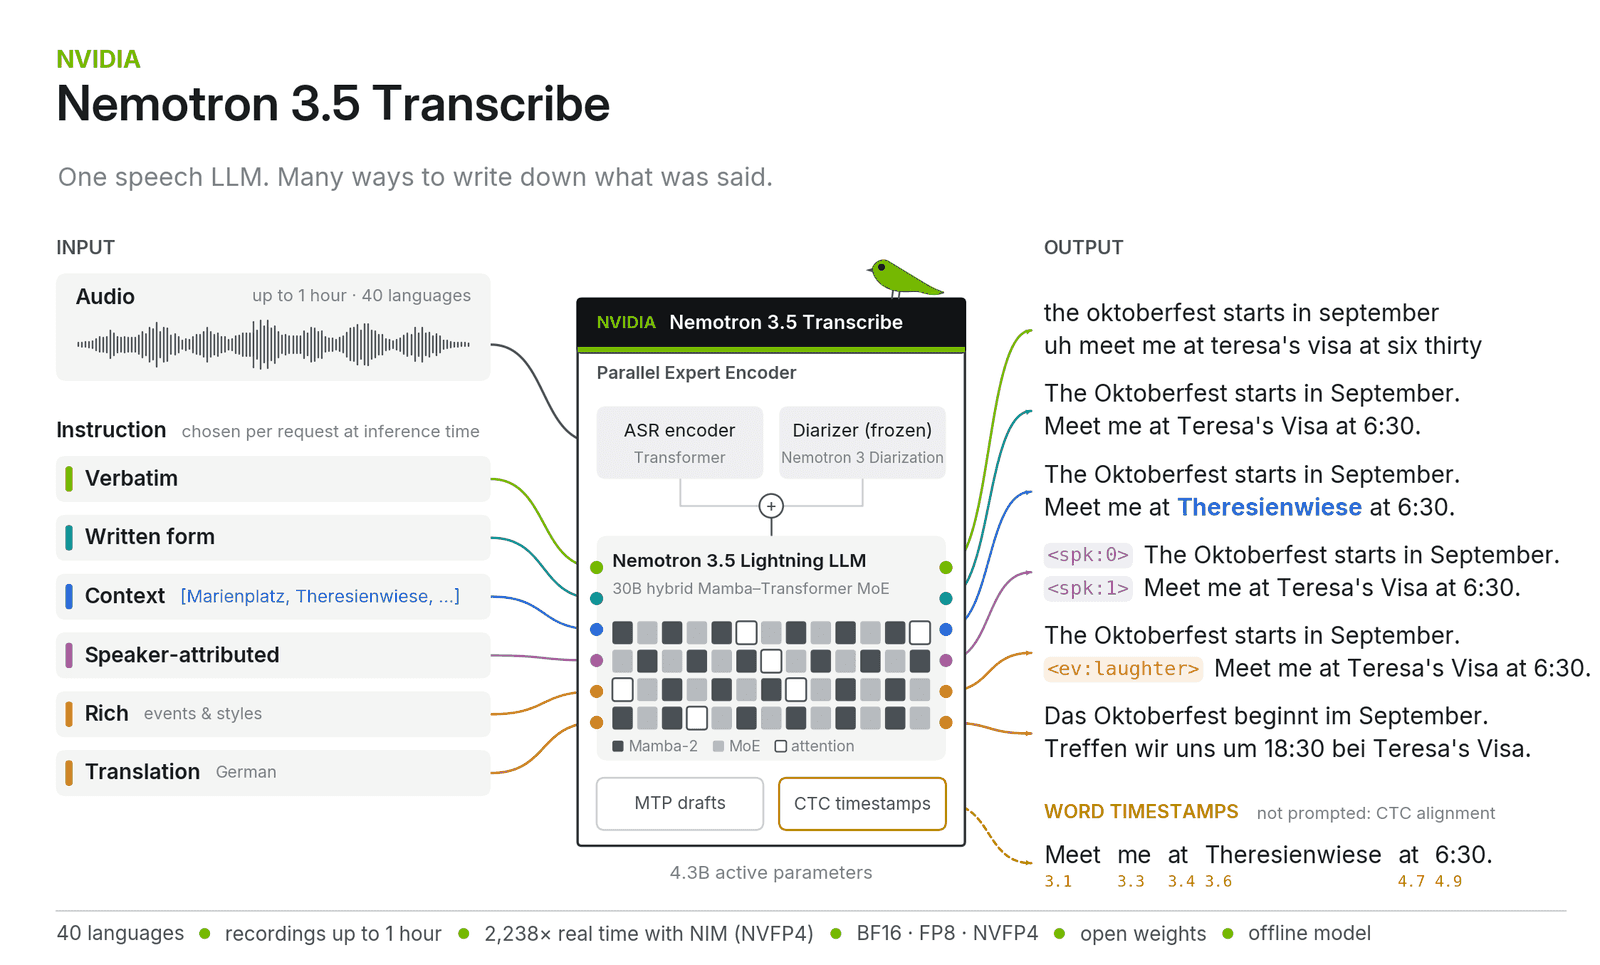
NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR
A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.
0 comments
No comments yet. Be the first to weigh in.