NVIDIA Releases SANA, a Camera-Controllable Video Model
The new model, SANA-WM, uses a bidirectional diffusion process to give creators fine-grained control over camera movement and video editing.

NVIDIA has released a new open-source video generation model called SANA-WM. Standing for "Stochastic Attention and Autoregressive World Model," the system is designed to create video from text or image prompts, with a particular focus on giving the user explicit control over the camera's movement.
The model's key innovation is its use of bidirectional diffusion. Unlike many generative models that create a sequence from start to finish, SANA-WM can work in multiple directions. This allows it to perform tasks that are crucial for practical video editing:
- In-filling: Generating missing frames between a known start and end point.
- Out-painting: Extending a video clip forward or backward in time.
- Looping: Creating seamless video loops by ensuring the end connects to the beginning.
This bidirectional capability is combined with precise camera controls. Users can define a specific camera trajectory, allowing them to dictate pans, zooms, and other movements within the generated scene. This moves beyond simple text-prompting into a more directorial role for the creator, enabling more intentional and dynamic visual storytelling.
Published on Hugging Face by NVIDIA's Efficient Large Model group, SANA-WM is available under a permissive Apache 2.0 license. Its release provides researchers and developers with a powerful tool for exploring controllable and editable video generation, pushing open-source capabilities closer to the sophisticated systems being developed in closed labs.
Sources
- Visit
Efficient-Large-Model/SANA-WM_bidirectional
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
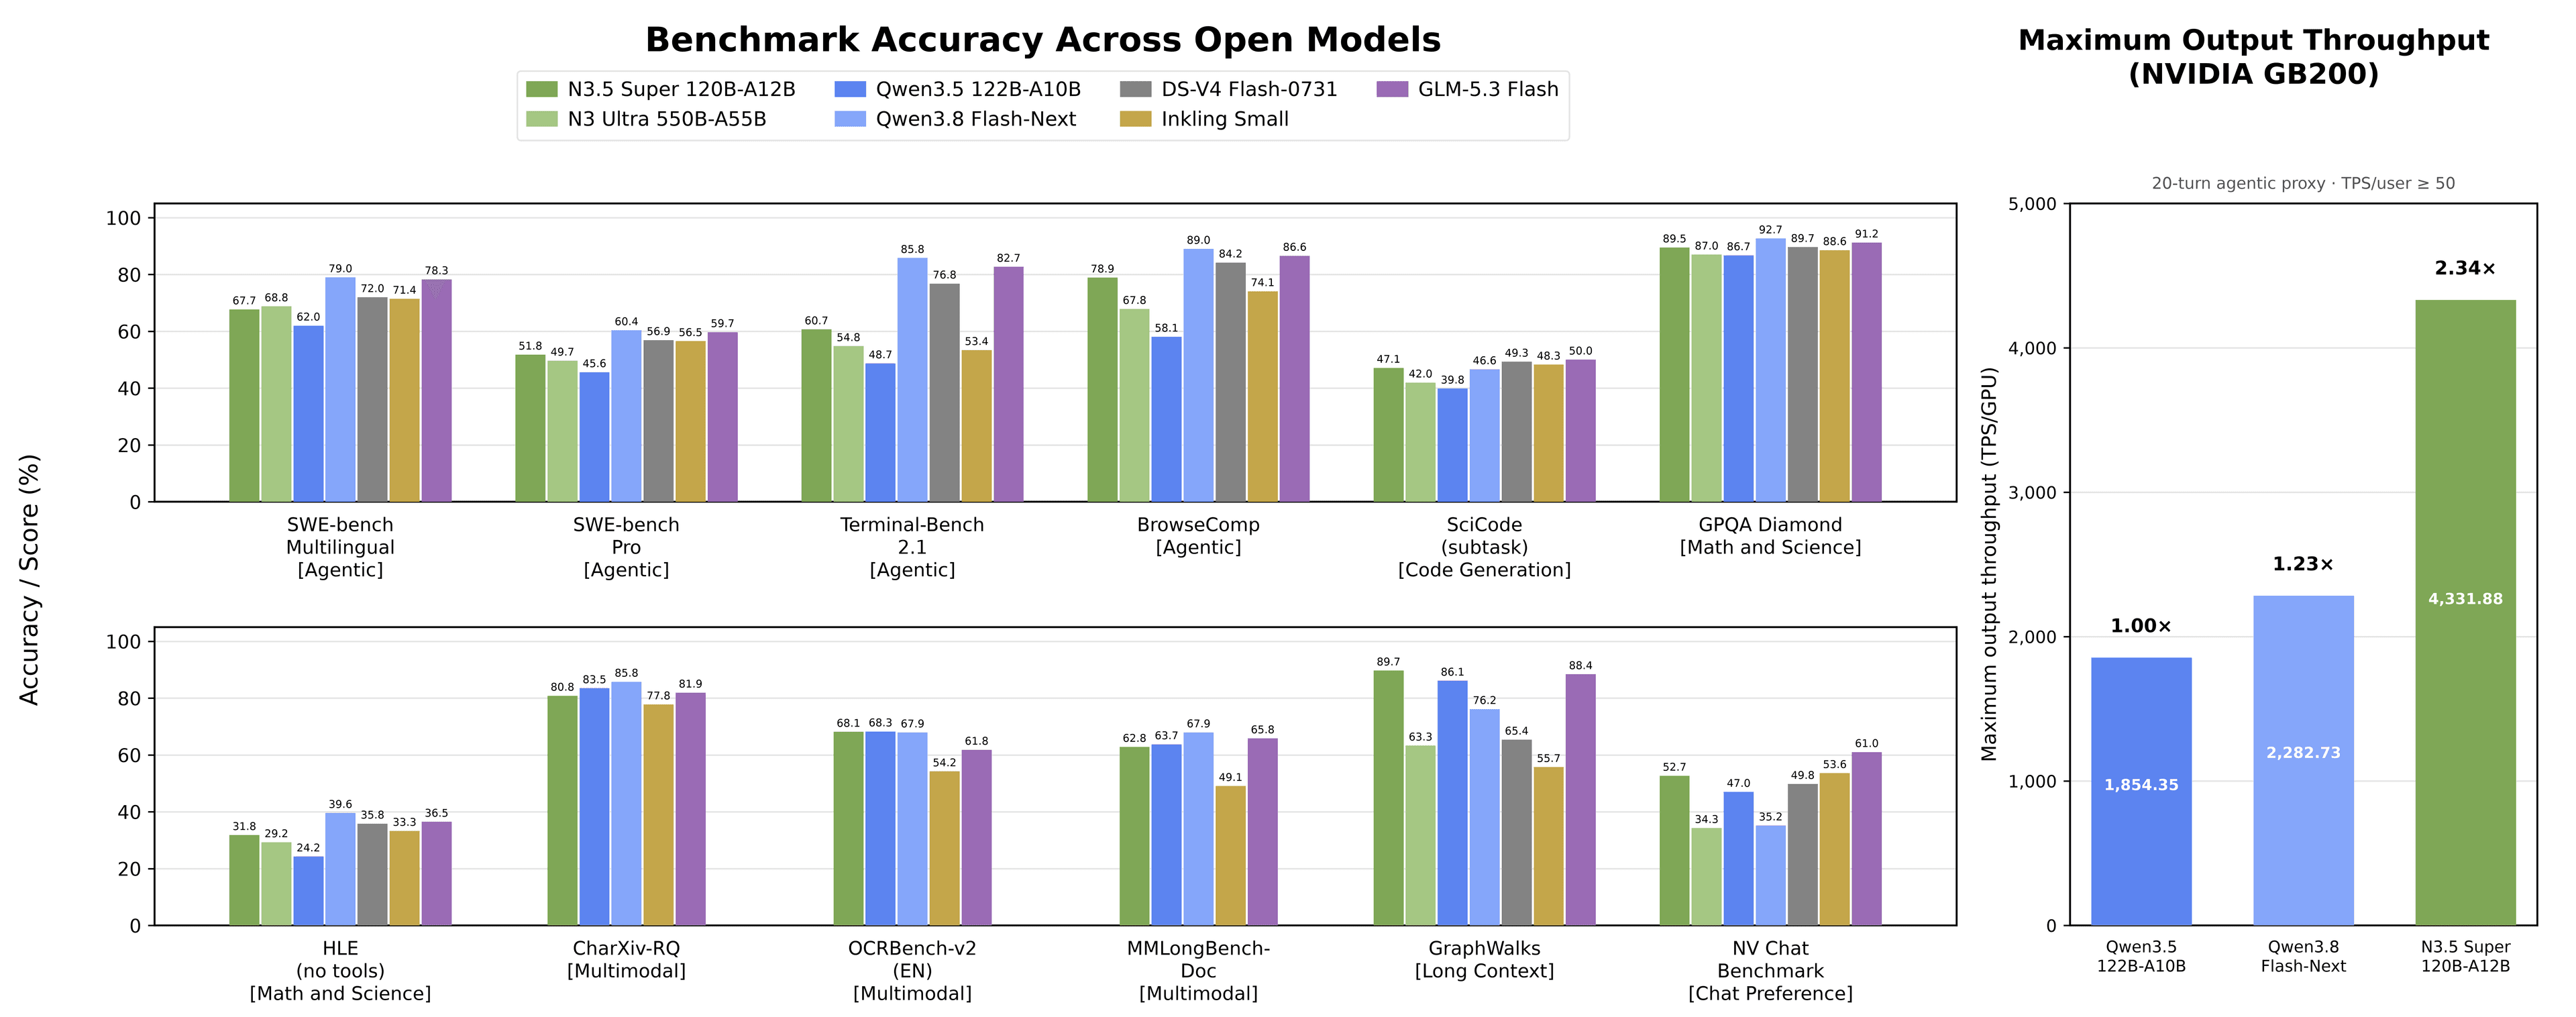
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
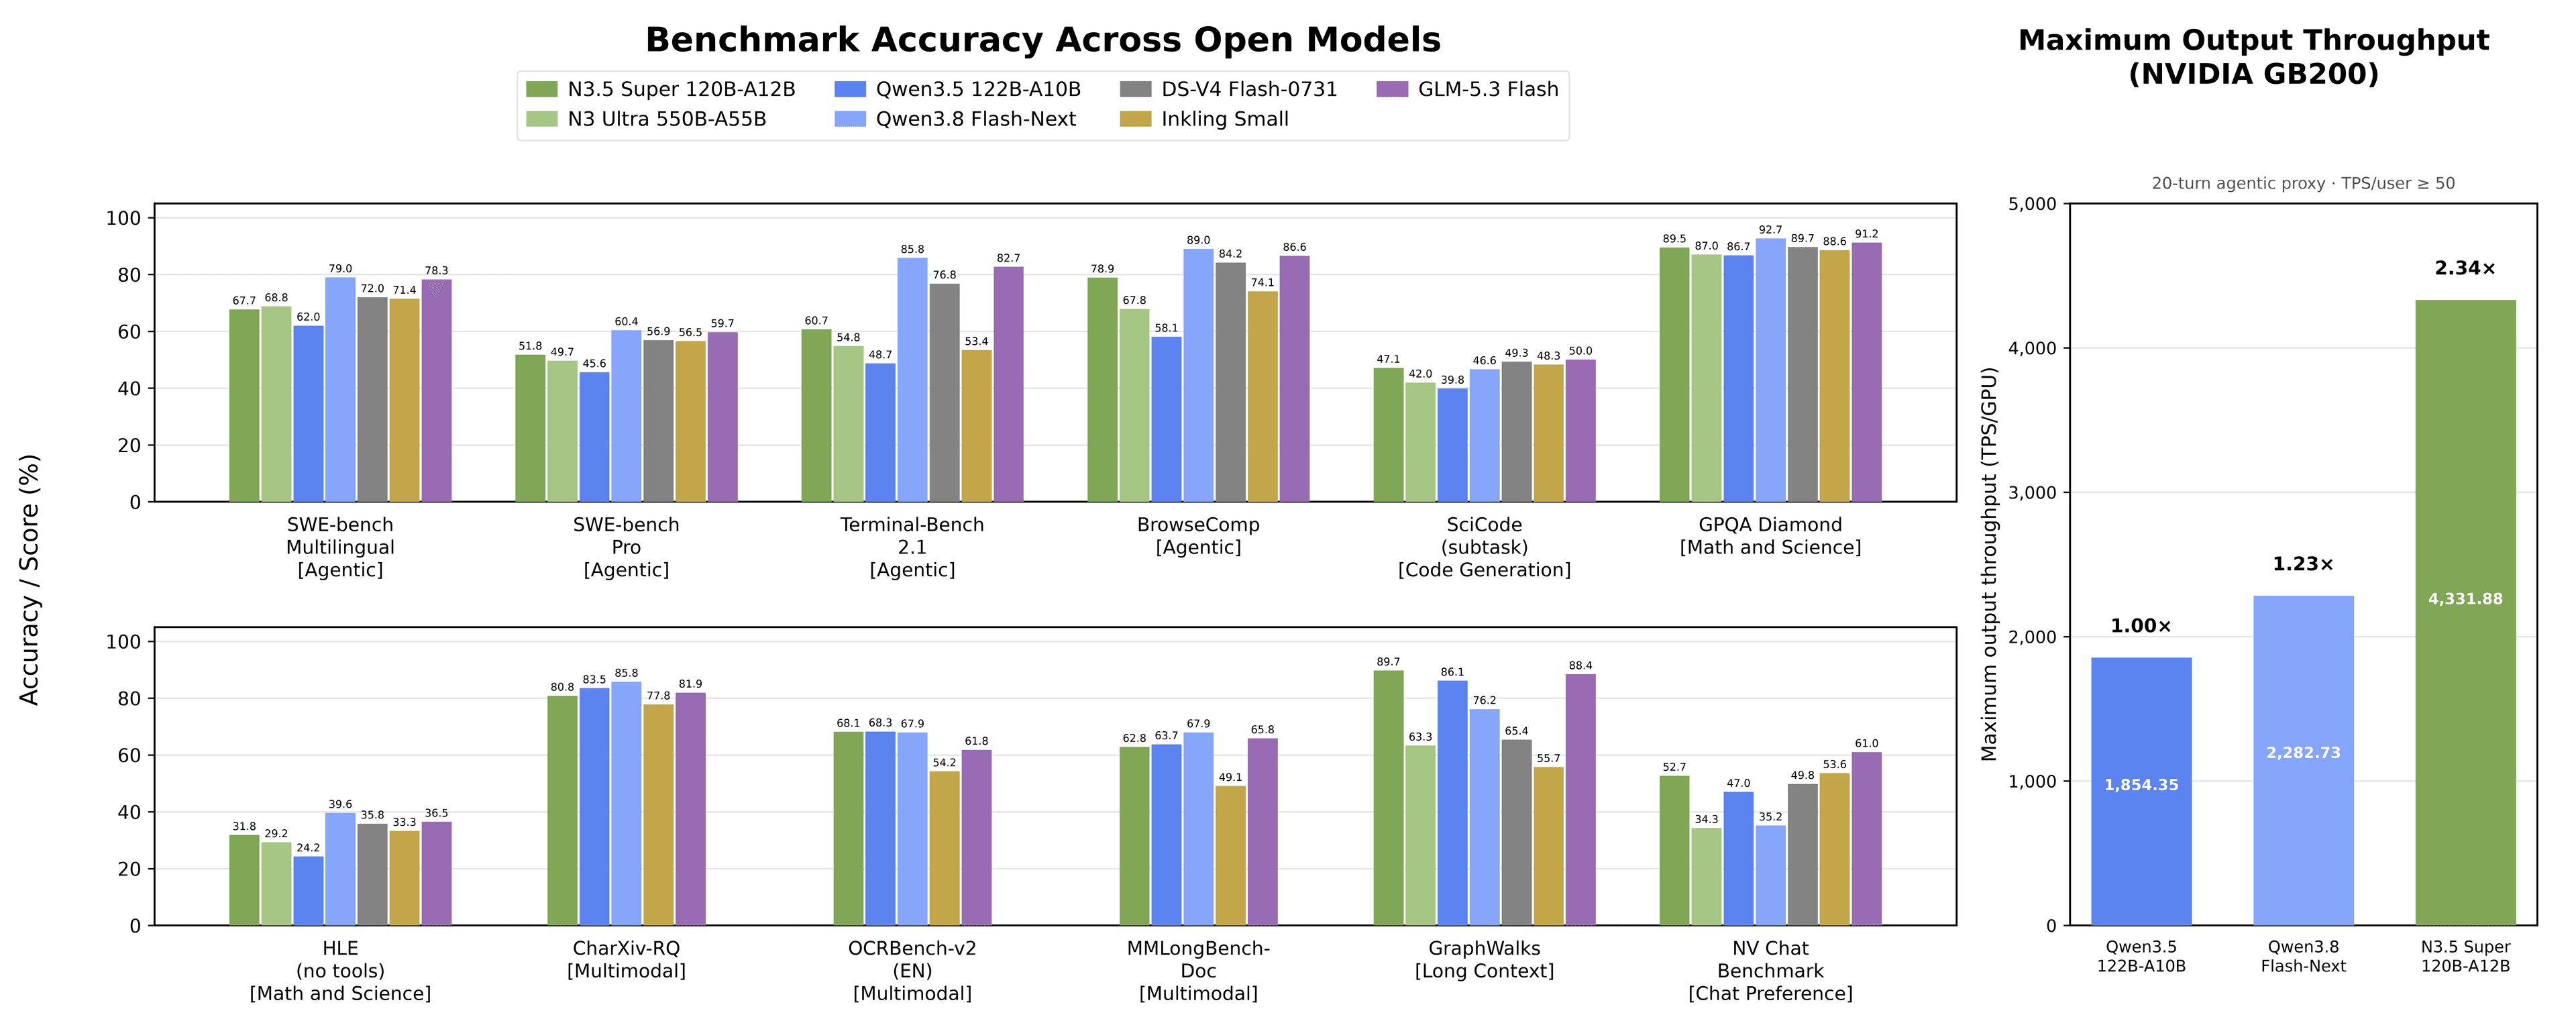
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Image → Video
All Image → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
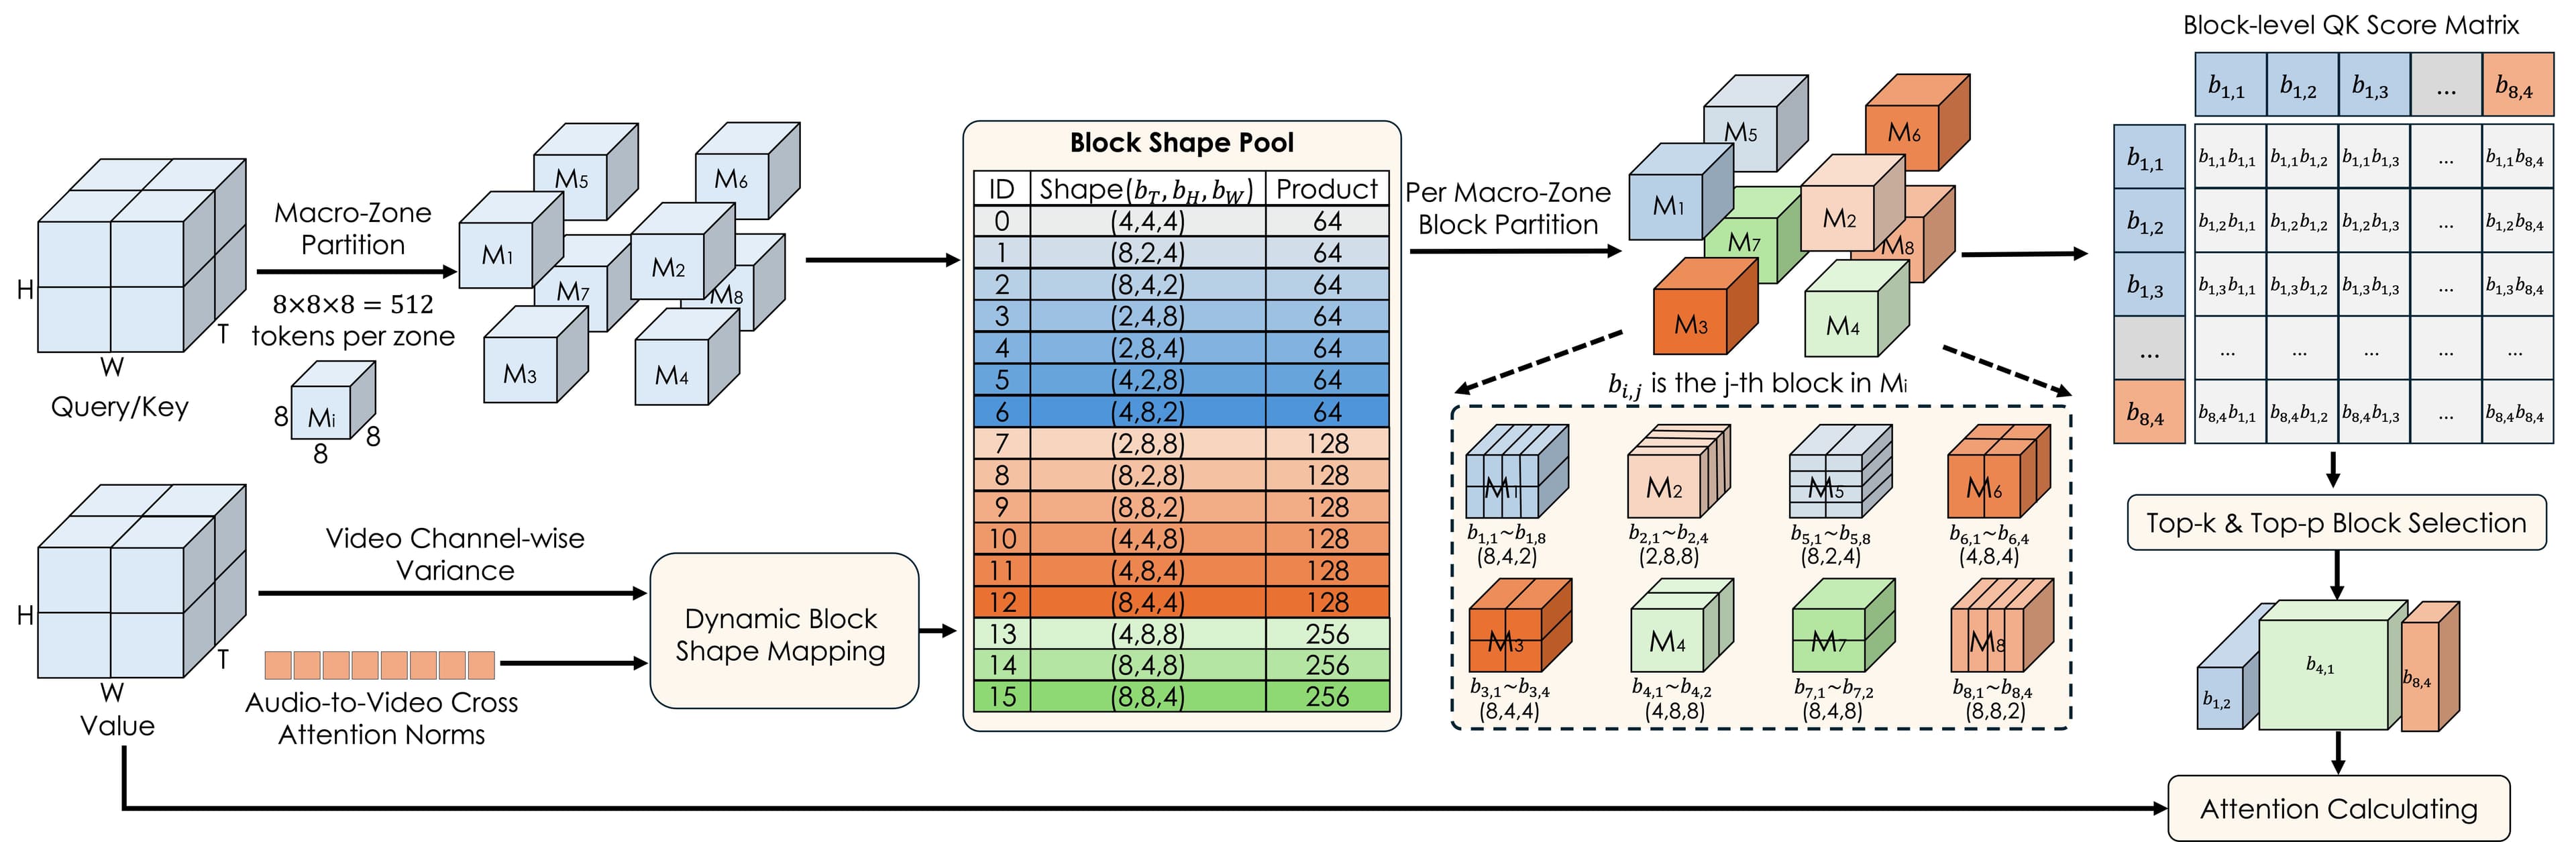
Prism Brings Joint Video-Audio Generation to Diffusion
A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.
Viggle Releases Viggle-Animate for Character Swaps
The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.
0 comments
No comments yet. Be the first to weigh in.