Viggle Releases Viggle-Animate for Character Swaps
The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.
Viggle has published Viggle-Animate on Hugging Face, an image-to-video model aimed at video editing and character replacement. The release marks the debut of the Animate line under Viggle's name.
The model is described as a distillation of MiniMax-H3, a technique that trains a smaller or more efficient model to reproduce the behavior of a larger parent. Distillation is a common route to faster inference and lower compute costs, which matters for video work where generation is expensive.
What it does
According to the model page, the focus is squarely on editing existing footage rather than generating clips from scratch:
- Character replacement, swapping a subject in a video for a new one
- General video editing tasks driven by an input image
Several technical details remain unspecified in the release record, including output resolution, frame rate, and maximum clip duration. The model ships under a non-standard "other" license, so teams evaluating it for production should read the terms carefully before building on top of it.
Why it matters: character-driven video editing has been one of the harder problems to open up, and Viggle's move puts a purpose-built tool in the hands of developers who want to experiment without a closed API. As with any distilled model, the real test will be how closely its quality tracks the MiniMax-H3 system it learns from.
Sources
- Visit
Viggle/Viggle-Animate
Hugging Face
More in Image → Video
All Image → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
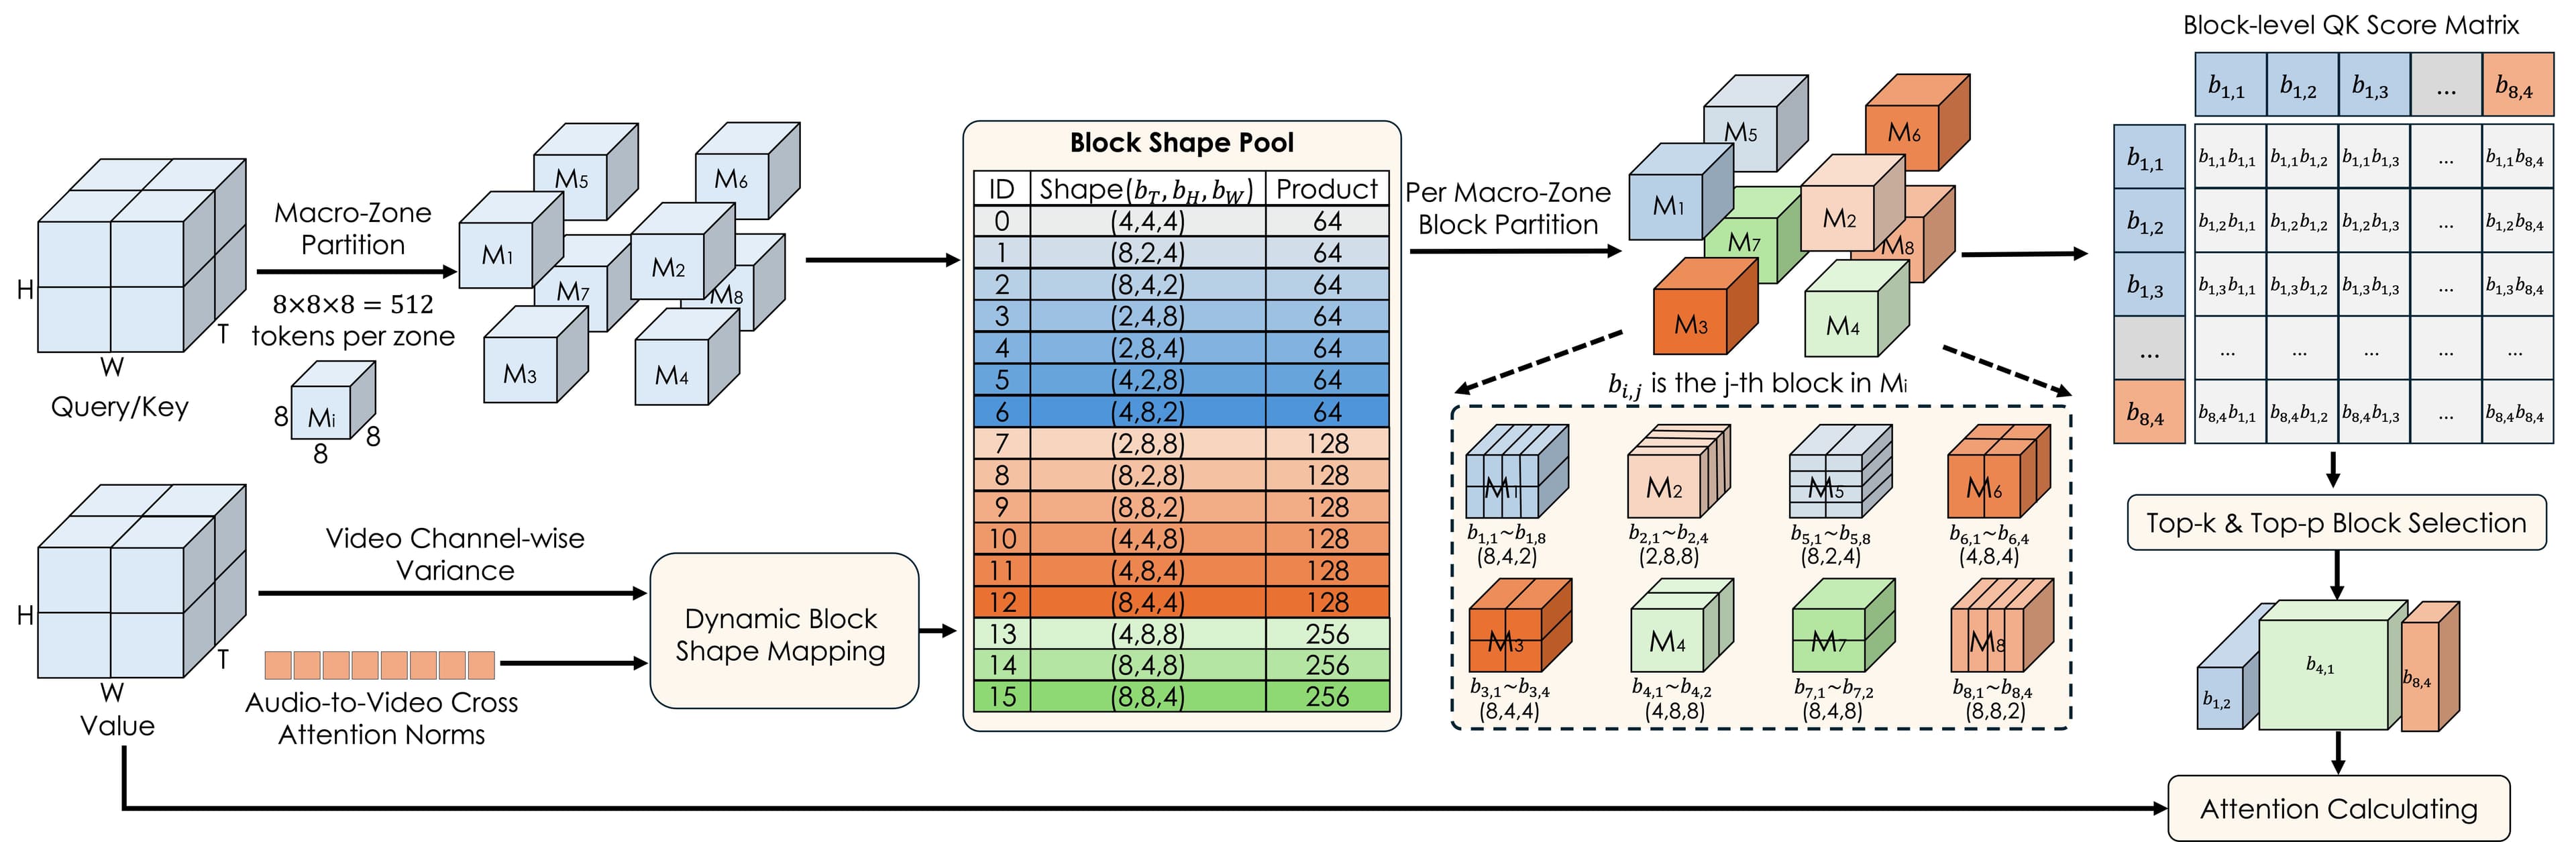
Prism Brings Joint Video-Audio Generation to Diffusion
A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.
Ant Research releases 4DAnyone for 4D human video
The new open model turns a single input into multiview video and reconstructs humans for novel-view synthesis.
0 comments
No comments yet. Be the first to weigh in.