Ant Research releases 4DAnyone for 4D human video
The new open model turns a single input into multiview video and reconstructs humans for novel-view synthesis.
Ant Group's research arm has published 4DAnyone, an image-to-video model focused on multiview video generation and 4D human reconstruction. The release is available now on Hugging Face under a custom license.
The system targets a difficult problem in computer vision: taking limited input and producing consistent views of a person across both space and time — the "4D" framing that combines three-dimensional geometry with motion. That pipeline enables novel-view synthesis, where a scene can be rendered from camera angles that were never actually captured.
Why it matters
Reconstructing believable, moving humans from sparse input has clear applications in virtual production, telepresence, gaming, and digital avatars. Open releases in this space are still relatively rare, so a publicly available model from a major industrial lab gives researchers and developers something concrete to build on and evaluate.
- Primary task: image-to-video generation
- Focus: multiview output and 4D human reconstruction
- Access: open weights on Hugging Face, custom license
- Version: 1.0, the family's initial release
As a first release labeled version 1.0, 4DAnyone is an early marker rather than a finished product, and the custom license means teams should review terms before commercial use. Full details, including any usage restrictions, are on the project's Hugging Face page.
Sources
- Visit
AntResearch/4DAnyone
Hugging Face
More in Image → Video
All Image → Video →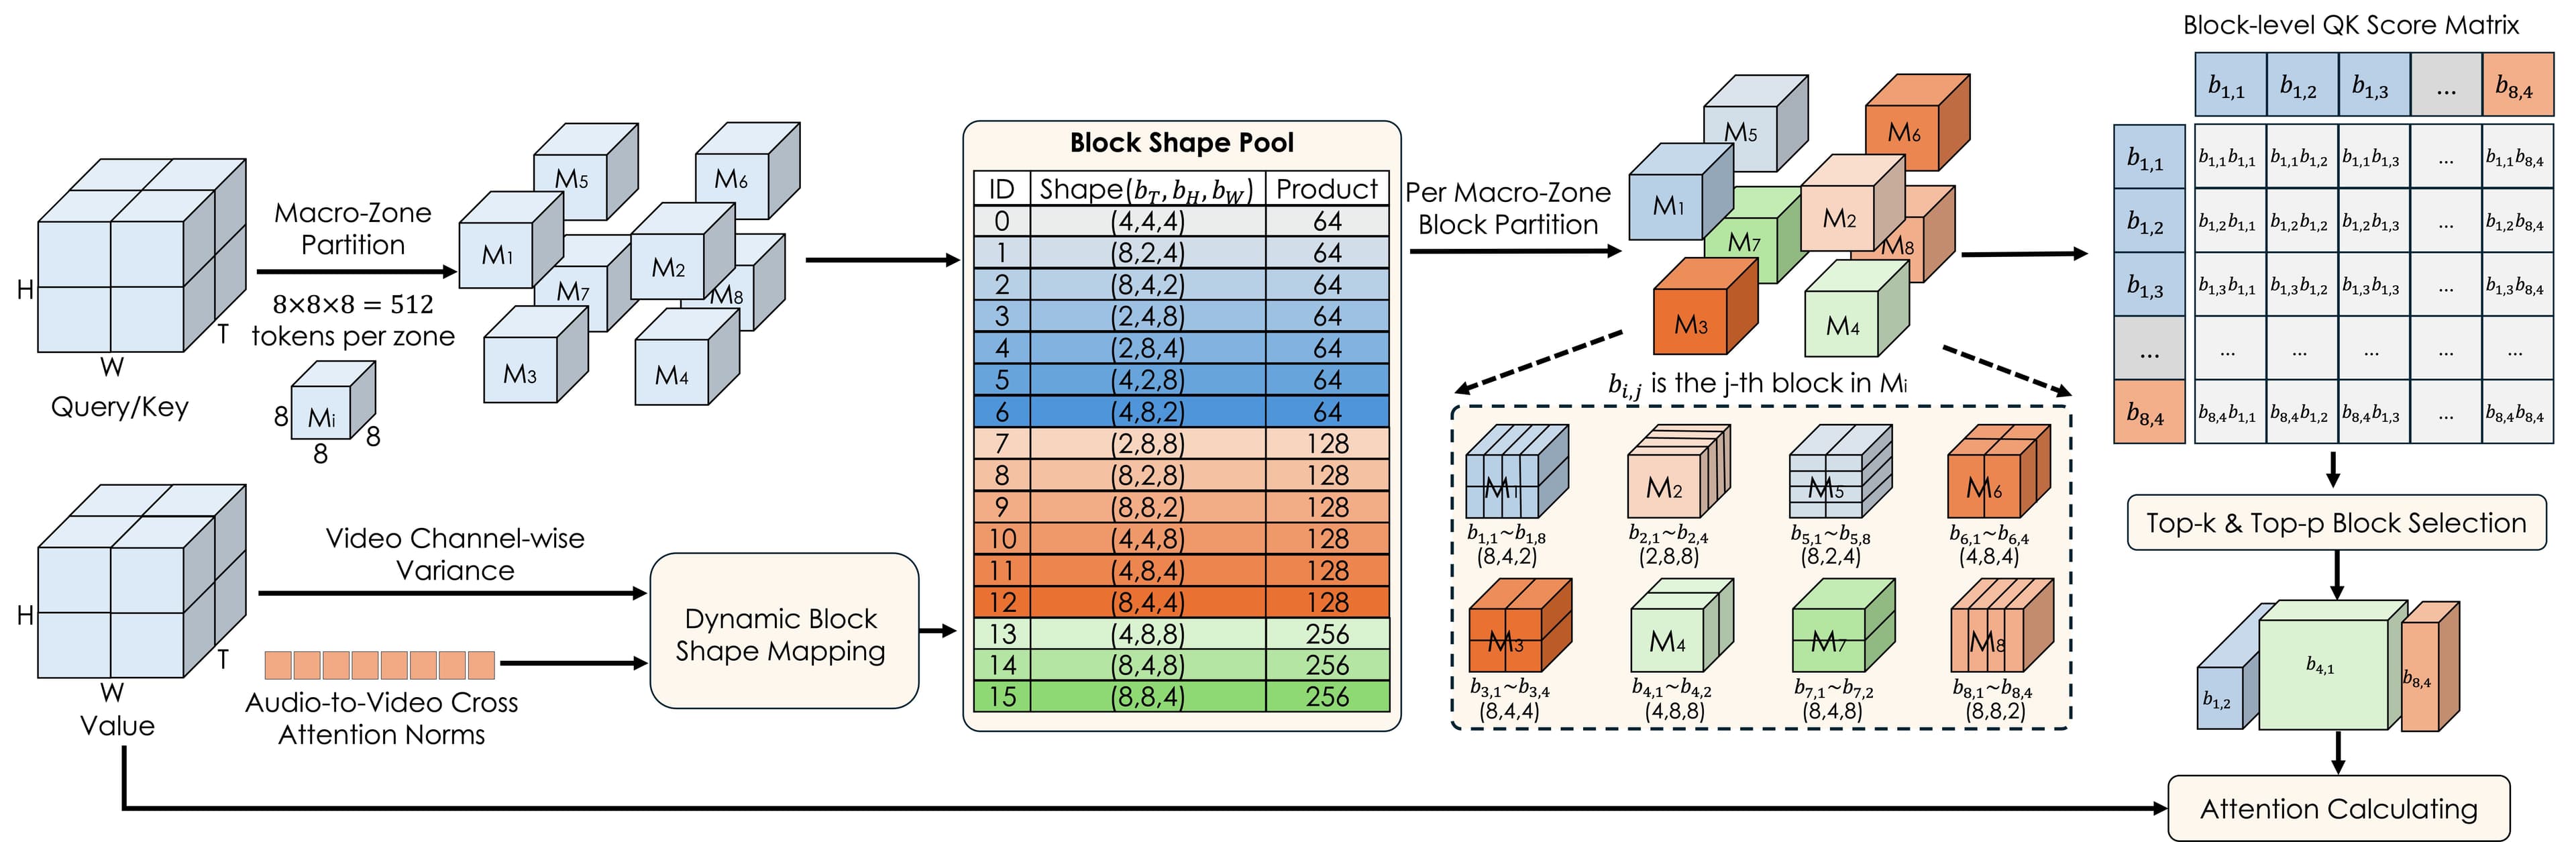
Prism Brings Joint Video-Audio Generation to Diffusion
A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.
Viggle Releases Viggle-Animate for Character Swaps
The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.
MiniMax Releases H3 Video Model on Hugging Face
The company's new diffusion model handles text-to-video and image-to-video, with support for joint audio-video generation.
0 comments
No comments yet. Be the first to weigh in.