Meituan's LongCat Adds Audio-Driven Avatar Video
The LongCat team releases an image-to-video model that animates still portraits from audio input.
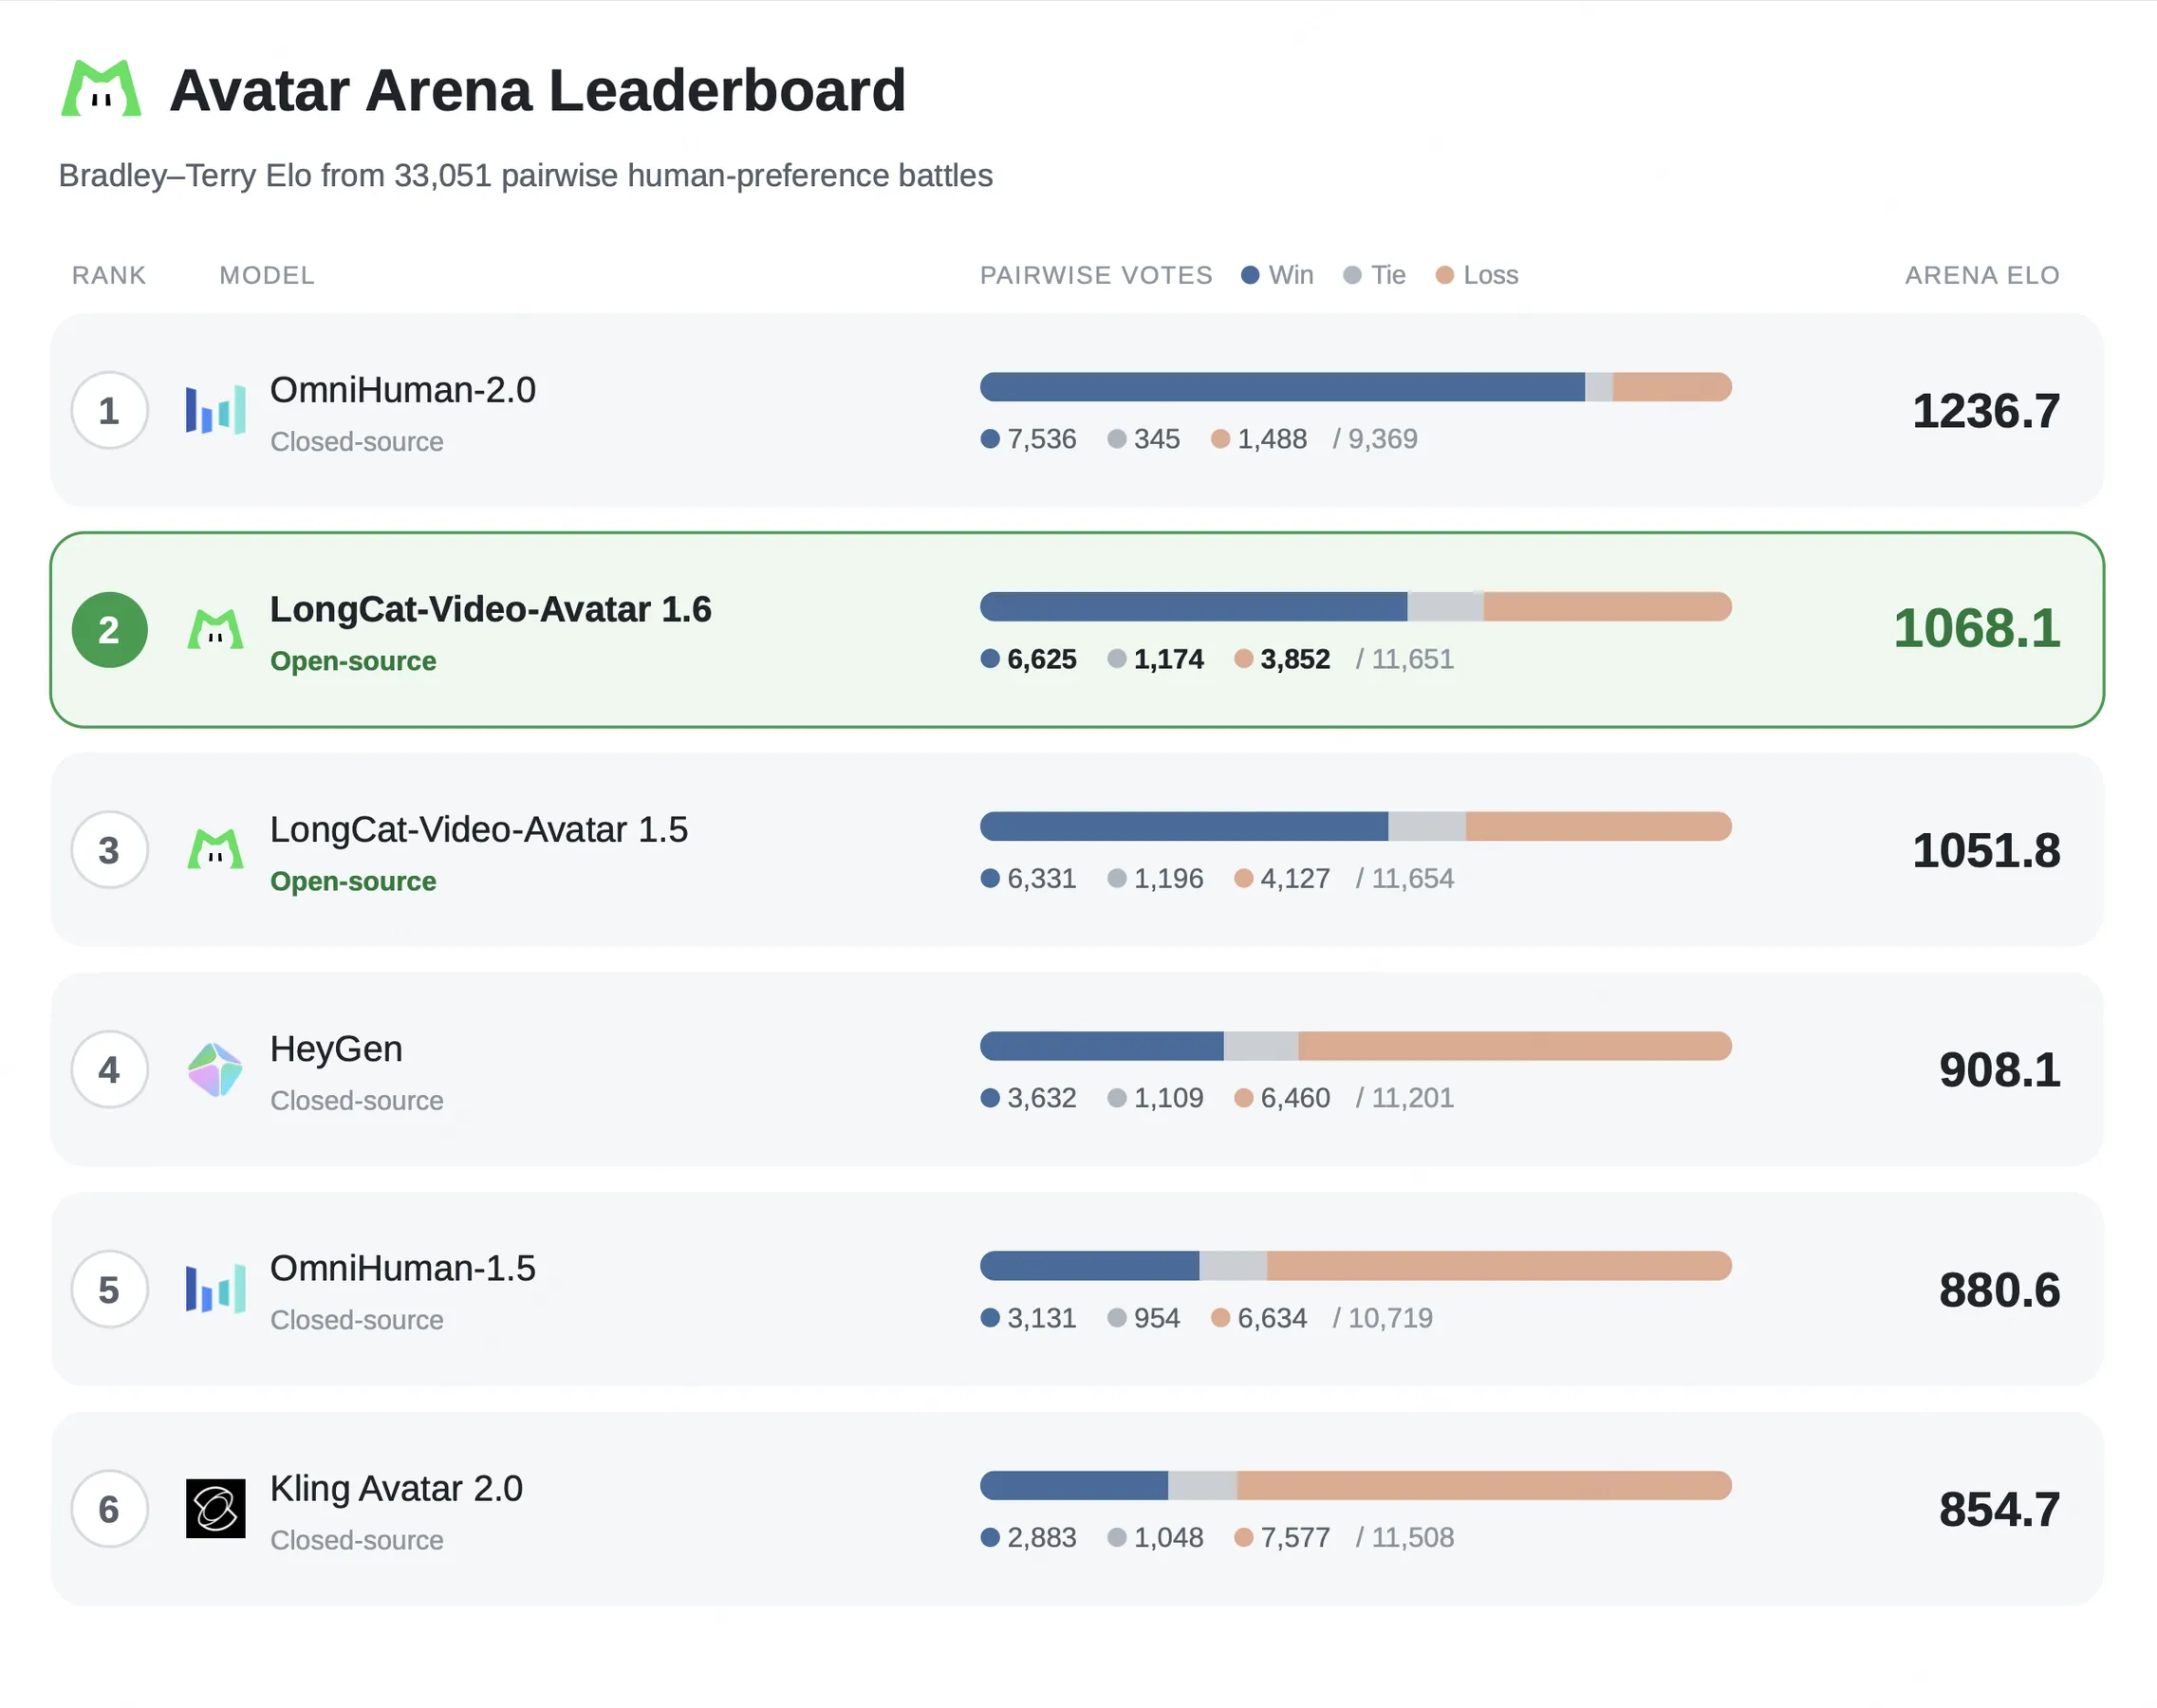
Meituan's LongCat team has published LongCat-Video-Avatar-1.6, an audio-driven avatar video generation model now available on Hugging Face. The model takes a still image and produces animated video, placing it in the fast-moving category of talking-head and digital-avatar generation.
The release is listed with an image-to-video primary modality, meaning it can take a source portrait and synthesize motion — the kind of lip-sync and expression animation that pairs a static image with an audio track. That makes it a candidate for use cases like virtual presenters, dubbing, and conversational interfaces.
Why it matters
Avatar video is one of the most commercially visible corners of generative media, and much of the leading work has stayed behind proprietary APIs. A major Chinese consumer-tech company putting a LongCat avatar model into open distribution gives developers something concrete to test and build on, rather than a closed service.
A few practical notes for anyone evaluating it:
- The weights ship under a custom "other" license, so terms should be reviewed before commercial use.
- Parameter count, context details, and benchmark figures were not disclosed in the release record.
- The 1.6 version label suggests ongoing iteration within the broader LongCat-Video effort.
As always with avatar generation, the capability raises familiar questions about consent and synthetic likeness. For now, the model is available to pull and experiment with directly from the LongCat repository on Hugging Face.
Sources
- Visit
meituan-longcat/LongCat-Video-Avatar-1.6
Hugging Face
More from Meituan
All Meituan releases →
Meituan Releases LongCat 2.5, an MIT-Licensed MoE
The Chinese delivery giant expands its open-model push with a multimodal, agentic mixture-of-experts system.

Meituan Ships a Lighter, Sparser LongCat-Flash
The food-delivery giant's newest open model trims its mixture-of-experts design for more efficient inference under an MIT license.

Meituan releases LongCat-2.0 language model
The Chinese delivery giant continues its push into open AI with a new text model on Hugging Face.
More in Image → Video
All Image → Video →NVIDIA Releases Cosmos 3 for World Simulation
The new open models push NVIDIA's world-foundation effort toward interactive, real-time video generation.
NVIDIA's Cosmos 3 Brings Open Interactive World Models
The new open release pushes beyond passive video generation toward simulated worlds that respond to input.
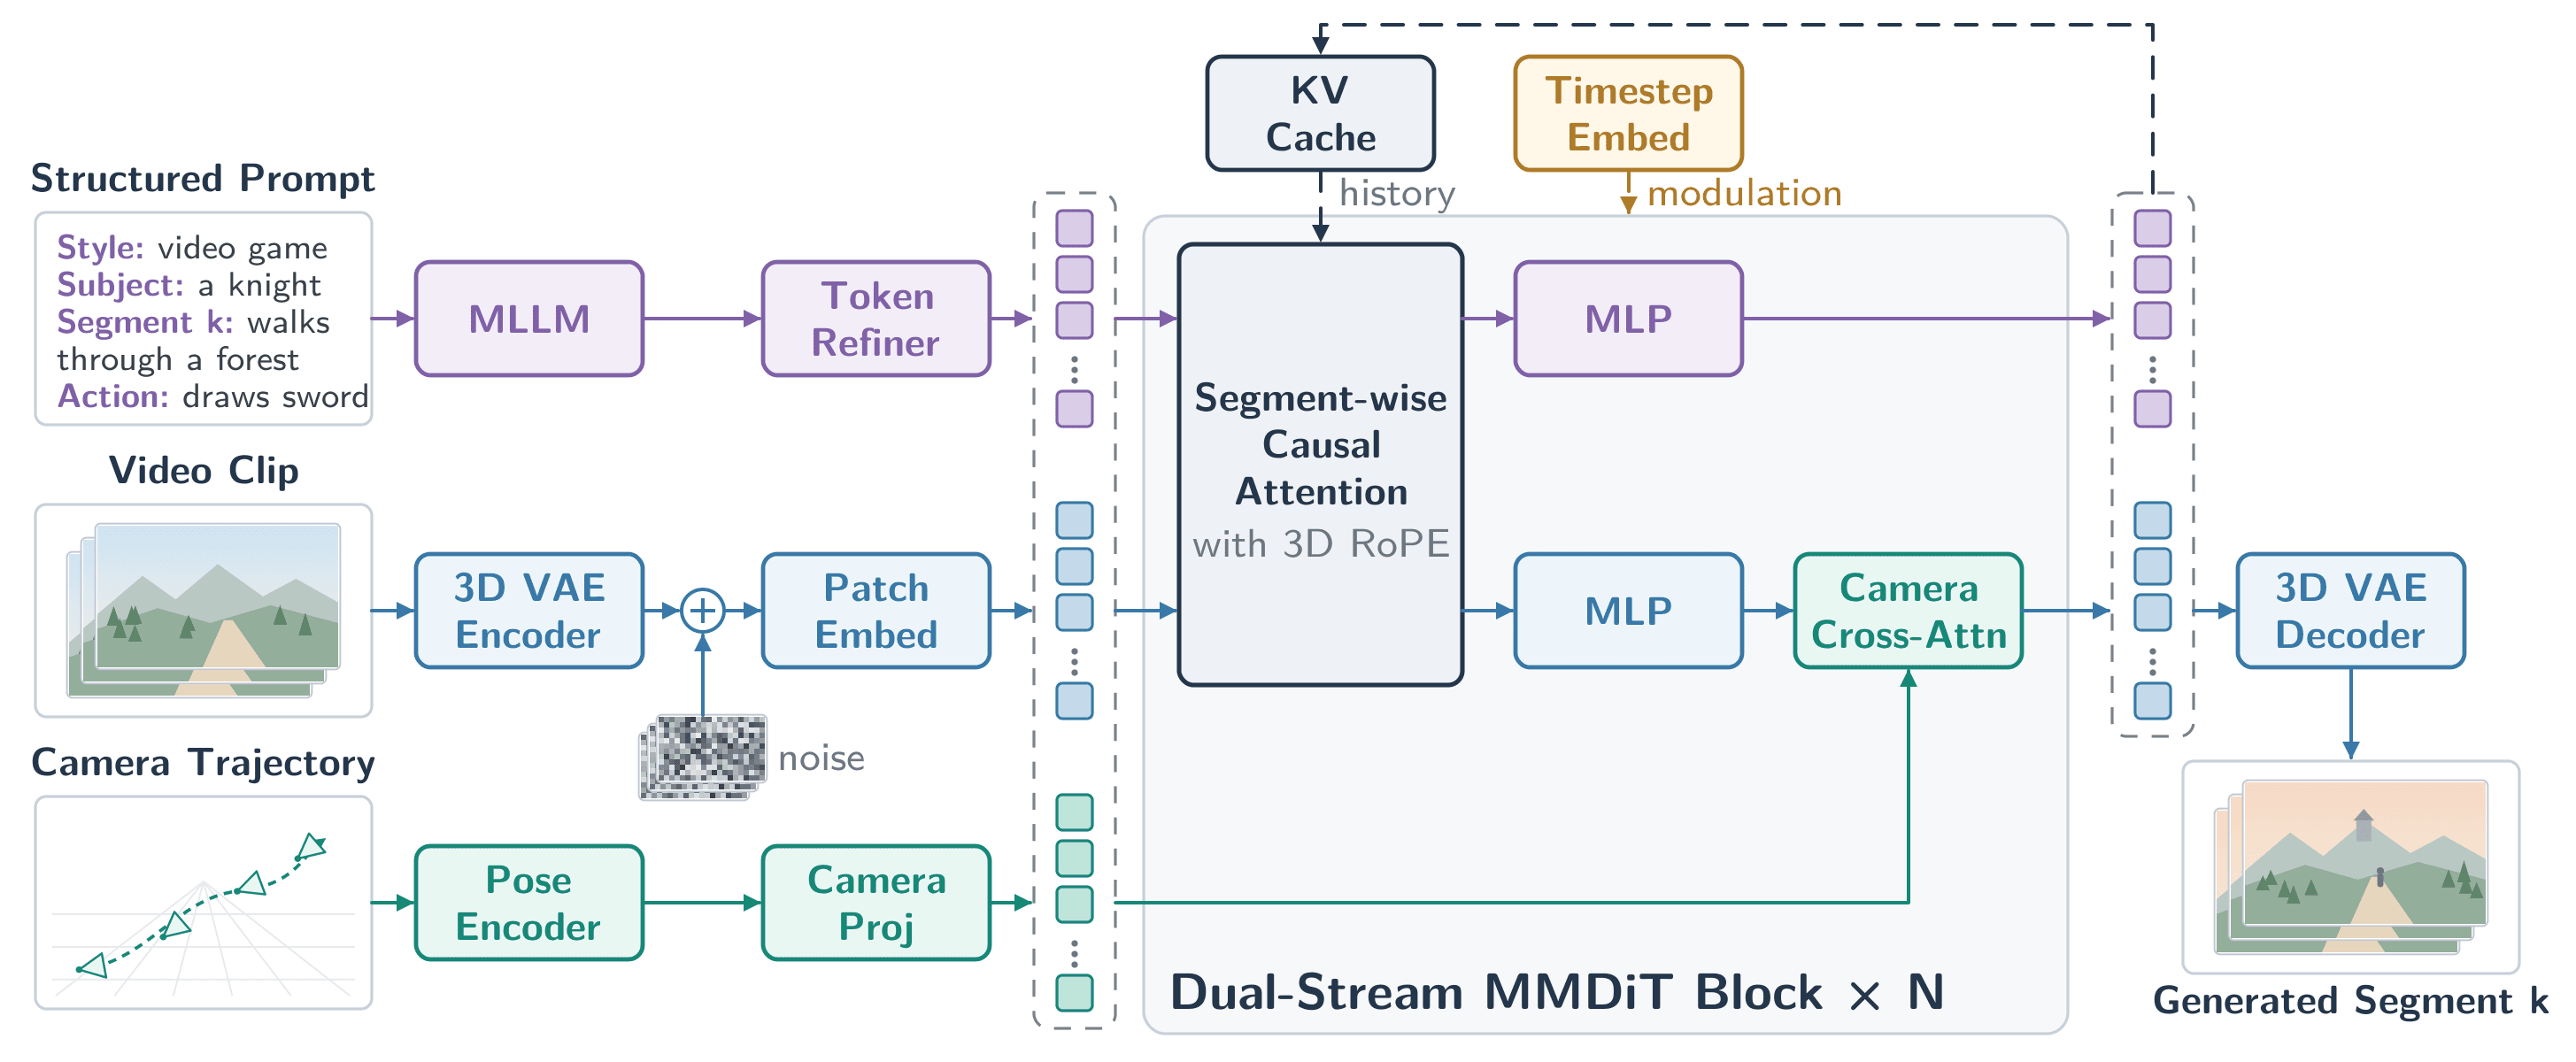
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
0 comments
No comments yet. Be the first to weigh in.