Haru-4B Brings Full-Duplex Speech to Six Languages
A compact 4-billion-parameter model handles real-time, two-way voice conversation across six languages in a single system.

Higurashi AI has released Haru-4B, a compact speech-to-speech model built for full-duplex conversation. At roughly 4 billion parameters, it is designed to listen and speak at the same time rather than trading rigid turns, and it supports six languages out of the box.
Full-duplex is the detail worth dwelling on. Most voice assistants still operate in a strict turn-based loop: you talk, the system transcribes, generates, and then speaks back. A full-duplex approach lets the model handle overlapping speech, interruptions, and backchannel cues like "mm-hm" the way people actually converse — a meaningfully different interaction model from the familiar push-to-talk pattern.
Why it matters
Speech pipelines have traditionally stitched together separate components for recognition, language modeling, and synthesis. Haru-4B folds those capabilities into one system, spanning:
- Speech-to-speech conversation as the primary mode
- Speech recognition (ASR) and synthesis (TTS)
- Coverage across six languages
At 4B parameters, the model sits in a size range that is realistic to run outside a data center, which lowers the barrier for developers building interactive voice interfaces. It is worth noting the model ships under a non-standard license, so teams should check the terms on the model page before building on it.
Details such as context length, supported sample rates, and the specific language list were not fully specified at release. For now, Haru-4B reads as an early but ambitious entry in the push toward natural, low-latency voice AI that runs at modest scale.
Sources
- Visit
higurashi-ai/Haru-4B
Hugging Face
More in Any-to-Any
All Any-to-Any →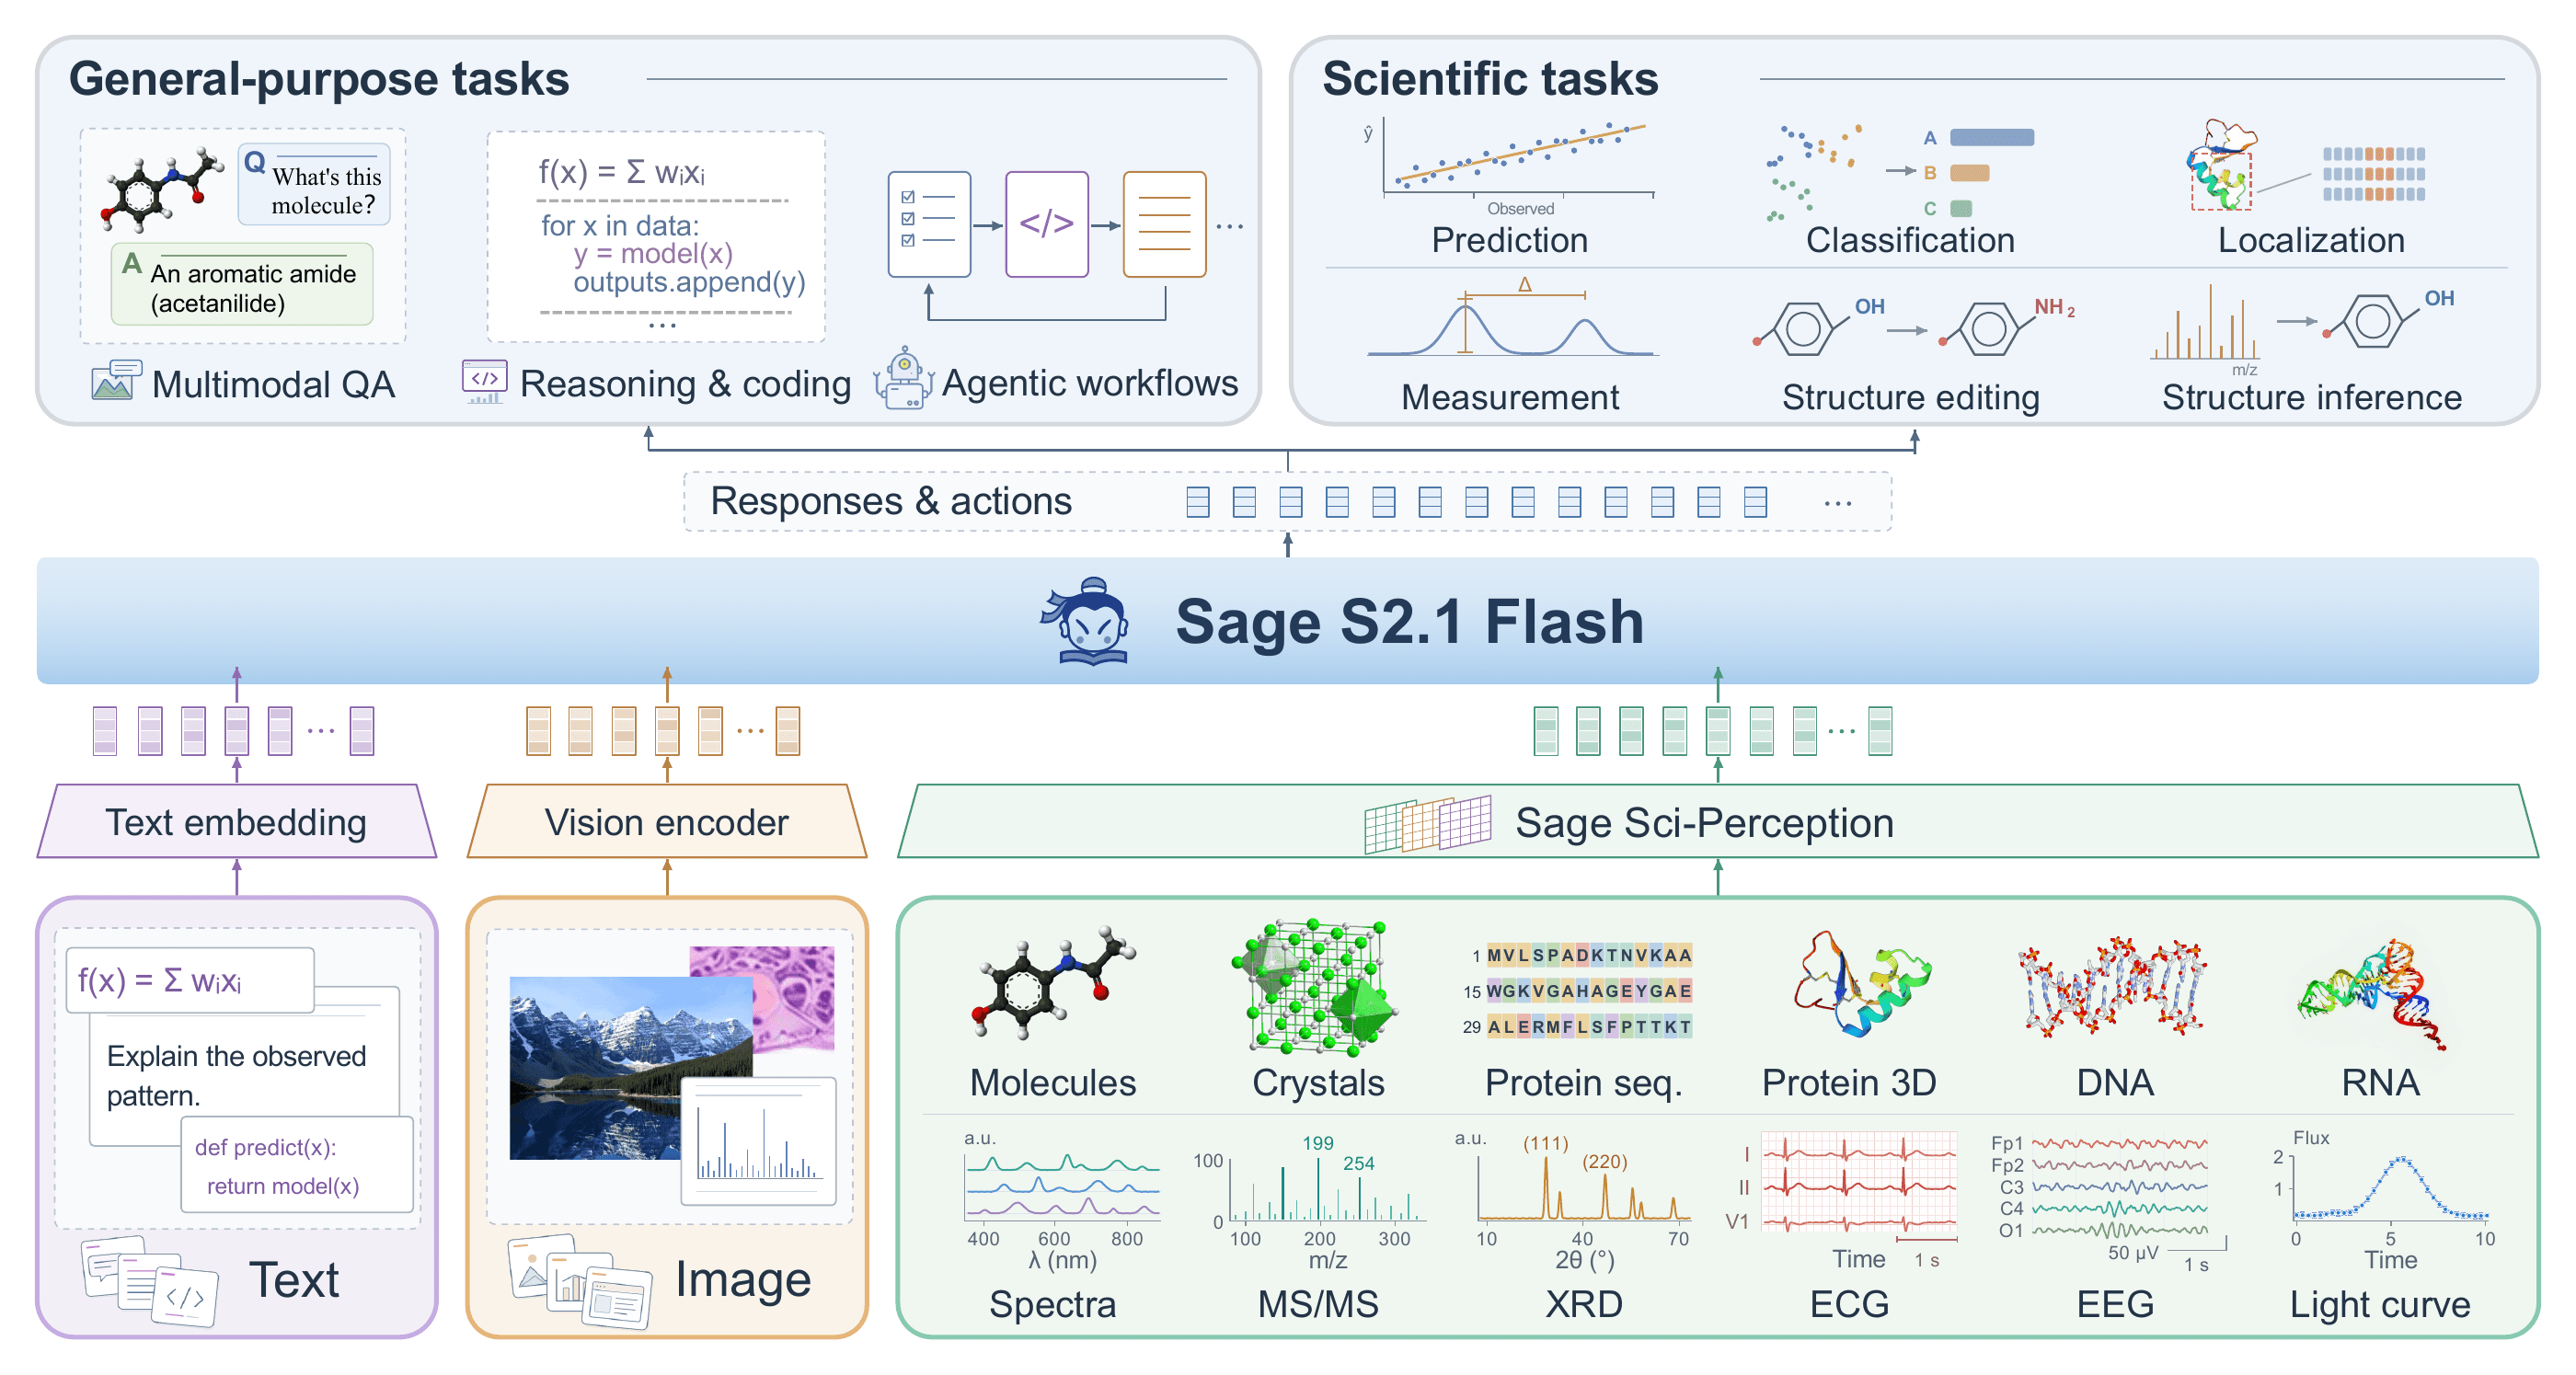
InternLM's Sage S2.1 Flash targets scientific reasoning
The 320B mixture-of-experts model is built to reason over scientific evidence and act inside interactive environments.
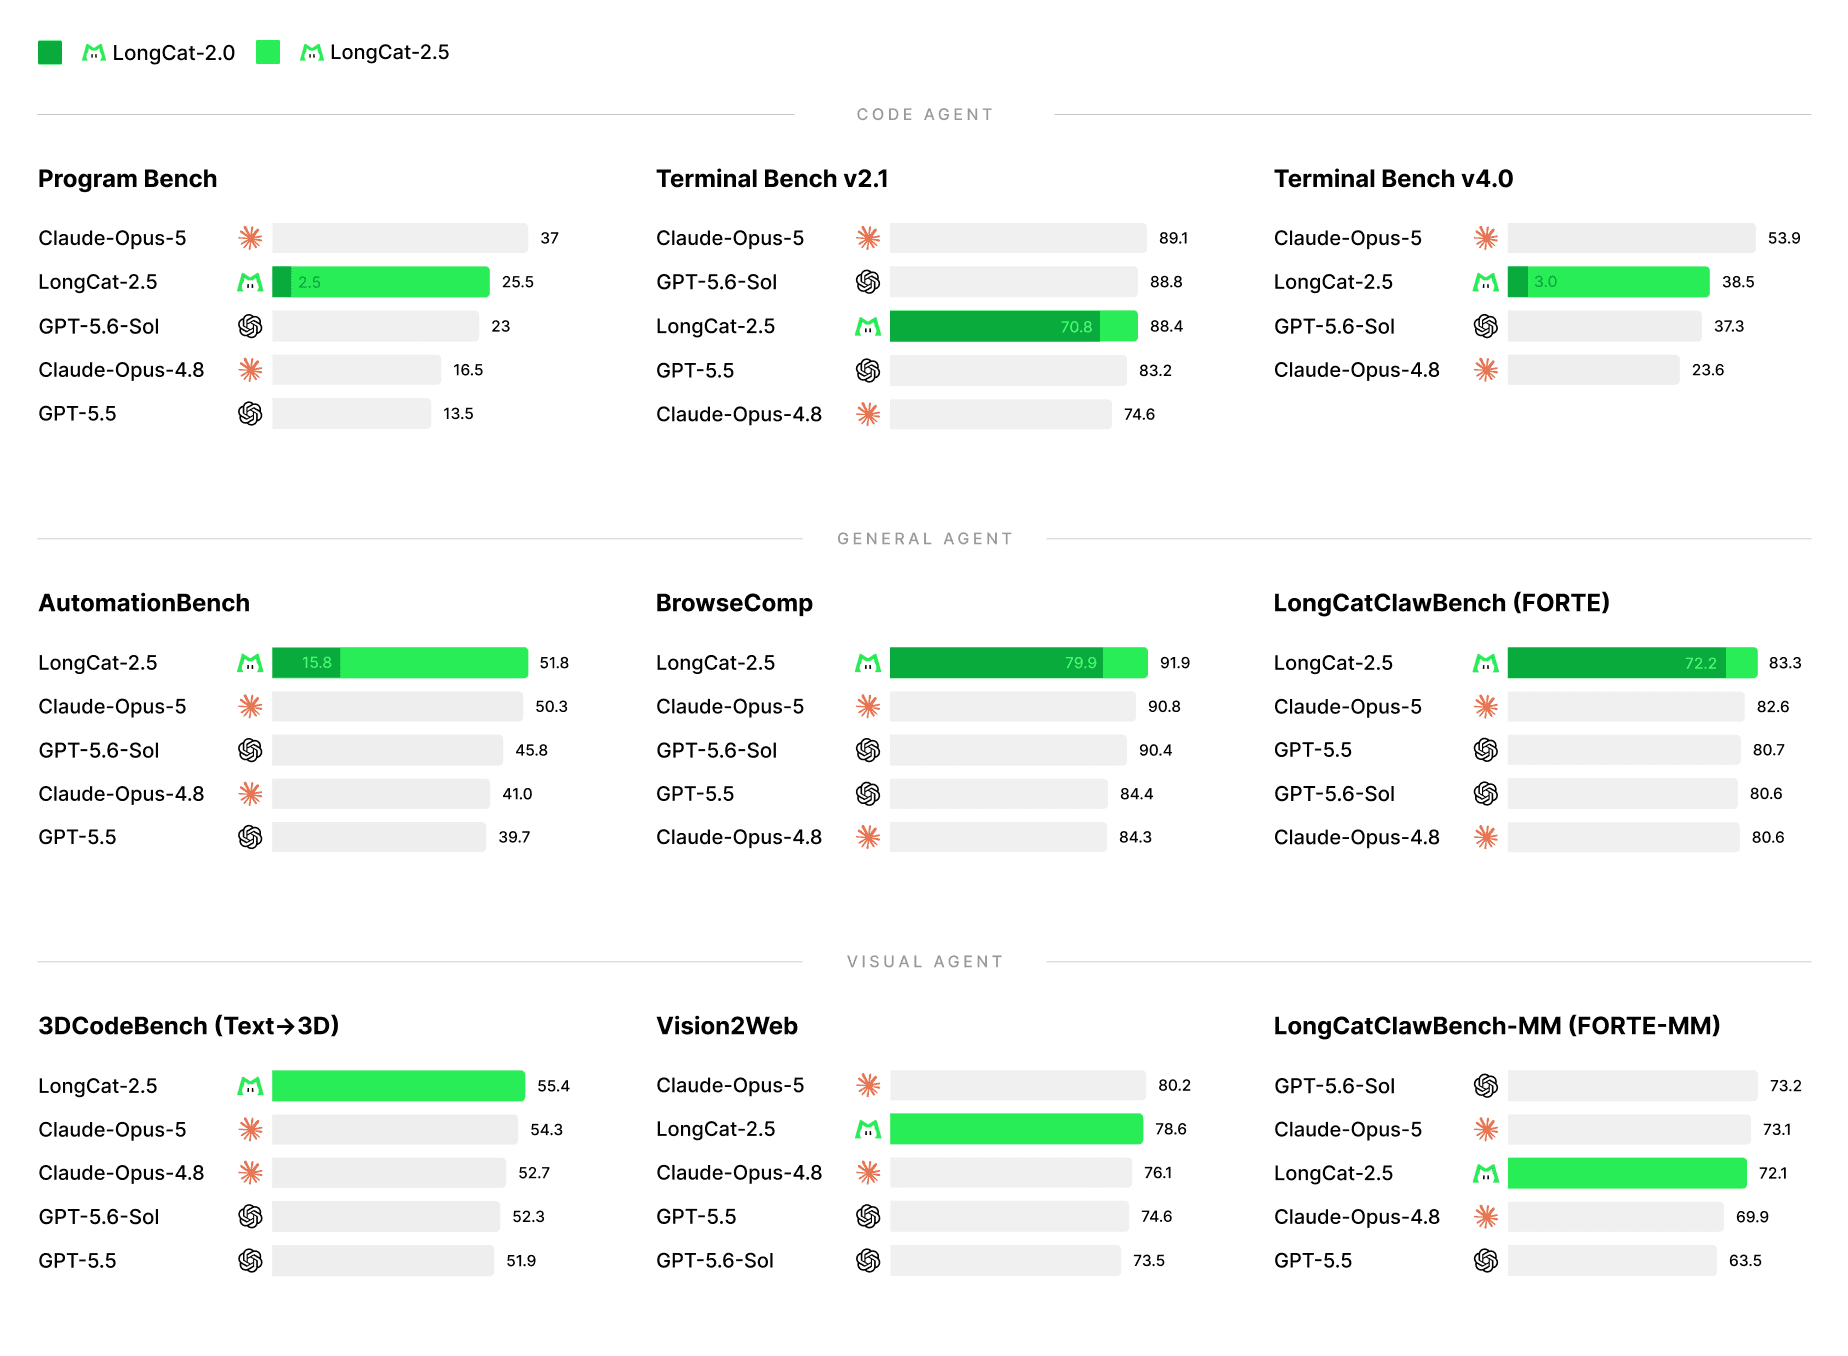
Meituan Releases LongCat 2.5, an MIT-Licensed MoE
The Chinese delivery giant expands its open-model push with a multimodal, agentic mixture-of-experts system.
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
0 comments
No comments yet. Be the first to weigh in.