InternLM's Sage S2.1 Flash targets scientific reasoning
The 320B mixture-of-experts model is built to reason over scientific evidence and act inside interactive environments.
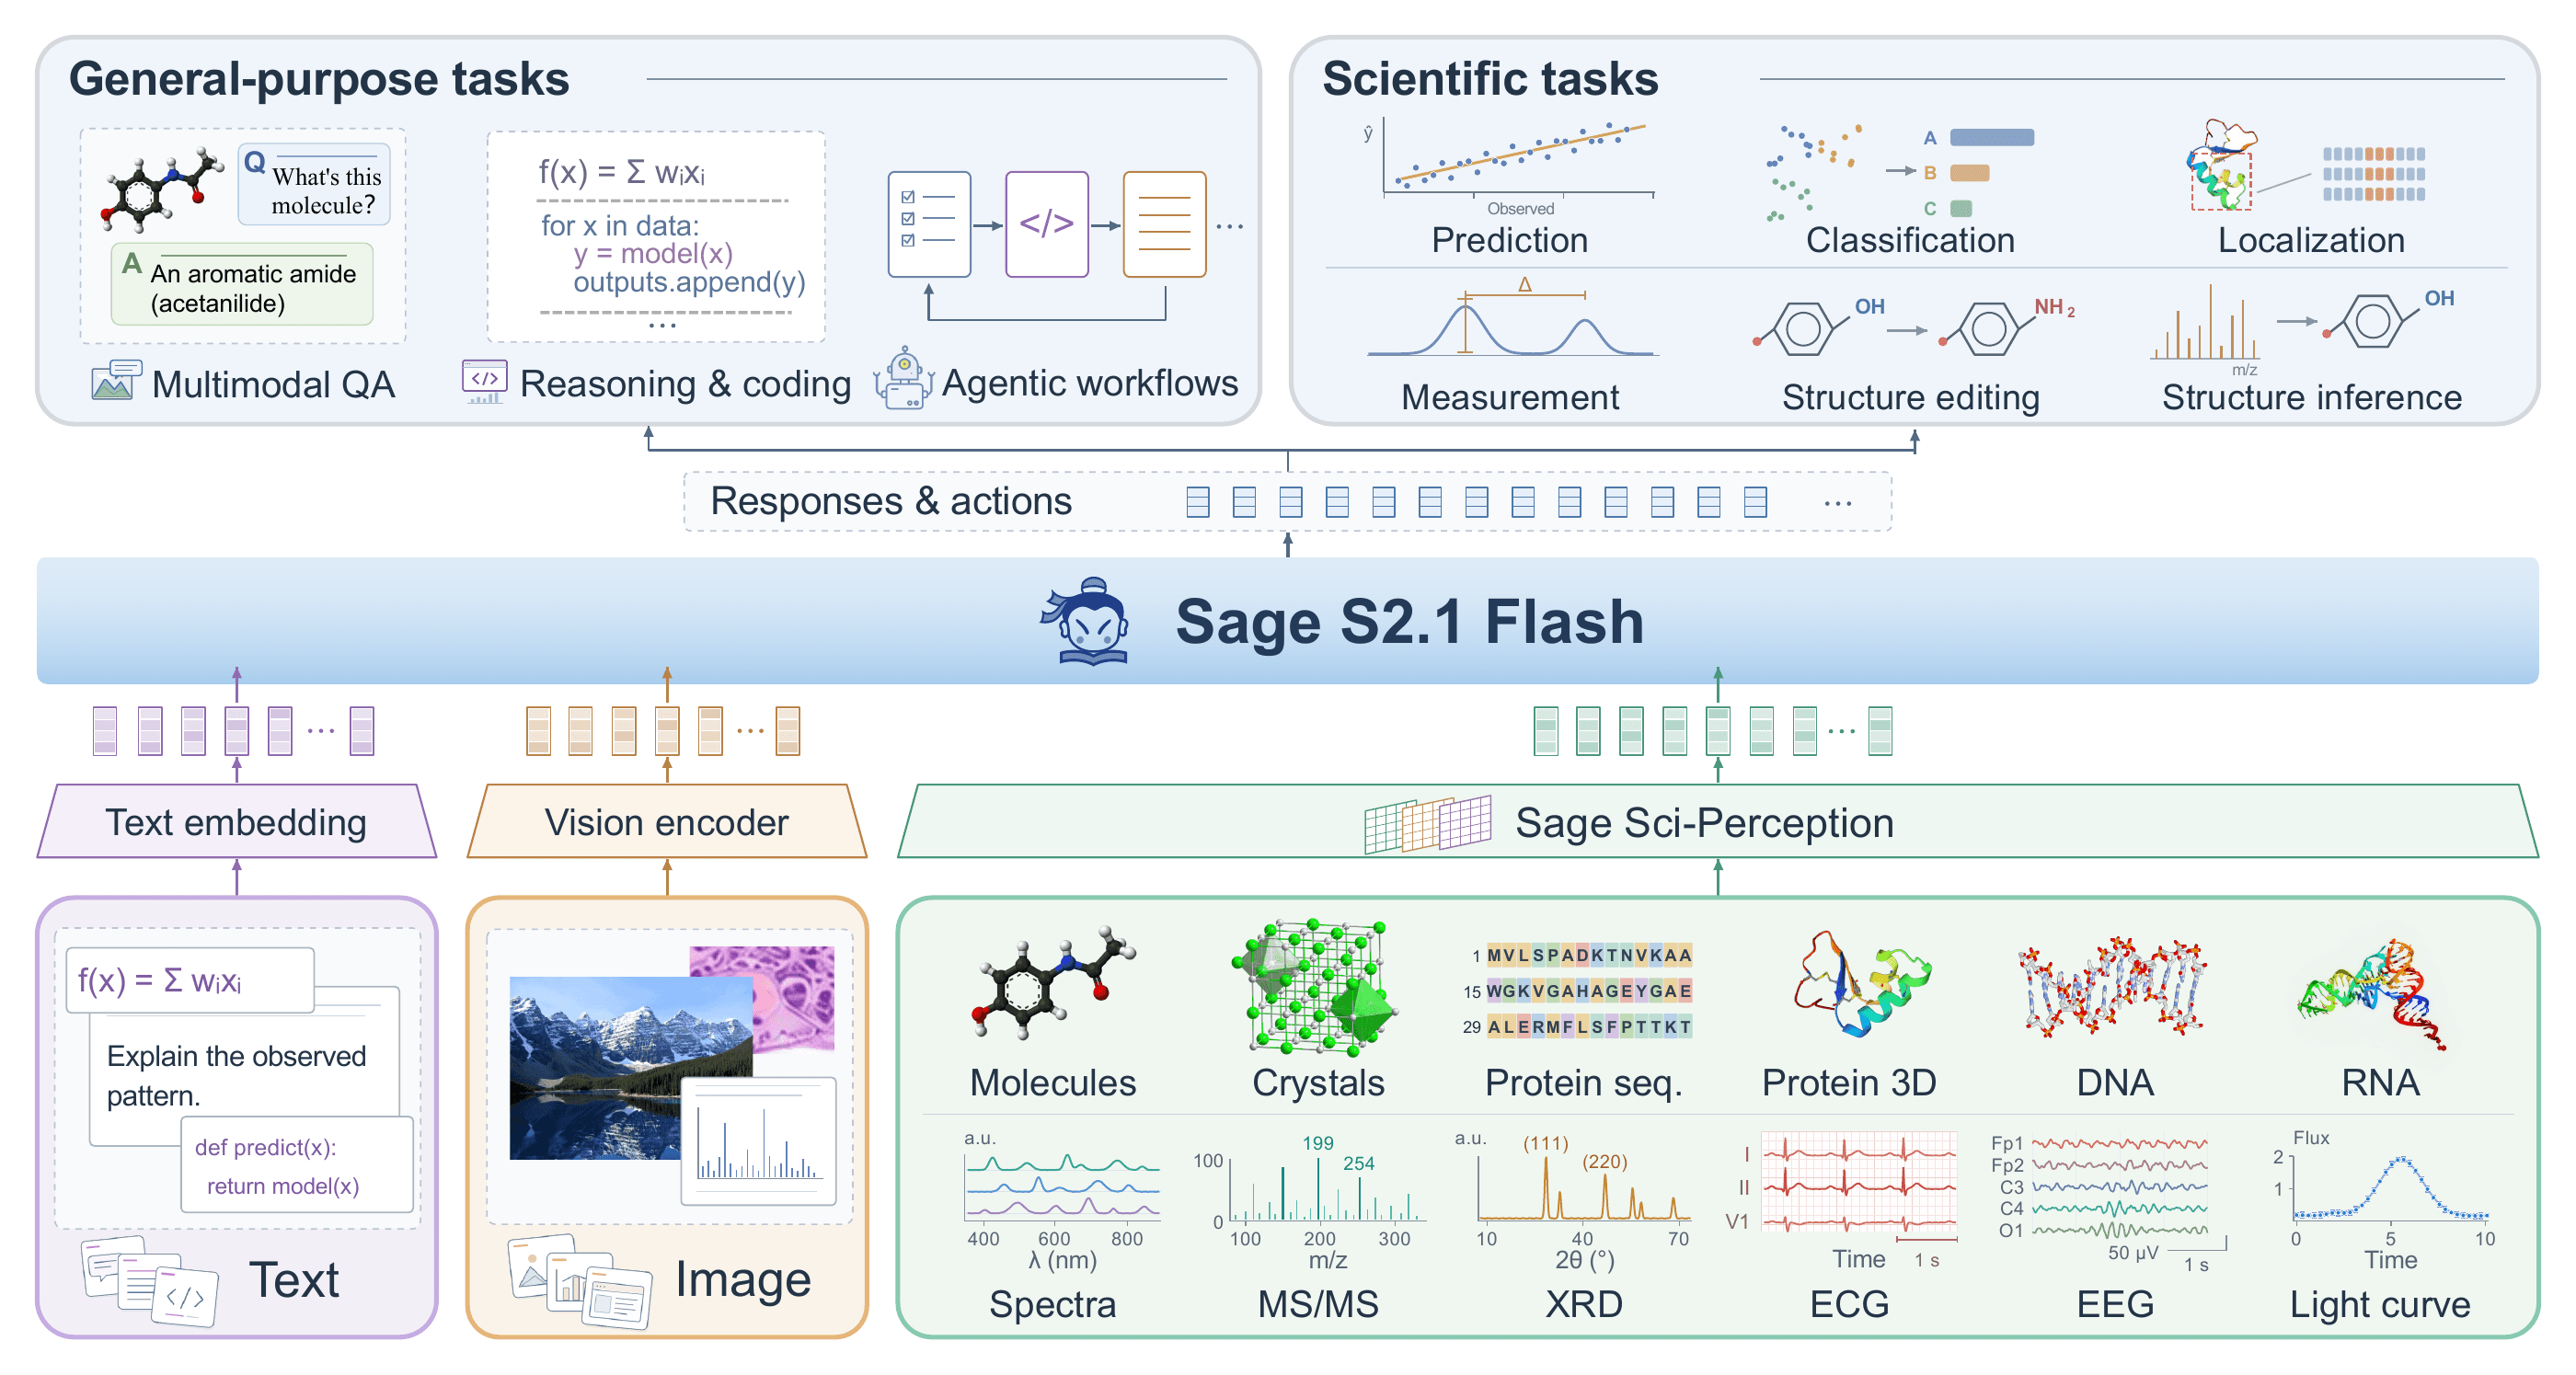
InternLM has released Sage S2.1 Flash, a large mixture-of-experts model designed less for general chat and more for a specific job: reasoning through scientific evidence and taking actions inside interactive environments. The model is available on Hugging Face.
At roughly 320 billion total parameters, Sage S2.1 Flash leans on a mixture-of-experts (MoE) design, which activates only a fraction of its weights per token to keep inference costs manageable relative to its raw size. InternLM positions it as a reasoning-first system with multimodal inputs, rather than a single-purpose text model.
Why it matters
Most frontier open-weights releases chase broad assistant benchmarks. Sage's framing is narrower and more interesting:
- Evidence-grounded reasoning over scientific material, rather than open-ended generation
- Agentic behavior, meaning the model is meant to act within interactive environments and tools
- An MoE architecture that trades sparse activation for scale
That combination points toward research and lab-style workflows, where tracing a conclusion back to evidence matters as much as the answer itself.
The model ships under a non-standard license, so teams evaluating it for production should read the terms on the model card carefully. InternLM links its accompanying paper via Hugging Face for those who want the methodology behind the release.
Sources
- Visit
internlm/Sage-S2.1-Flash
Hugging Face
More from Internlm
All Internlm releases →
InternLM's Atria Dawn Preview Targets Agentic Tasks
A new mixture-of-experts model trained on verified tool interactions arrives as an early preview under an MIT license.
InternLM Previews 397B Vision-Language Model
The Intern-S2 preview arrives as a very large multimodal system under a permissive Apache-2.0 license.
More in Reasoning
All Reasoning →ServiceNow Debuts Apriel Voice 27B, an Open Speech Model
The 27-billion-parameter preview unifies text-to-speech, transcription, and reasoning in a single open model.
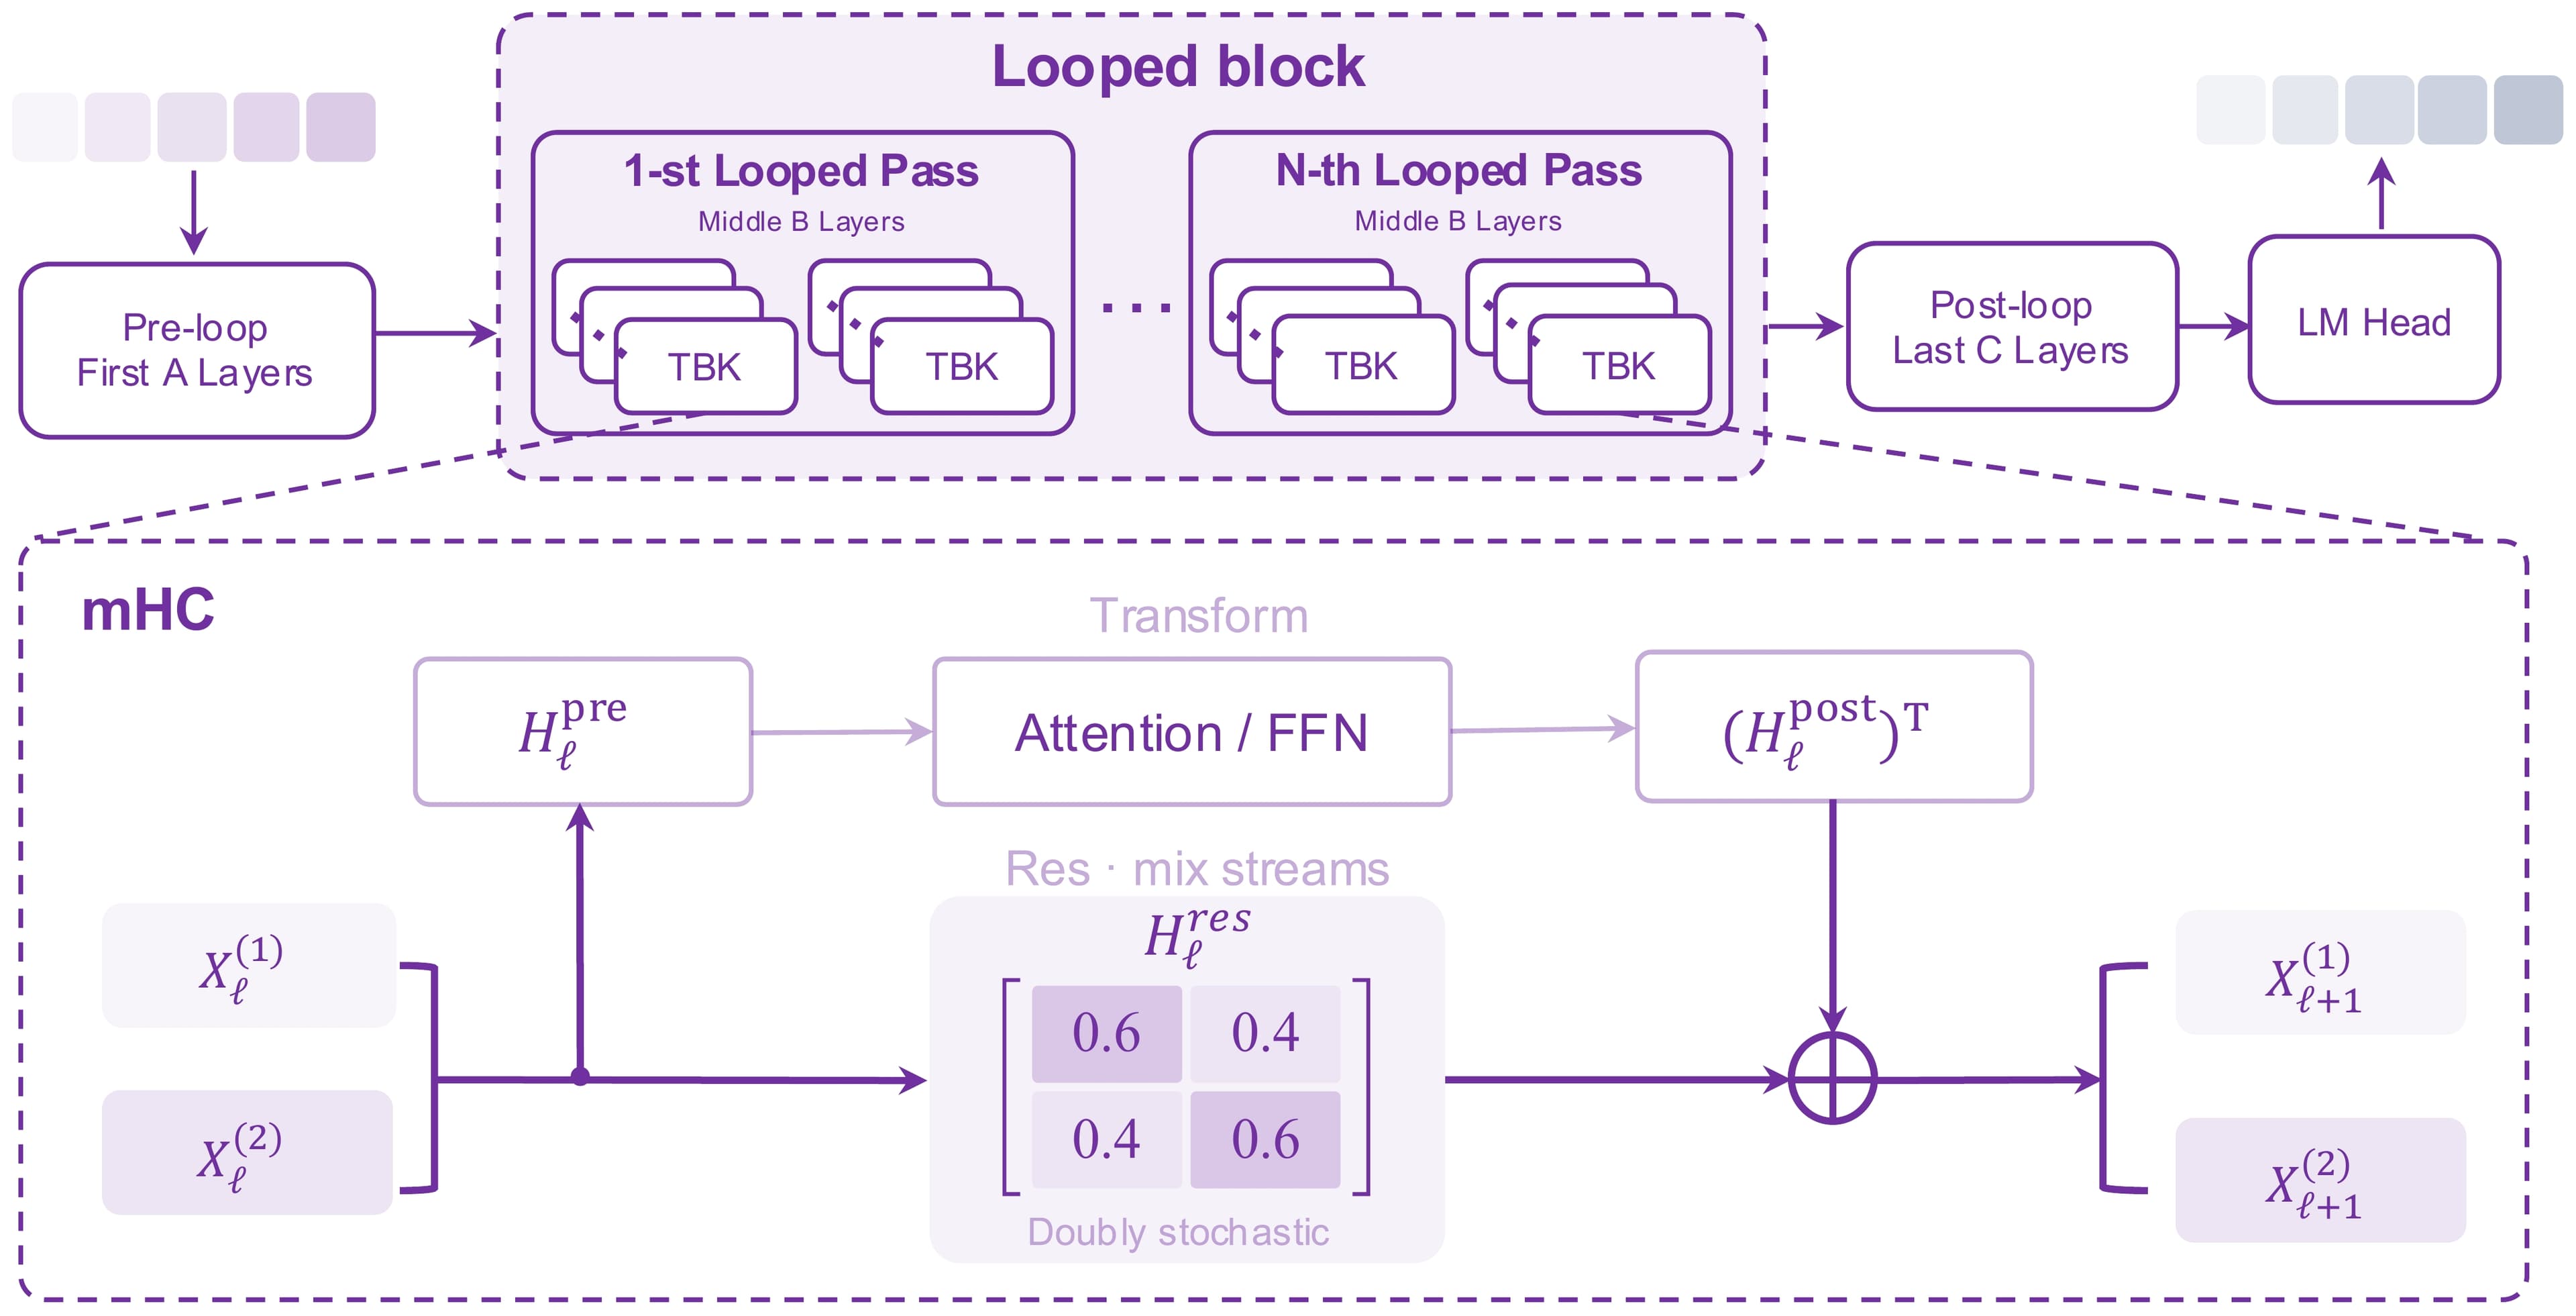
SenseTime previews a 9B looped-transformer VLM
SenseNova-Loop-9B-Preview puts a recurrent-depth architecture to work on multimodal reasoning.

DeepSeek Releases V4.1-Flash, an Open Multimodal MoE
The new mixture-of-experts model handles text, vision, and reasoning, and ships under a permissive MIT license.
0 comments
No comments yet. Be the first to weigh in.