NVIDIA's Kumo Takes Aim at Tabular Prediction
A new foundation model targets structured data, where spreadsheets and databases still dominate real-world machine learning.
NVIDIA has released Kumo Tabular, a foundation model aimed at one of machine learning's least glamorous but most pervasive problems: prediction over structured, tabular data. The model is available on Hugging Face, with an accompanying write-up describing it as setting a new accuracy-efficiency frontier for the task.
Most enterprise data still lives in rows and columns — transaction logs, customer records, sensor readings — rather than in the text and images that dominate the headlines. Historically, gradient-boosted trees have been the reliable workhorse here, often outperforming neural approaches. A foundation model that generalizes across tables would, if it holds up, shift how teams approach forecasting, classification, and ranking on structured data.
Why it matters
- Tabular problems are everywhere in industry, and a strong general-purpose model could reduce per-task engineering.
- NVIDIA frames Kumo around the trade-off that matters most in production: accuracy against compute cost.
- Releasing on Hugging Face lowers the barrier for practitioners to benchmark it against their existing pipelines.
Some details remain thin at launch: the record lists the license as unspecified "other," and parameter count and context length are not disclosed. As with any model touting a new frontier, the real test will come from independent evaluation against established baselines on standard tabular benchmarks. For now, it is a notable entry in a category that rarely gets a dedicated foundation model.
Sources
More from NVIDIA
All NVIDIA releases →NVIDIA's Cosmos 3 Brings Open Interactive World Models
The new open release pushes beyond passive video generation toward simulated worlds that respond to input.
NVIDIA Releases Cosmos 3 for World Simulation
The new open models push NVIDIA's world-foundation effort toward interactive, real-time video generation.
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
More in Any-to-Any
All Any-to-Any →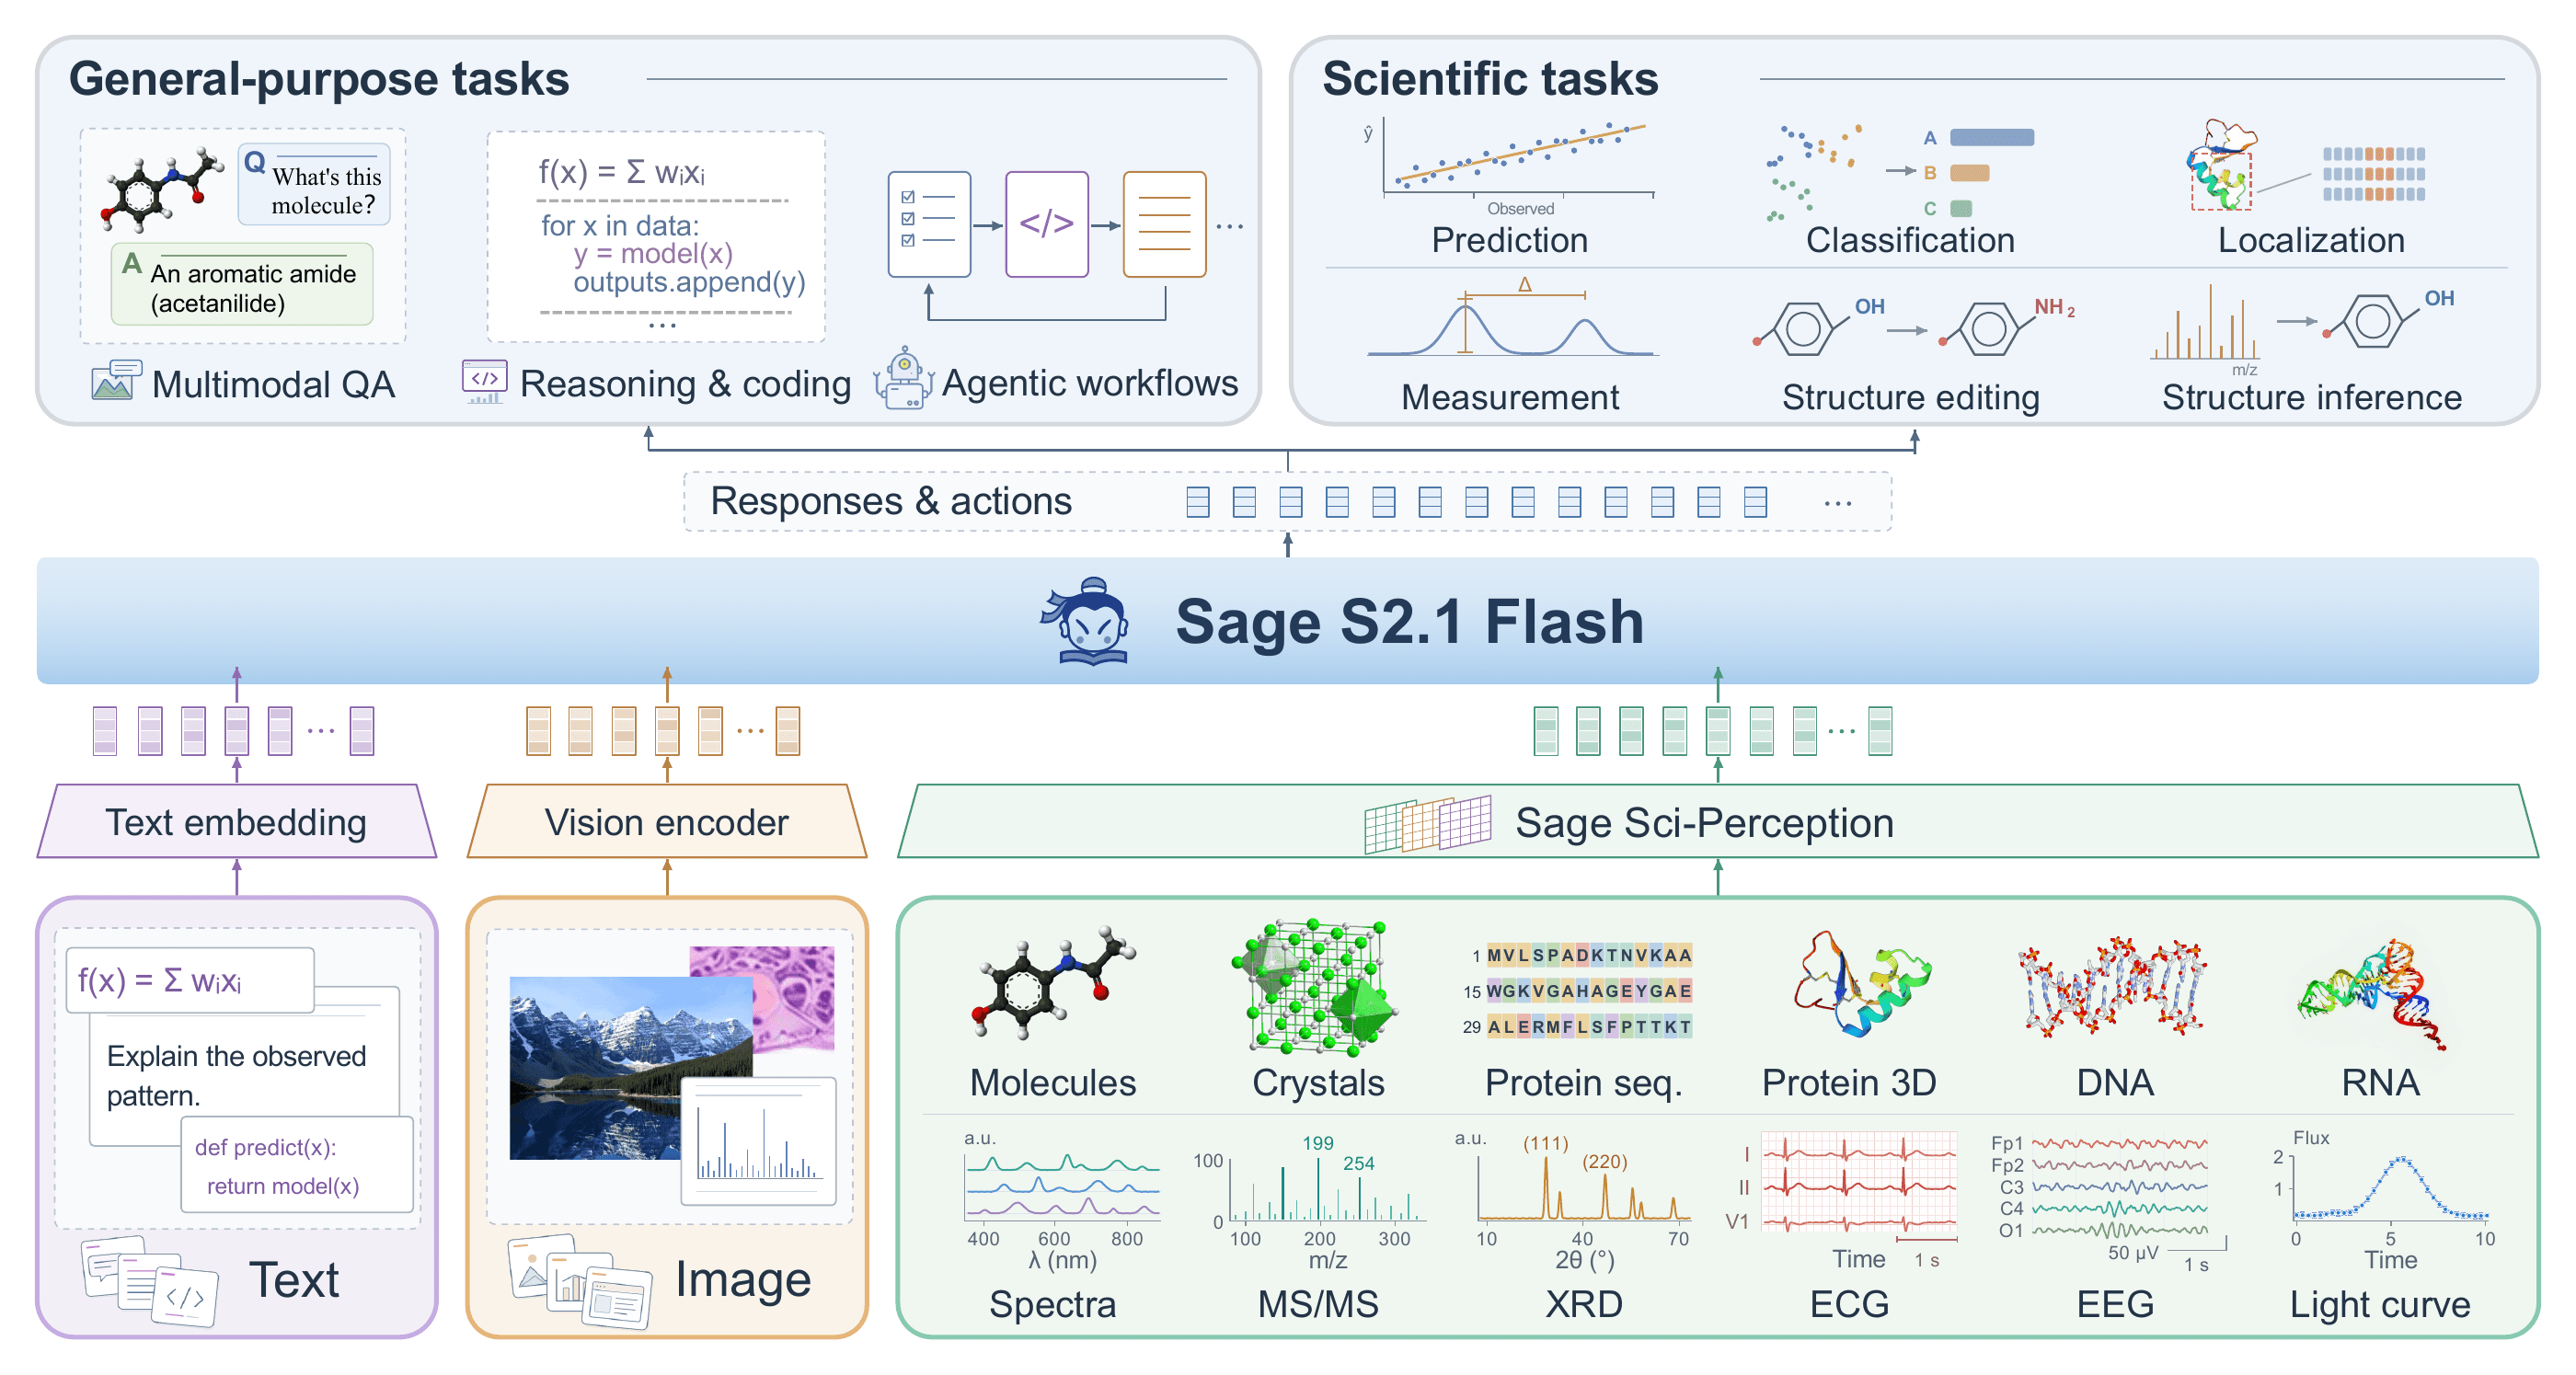
InternLM's Sage S2.1 Flash targets scientific reasoning
The 320B mixture-of-experts model is built to reason over scientific evidence and act inside interactive environments.

Haru-4B Brings Full-Duplex Speech to Six Languages
A compact 4-billion-parameter model handles real-time, two-way voice conversation across six languages in a single system.
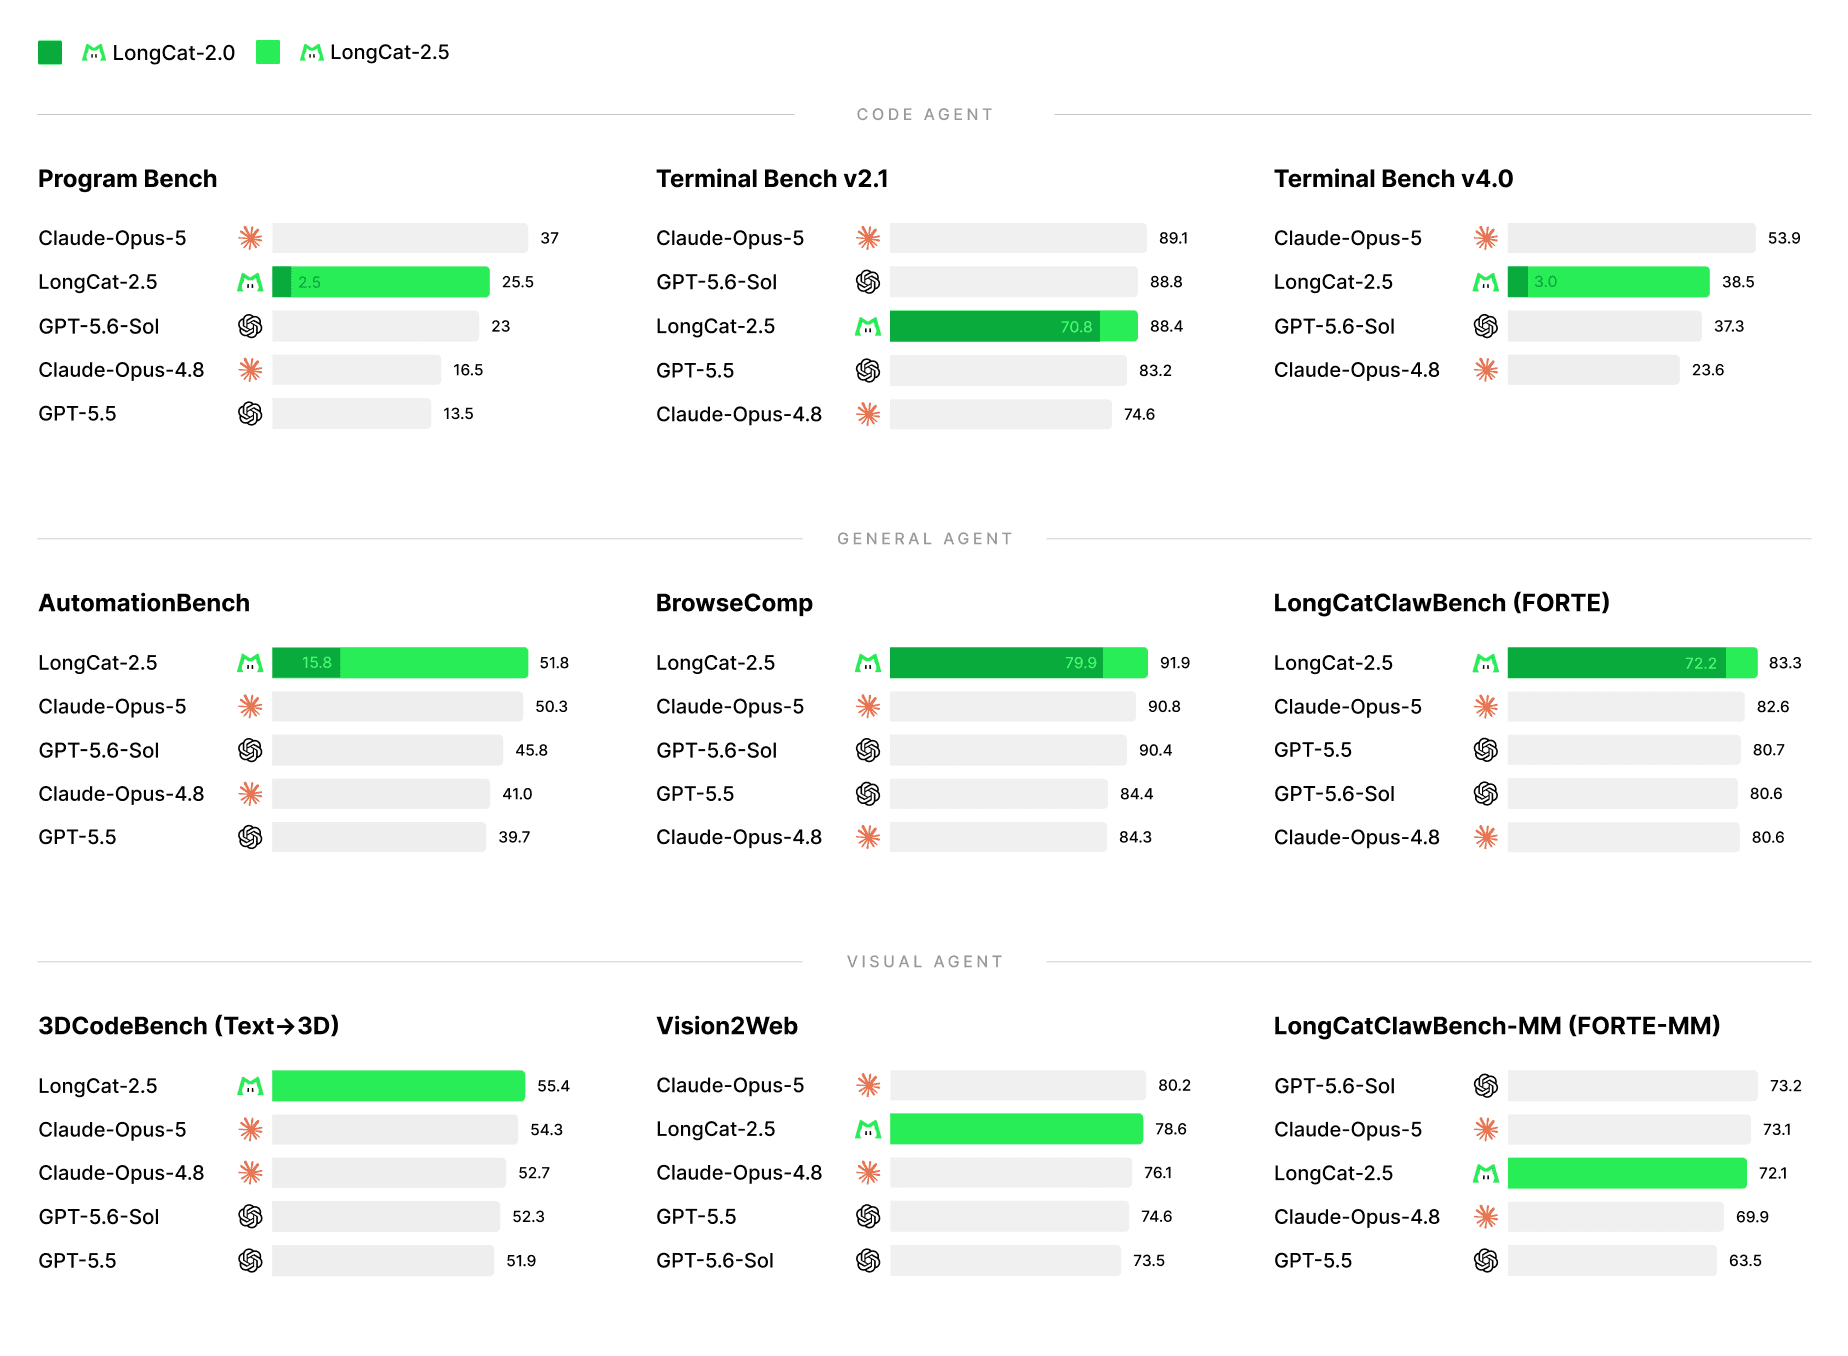
Meituan Releases LongCat 2.5, an MIT-Licensed MoE
The Chinese delivery giant expands its open-model push with a multimodal, agentic mixture-of-experts system.
0 comments
No comments yet. Be the first to weigh in.