ByteDance Releases Lance, a Unified Generative AI Model
The 3-billion-parameter model handles image and video generation, editing, and understanding from a single set of weights under a permissive license.
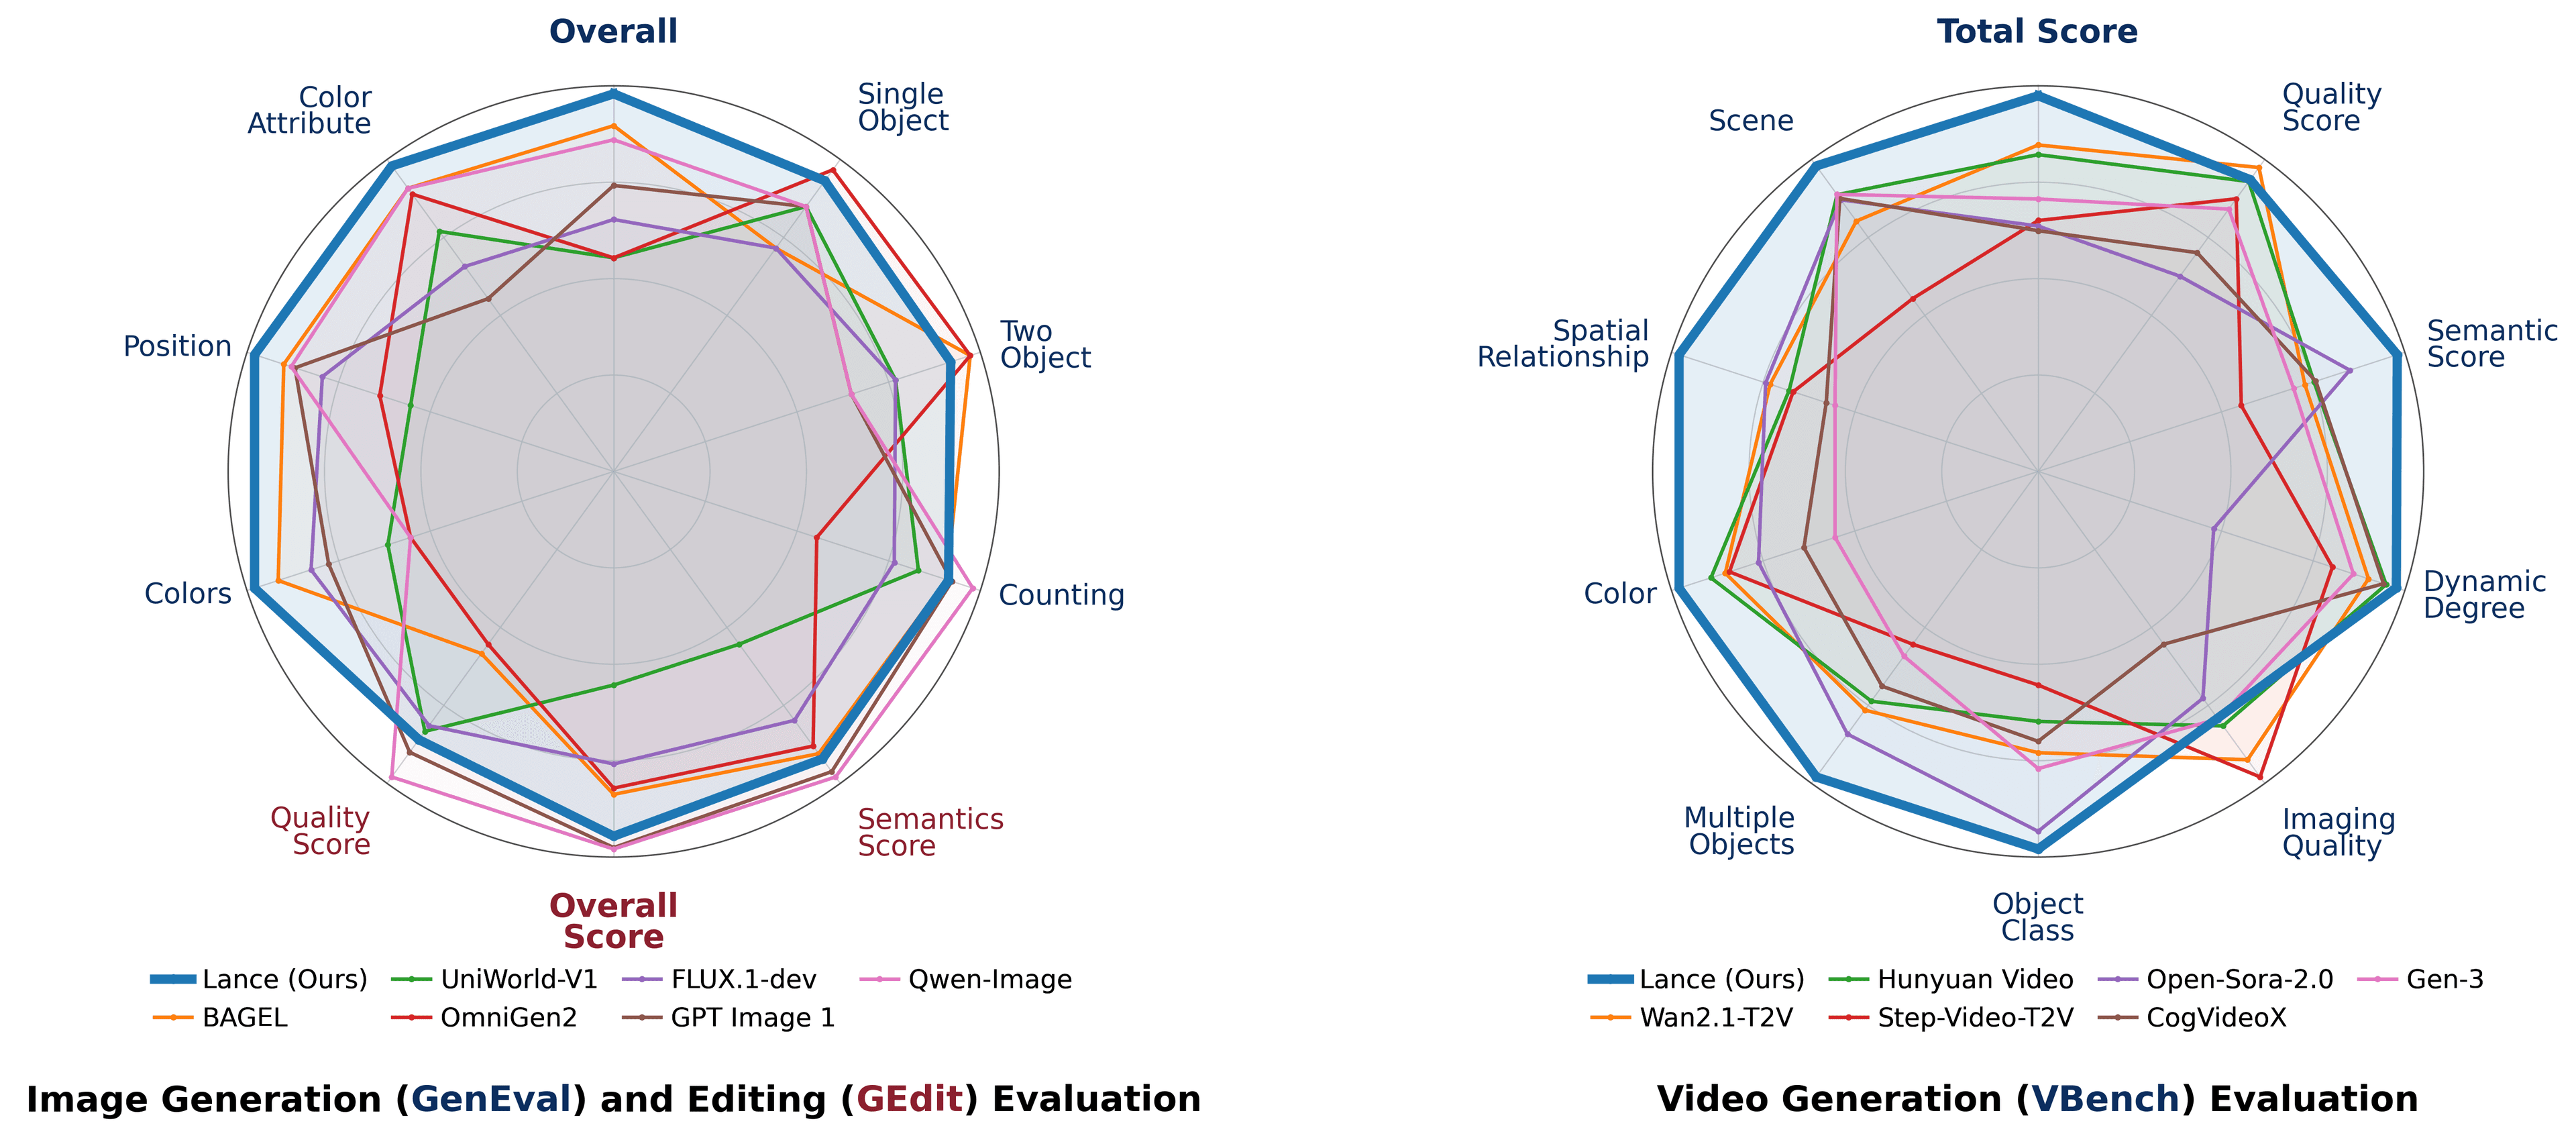
ByteDance has released Lance, a new 3-billion-parameter generative model that takes a unified approach to multimodal tasks. Released under a permissive Apache 2.0 license, Lance is designed to handle a wide range of creative and analytical tasks involving both images and video using a single, cohesive architecture.
The model's key innovation is its unified nature. Instead of relying on separate, specialized models for different tasks—one for generating images, another for editing video—Lance integrates these capabilities into one system. This design allows it to perform generation, editing, and understanding across different media formats without switching contexts or toolchains.
A Multi-Talented Architecture
Lance's single framework is trained to handle several distinct creative functions. According to the release documentation, its primary skills include:
- Text-to-Image and Text-to-Video Generation: Creating visual content from text prompts.
- Image Editing: Modifying existing images based on instructions.
- Multimodal Understanding: Analyzing and interpreting the content of images and video.
This release provides the open-source community with a powerful and flexible tool for building complex creative applications. By consolidating multiple functions into a relatively compact model, Lance offers an efficient alternative to more fragmented, multi-model pipelines. Researchers and developers can explore the model's weights and architecture, which are available on its Hugging Face repository.
Sources
- Visit
bytedance-research/Lance
Hugging Face
More from ByteDance
All ByteDance releases →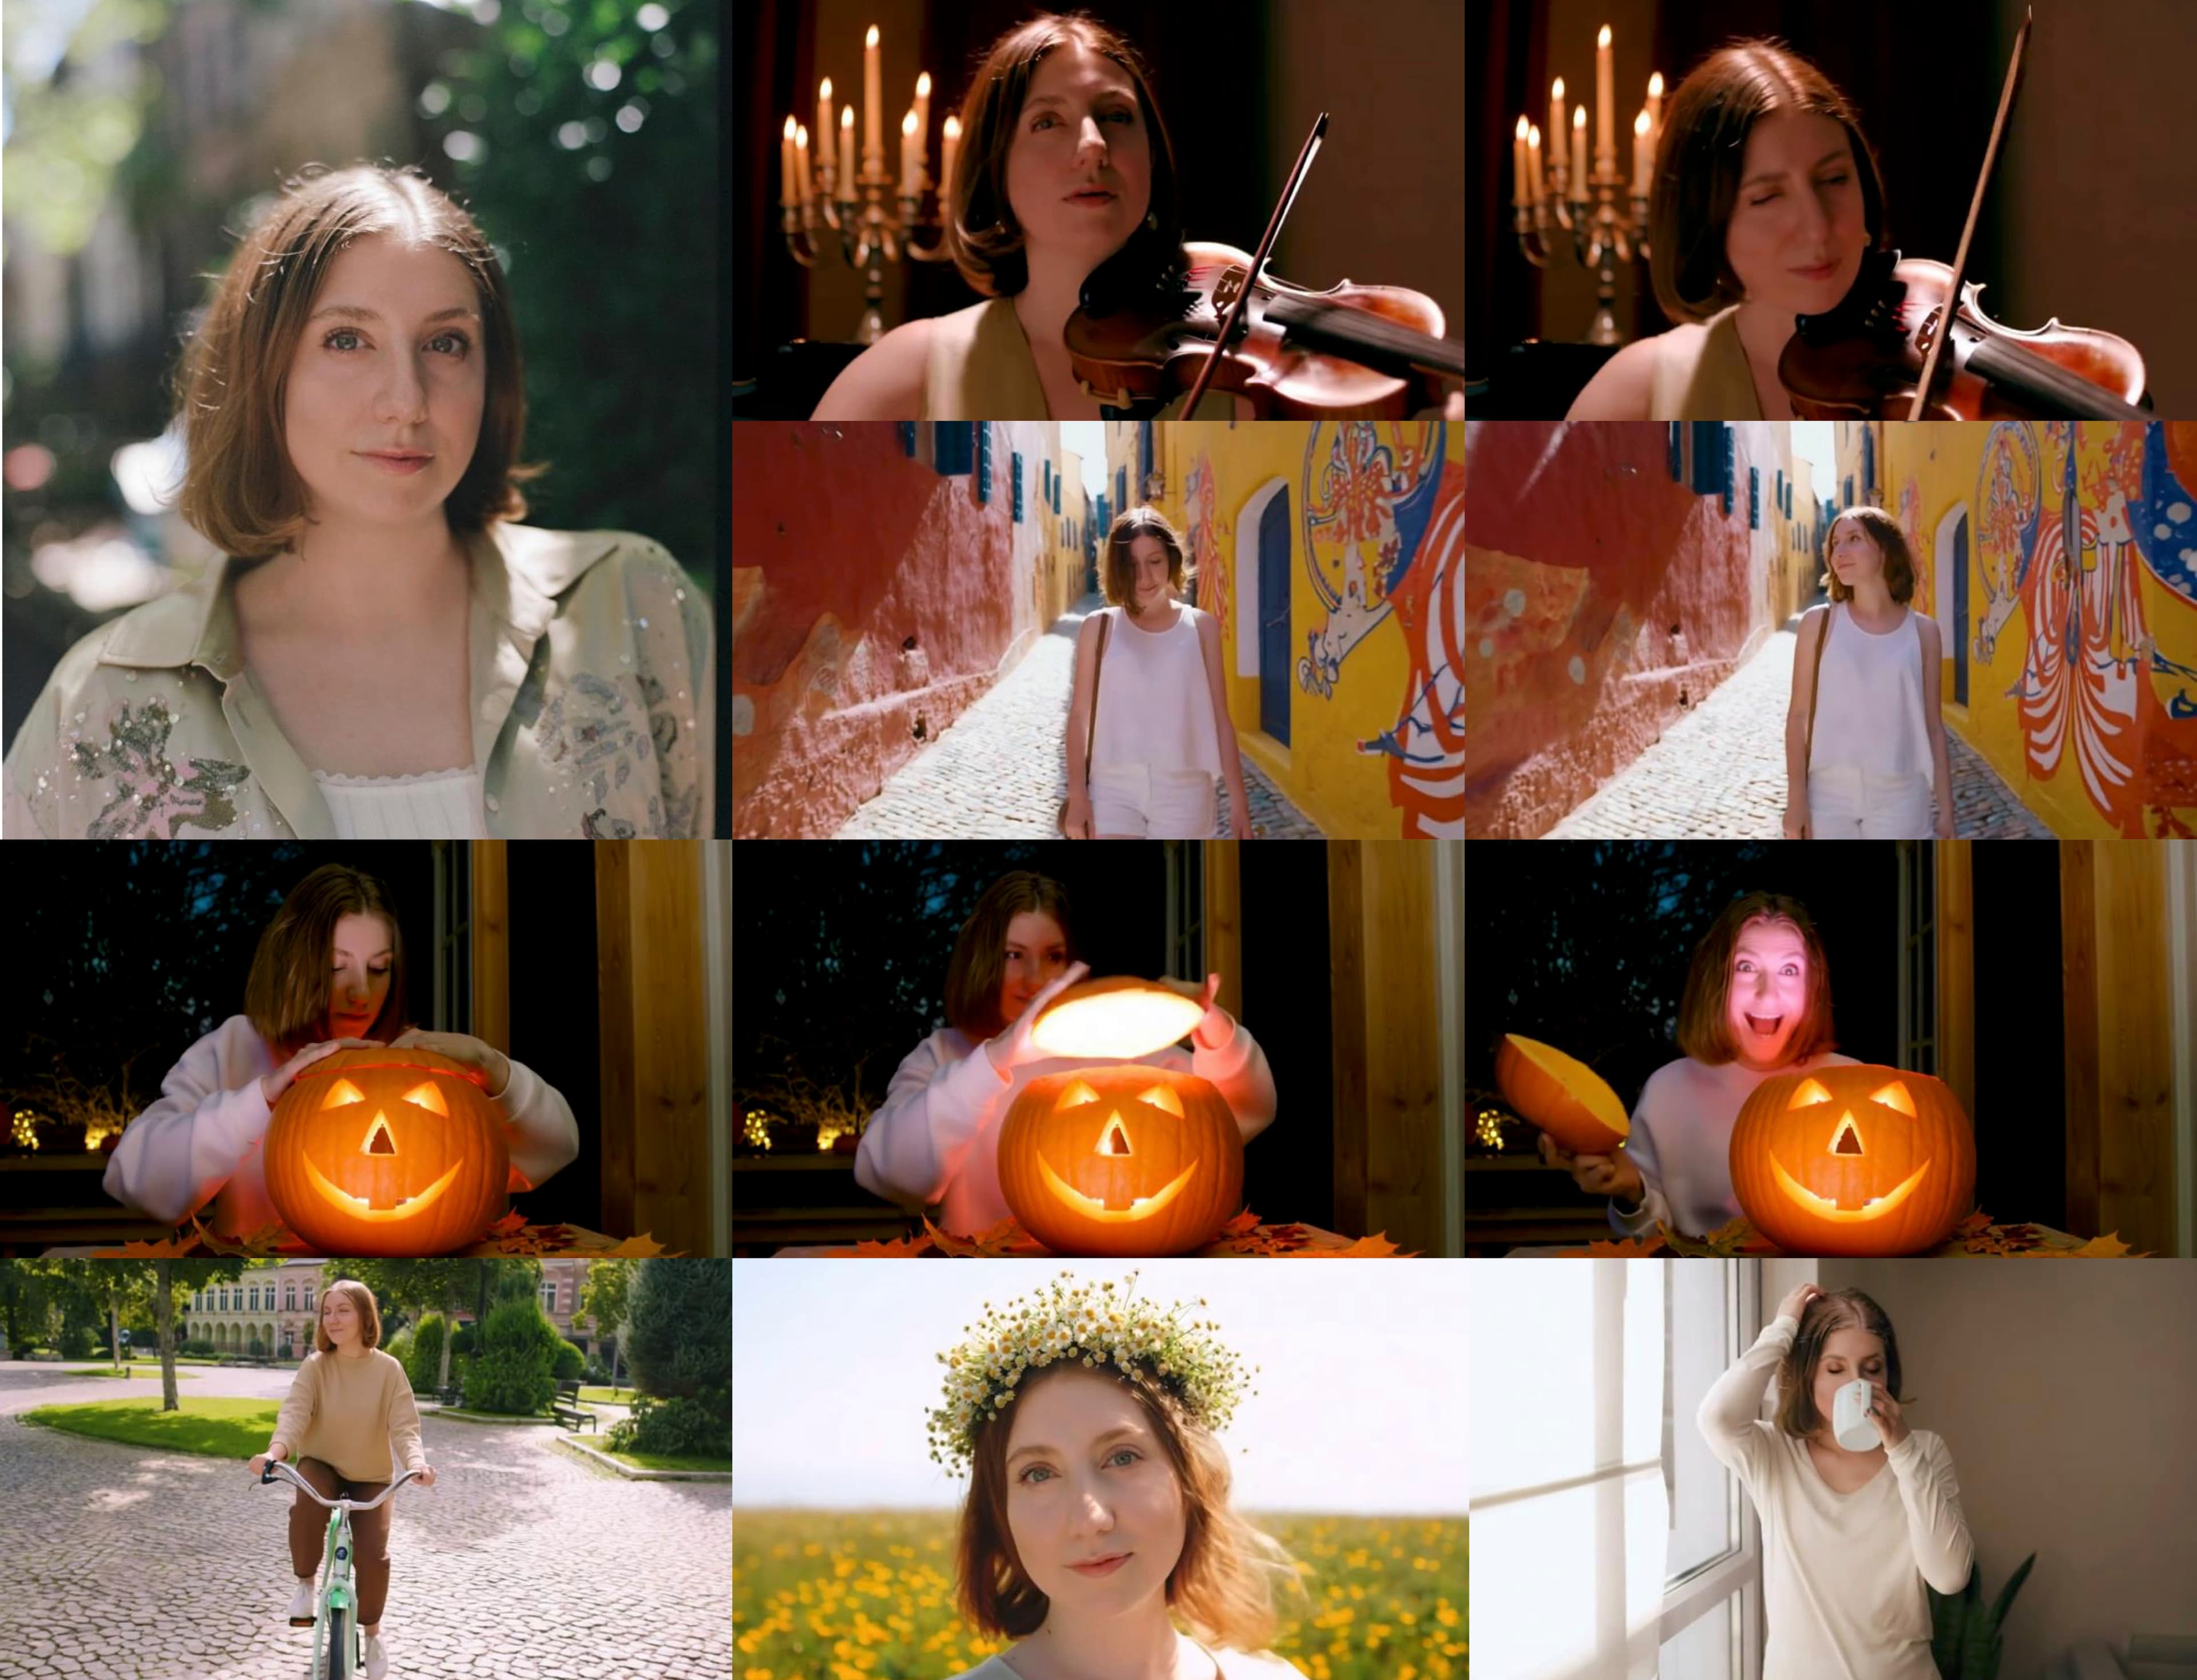
ByteDance Releases Lynx for Identity-Preserving Video
The new model from the TikTok parent company generates short video clips that maintain a person's likeness from a single reference image.
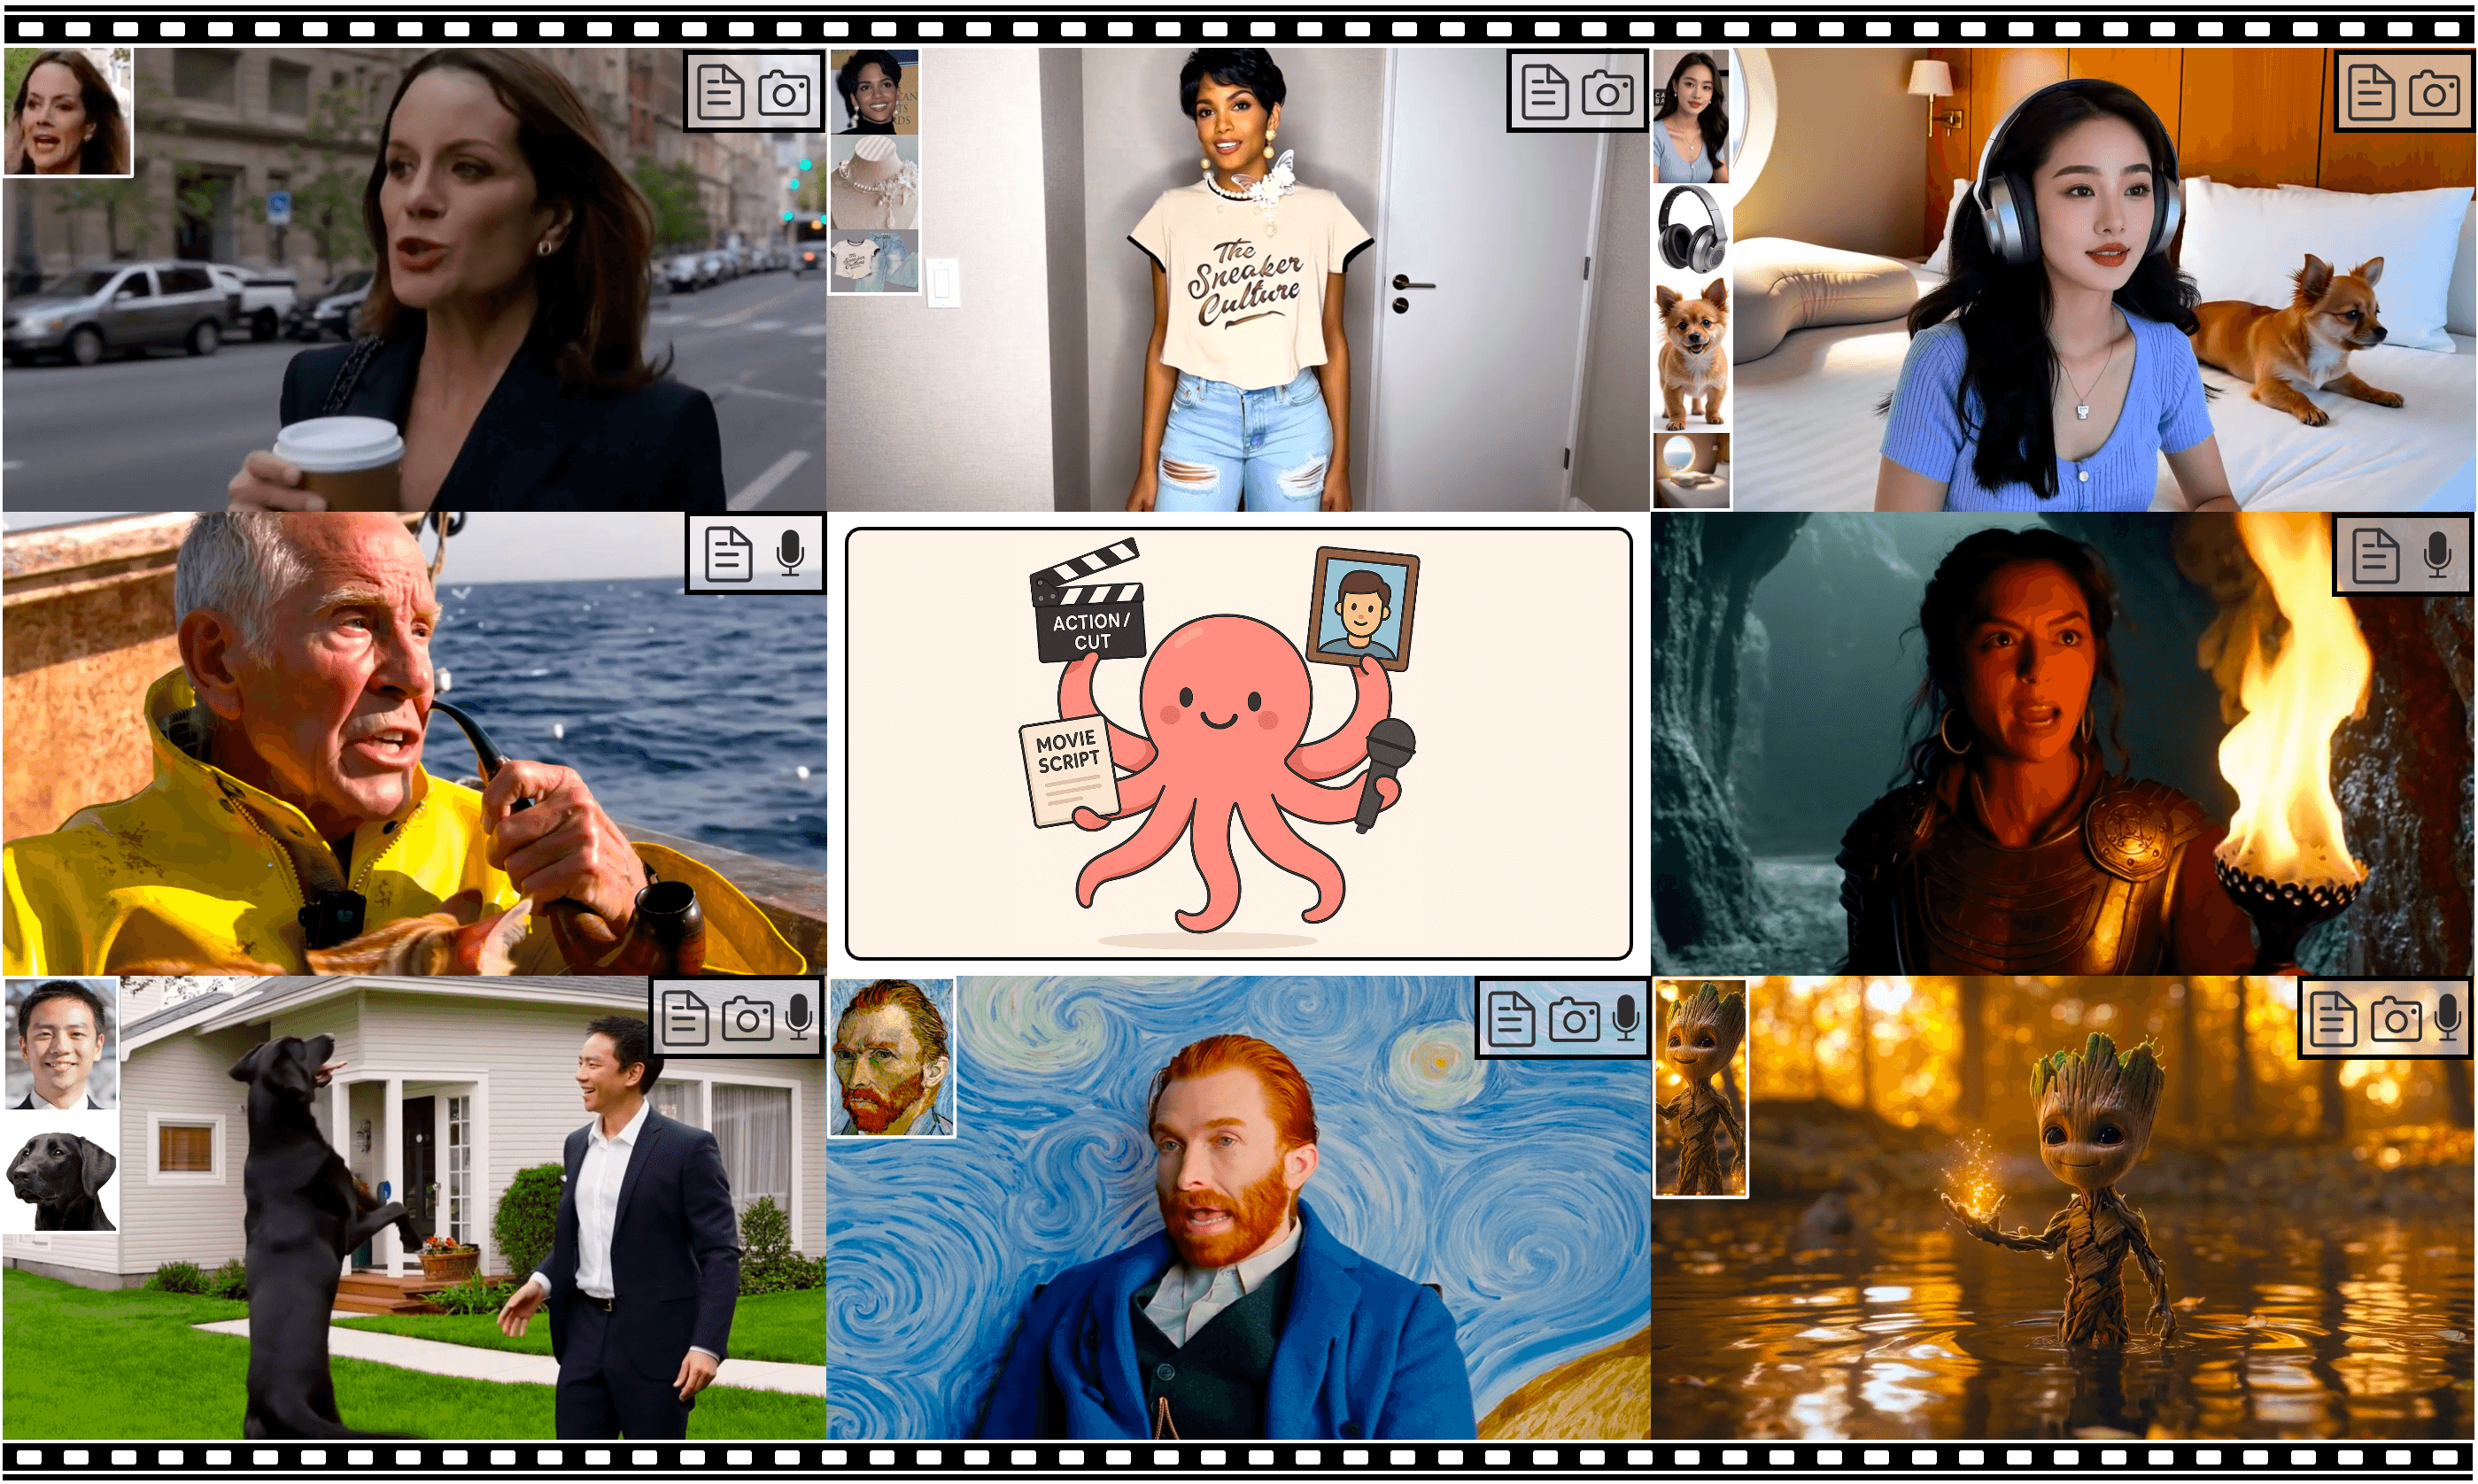
ByteDance Releases HuMo for Human Video Generation
The new open-source model specializes in creating realistic videos of people, separating appearance from motion for greater control.
ByteDance Releases Tar-7B for 'Any-to-Any' Multimodality
The new 7-billion-parameter model from the company's SEED team can process and generate a mix of text, images, audio, and video in a single unified framework.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.