KRAFTON releases A.X-K2 Raon speech MoE model
The game maker's new open model blends text-to-speech and speech recognition in a single 21B mixture-of-experts system with just 3B active parameters.
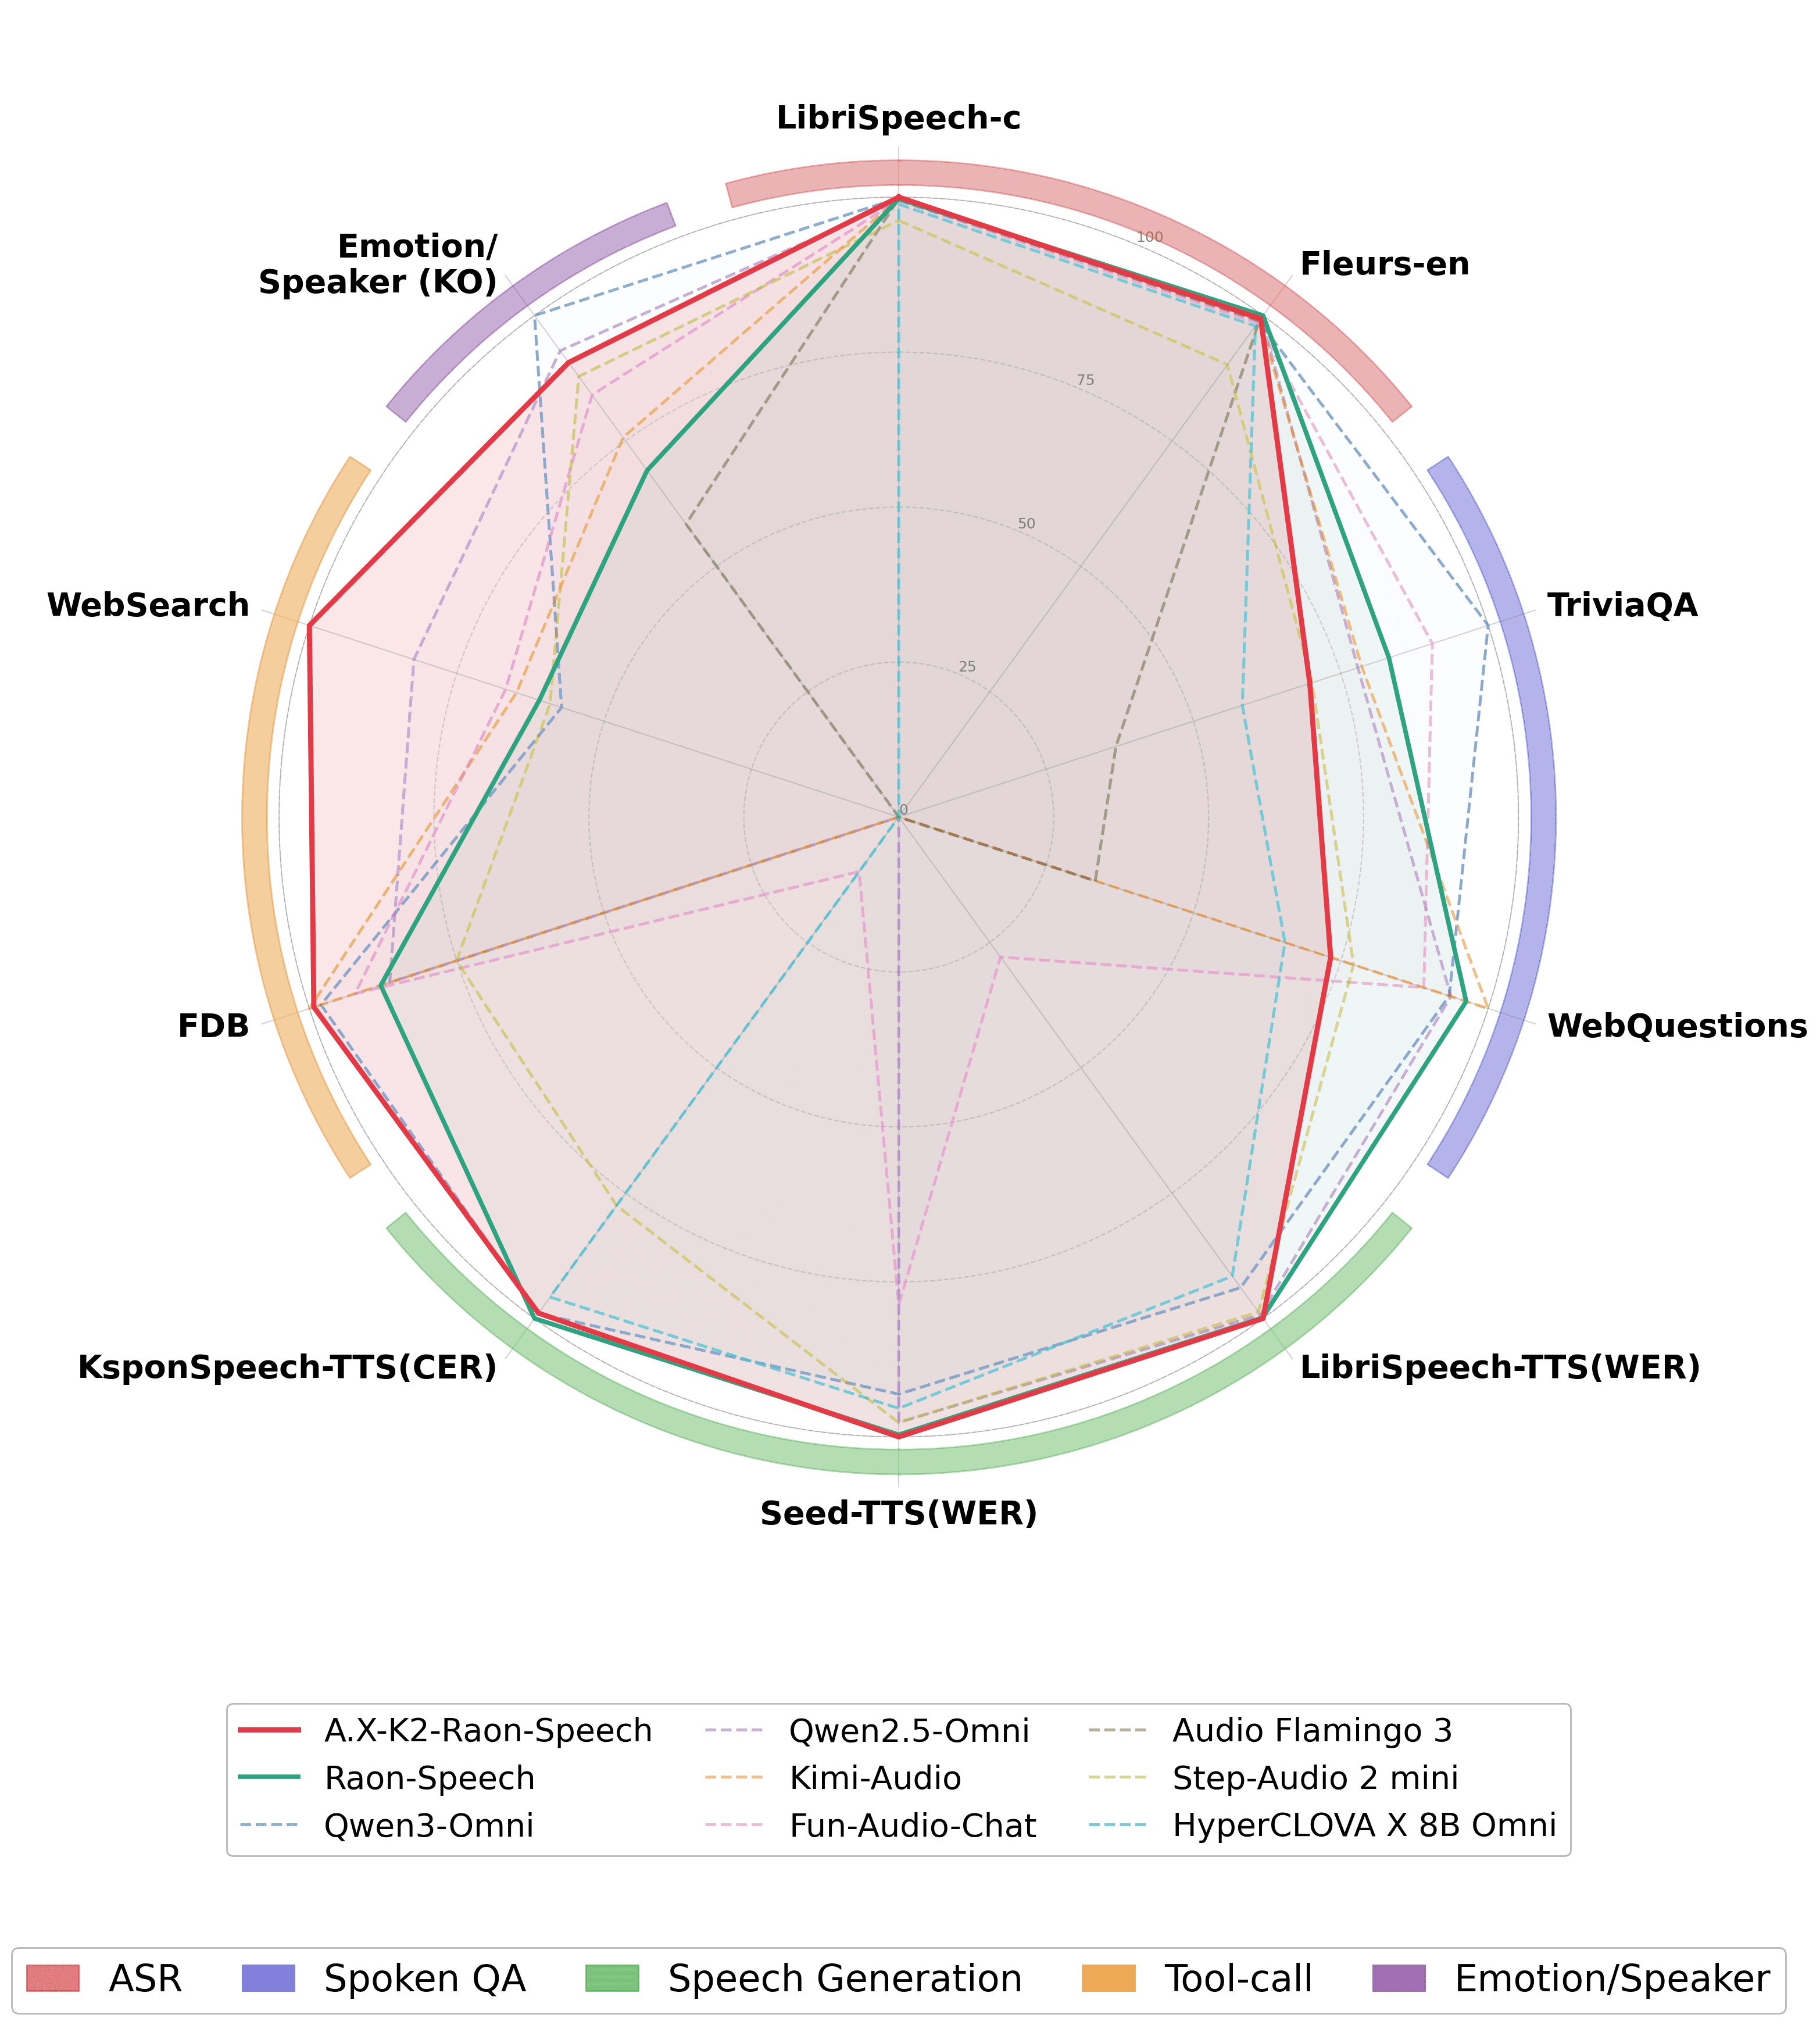
KRAFTON, the South Korean company best known as the studio behind PUBG, has published A.X-K2 Raon Speech 21B-A3B, an open speech model that handles both synthesis and recognition. The release is available now on Hugging Face.
The model is built as a mixture-of-experts system with roughly 21 billion total parameters but only about 3 billion active per token. That design lets a large model stay comparatively cheap to run at inference time, since only a fraction of its weights fire on any given pass — an approach that has become common in recent large language and multimodal releases.
One model, two directions
Rather than shipping separate systems for each task, Raon Speech aims to cover both ends of the speech pipeline in a single any-to-any architecture:
- Text-to-speech (TTS) audio generation
- Automatic speech recognition (ASR), or speech-to-text
Combining these capabilities is notable because most open speech stacks still rely on distinct specialized models. A unified system can simplify deployment and, in principle, share learned representations between listening and speaking.
The repository lists an "other" custom license, so teams evaluating the model for production should read the terms closely before building on it. KRAFTON has not published detailed benchmark figures alongside the initial release, so real-world quality across languages and audio conditions remains to be tested by the community. Still, the entry of a major game company into open speech modeling is a sign of how broadly the field is expanding beyond the usual AI labs.
Sources
- Visit
KRAFTON/A.X-K2-Raon-Speech-21B-A3B
Hugging Face
More from KRAFTON
All KRAFTON releases →
KRAFTON releases Raon-1-mini preview under Apache 2.0
The Korean game studio behind PUBG puts out a compact, permissively licensed language model as an early preview.
KRAFTON releases 1B zero-shot voice-cloning TTS
Raon-OpenTTS-1B is a flow-matching diffusion transformer that clones English voices from short reference clips.
KRAFTON Releases 9B Bilingual Speech Model
The gaming giant behind 'PUBG' has released Raon-Speech-9B, a multimodal model for English and Korean speech recognition and synthesis.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.