KRAFTON releases 1B zero-shot voice-cloning TTS
Raon-OpenTTS-1B is a flow-matching diffusion transformer that clones English voices from short reference clips.
KRAFTON has published Raon-OpenTTS-1B, a one-billion-parameter text-to-speech model that generates English speech and can mimic a target voice from a short reference sample. The release is available on Hugging Face and marks the first version of the Raon open TTS line.
The model is a flow-matching diffusion transformer, an architecture that has become popular for high-quality audio and image synthesis because it can produce natural output in relatively few sampling steps. Positioned as a zero-shot voice-cloning system, it aims to reproduce a speaker's timbre without per-voice fine-tuning, relying instead on a reference clip at inference time.
What it offers
- Roughly 1B parameters, a size that stays practical to run on a single modern GPU
- Zero-shot voice cloning from a short reference sample
- English-language output
- A flow-matching diffusion-transformer backbone
Why it matters
Open zero-shot TTS remains a competitive space, and a compact 1B model that clones voices lowers the barrier for developers building narration, accessibility, and assistant features without training custom voices. The tradeoff is scope: this initial release targets English only, and the repository carries a non-standard "other" license, so teams should check the terms before commercial use. As a version 1.0, it establishes a baseline the family can iterate on.
Sources
- Visit
KRAFTON/Raon-OpenTTS-1B
Hugging Face
More from KRAFTON
All KRAFTON releases →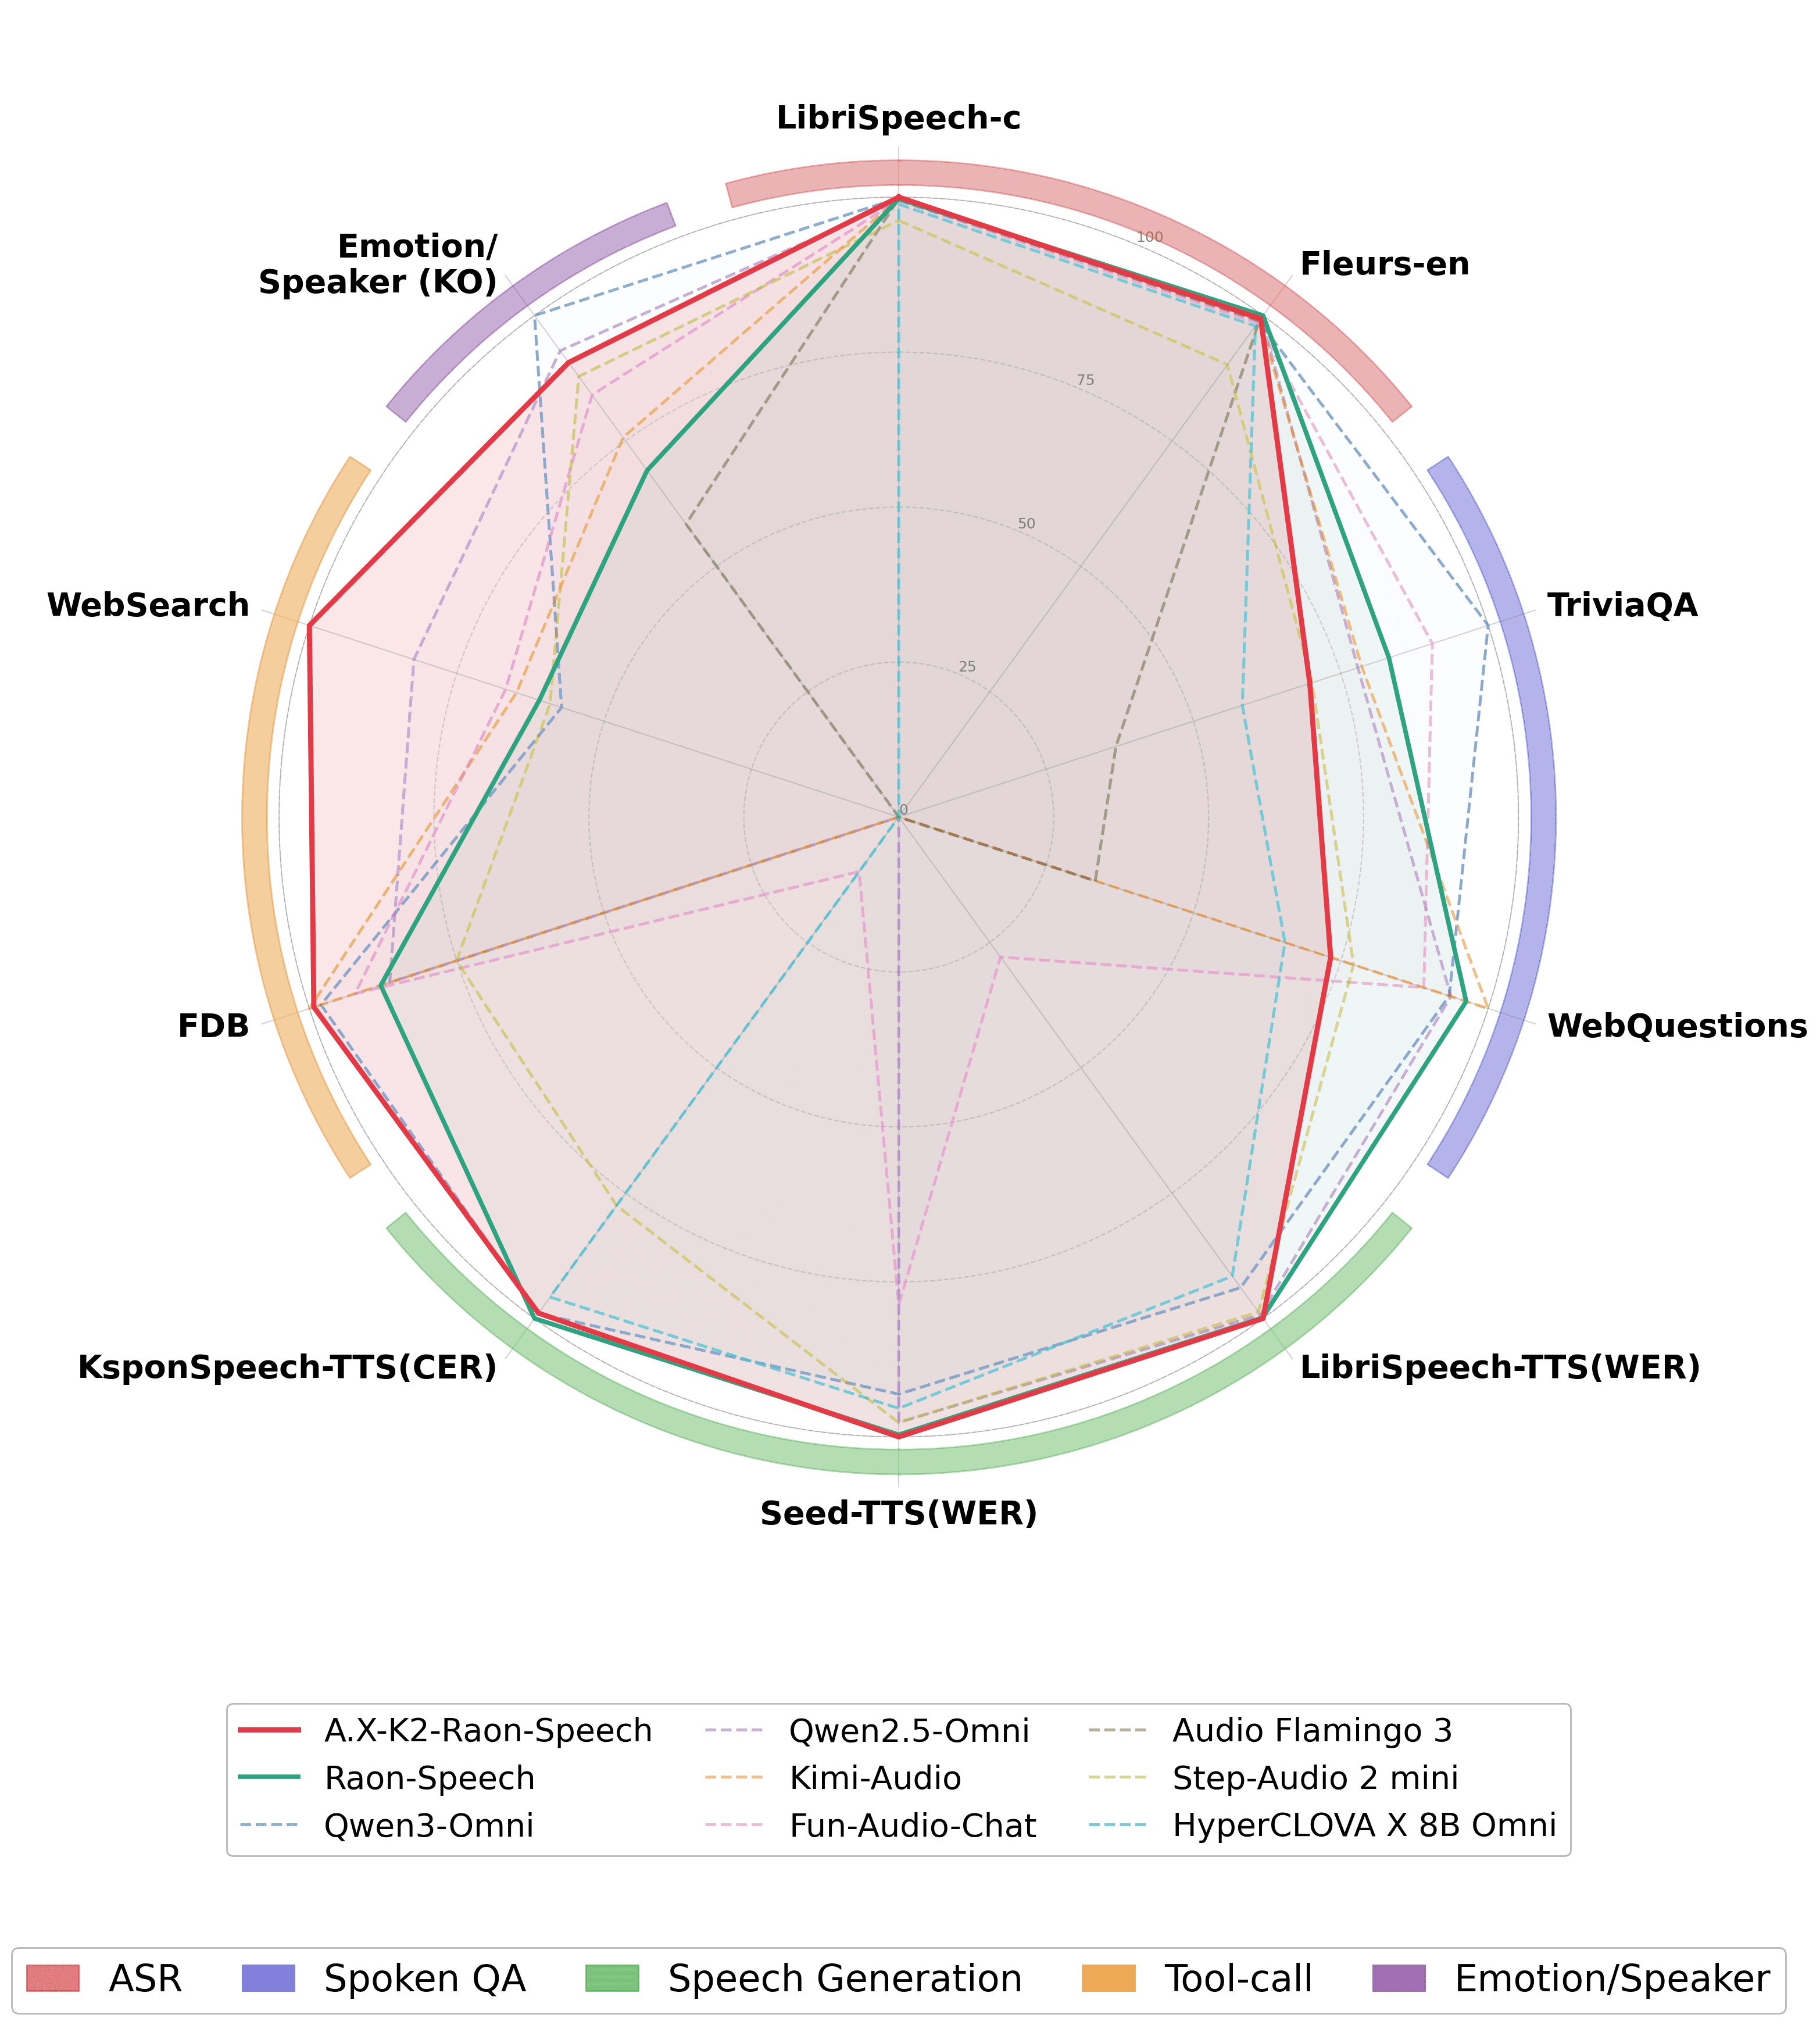
KRAFTON releases A.X-K2 Raon speech MoE model
The game maker's new open model blends text-to-speech and speech recognition in a single 21B mixture-of-experts system with just 3B active parameters.
KRAFTON Releases 9B Bilingual Speech Model
The gaming giant behind 'PUBG' has released Raon-Speech-9B, a multimodal model for English and Korean speech recognition and synthesis.
More in Text → Speech
All Text → Speech →Nari Labs Ships Qwen3-Based TTS and ASR Models
The startup pairs speech synthesis and recognition built on Qwen3, pitching accuracy, low latency, and lower cost.
StepFun's StepAudio 3 Realtime targets live voice AI
The audio-language foundation model builds a listen-converse-think-act loop aimed at natural, low-latency spoken interaction.
StepFun's StepAudio 3 Gen Unifies TTS and Music
A single discrete autoregressive model handles speech, voice design, sound effects, and music generation.
0 comments
No comments yet. Be the first to weigh in.