NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR
A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.
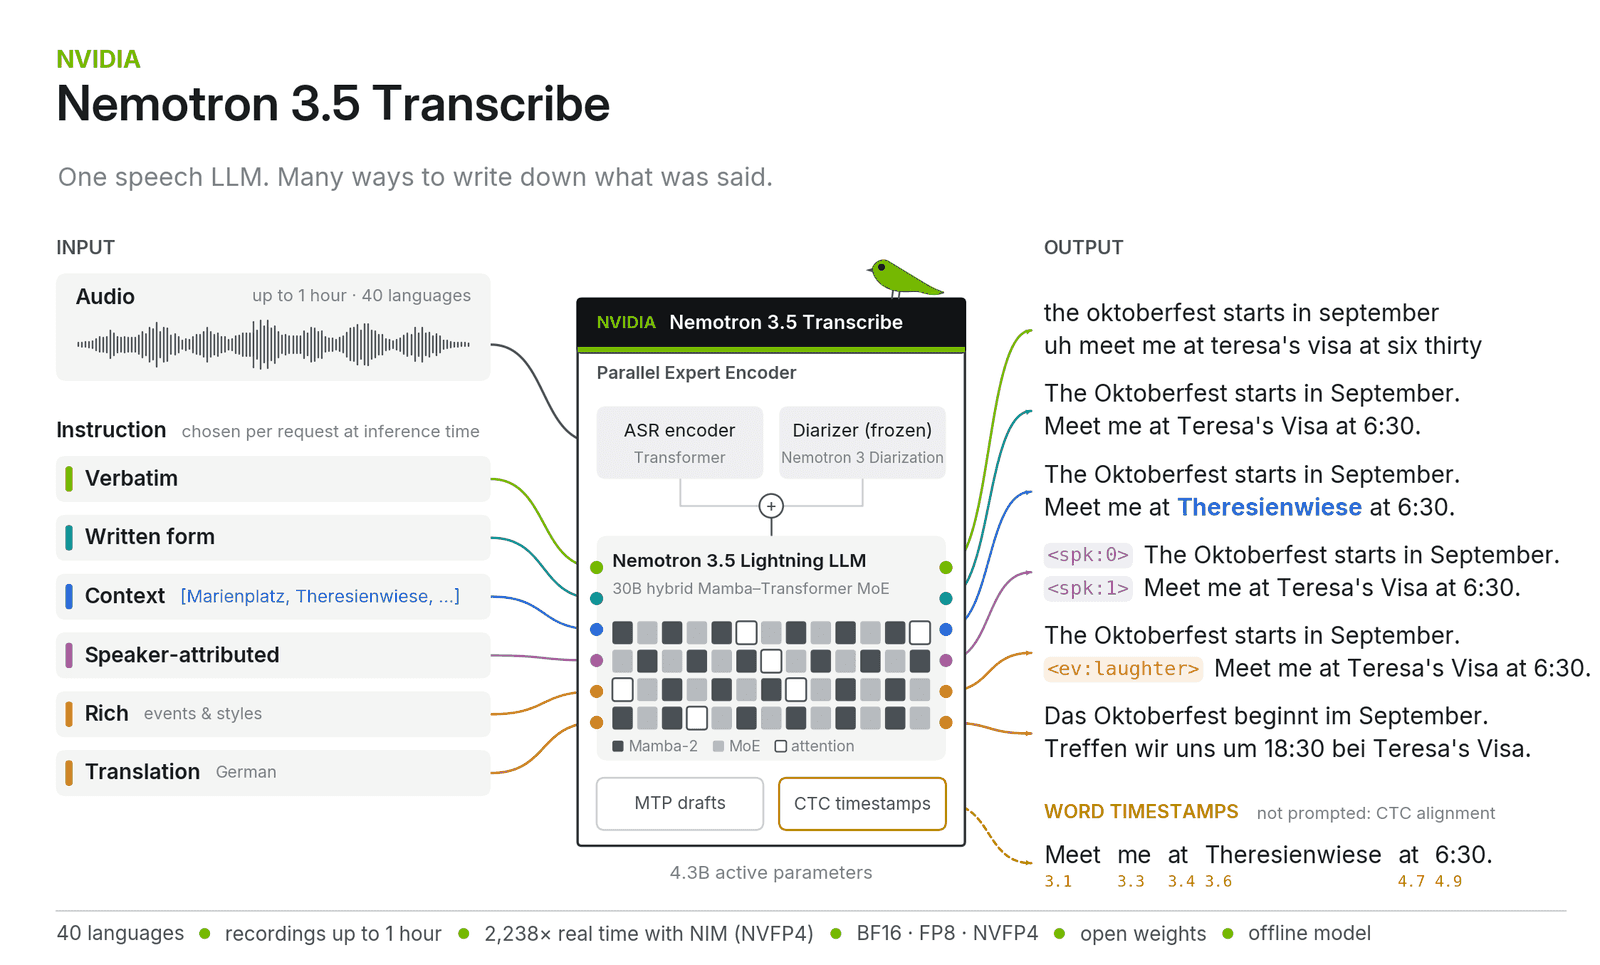
NVIDIA has released Nemotron 3.5 Transcribe 30B-A4B, a speech recognition model that leans on a mixture-of-experts design to keep inference light while scaling capacity. The model totals roughly 30 billion parameters but activates only about 4 billion per token, a now-familiar pattern that aims to deliver larger-model quality at a smaller compute cost.
The headline feature is that it is promptable: rather than a fixed transcription pipeline, the model can be steered toward different tasks through instructions. According to NVIDIA's release write-up, that includes multilingual transcription, speech translation, and speaker diarization from a single system.
What it does
- Multilingual automatic speech recognition
- Speech-to-text translation across languages
- Speaker diarization to separate who said what
- Prompt-based control over the output task
Combining these capabilities in one promptable model is the interesting part. Teams typically stitch together separate systems for transcription, translation, and diarization; folding them into a single checkpoint simplifies deployment and could reduce the glue code and latency that usually come with multi-stage audio pipelines.
Why it matters: open ASR has lagged behind the pace of open text and image models, and a sparse, instruction-driven option from a major vendor gives developers a flexible building block for captioning, meeting tools, and voice interfaces. The model ships under a custom NVIDIA license, so prospective users should review the terms before building on it.
Sources
- Visit
nvidia/NVIDIA-Nemotron-3.5-Transcribe-30B-A4B
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Speech → Text
All Speech → Text →IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
TII extends the Falcon family into speech recognition
The Abu Dhabi lab behind the Falcon language models releases Falcon ASR, an open speech-to-text system.
0 comments
No comments yet. Be the first to weigh in.