NVIDIA Releases Cosmos3 Image-to-Video World Model
The latest release in NVIDIA's 'world model' research family aims to generate coherent and realistic video from a single static image.
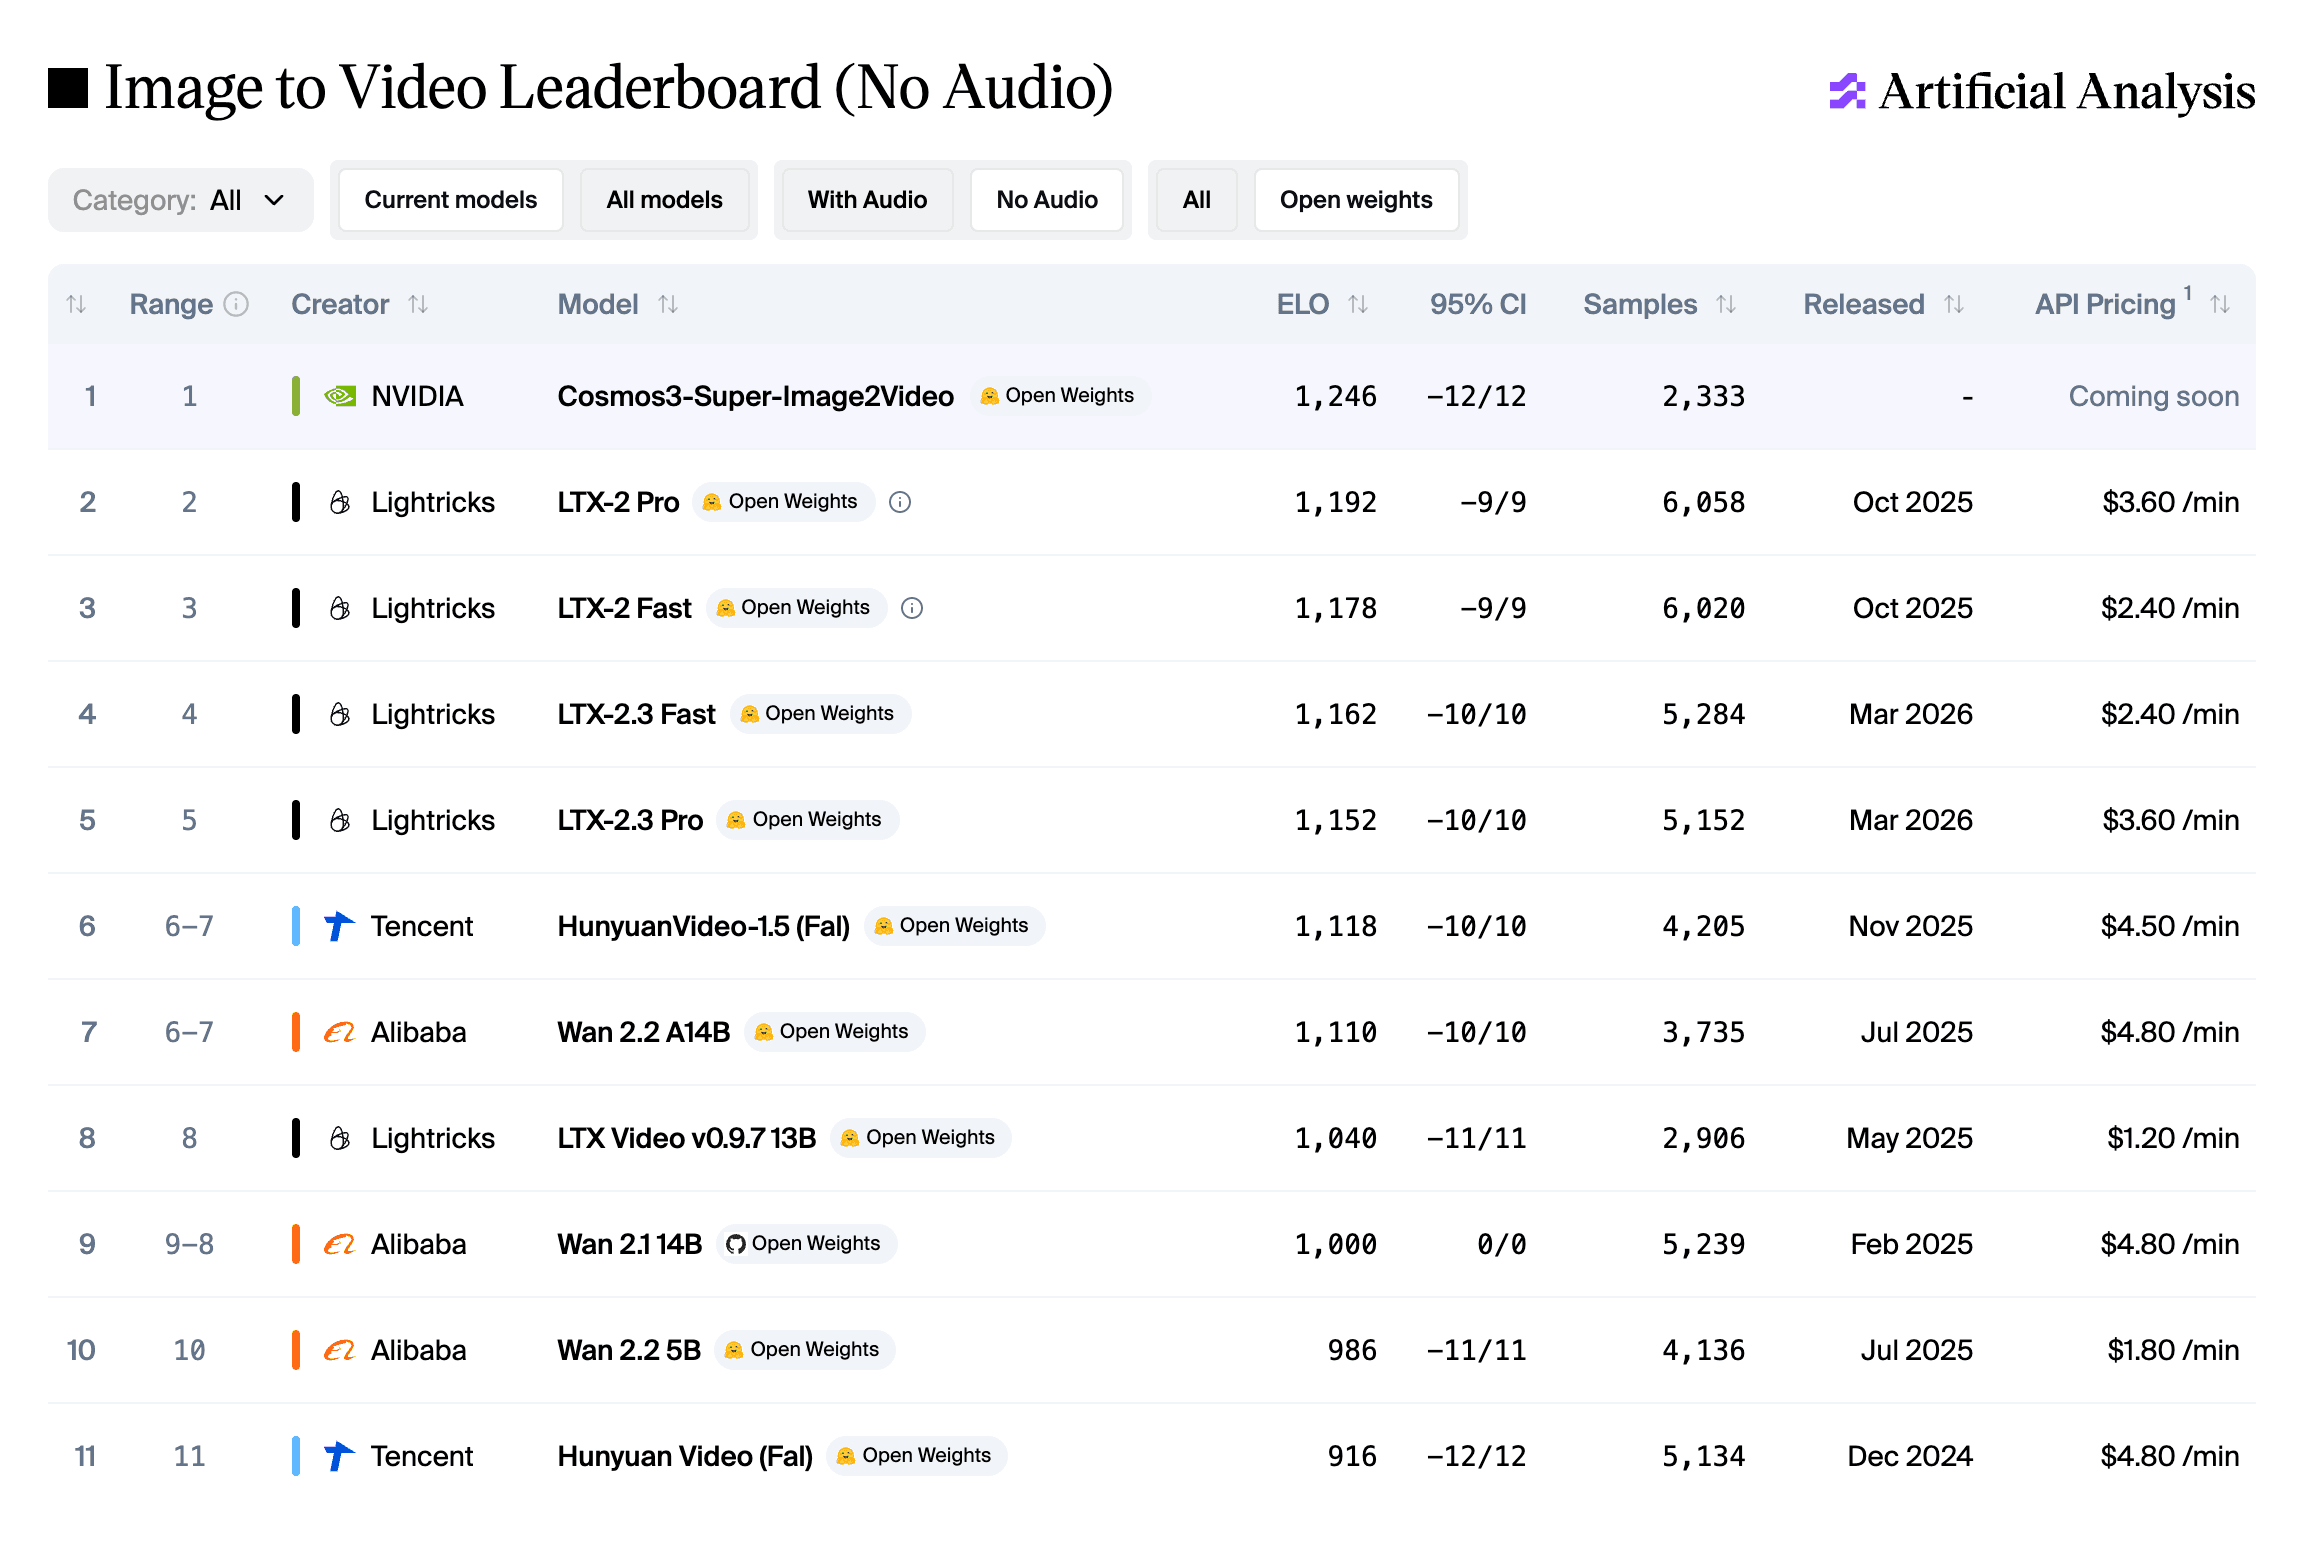
NVIDIA has quietly released a new generative video model, Cosmos3 Super Image2Video, making the weights available for download on Hugging Face. The model is designed for the increasingly popular task of image-to-video generation, creating short video clips from a single static input image.
Unlike many other animation models, NVIDIA frames Cosmos3 as part of its "world-model" research family. This framing suggests an ambitious goal beyond simple motion generation. World models aim to create an internal representation of the rules and dynamics of an environment, which could lead to more physically plausible and temporally coherent video outputs. The goal is to animate a scene by simulating its evolution rather than just interpolating pixels.
The model is available now for researchers and developers to explore. However, it is released under a custom license that is not open-source and comes with specific use restrictions. Potential users should review the terms carefully before integrating it into their projects.
This release underscores NVIDIA's deep investment in foundational AI research, extending far beyond its role as a hardware provider. As generative video technology advances, models that can demonstrate a more robust understanding of the real world—its physics, object interactions, and causal relationships—will be critical. Cosmos3 represents another step by a major industry player toward that more sophisticated future.
Sources
- Visit
nvidia/Cosmos3-Super-Image2Video
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
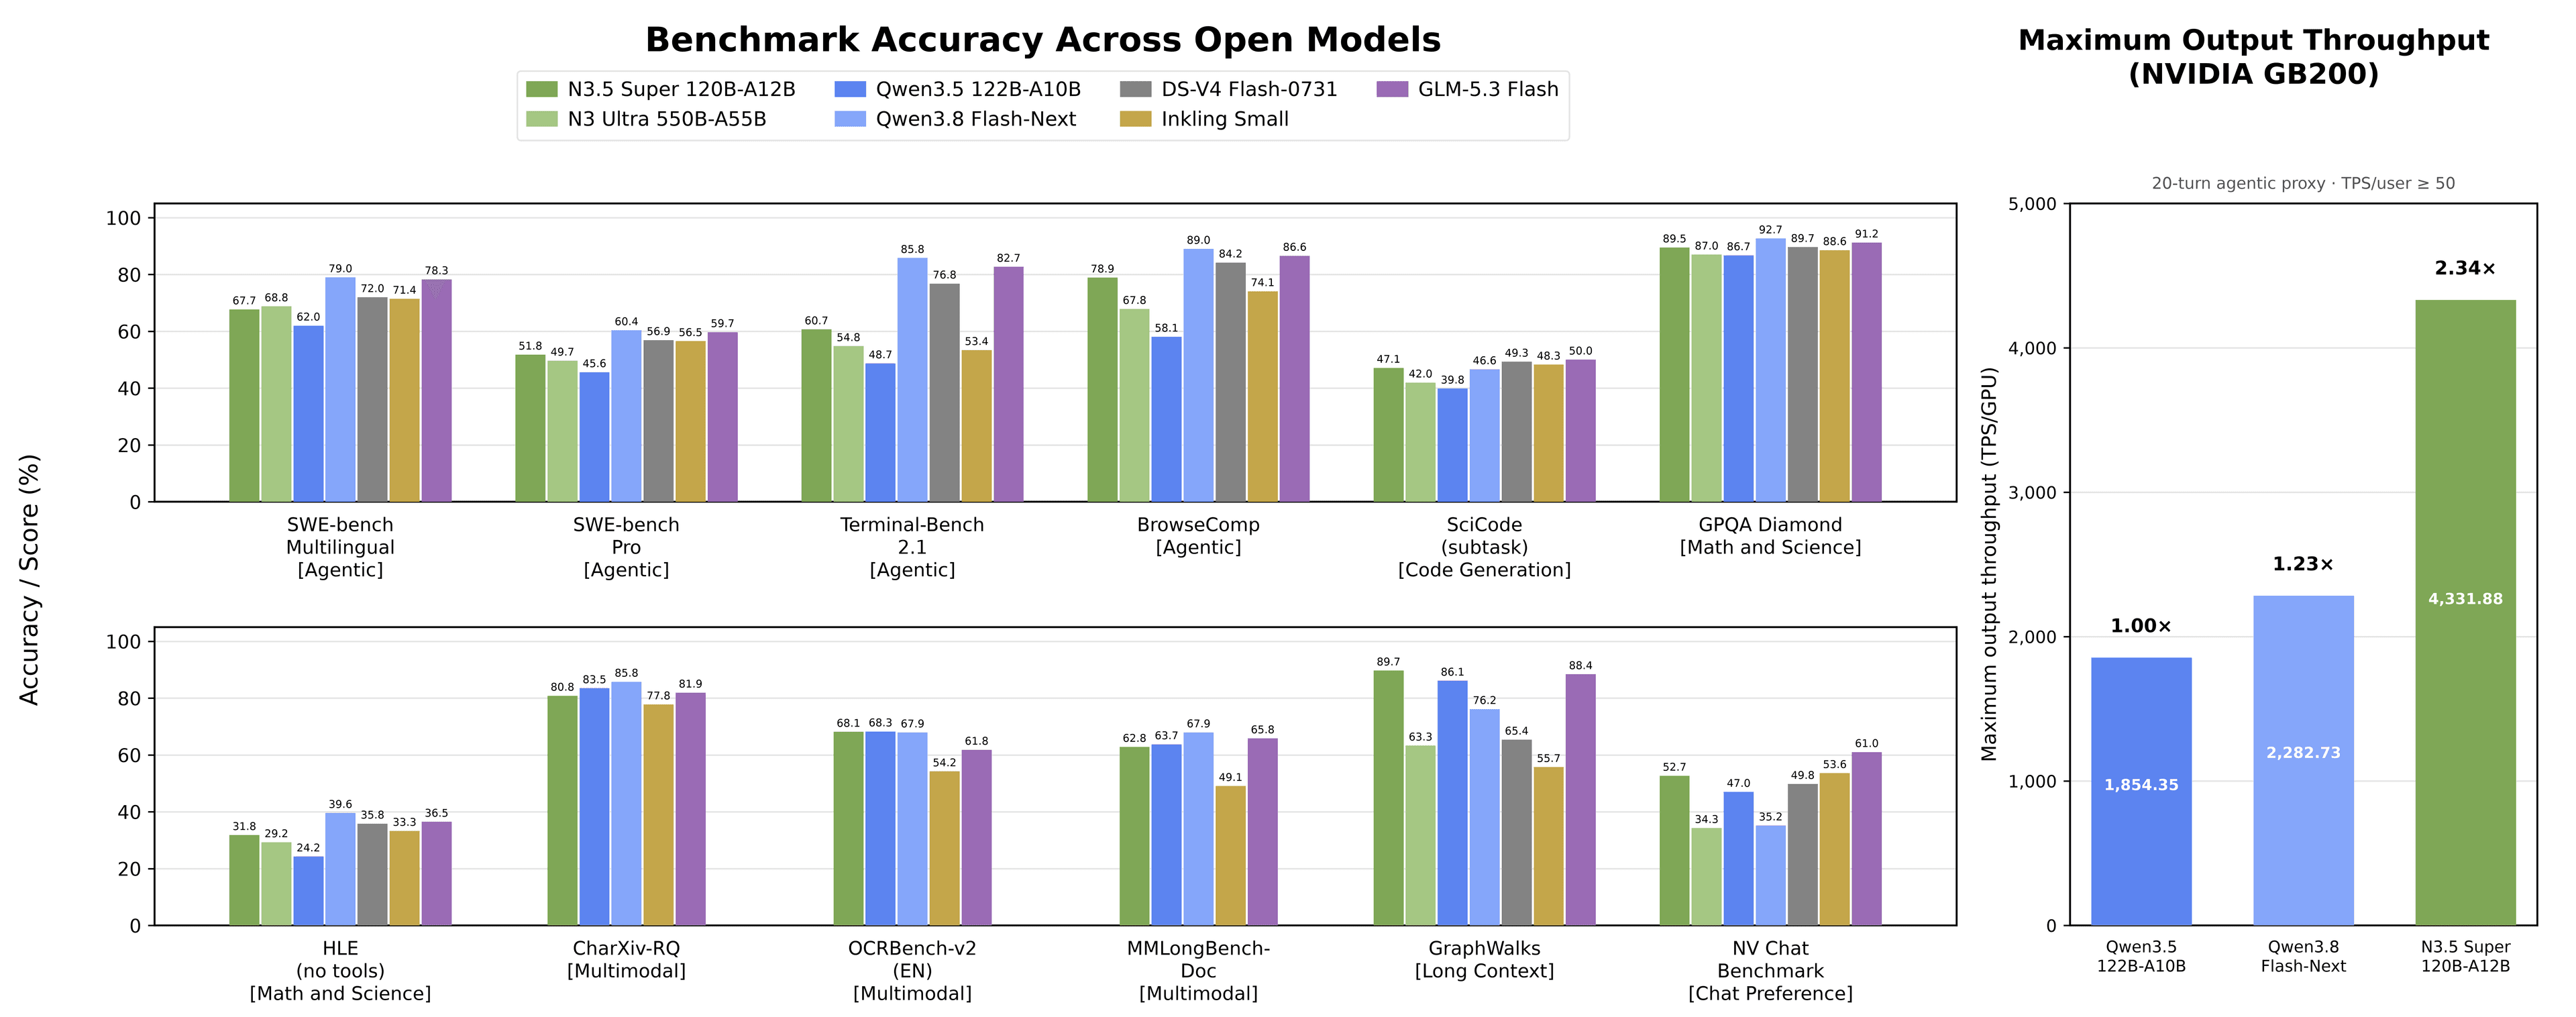
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
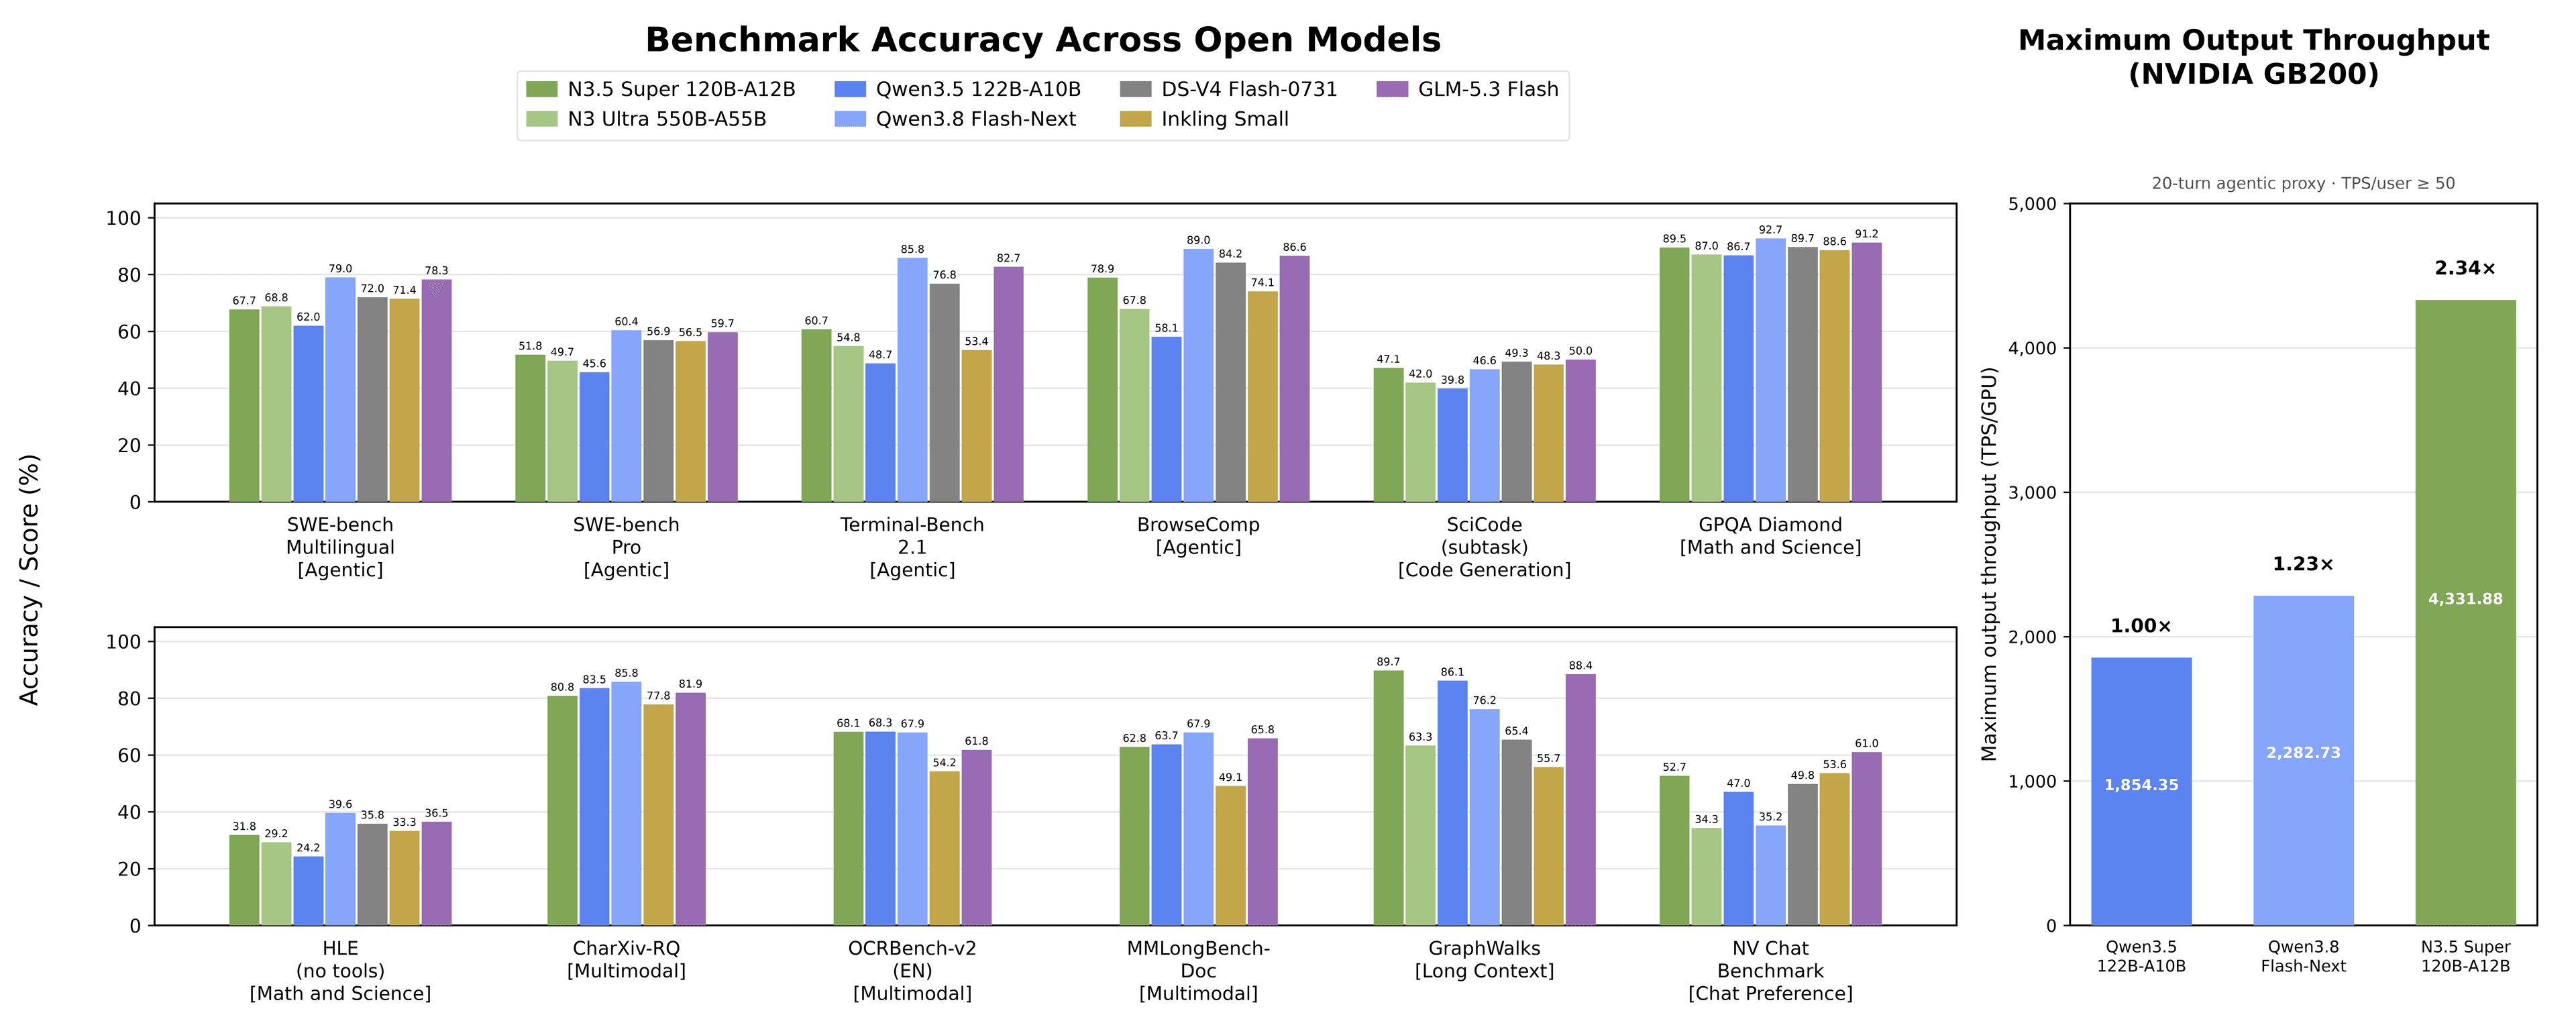
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Image → Video
All Image → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
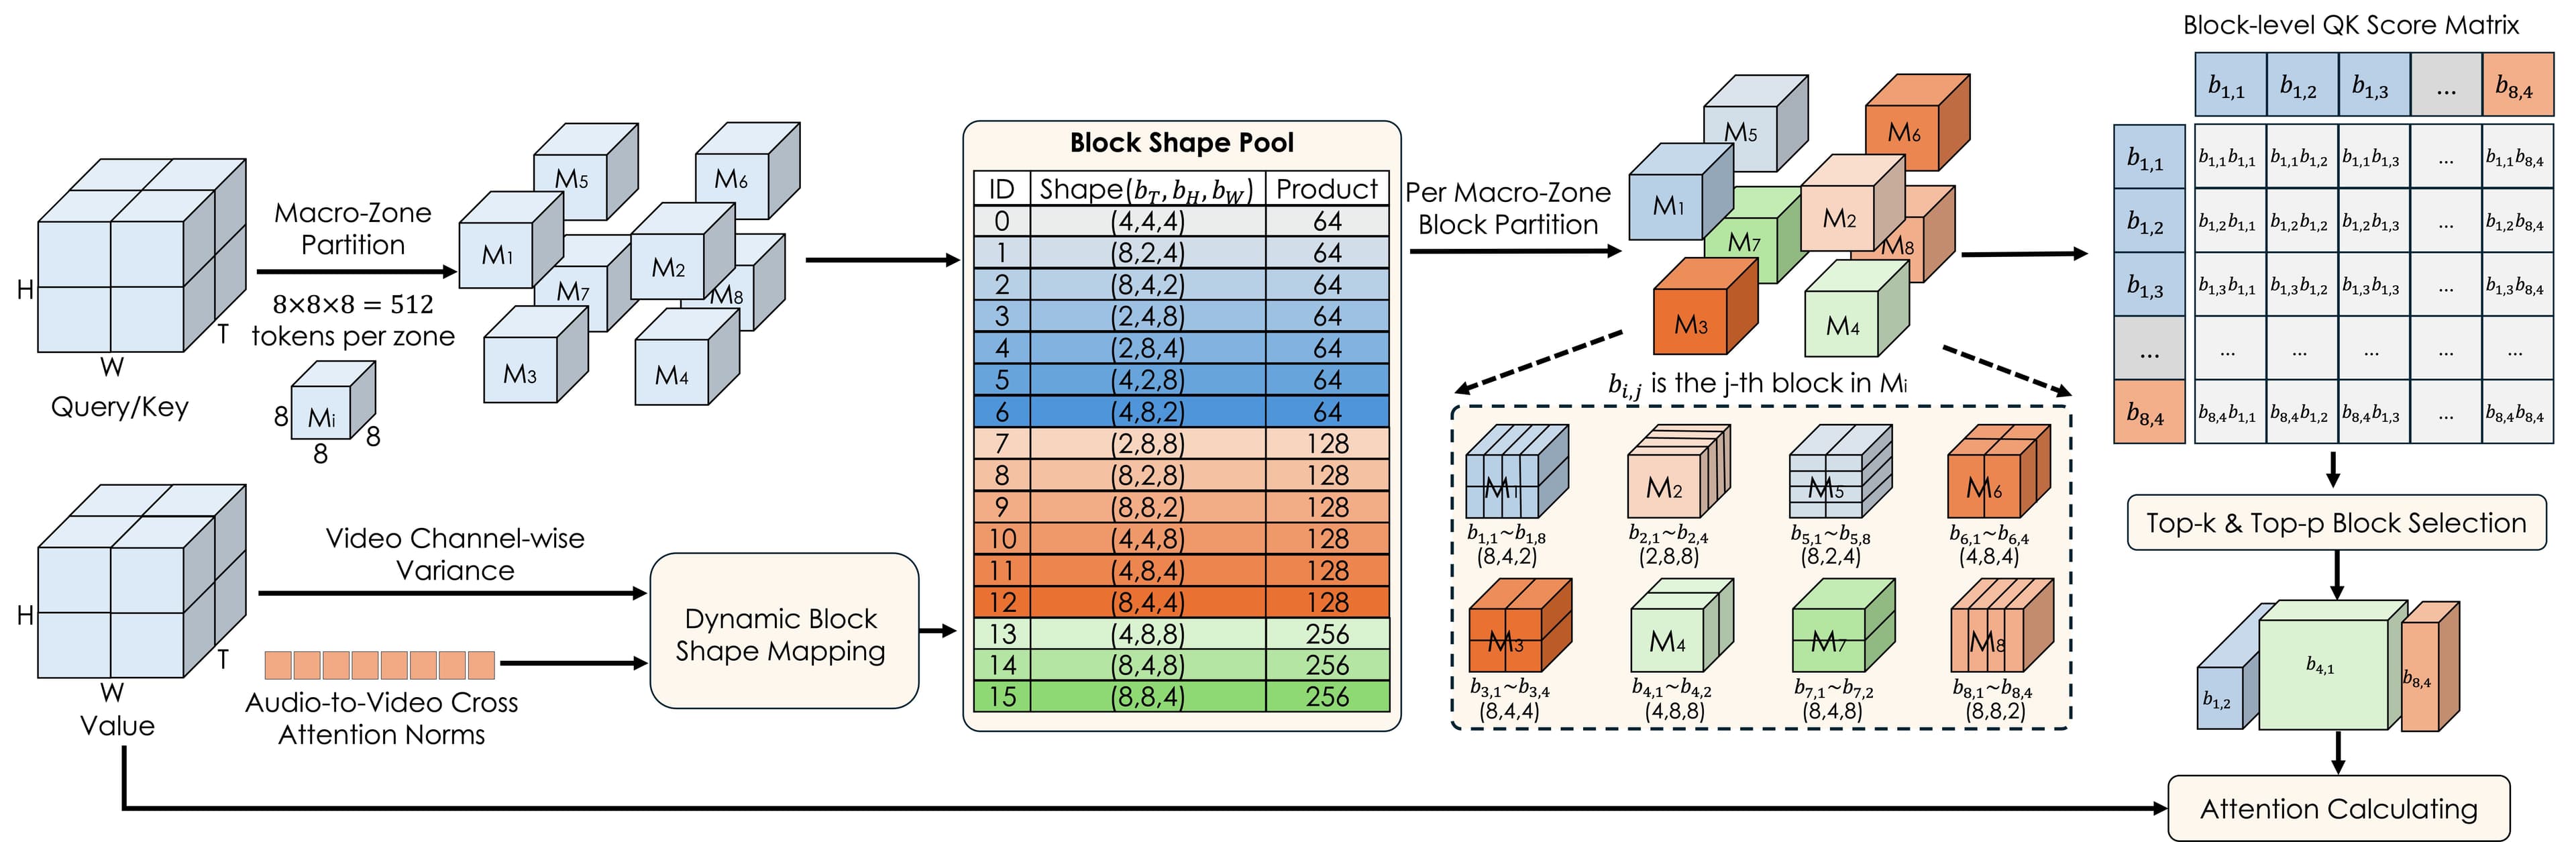
Prism Brings Joint Video-Audio Generation to Diffusion
A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.
Viggle Releases Viggle-Animate for Character Swaps
The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.
0 comments
No comments yet. Be the first to weigh in.