NVIDIA Releases Canary 1B v2 Multilingual Speech Model
The new 1-billion-parameter model handles both transcription and translation across five languages using the company's efficient FastConformer architecture.

NVIDIA has released Canary 1B v2, a versatile 1-billion-parameter model for automatic speech recognition (ASR) and translation. Published with a permissive CC-BY-4.0 license, the model provides developers with a powerful new tool for building voice-enabled applications.
The model is built on NVIDIA's FastConformer architecture, which is designed for high-performance and efficient speech processing. Canary excels at multilingual tasks, handling both transcription in a source language and translation from that language into English within a single model.
Core Capabilities
According to its official release card, Canary 1B v2 was trained to handle several key tasks without the need for separate models:
- Transcription: Supports English, German, French, Spanish, and Mandarin.
- Translation: Can translate any of the supported source languages into English text.
- Formatting: Includes automatic punctuation and capitalization to produce more readable output.
This release adds another high-quality, open-source option to a field largely defined by models like OpenAI's Whisper. By providing a permissively licensed and efficient alternative, NVIDIA gives developers more flexibility for integrating advanced speech AI. The model and its usage instructions are available on NVIDIA's Hugging Face page.
Sources
- Visit
nvidia/canary-1b-v2
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
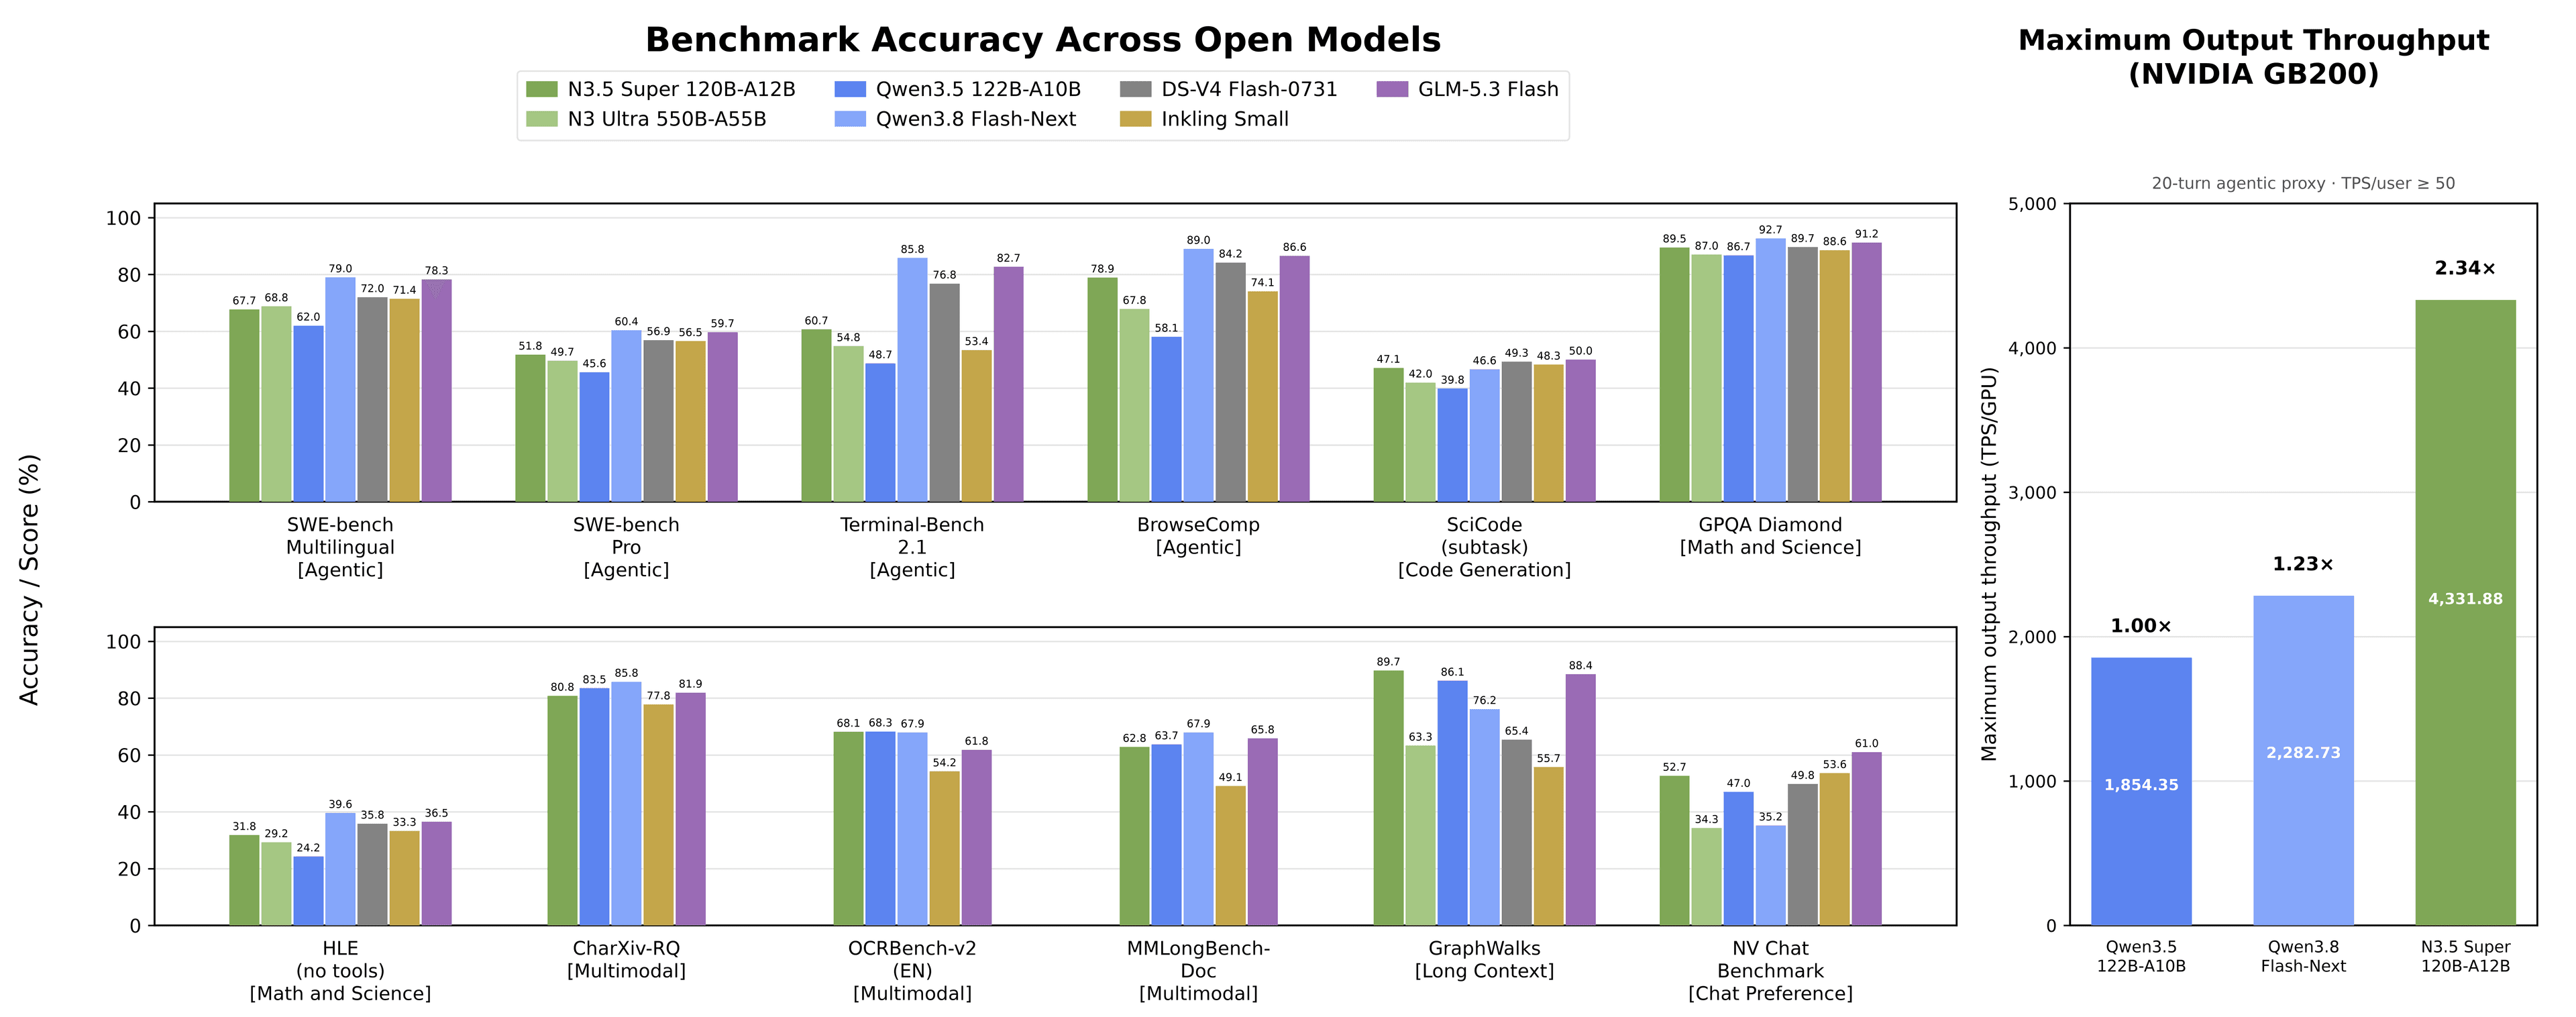
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
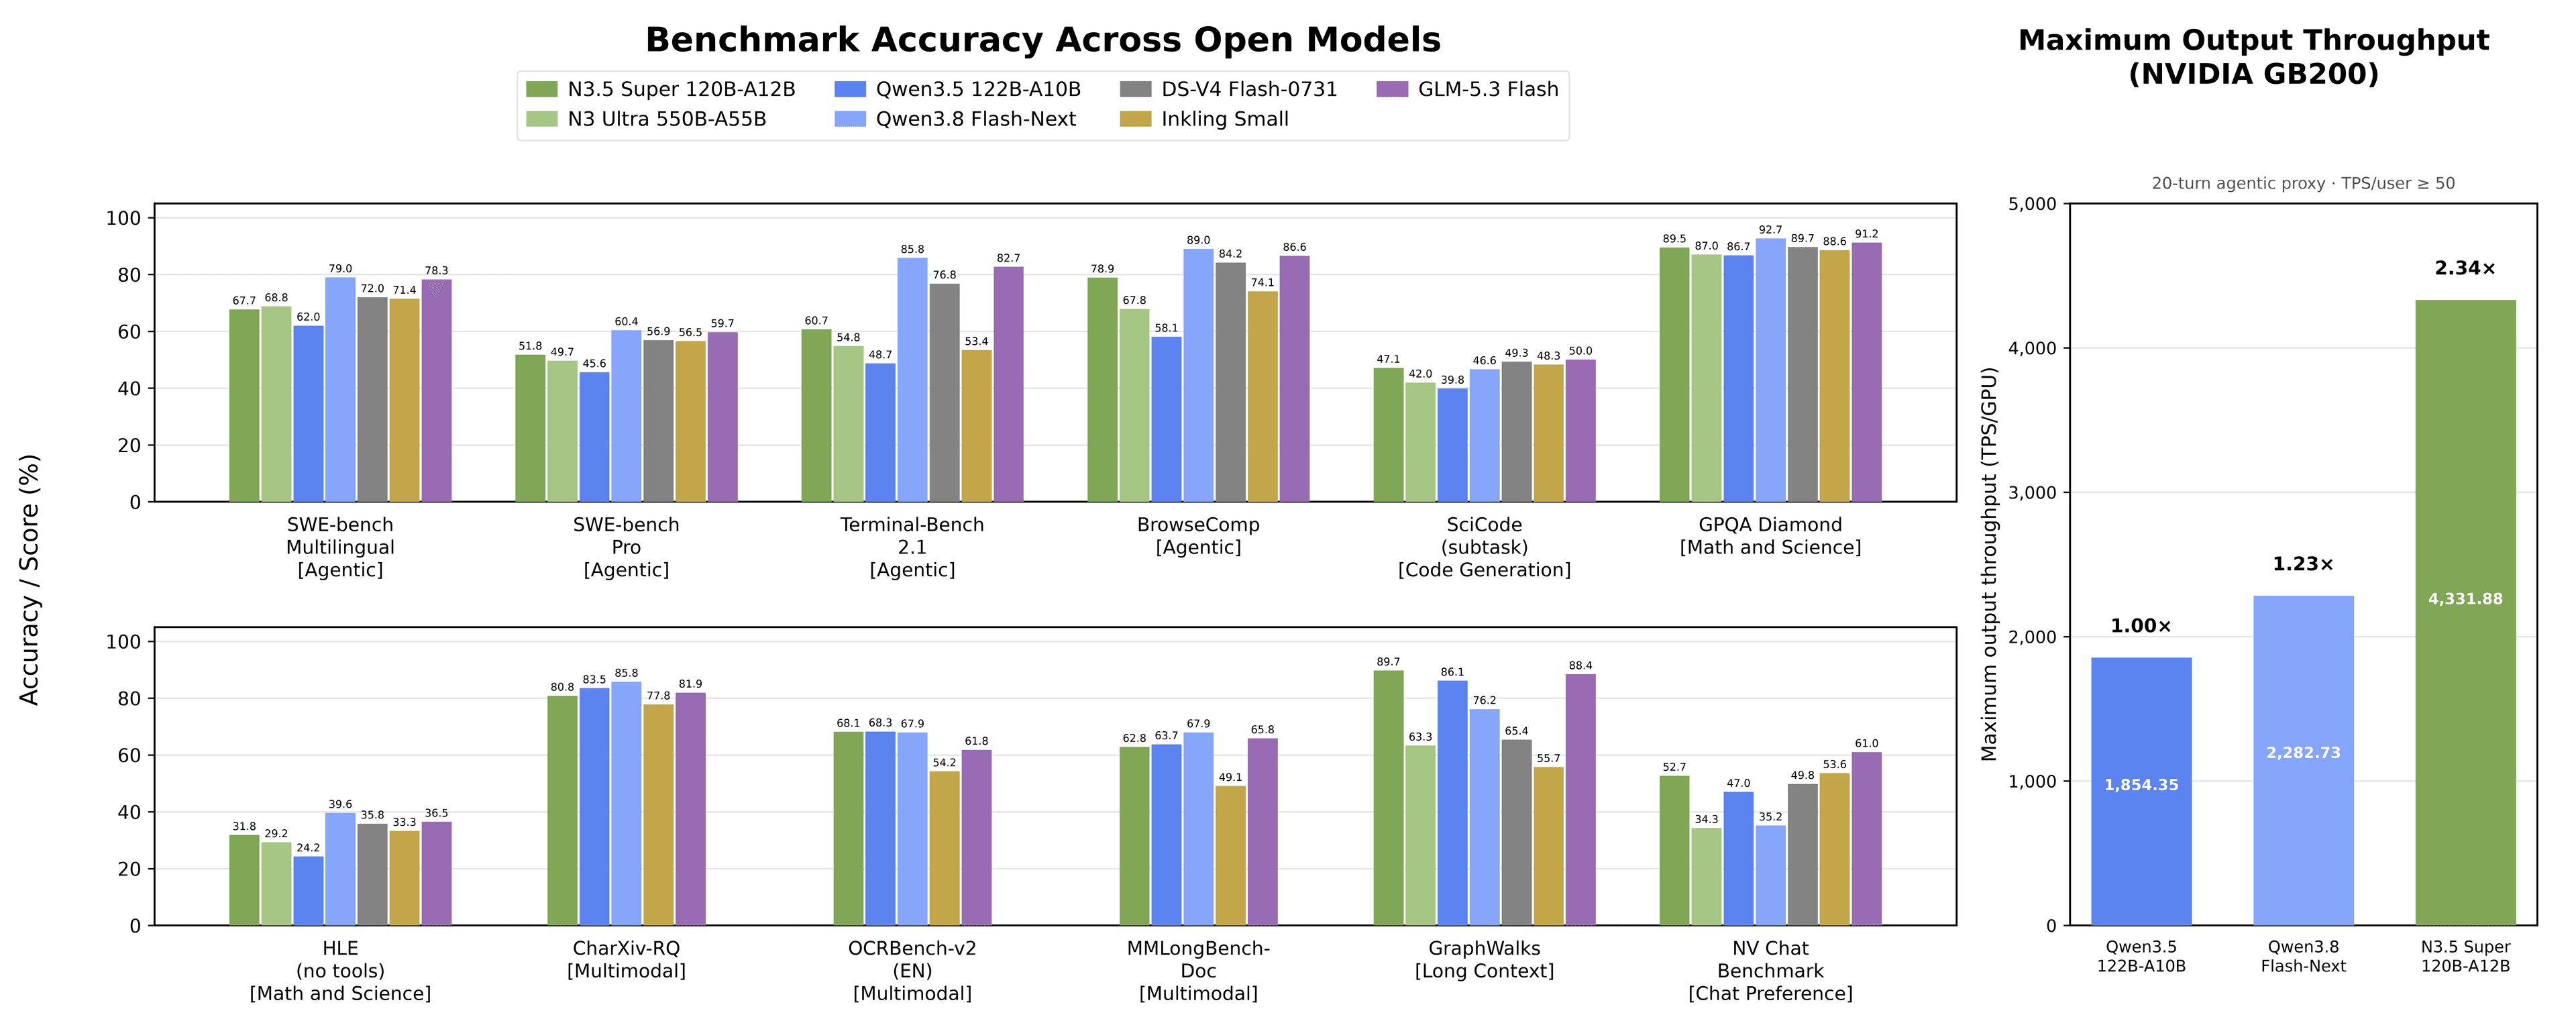
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Speech → Text
All Speech → Text →IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
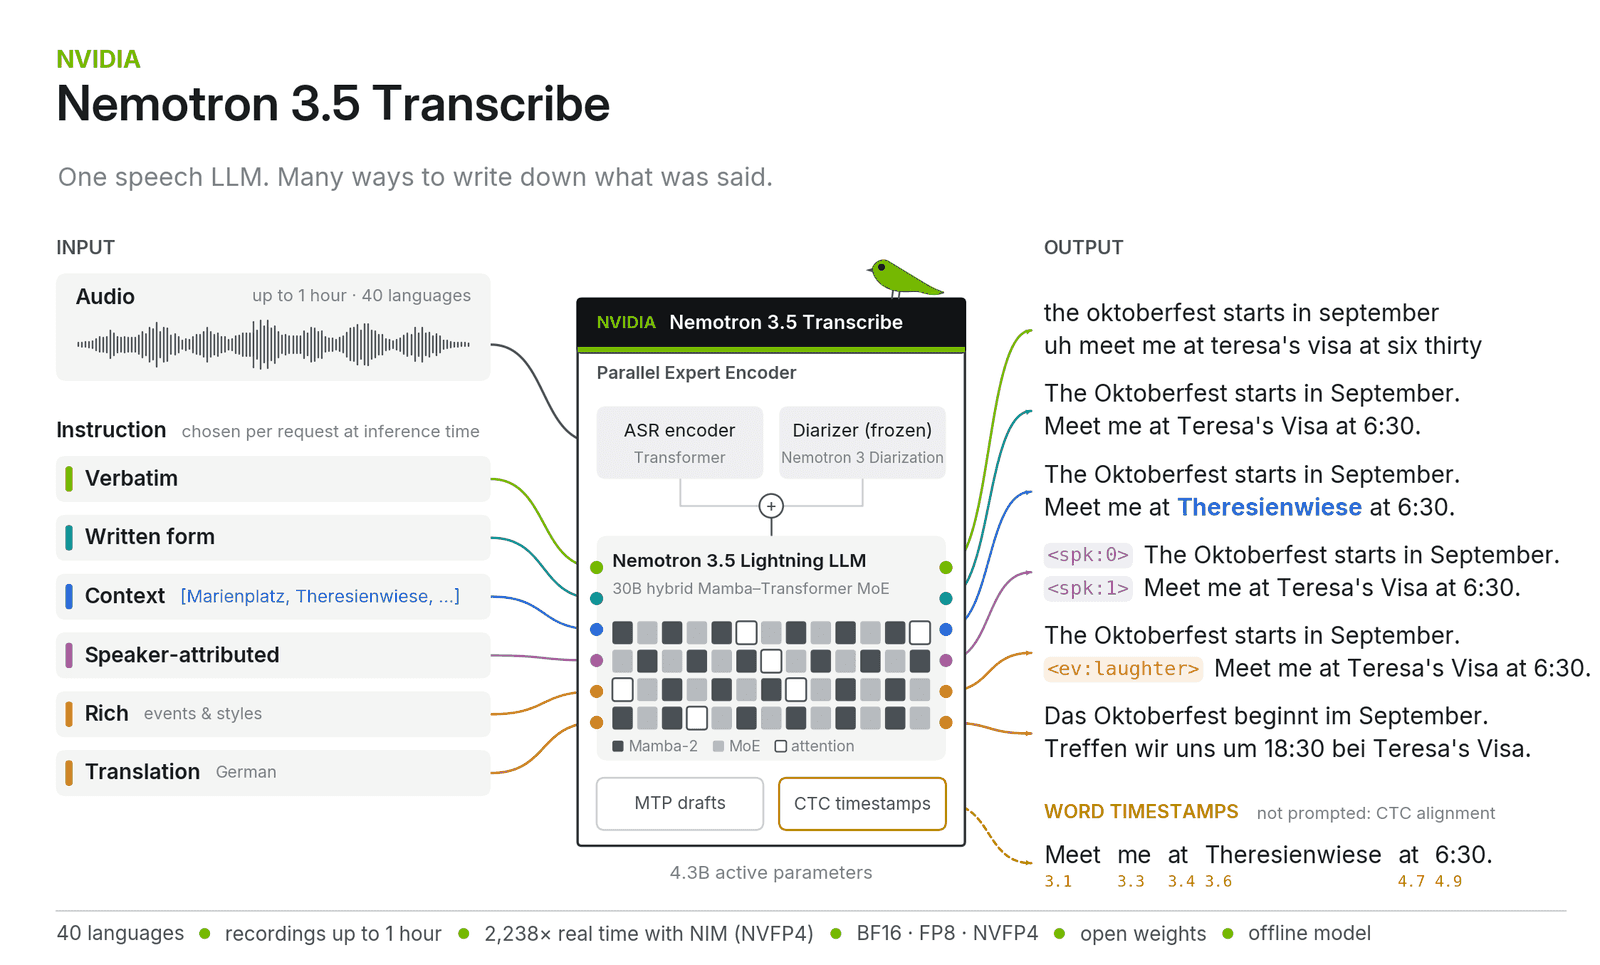
NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR
A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.
0 comments
No comments yet. Be the first to weigh in.