NVIDIA Releases Efficient Nemotron-3 Multimodal MoE
The new 30-billion parameter Mixture-of-Experts model handles text and images while using only 3 billion active parameters for inference.

NVIDIA has released Nemotron-3 Nano Omni, a new multimodal model designed for complex reasoning tasks. The model continues the company's expansion into open AI, offering a sophisticated tool capable of understanding and processing both text and visual information.
The key innovation in Nemotron-3 Nano Omni is its efficient architecture. It's a Mixture-of-Experts (MoE) model with a total of 30 billion parameters, but it only activates a fraction of them—just 3 billion—for any given task. This design significantly reduces the computational cost of inference compared to a traditional dense model of the same size, a focus highlighted by the "Nano" in its name.
As a Vision-Language Model (VLM), Nemotron-3 Nano Omni can perform tasks that require a simultaneous understanding of images and language. This makes it suitable for applications like detailed image captioning, visual question answering, and other reasoning challenges that depend on integrating visual context with textual prompts.
Developers can access the model, optimized in the NVFP4 format, on the Hugging Face Hub. It is available under the Nvidia Open Model License, a custom license that users should review before integrating it into their projects. This release provides a powerful, resource-conscious option for teams building multimodal AI applications.
Sources
- Visit
nvidia/Nemotron-3-Nano-Omni-30B-A3B-Reasoning-NVFP4
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
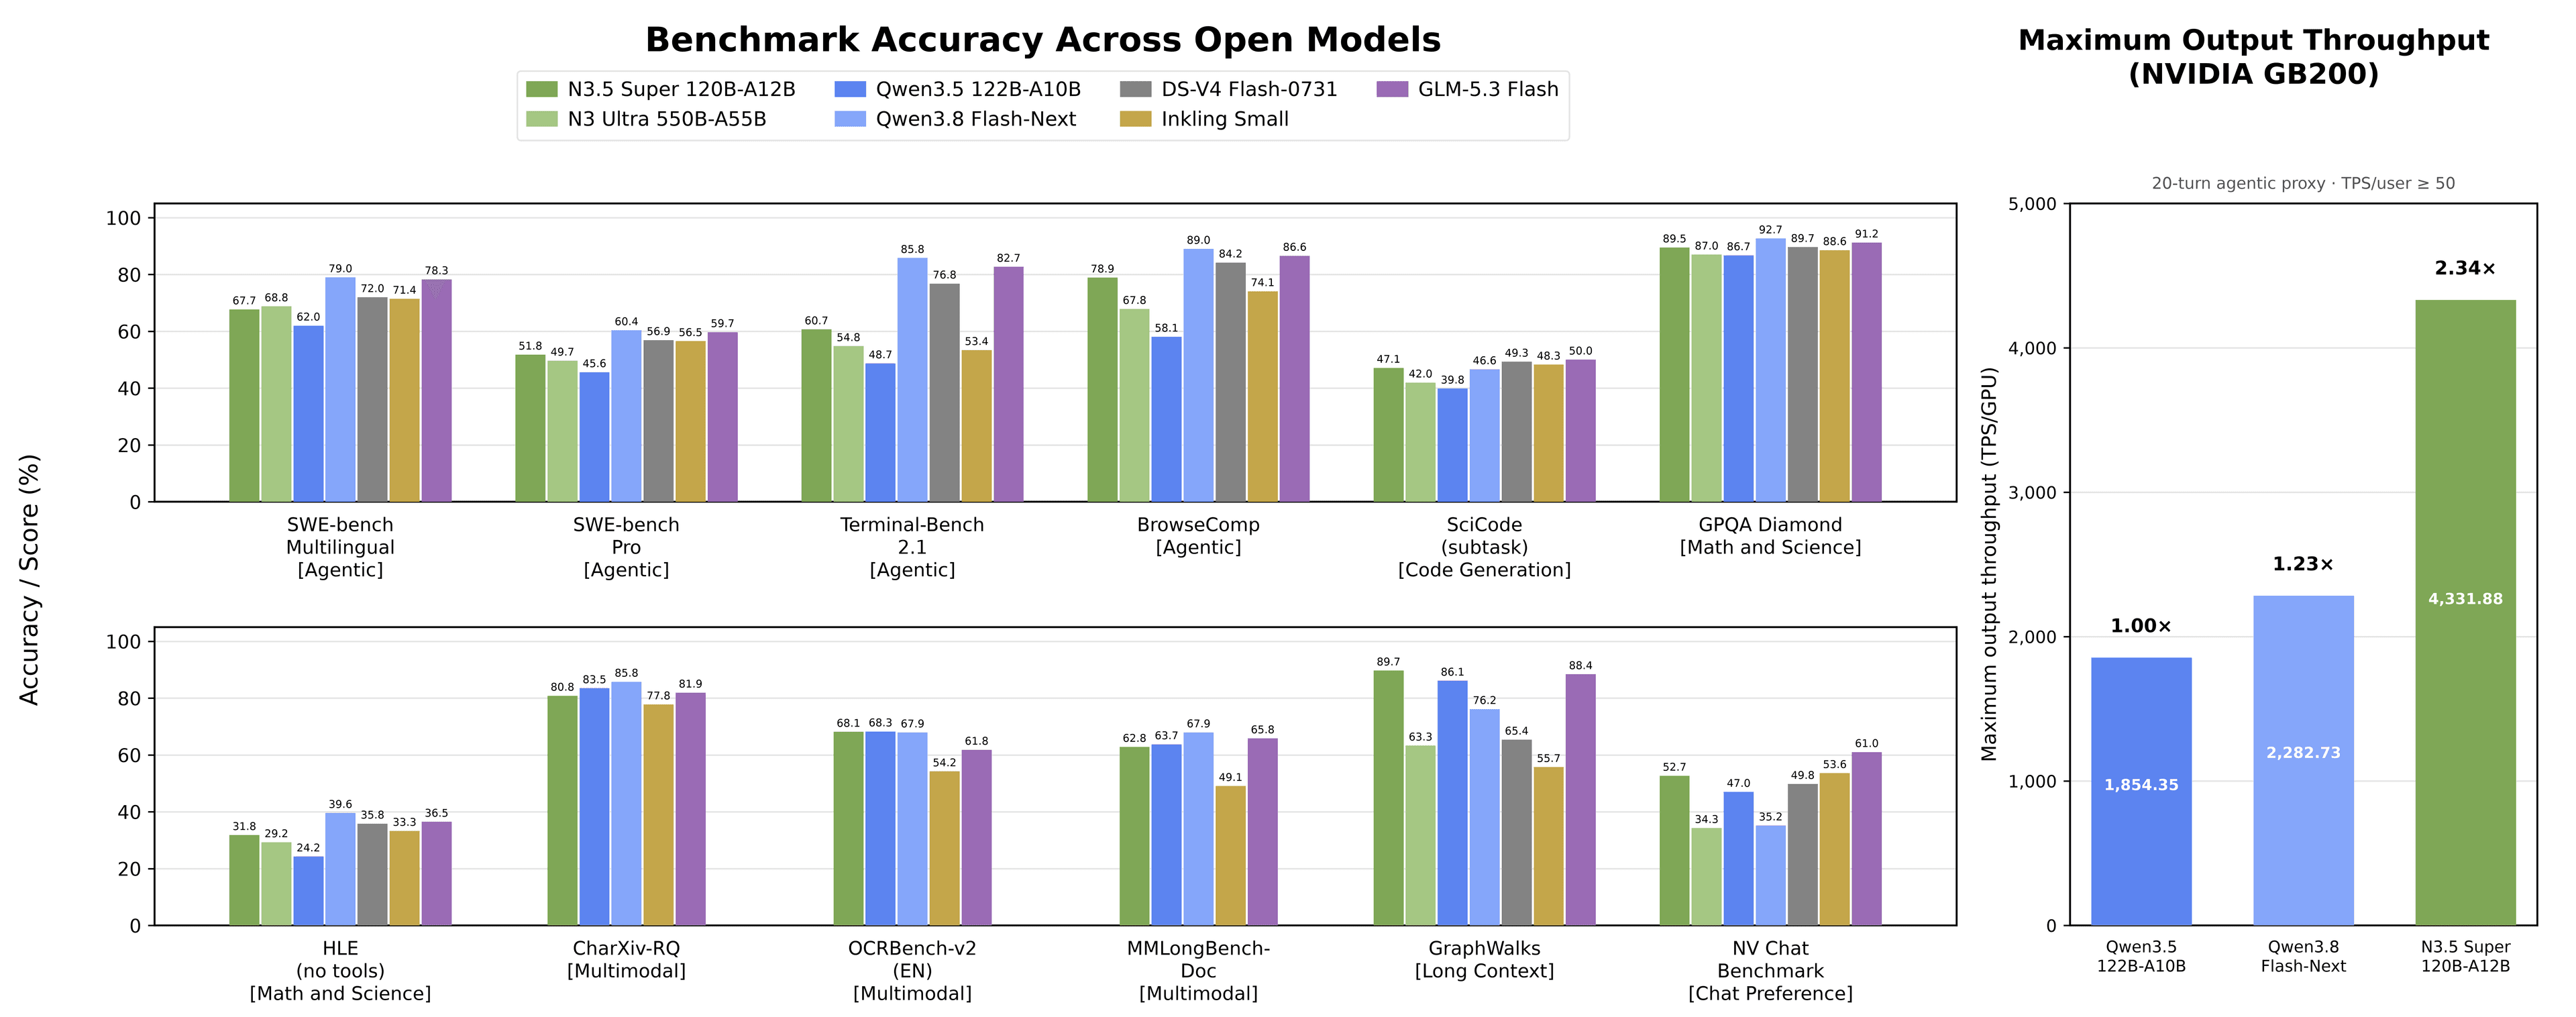
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
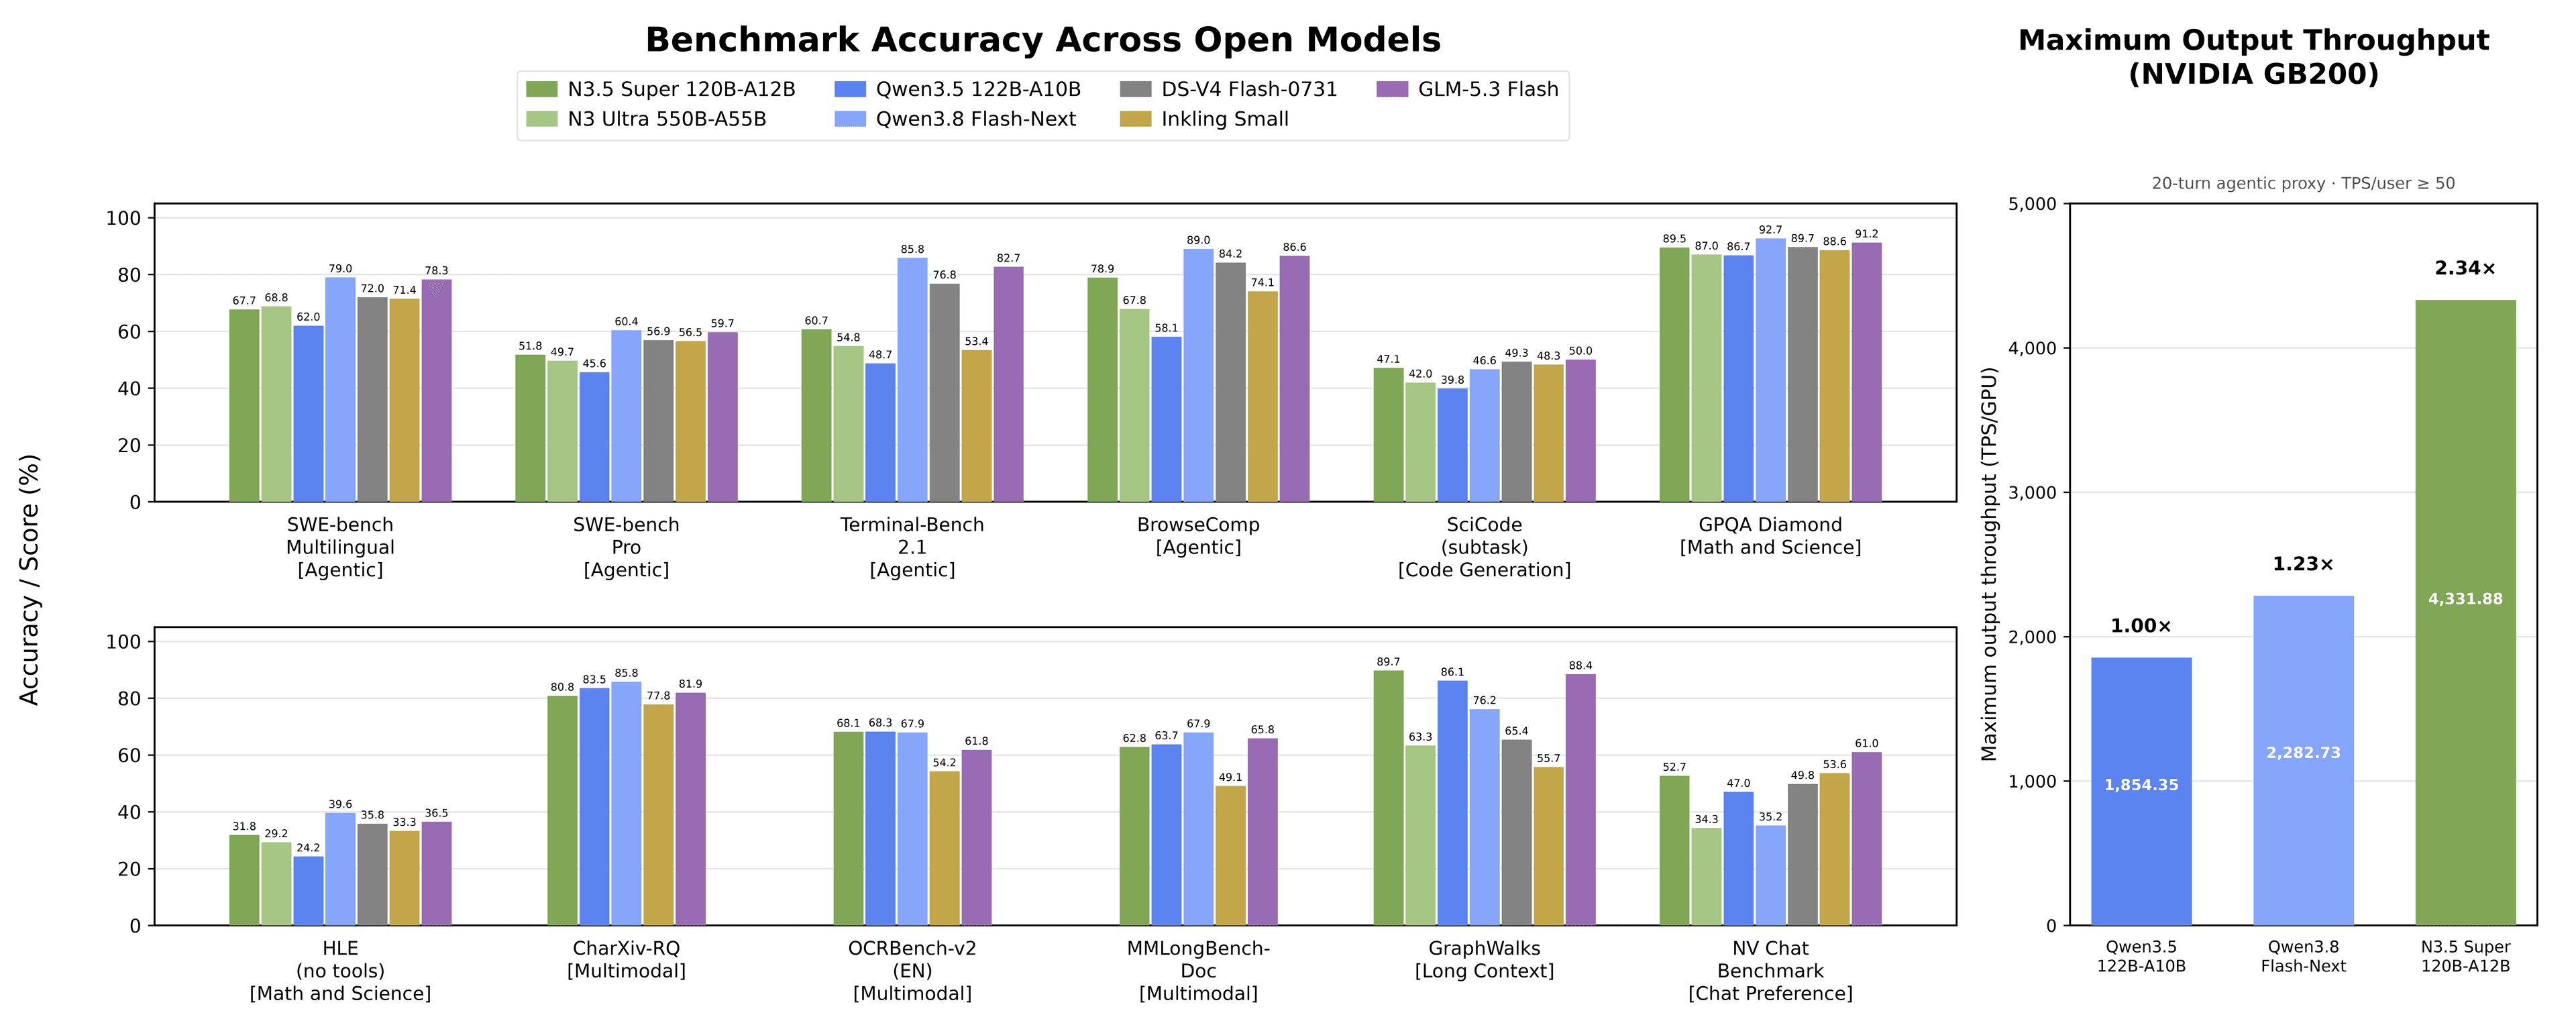
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.