NVIDIA's Nemotron-3 Puzzle Brings a Lean MoE to Reasoning
The 75B-parameter model activates just 9B per token and ships in NVIDIA's NVFP4 format for efficient inference.

NVIDIA has released Nemotron-3 Puzzle 75B-A9B, a mixture-of-experts language model aimed at text generation and reasoning. Despite carrying 75 billion total parameters, the model activates only about 9 billion per token, a design meant to deliver the capacity of a large model at a fraction of the per-inference cost. The weights are available now on Hugging Face.
The release ships in NVIDIA's NVFP4 format, a 4-bit floating-point quantization scheme tuned for the company's own accelerators. That, combined with multi-token prediction (MTP), signals a focus on throughput: MTP lets the model draft several tokens per forward pass, which can meaningfully speed up decoding when paired with the right serving stack.
Why it matters
Sparse activation has become the dominant playbook for scaling open models without scaling inference bills, and Nemotron-3 Puzzle leans into that trend hard. Its 9B active footprint puts it in reach of more modest hardware budgets than its 75B headline size would suggest.
- Latent-MoE architecture with 75B total and 9B active parameters
- Multi-token prediction for faster decoding
- NVFP4 quantization optimized for NVIDIA hardware
- Positioned for text and reasoning workloads
A few details remain unstated in the initial listing, including context length and the specifics of NVIDIA's licensing terms, both marked as "other" pending further documentation. As with prior Nemotron drops, the practical draw will be how the efficiency claims hold up under real serving conditions, and whether the reasoning performance justifies the architecture's added complexity.
Sources
- Visit
nvidia/NVIDIA-Nemotron-Labs-3-Puzzle-75B-A9B-NVFP4
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
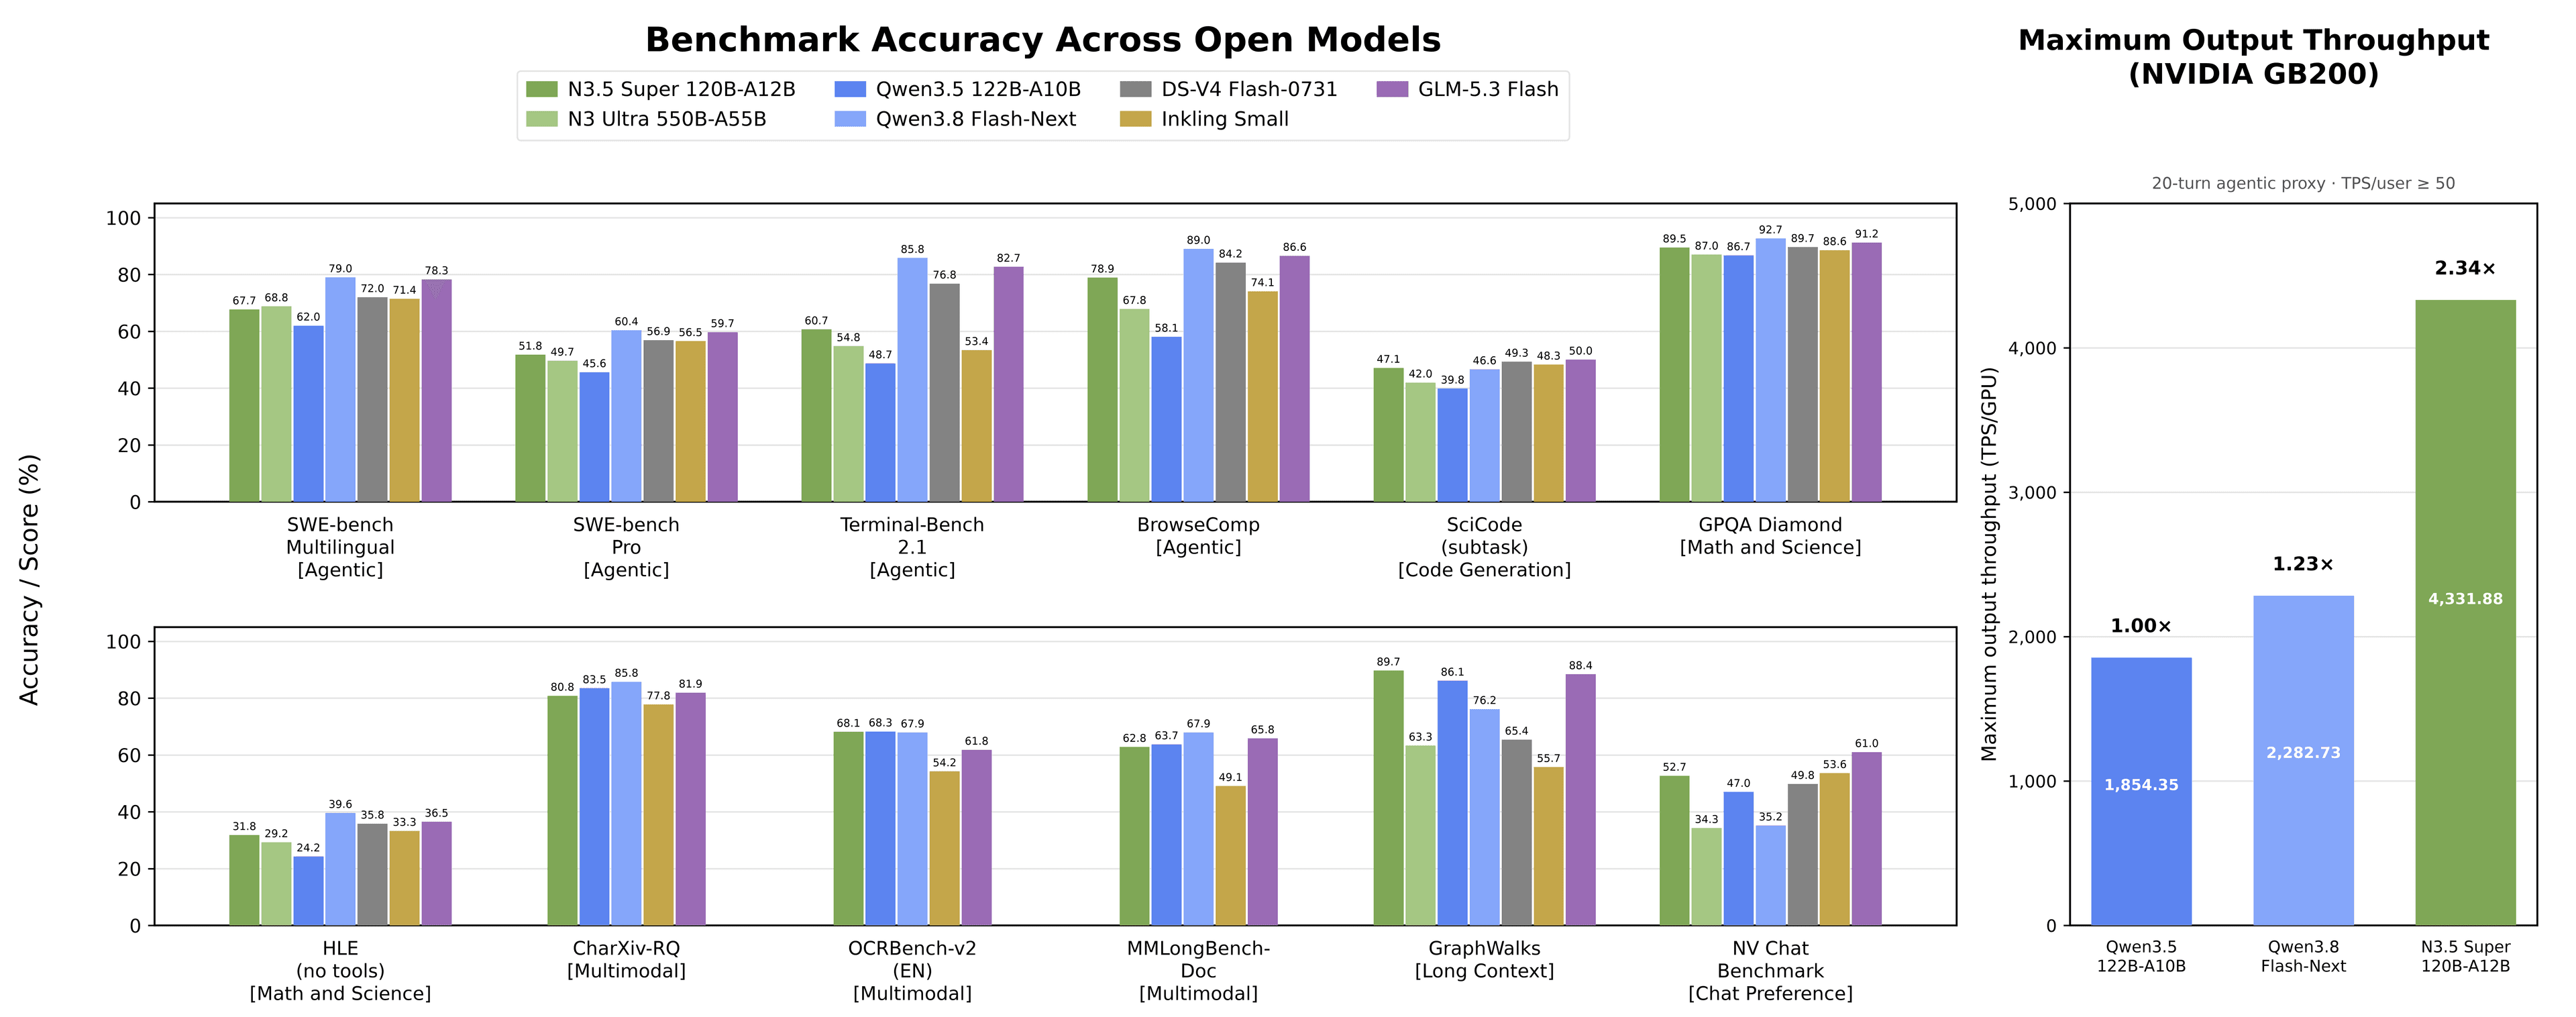
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
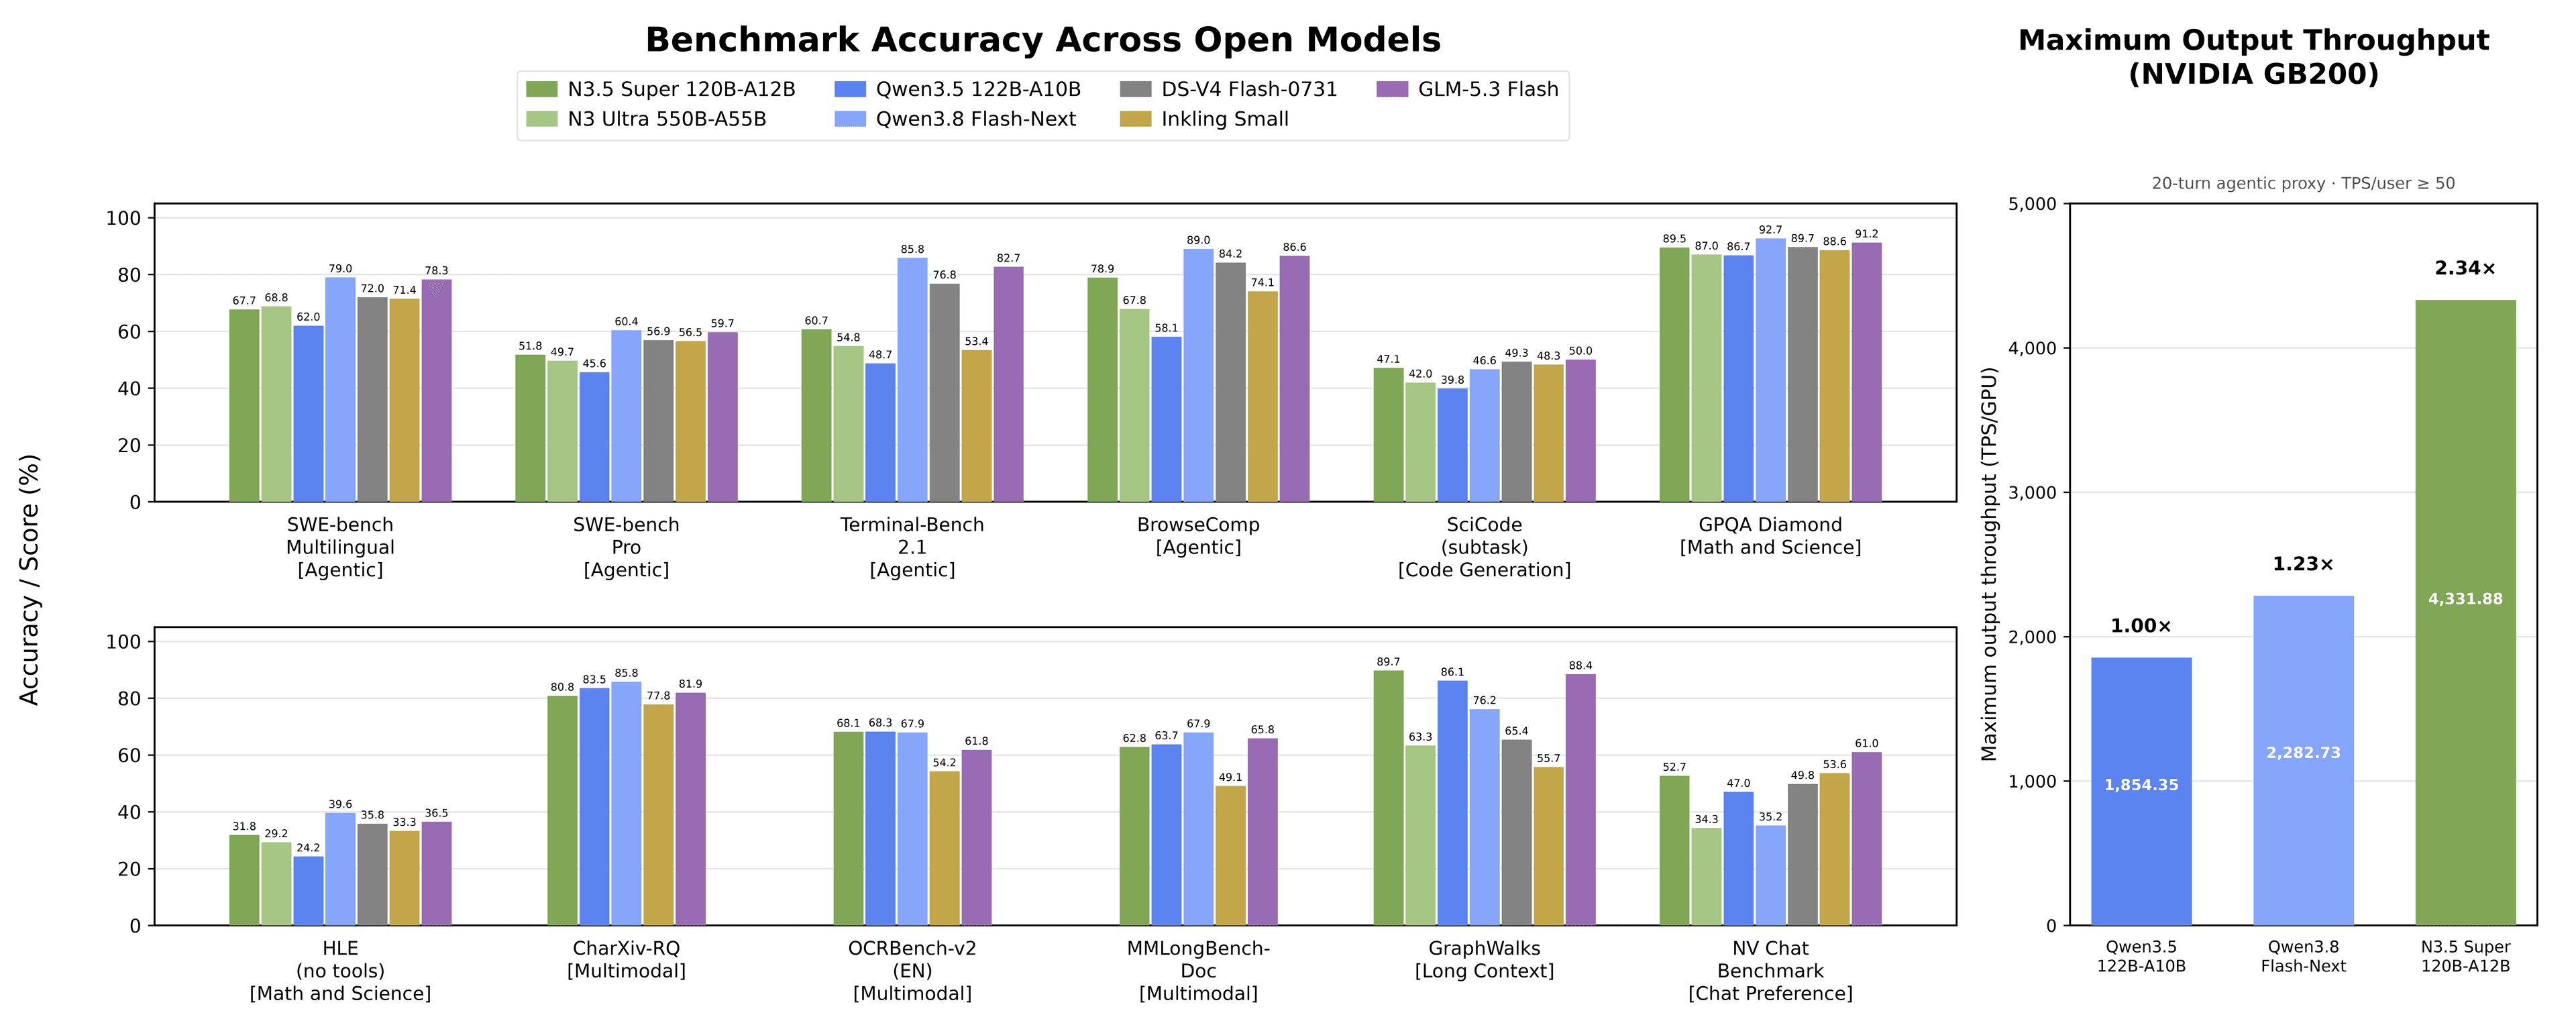
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.