NVIDIA's Nemotron 3 Puzzle Runs Big on a Lean Budget
A 75-billion-parameter mixture-of-experts reasoning model that activates just 9 billion parameters per token.

NVIDIA has published Nemotron-Labs-3-Puzzle-75B-A9B, a new open-weight reasoning model that leans on a sparse mixture-of-experts design to keep inference costs down. The model carries 75 billion total parameters but activates only about 9 billion per token, according to its Hugging Face repository. The weights are distributed in BF16.
Why it matters
The appeal of a latent-MoE layout is straightforward: you get the knowledge capacity of a large model without paying to run all of it at once. That trade-off has become a common thread across recent open releases, and Nemotron 3 Puzzle slots into that trend by targeting reasoning workloads specifically, where a slimmer active footprint can translate into faster, cheaper chains of thought.
A few things stand out from the release:
- Total vs. active split: 75B parameters on disk, roughly 9B engaged per token.
- Reasoning focus: the model is tagged for text generation and reasoning tasks.
- BF16 weights: shipped in a format suited to modern accelerators.
NVIDIA has been steadily expanding its Nemotron line, and this "Puzzle" variant signals continued investment in sparse architectures aimed at reasoning rather than raw scale. The company has not published a context length for this checkpoint, and the license is listed as a custom NVIDIA agreement, so teams should read the terms before building on it.
For developers weighing open models, the pitch here is efficiency: a large knowledge base that behaves, at runtime, like something much smaller. Full details and the model card are available on Hugging Face.
Sources
- Visit
nvidia/NVIDIA-Nemotron-Labs-3-Puzzle-75B-A9B-BF16
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
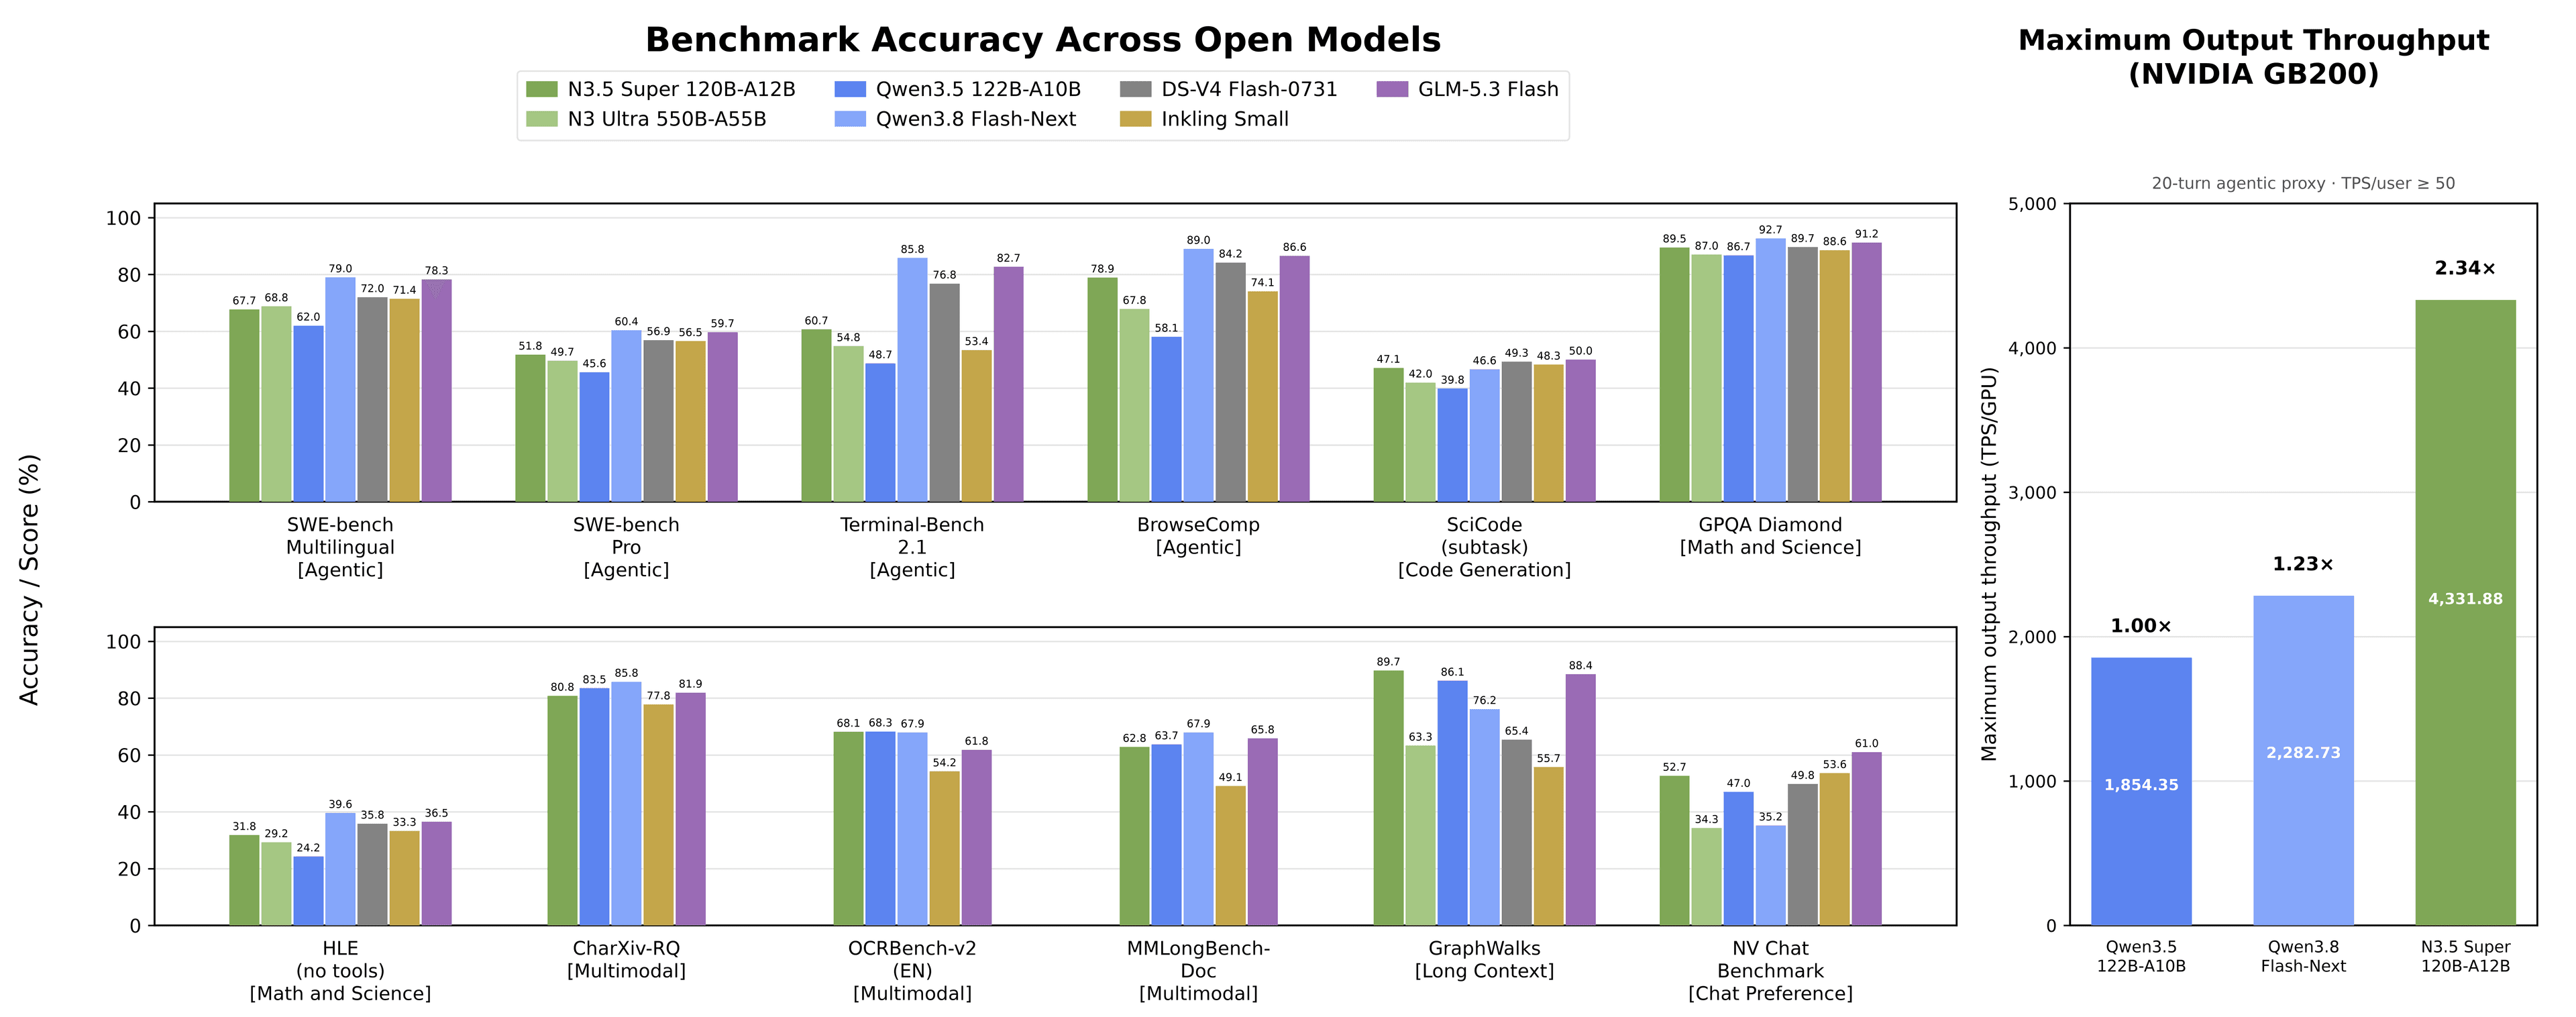
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
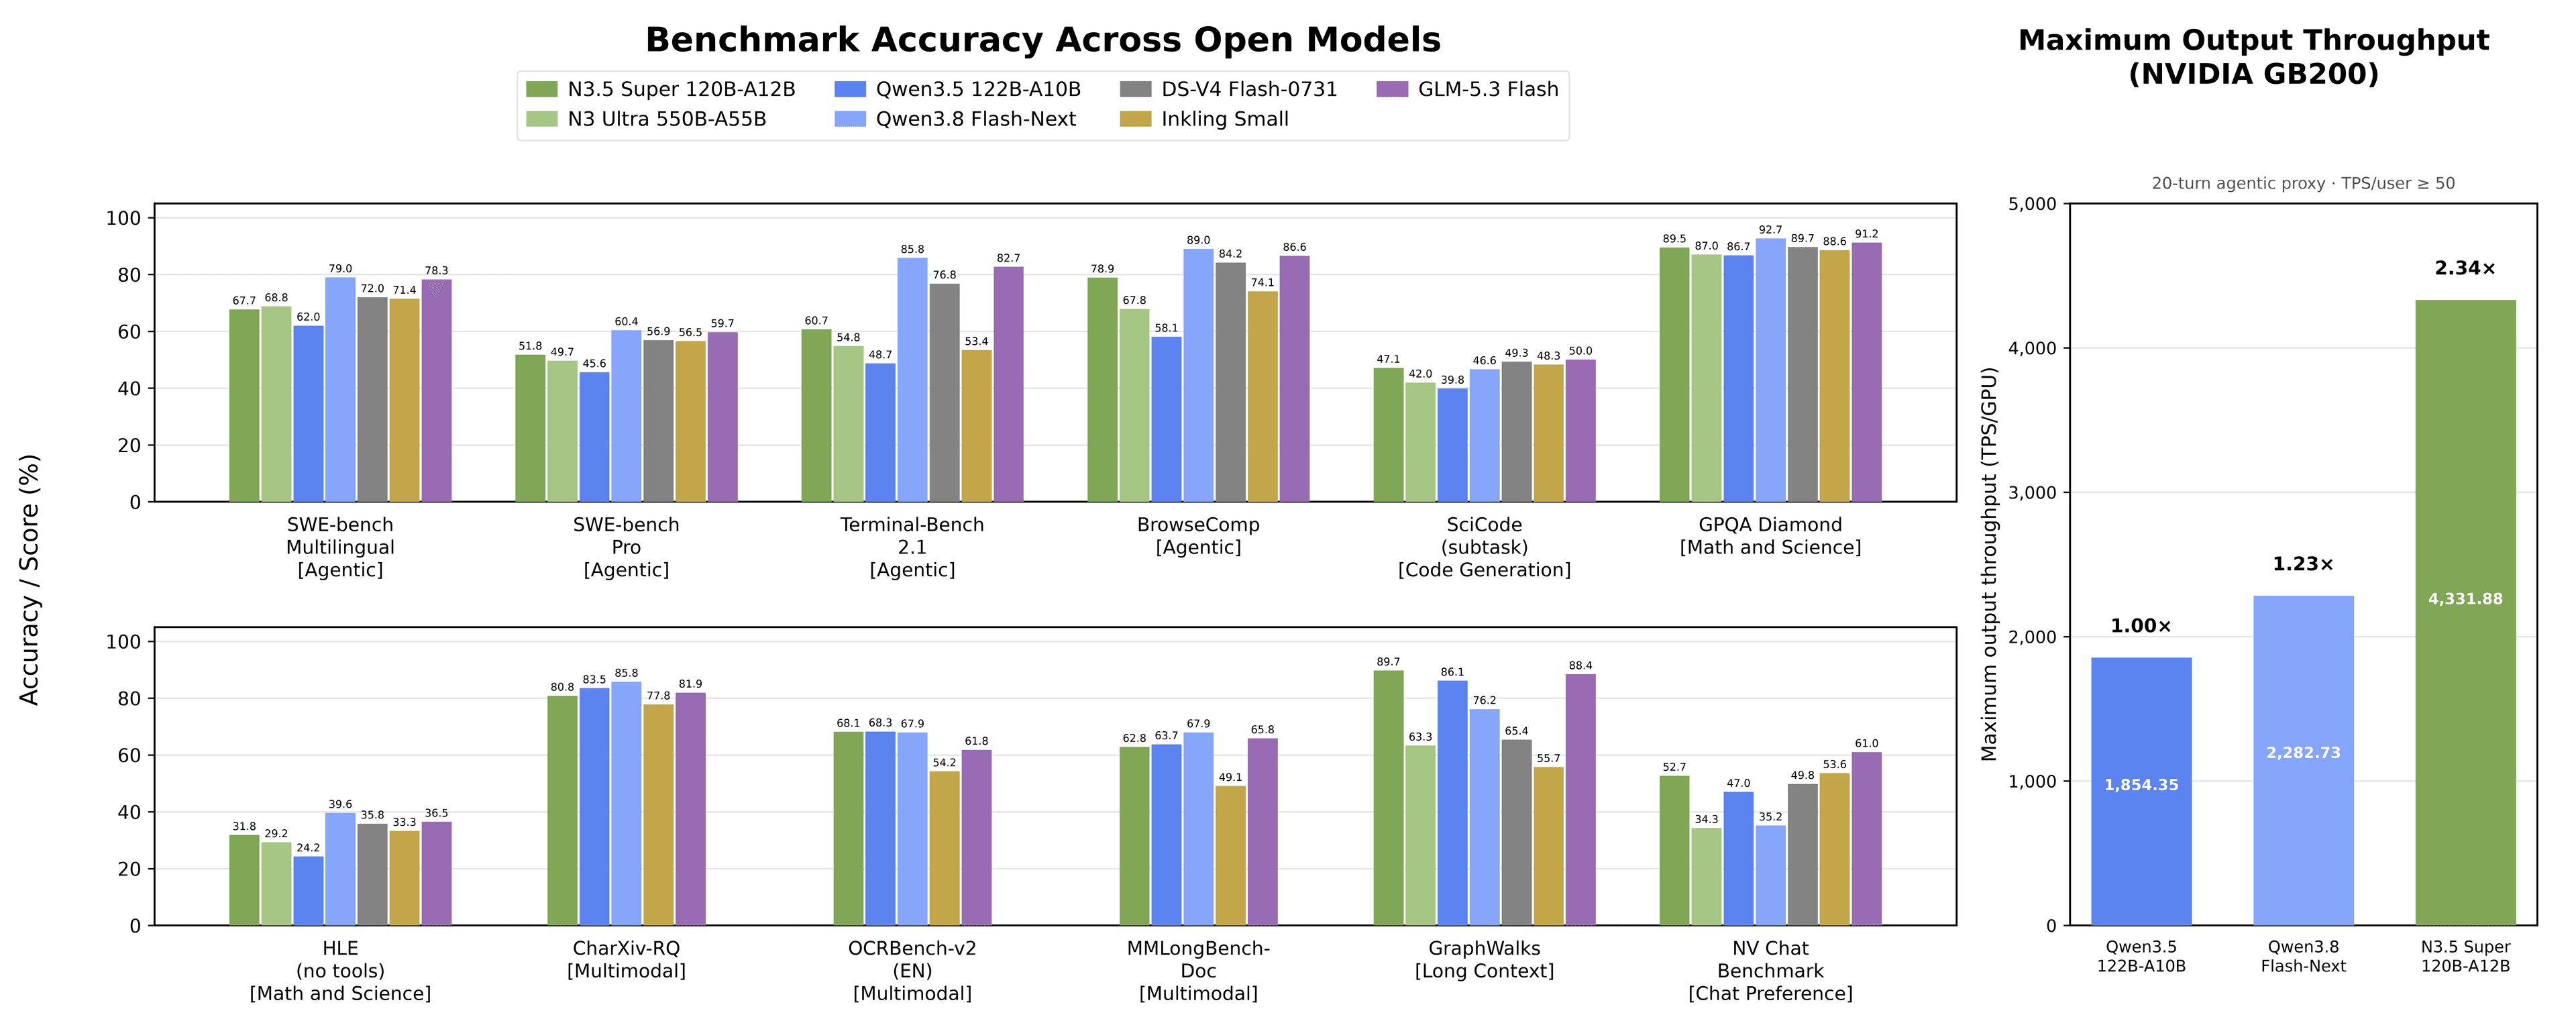
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.