NVIDIA's New 3B VLM Pinpoints Objects in Images
The new 3-billion-parameter model, based on the company's Eagle architecture, is designed for high-precision visual grounding tasks.
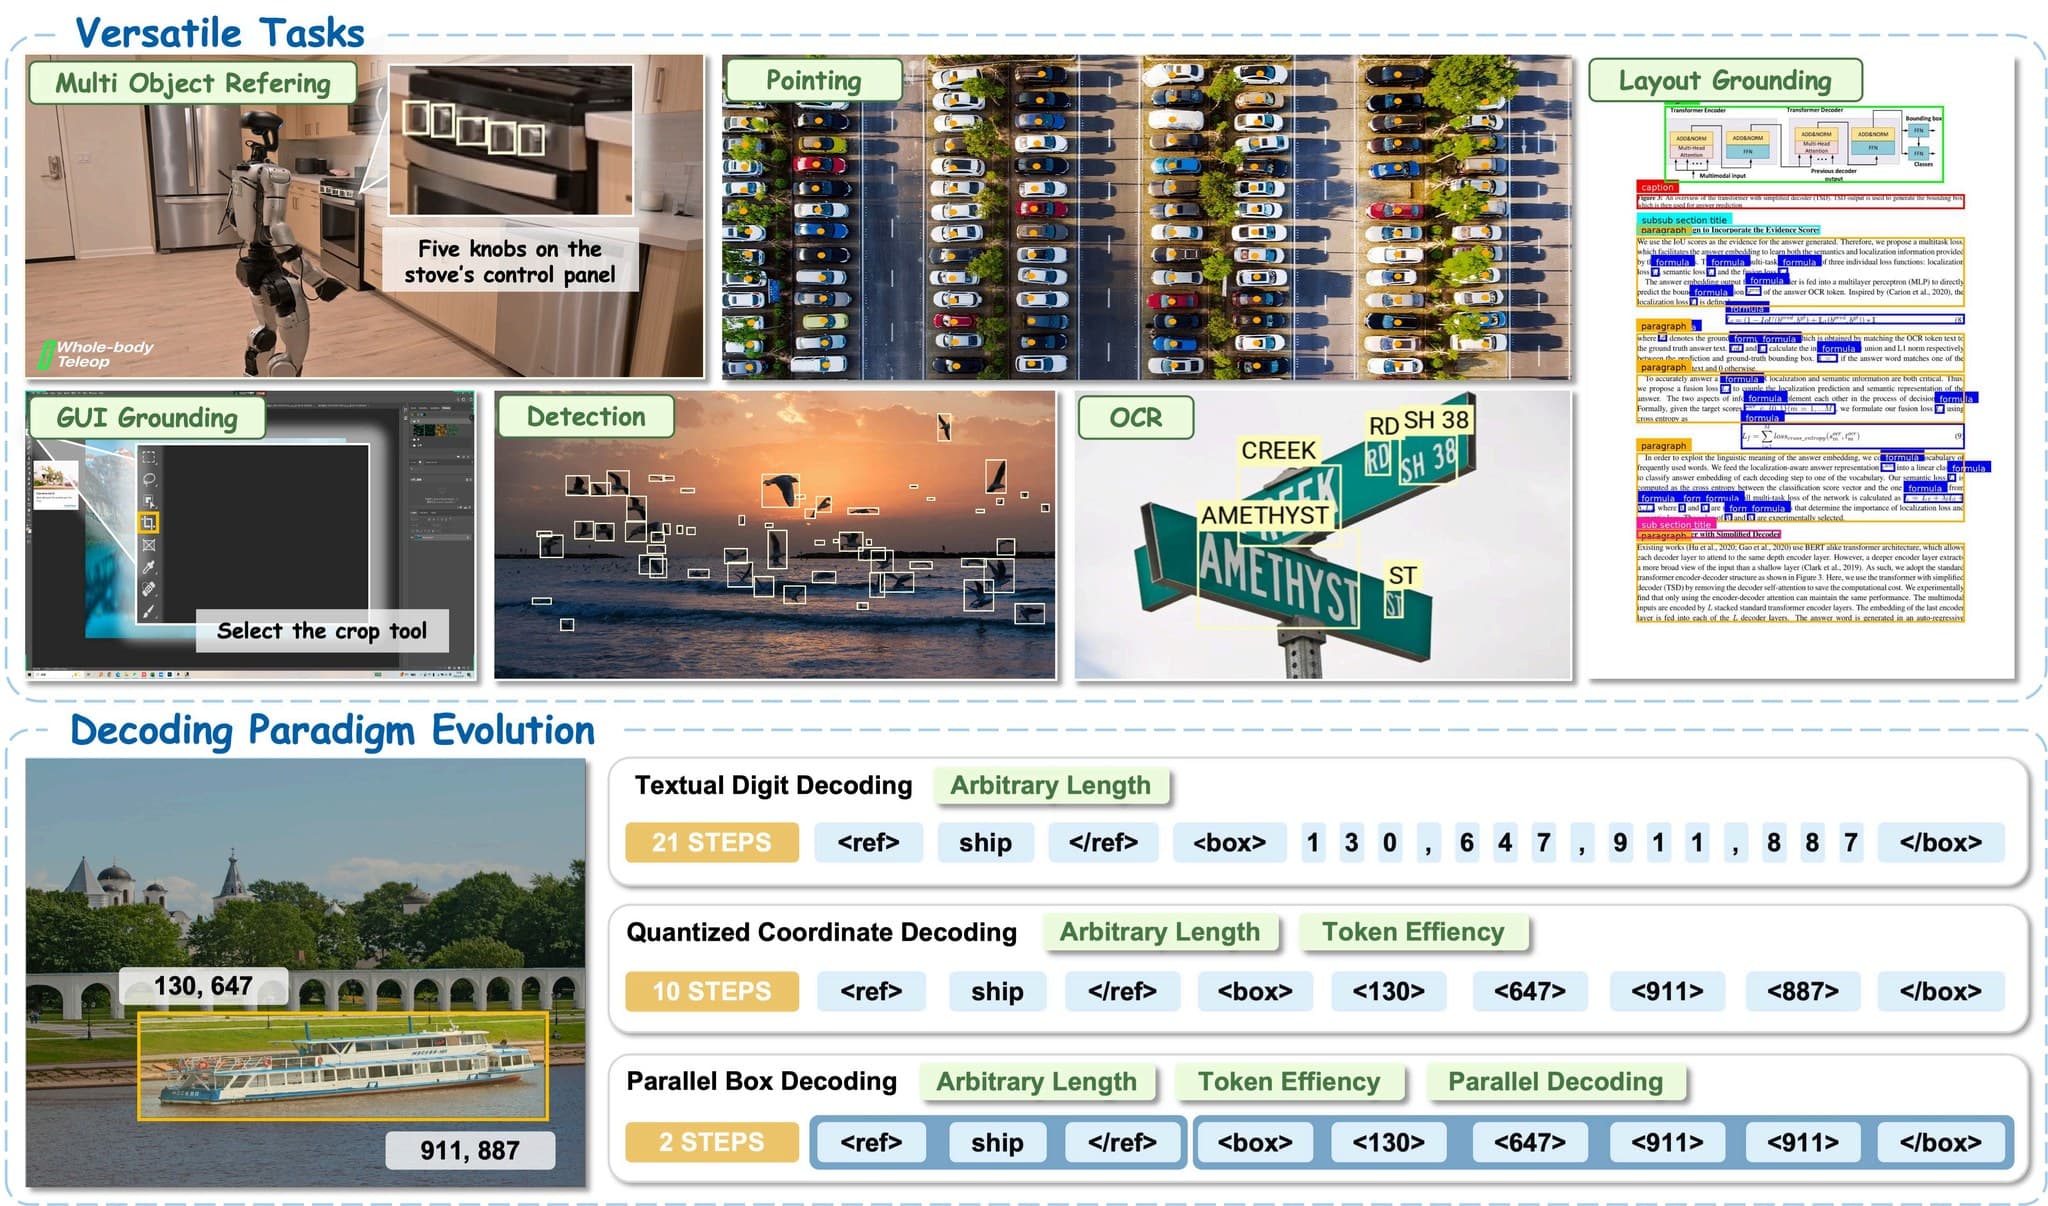
NVIDIA has introduced LocateAnything-3B, a new vision-language model designed to precisely identify and outline objects in an image based on a text prompt. This specialized 3-billion-parameter model excels at visual grounding, which connects natural language descriptions to specific pixel regions in a picture.
Built upon the foundation of NVIDIA's Eagle architecture, LocateAnything-3B combines a powerful vision encoder with a language model. This dual structure enables it to interpret complex visual scenes and understand user queries to answer the question, "Where is the object I'm describing?" with a high degree of accuracy.
Potential Applications
The ability to precisely locate objects opens up possibilities for a range of applications. Key use cases for this technology include:
- Interactive Photo Editing: Allowing users to select complex objects with simple text commands like "select the red sports car."
- Robotics and Automation: Providing visual intelligence for robots to identify and interact with specific items in their environment.
- Accessibility Tools: Enhancing systems that describe image content for visually impaired users by specifying where objects are located.
The model and its weights are now available on the Hugging Face Hub. According to its model card, LocateAnything-3B is released for non-commercial research purposes only, an important consideration for developers exploring its capabilities.
Sources
- Visit
nvidia/LocateAnything-3B
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
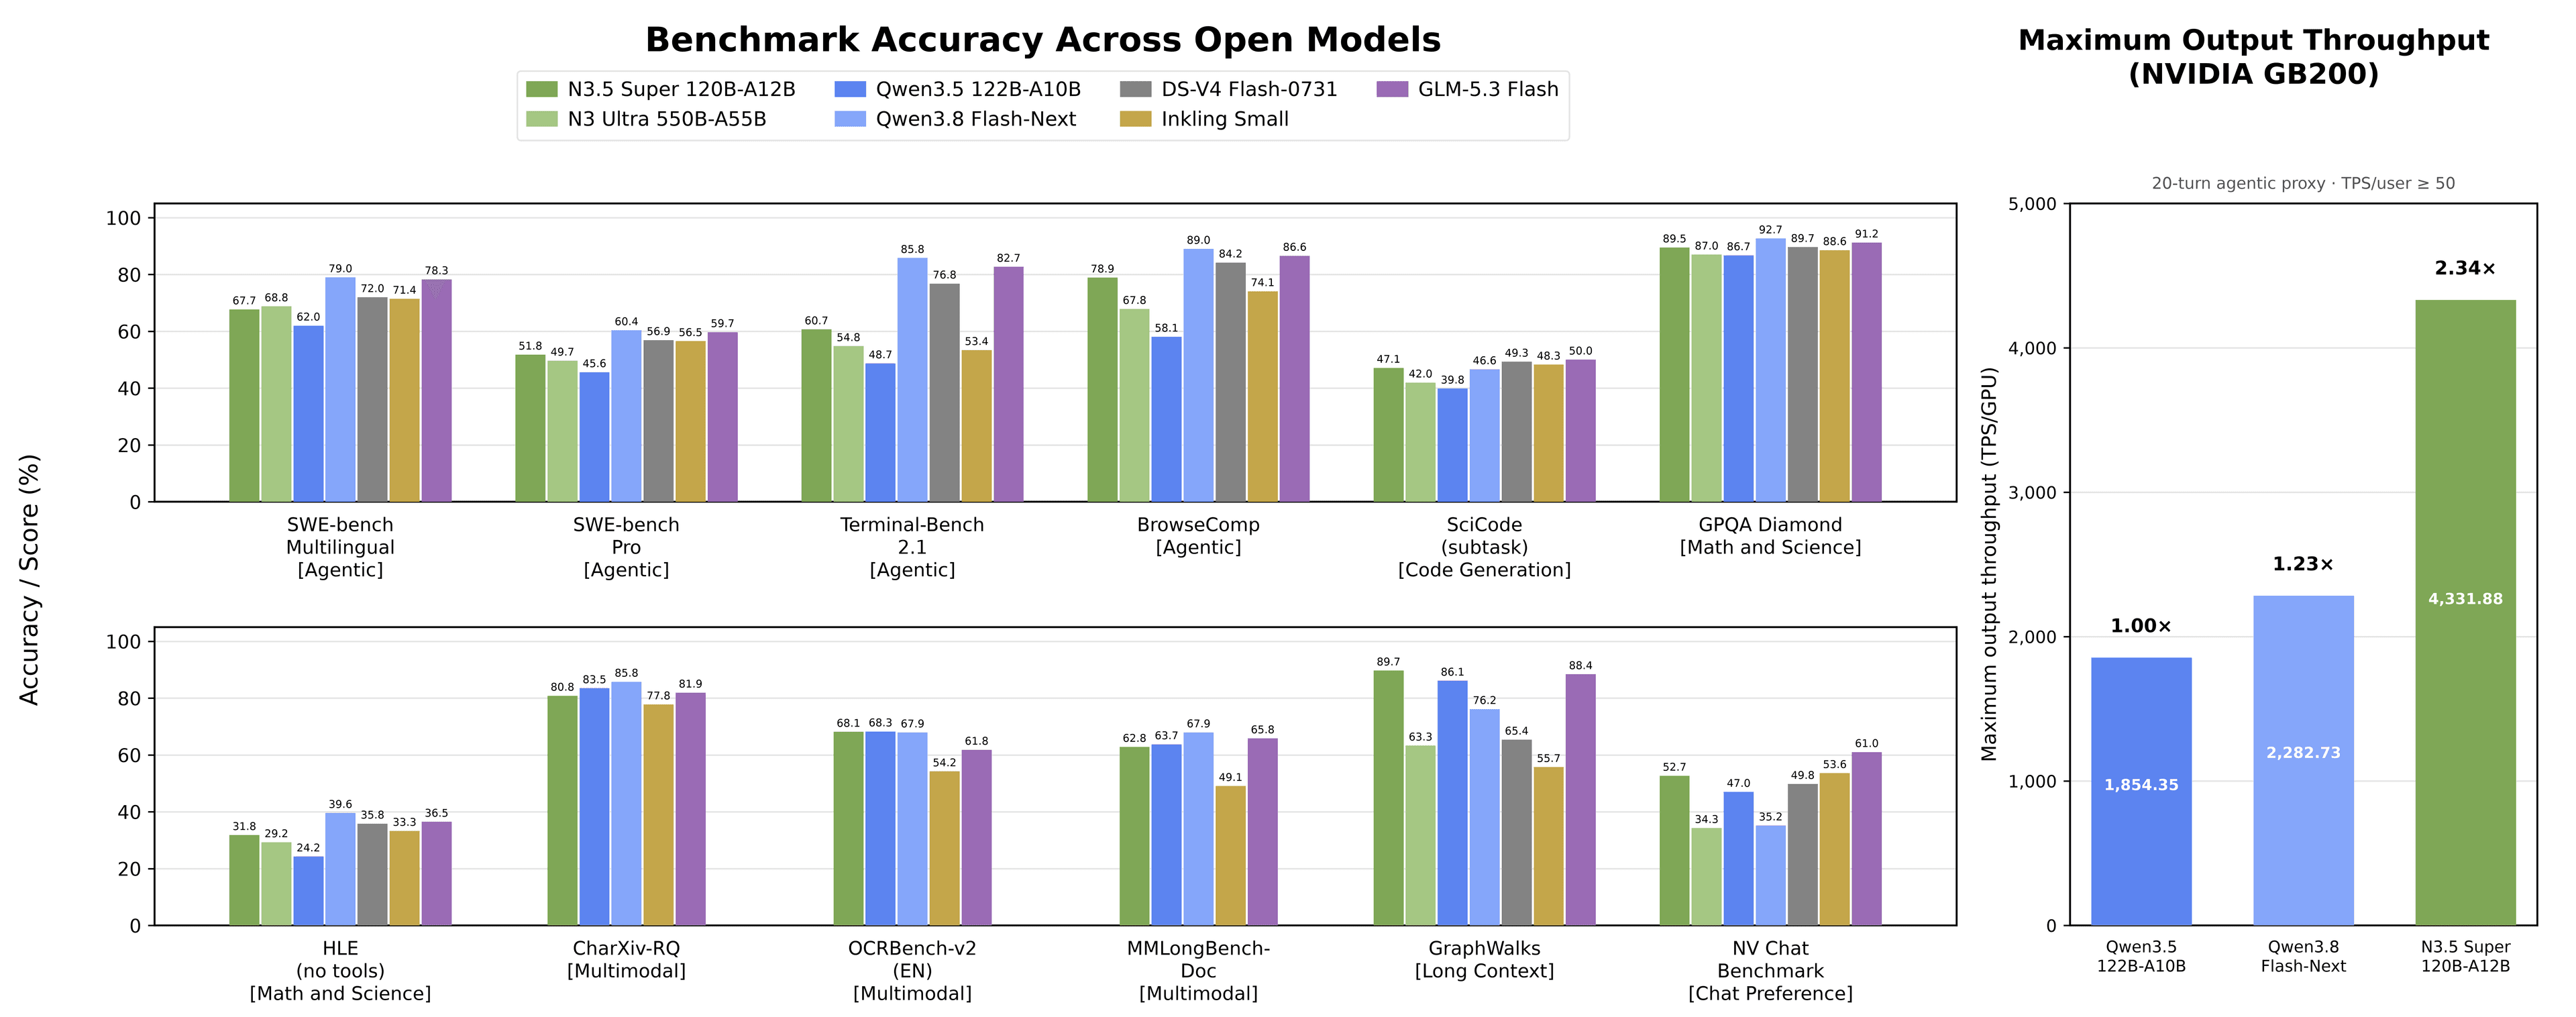
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
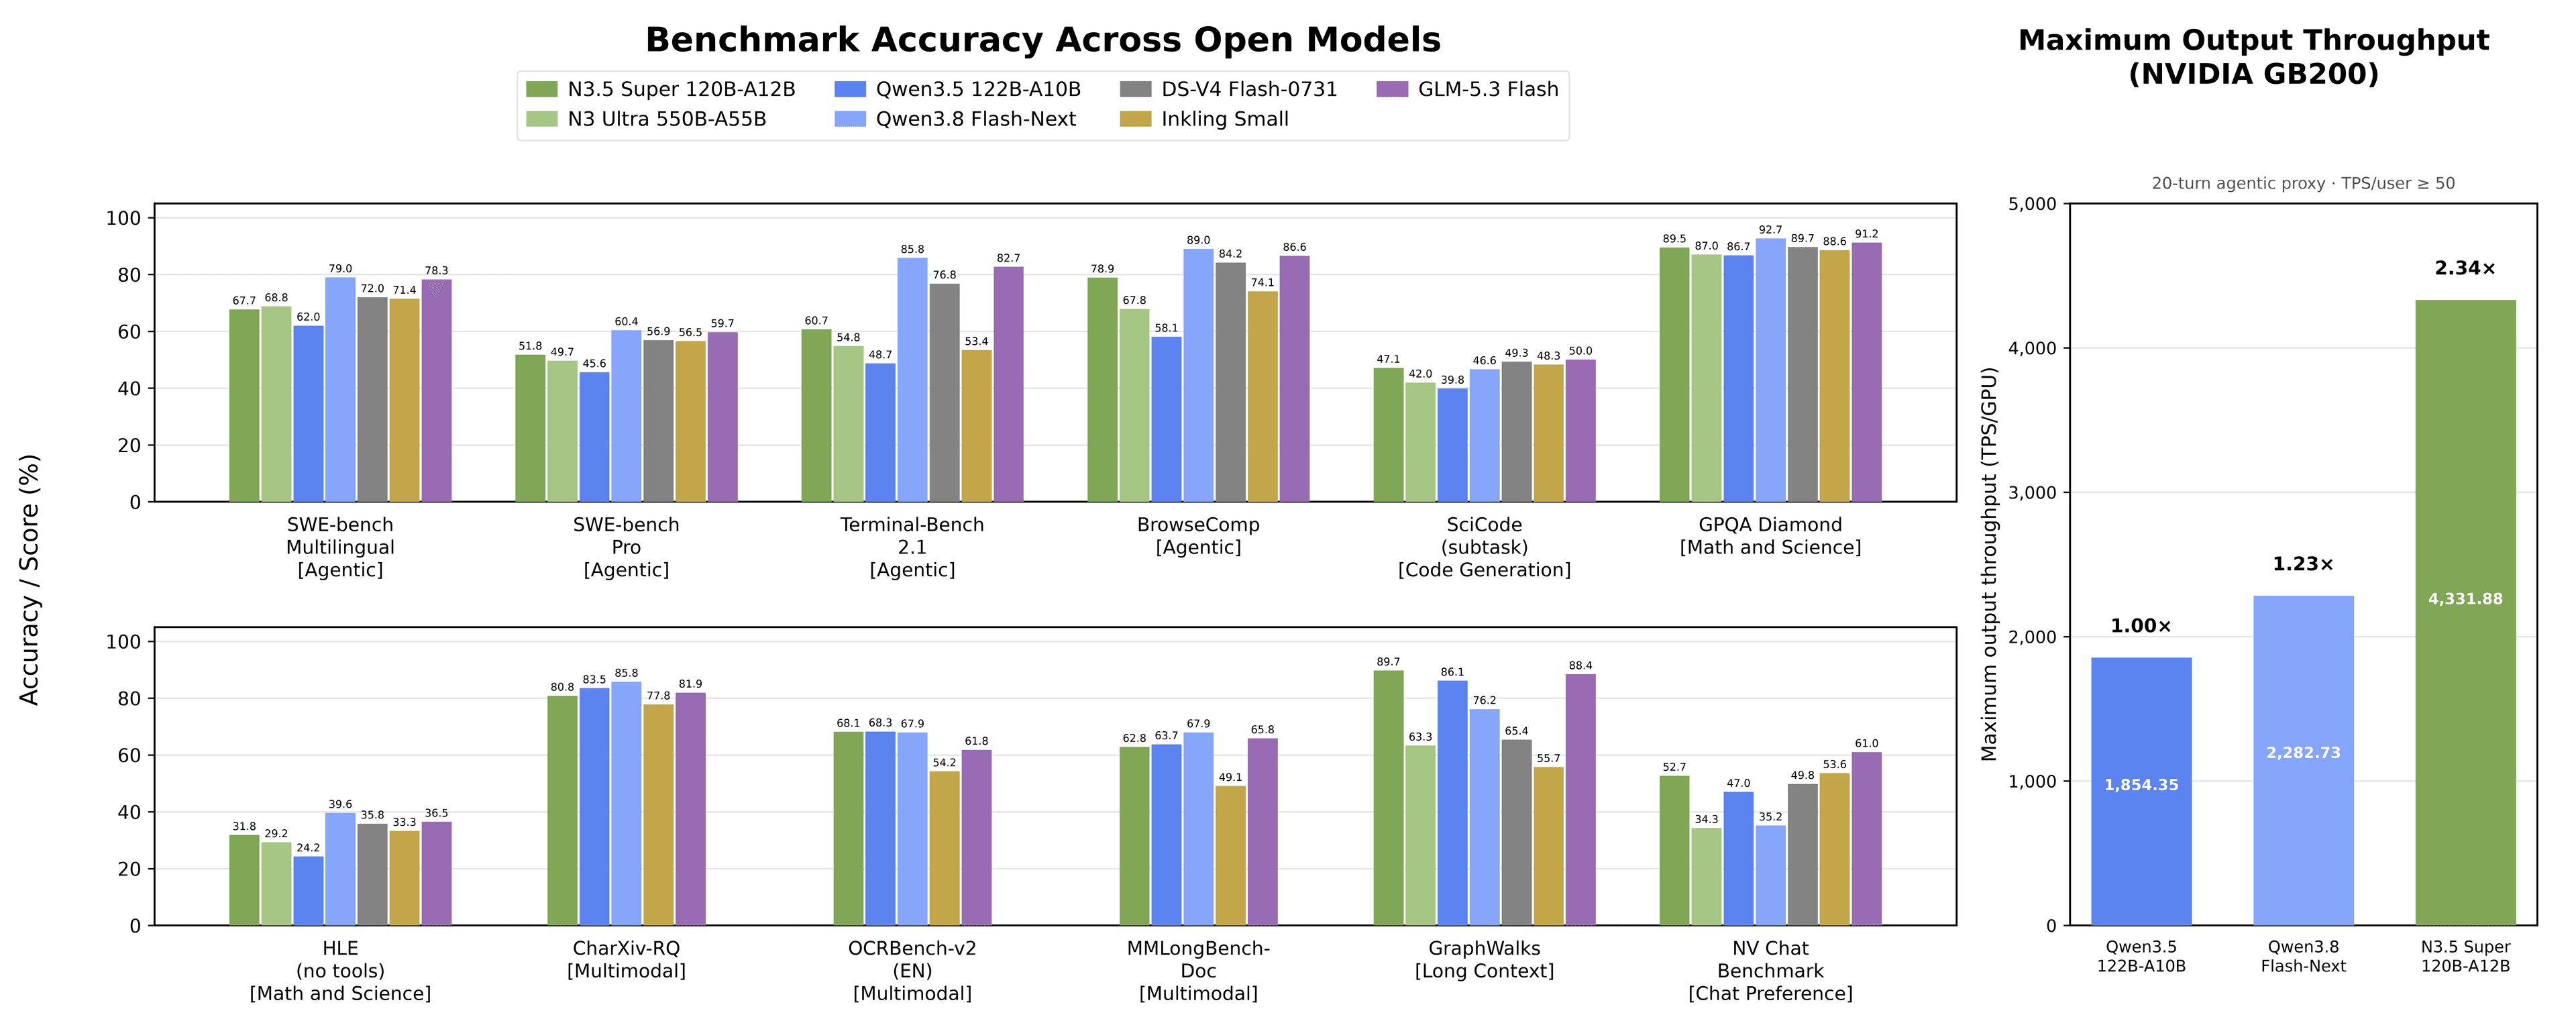
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Vision-Language
All Vision-Language →
Microsoft's Mage-VL-Cowork takes on computer-use tasks
A new vision-language agent model aims to operate GUIs, write code, and work the terminal.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.
0 comments
No comments yet. Be the first to weigh in.