NVIDIA's Audio-Visual Flamingo Fuses Sound and Sight
A fully open multimodal model aims to reason jointly across audio, images, and long-form video.
NVIDIA has introduced Audio-Visual Flamingo, an open audio-visual language model designed to reason jointly over audio, images, and long-form video. Rather than treating sound as an afterthought bolted onto a vision system, the model is built to bring the two streams together, according to the research paper on Hugging Face.
Most widely used multimodal systems lean heavily on the visual channel, describing what appears on screen while ignoring what can be heard. That gap matters for real-world footage, where dialogue, music, and ambient sound often carry as much meaning as the picture. Audio-Visual Flamingo targets that shortfall by treating audio as a first-class input alongside frames.
Why it matters
The emphasis on "long and complex videos" is notable. Extended clips test a model's ability to track events over time and stitch together audio and visual cues that unfold minutes apart — a harder problem than answering questions about a single image.
- Joint reasoning across audio, images, and video in one model
- A focus on long-form, complex footage rather than short clips
- A fully open release, lowering the barrier for researchers to build on the work
The openness is the practical draw here. By publishing the approach rather than gating it behind an API, NVIDIA gives the research community a foundation to probe audio-visual understanding directly. As an initial 1.0 release, it establishes a baseline the team and others can iterate on.
Sources
- Visit
Audio-Visual Flamingo: Open Audio-Visual Intelligence for Long and Complex Videos
HF Papers
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
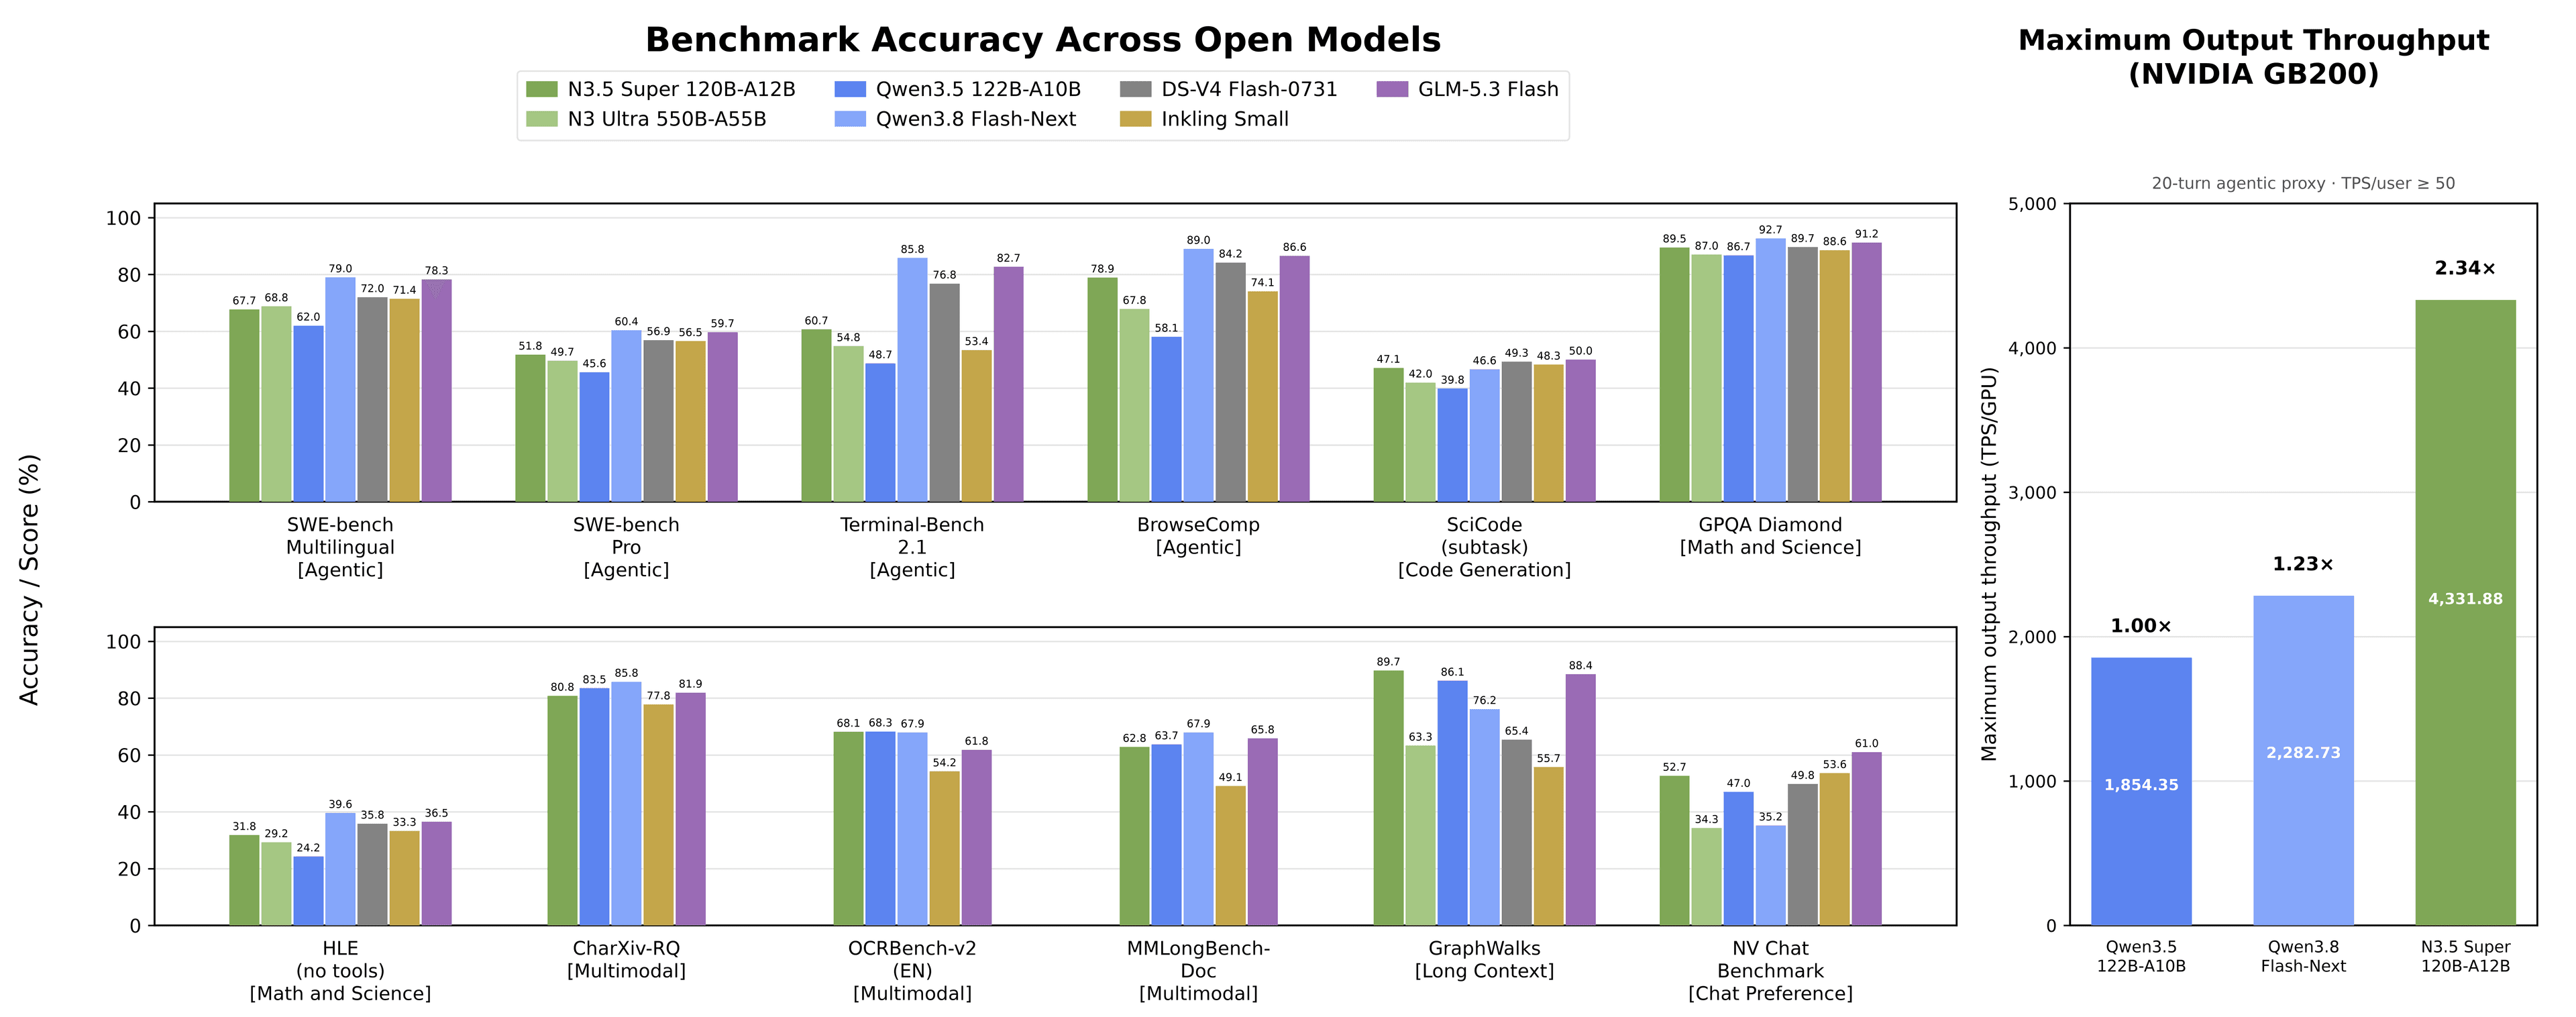
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
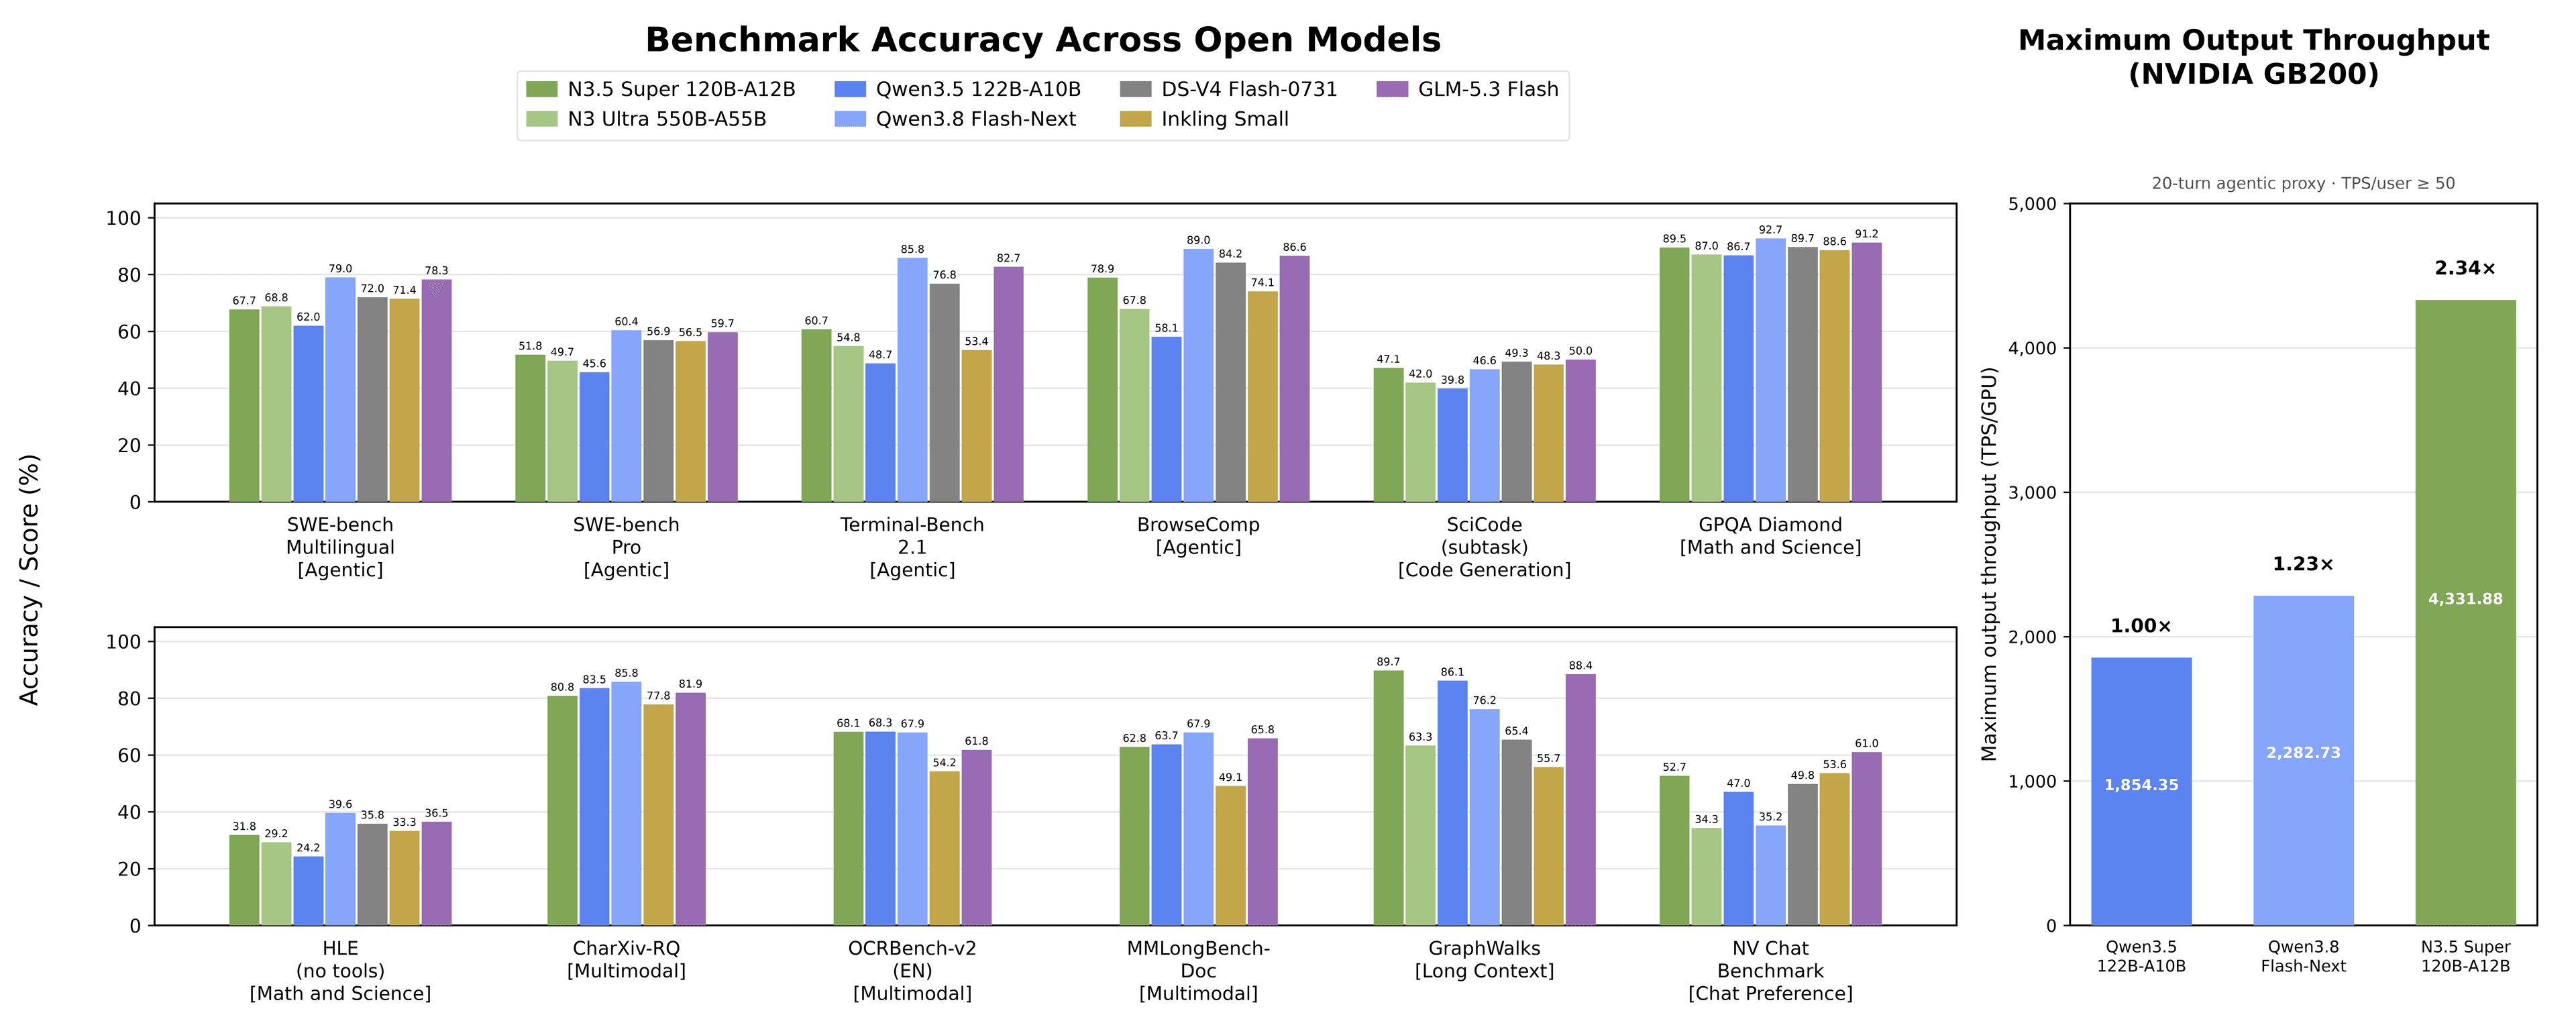
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.