Microsoft's Fara1.5-27B targets computer-use agents
A 27B-parameter vision-language model built to drive browsers and desktop apps like a human operator.
Microsoft has published Fara1.5-27B, a vision-language model designed for computer-use automation, on Hugging Face. Rather than answering questions from a chat box, the model is built to perceive graphical interfaces and take actions across web browsers and desktop applications.
At 27 billion parameters, Fara1.5-27B sits in the mid-size tier of open-weight releases—large enough to handle the visual reasoning that agentic tasks demand, but small enough to run without the infrastructure that frontier systems require. It is a dense model rather than a mixture-of-experts design, and it is distributed under a custom license.
Why it matters
Computer-use agents are one of the more contested frontiers in applied AI right now. Systems that can read a screen, click buttons, fill forms, and navigate multi-step workflows promise to automate work that has resisted traditional scripting. Making that capability available as open weights lets researchers and developers study, fine-tune, and self-host the technology instead of depending on a closed API.
Key details from the release:
- Vision-language model tuned for browser and desktop automation
- 27B parameters, dense architecture
- Released under a custom ("other") license
As with any agent that can operate a machine on a user's behalf, the practical questions will center on reliability, safety, and how well the model generalizes beyond the benchmarks it was trained against. Microsoft's decision to ship Fara1.5-27B openly gives the community a chance to probe those limits directly. Full documentation and weights are available on the model's Hugging Face page.
Sources
- Visit
microsoft/Fara1.5-27B
Hugging Face
More from Microsoft
All Microsoft releases →
Microsoft Releases FrogNano-4B Under MIT License
The compact 4-billion-parameter text model lands on Hugging Face with a permissive license aimed at developers.
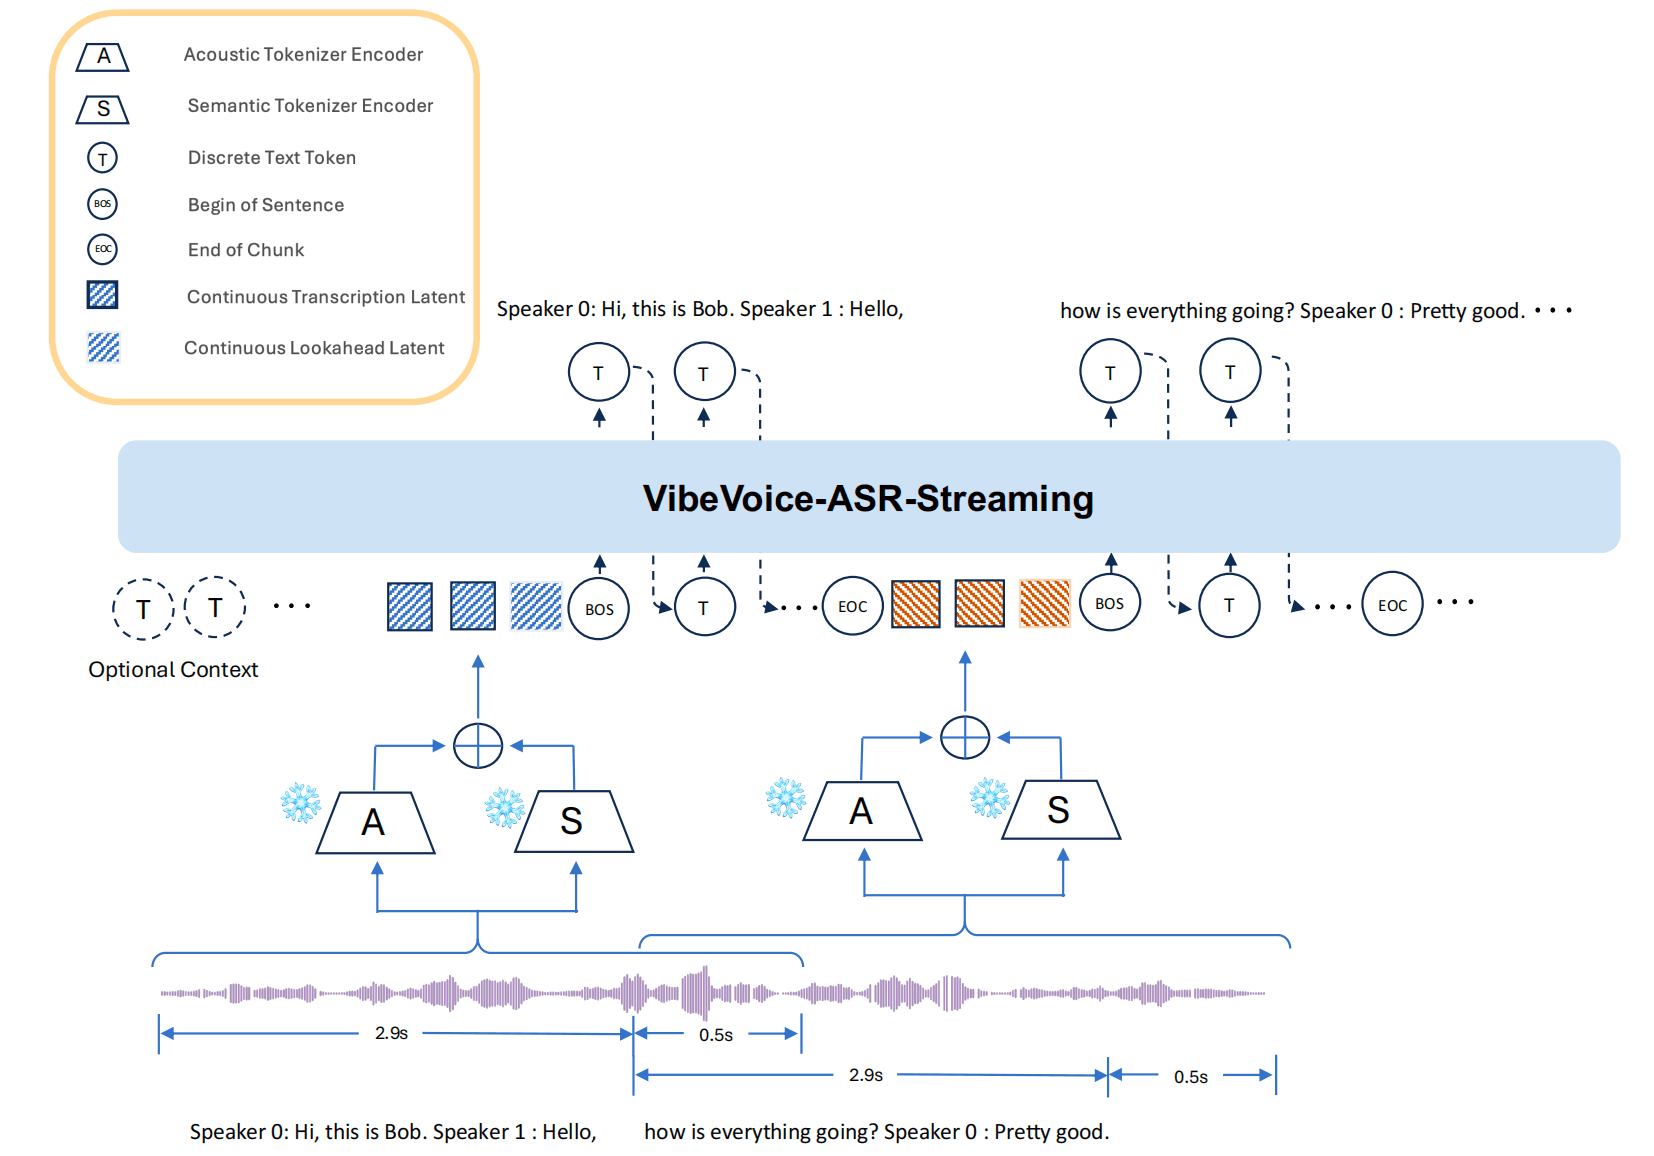
Microsoft's VibeVoice ASR brings streaming speech-to-text
A 7-billion-parameter model targets real-time, multilingual transcription with an open release on Hugging Face.
Microsoft's Mage-VL Streams Video Natively
A codec-native multimodal foundation model aims to understand live video and vision-language input in real time.
More in Vision-Language
All Vision-Language →
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.

Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
0 comments
No comments yet. Be the first to weigh in.