Microsoft's VibeVoice ASR brings streaming speech-to-text
A 7-billion-parameter model targets real-time, multilingual transcription with an open release on Hugging Face.
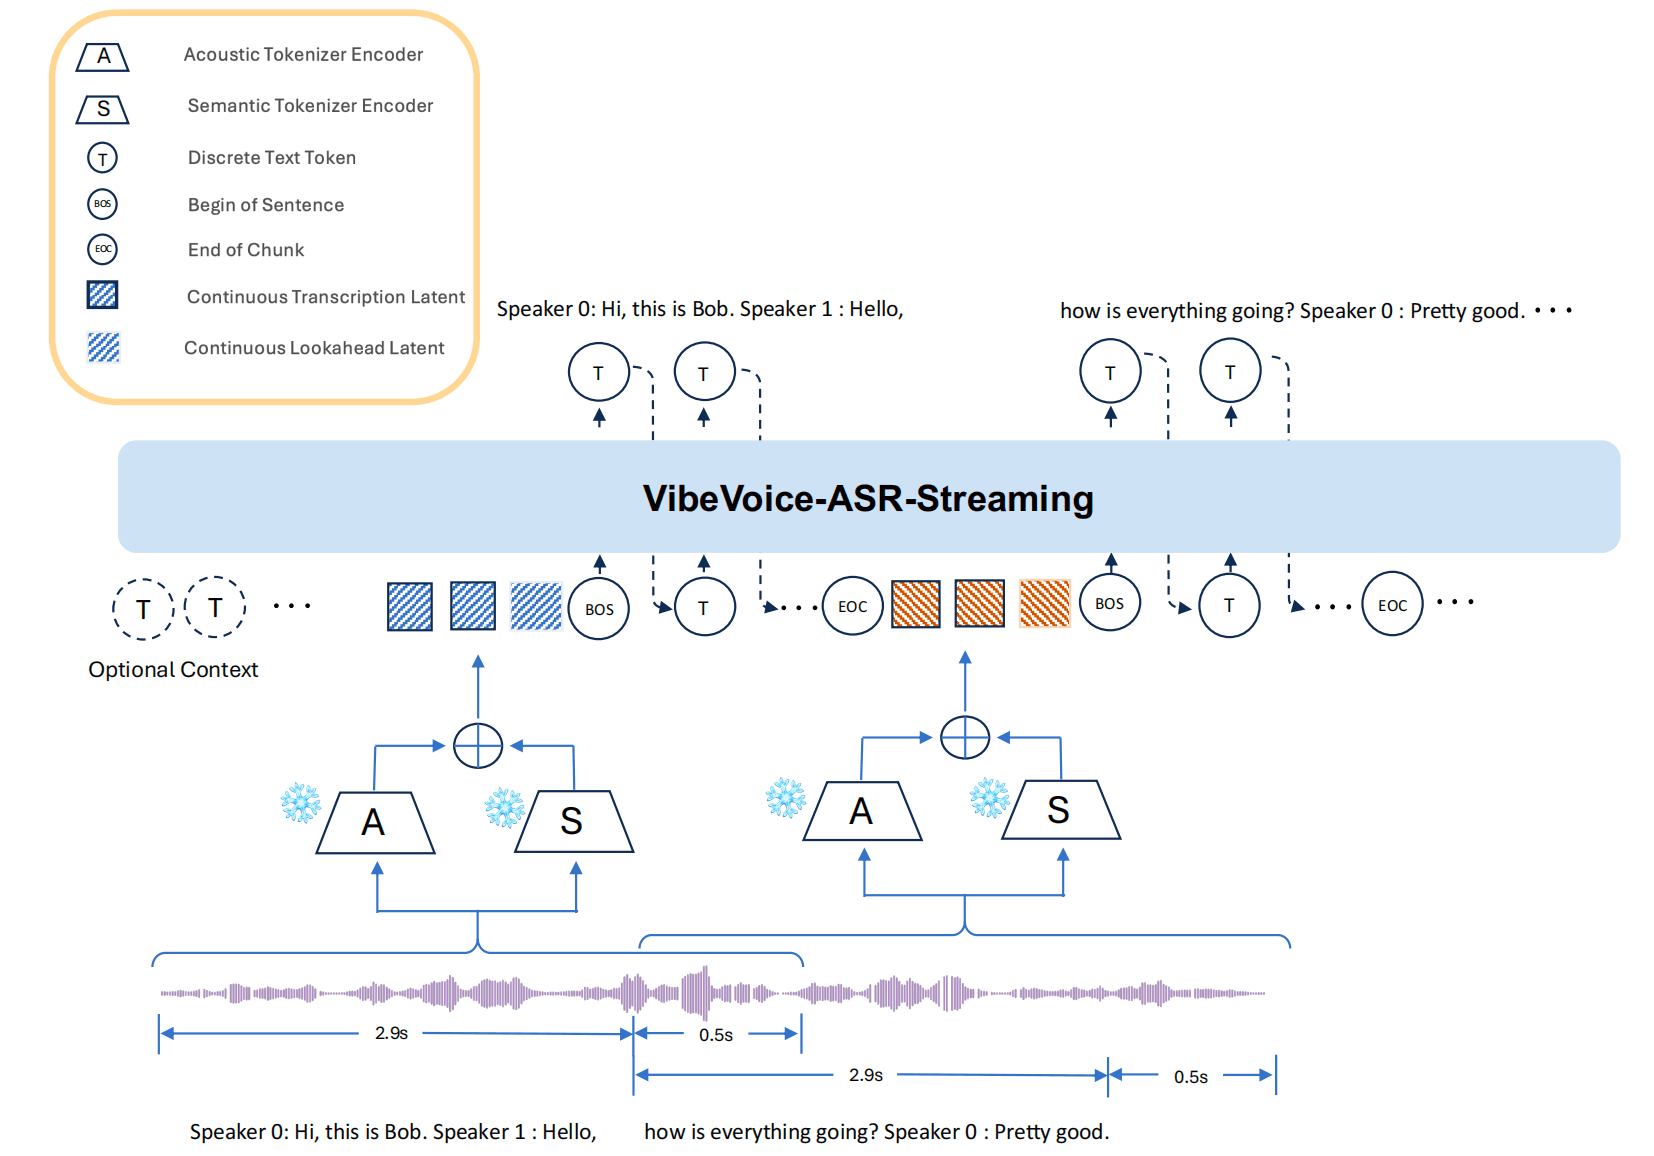
Microsoft has published VibeVoice-ASR-Streaming-7B, a speech recognition model designed for streaming transcription, on Hugging Face. The 7-billion-parameter dense model handles automatic speech recognition across multiple languages, including English, Chinese, and Spanish.
The "streaming" designation is the key detail here. Rather than waiting for a full audio clip to finish before producing text, streaming ASR emits transcriptions incrementally as audio arrives. That makes the model a better fit for live captioning, meeting notes, voice interfaces, and any application where latency matters as much as accuracy.
Why it matters
Speech-to-text has become a crowded field, but most of the attention has gone to batch-oriented models. A capable open-weight streaming option from a major lab gives developers more flexibility to build low-latency, on-device or self-hosted transcription pipelines.
- 7B parameters, dense (not a mixture-of-experts model)
- Multilingual coverage spanning English, Chinese, Spanish, and more
- Built specifically for streaming, real-time transcription
The model is distributed under a custom license, so teams evaluating it for production should review the terms on the model card before deploying. As an initial release in the VibeVoice ASR line, it also signals Microsoft's continued investment in open speech tooling.
Sources
- Visit
microsoft/VibeVoice-ASR-Streaming-7B
Hugging Face
More from Microsoft
All Microsoft releases →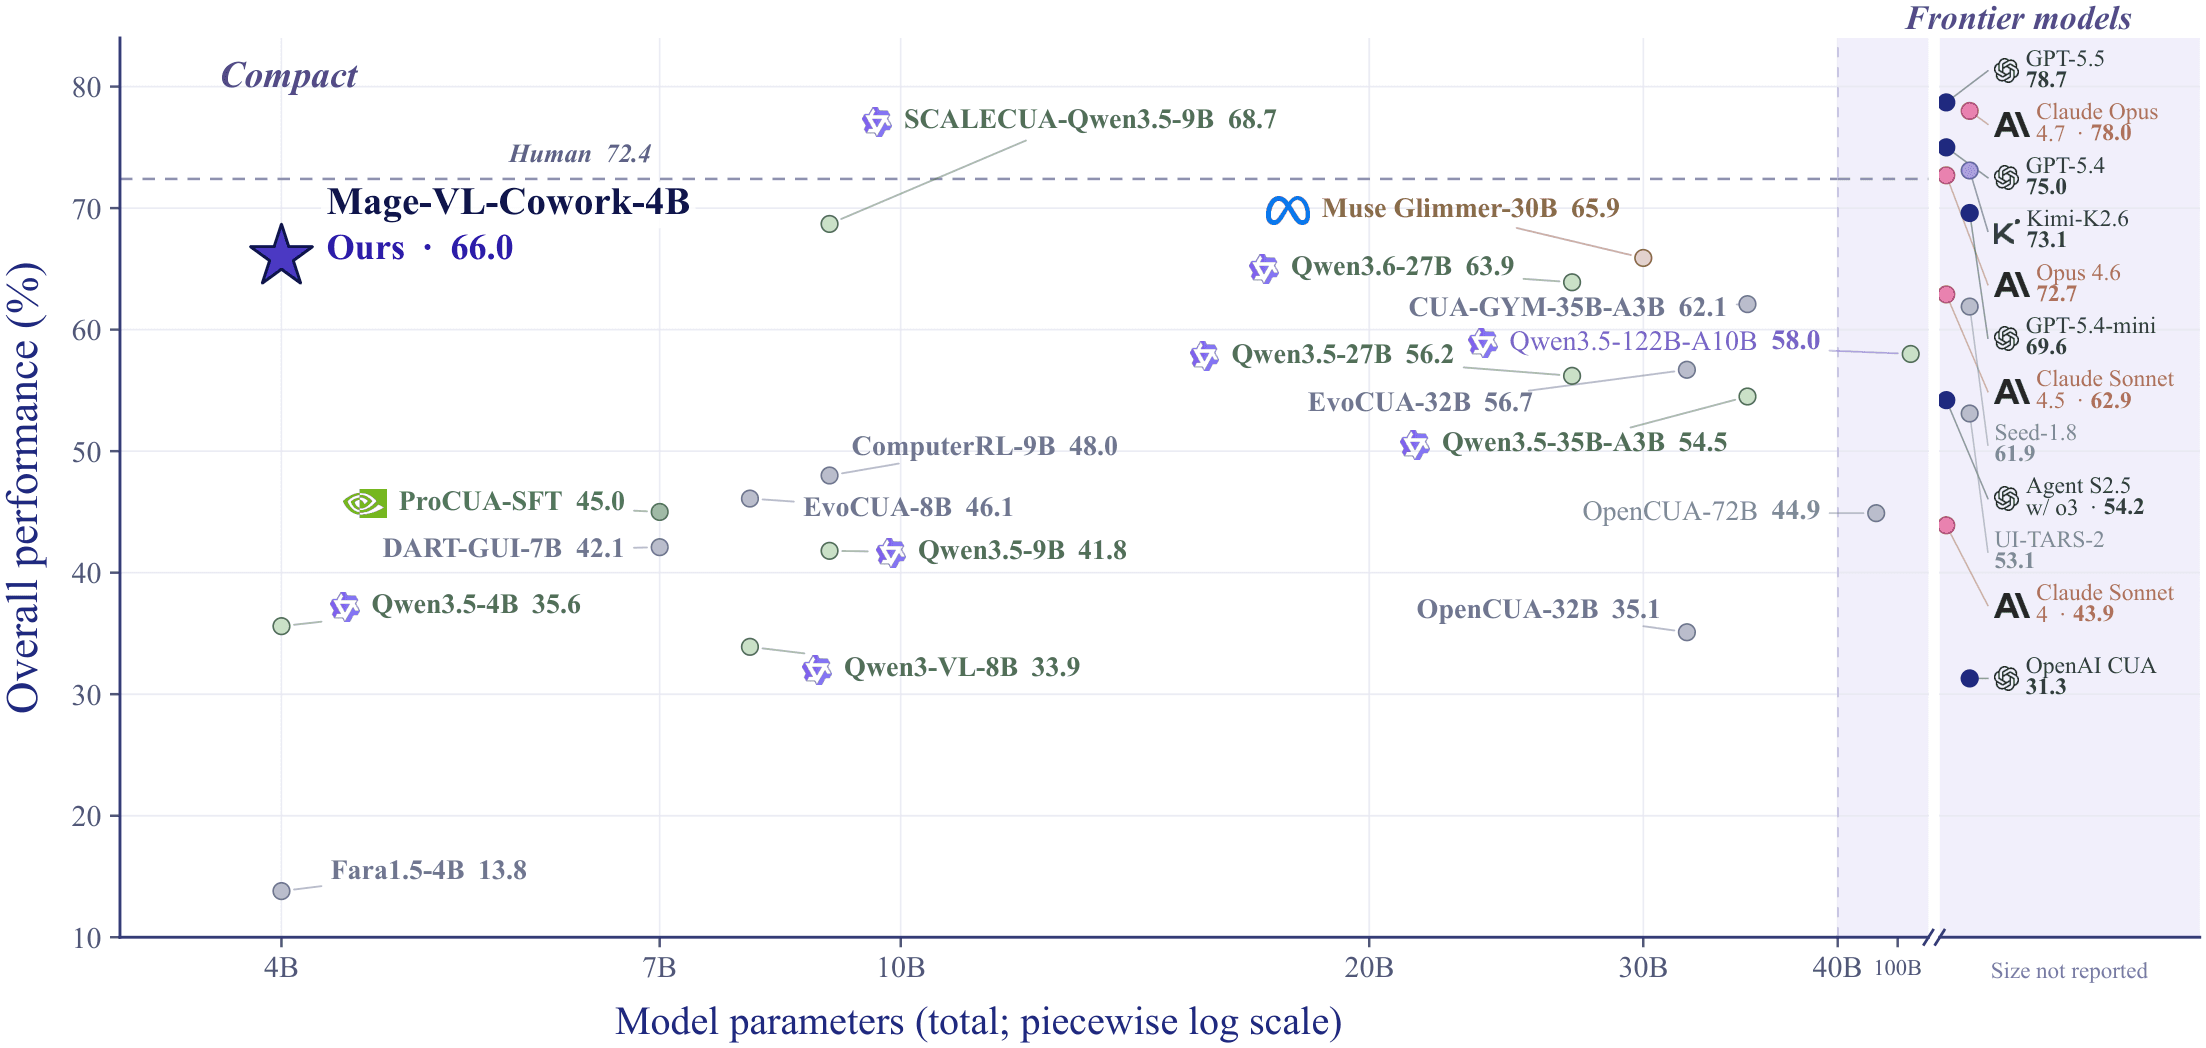
Microsoft's Mage-VL-Cowork takes on computer-use tasks
A new vision-language agent model aims to operate GUIs, write code, and work the terminal.
Microsoft Releases FrogNano-4B Under MIT License
The compact 4-billion-parameter text model lands on Hugging Face with a permissive license aimed at developers.
Microsoft's Mage-VL Streams Video Natively
A codec-native multimodal foundation model aims to understand live video and vision-language input in real time.
More in Speech → Text
All Speech → Text →
Haru-4B Brings Full-Duplex Speech to Six Languages
A compact 4-billion-parameter model handles real-time, two-way voice conversation across six languages in a single system.
ServiceNow Debuts Apriel Voice 27B, an Open Speech Model
The 27-billion-parameter preview unifies text-to-speech, transcription, and reasoning in a single open model.
IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
0 comments
No comments yet. Be the first to weigh in.