Microsoft's Aion 1.0 Instruct is a compact 2.3B chat model
A small, multilingual instruction-tuned model aimed at chat and summarization lands on Hugging Face.
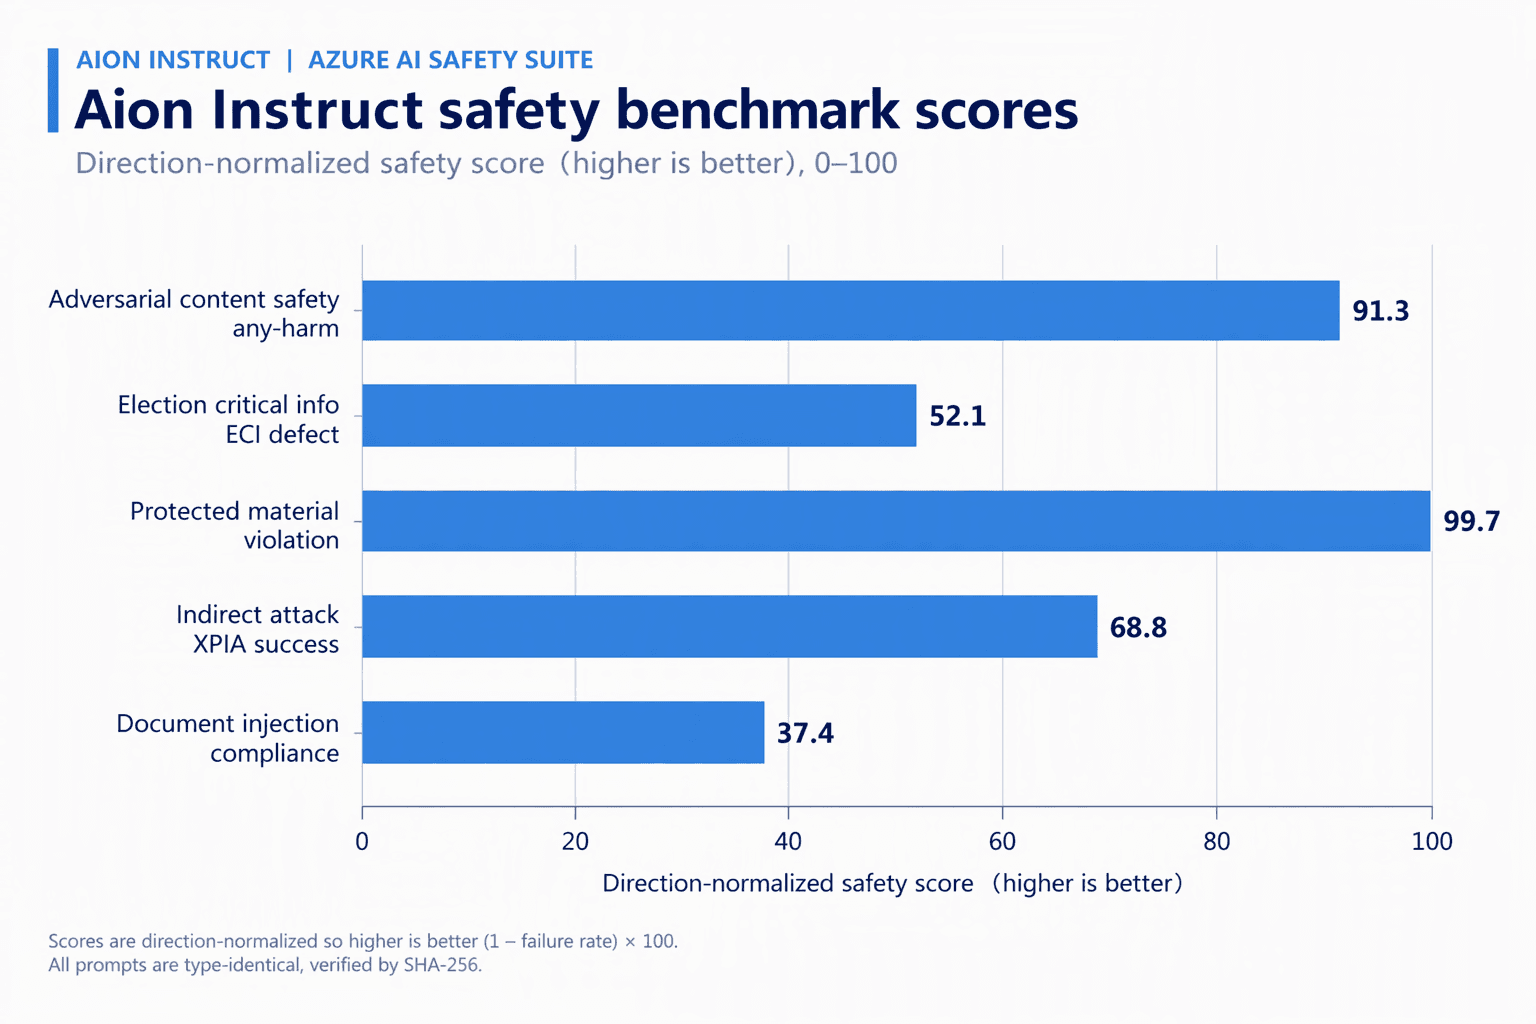
Microsoft has published Aion-1.0-Instruct-2.3B, a compact instruction-tuned language model built for conversational tasks and summarization across multiple languages. At 2.3 billion parameters, it sits firmly in the small-model tier that has become increasingly popular for teams that need capable text generation without the cost and latency of frontier-scale systems.
The model is a dense (non-mixture-of-experts) text LLM, released under a custom license noted on the model card. Microsoft frames Aion 1.0 Instruct around multilingual chat and summarization, two workloads where small models have matured quickly over the past year.
Why it matters
Small, instruction-tuned models have become the practical backbone of many real-world deployments, where predictable cost and on-device or edge-friendly footprints matter more than leaderboard supremacy. A 2.3B model is small enough to run on modest hardware yet large enough to handle everyday assistant tasks.
- Roughly 2.3B parameters, dense architecture
- Tuned for multilingual chat and summarization
- Distributed via Hugging Face under a custom license
As an initial release, Aion 1.0 Instruct establishes a new model family rather than iterating on an existing one. Developers evaluating it should check the model card for license terms, supported languages, and usage details before building on top of it.
Sources
- Visit
microsoft/Aion-1.0-Instruct-2.3B
Hugging Face
More from Microsoft
All Microsoft releases →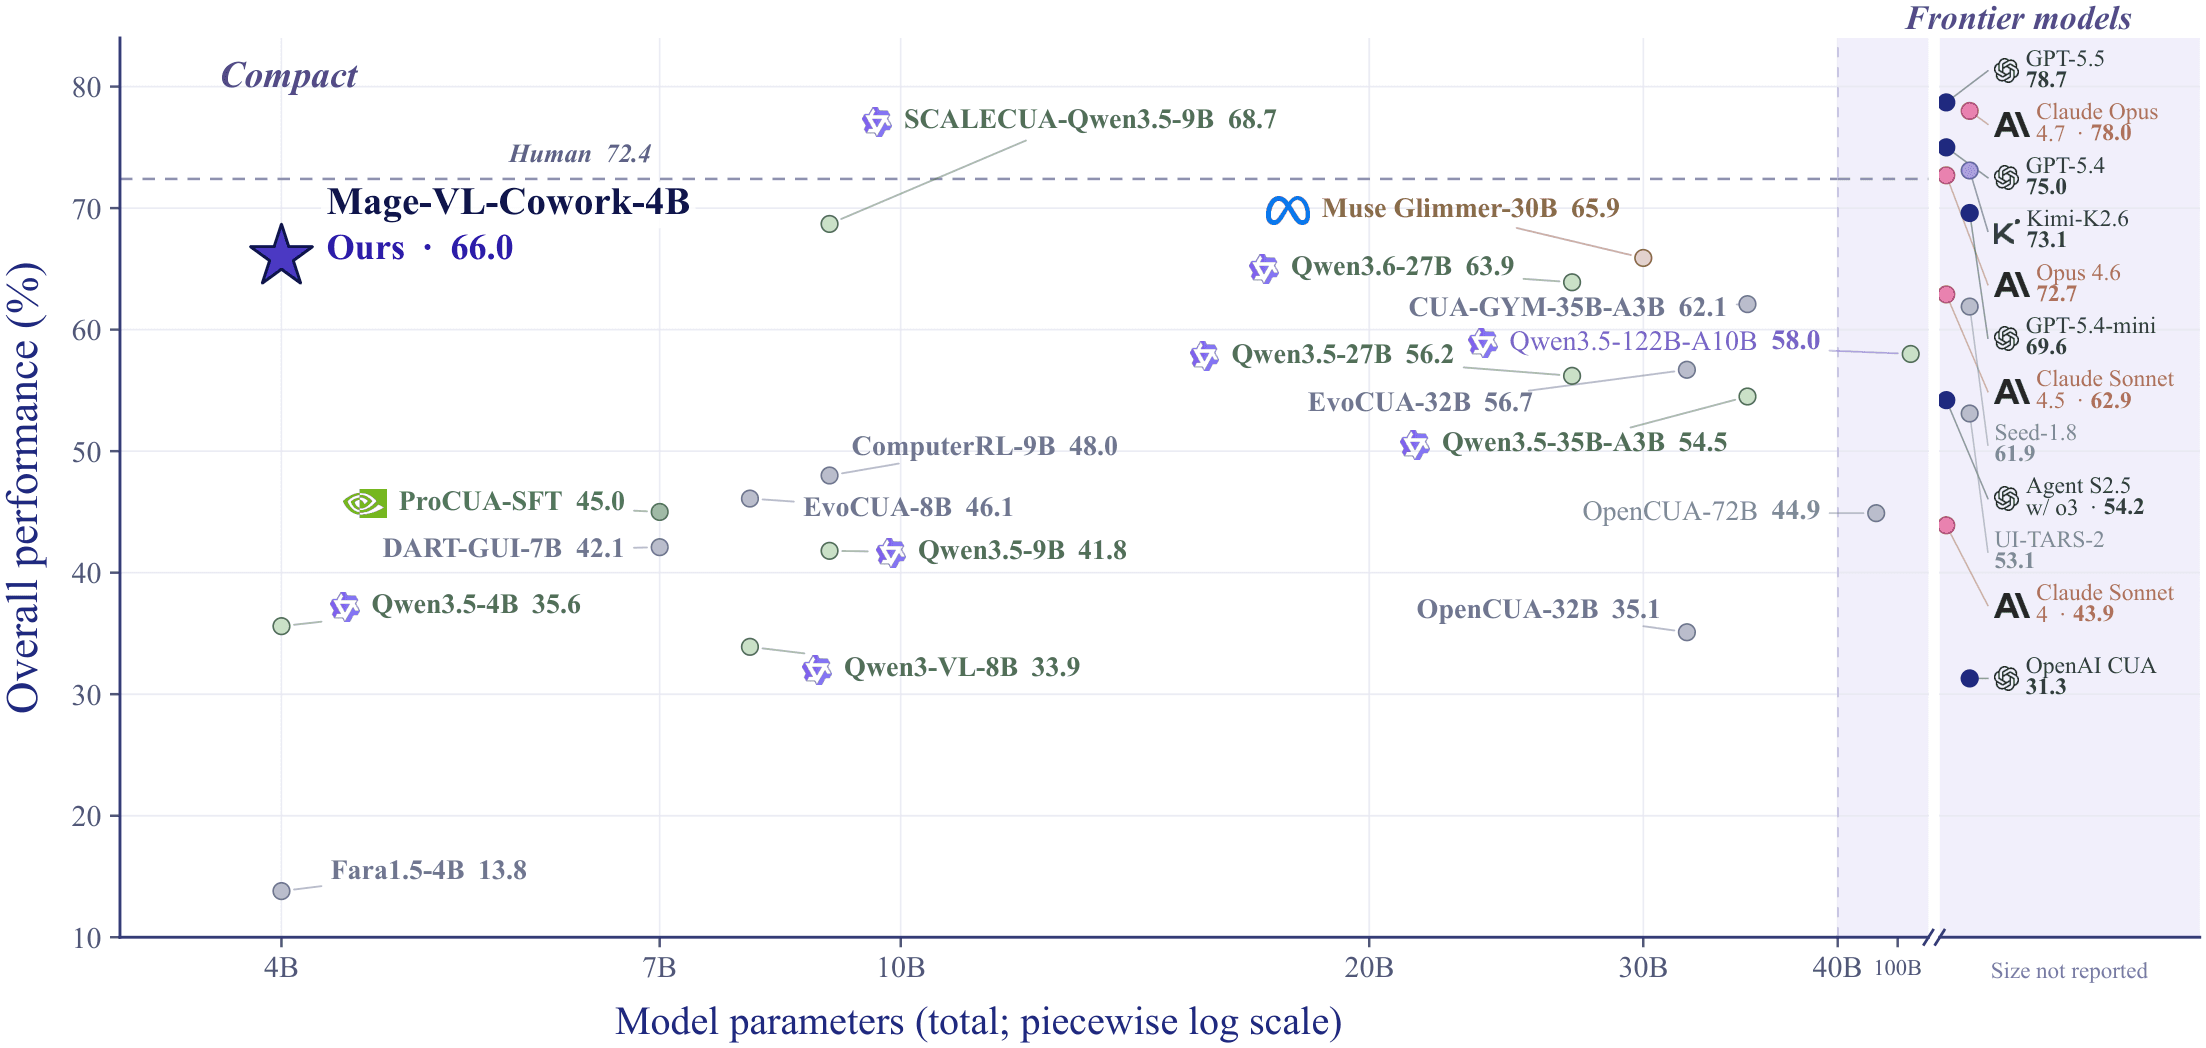
Microsoft's Mage-VL-Cowork takes on computer-use tasks
A new vision-language agent model aims to operate GUIs, write code, and work the terminal.
Microsoft Releases FrogNano-4B Under MIT License
The compact 4-billion-parameter text model lands on Hugging Face with a permissive license aimed at developers.
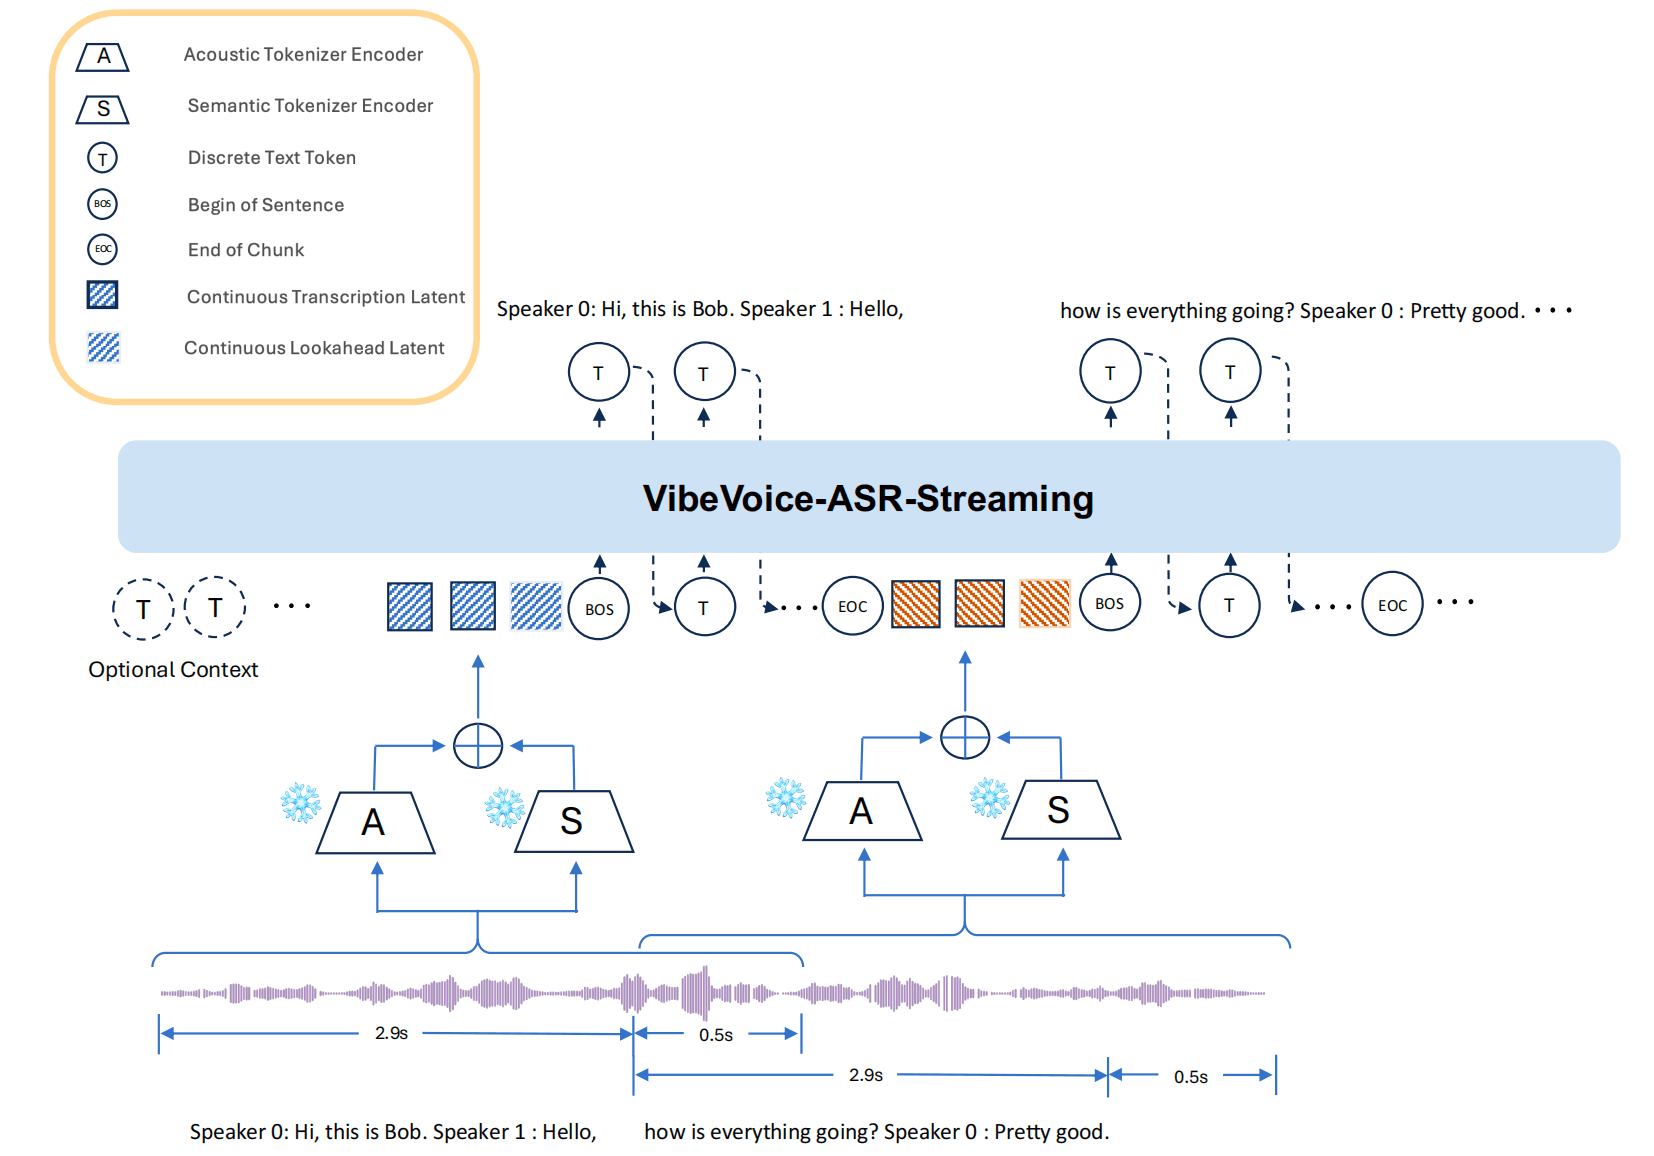
Microsoft's VibeVoice ASR brings streaming speech-to-text
A 7-billion-parameter model targets real-time, multilingual transcription with an open release on Hugging Face.
More in Text / LLM
All Text / LLM →
SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.

Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.
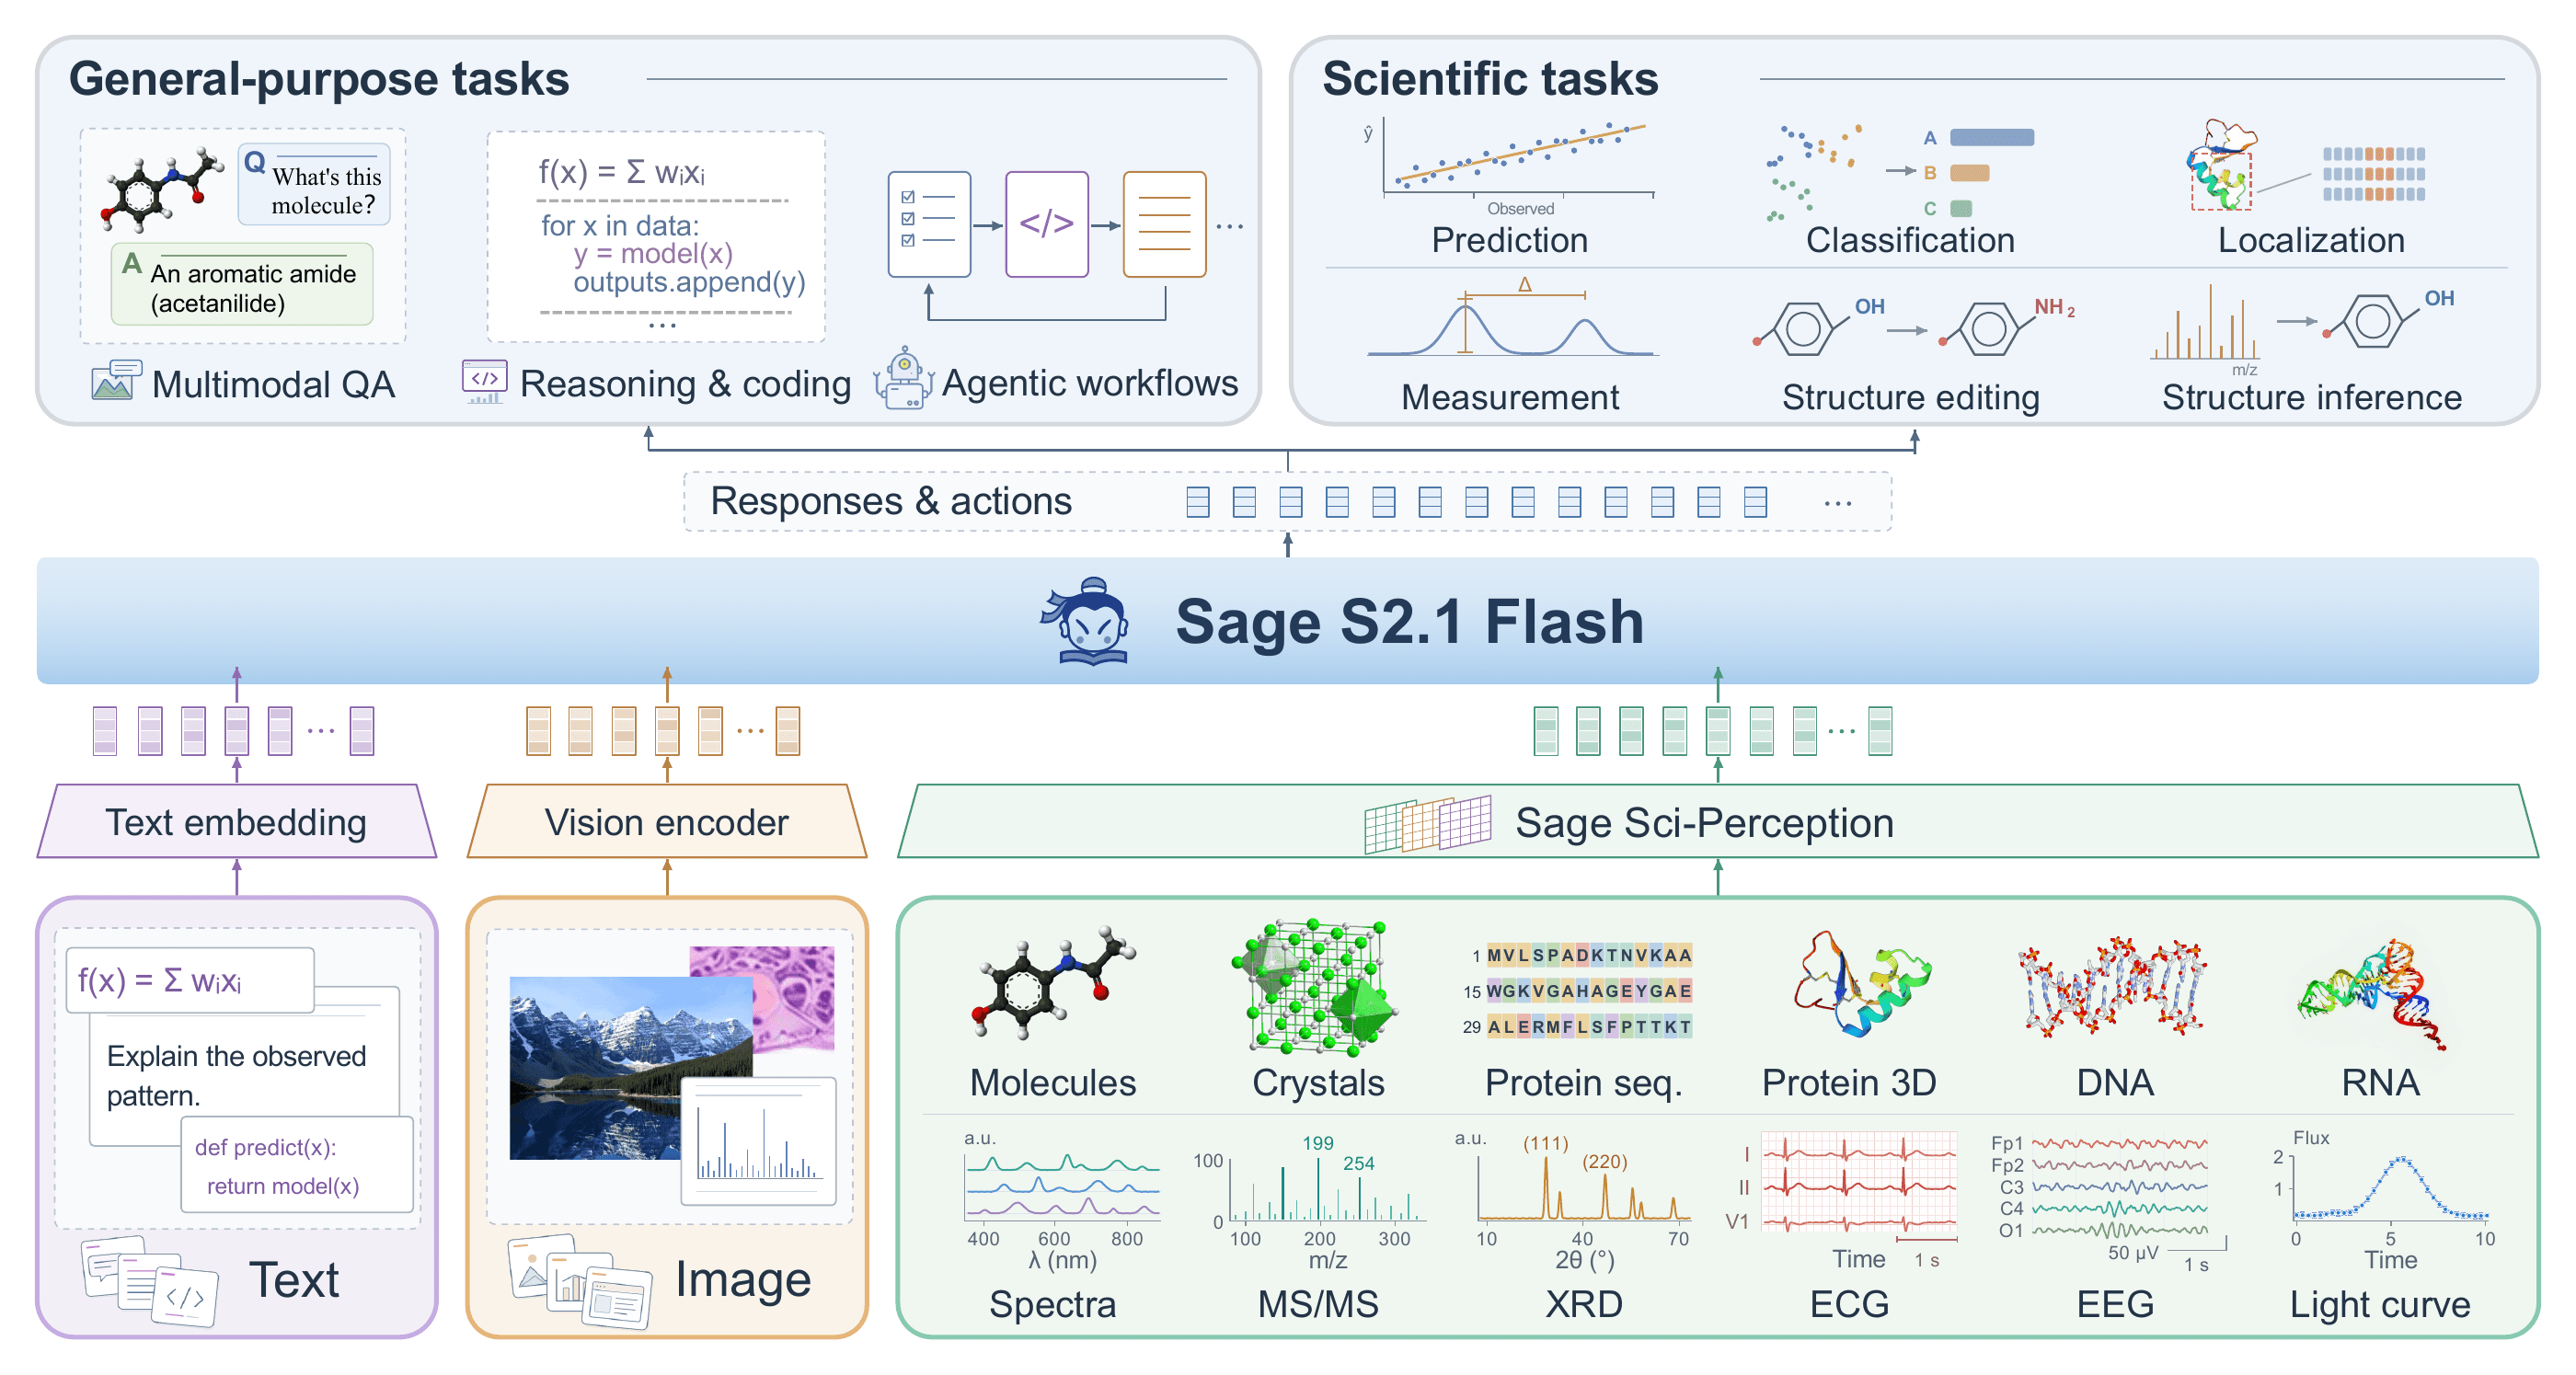
InternLM's Sage S2.1 Flash targets scientific reasoning
The 320B mixture-of-experts model is built to reason over scientific evidence and act inside interactive environments.
0 comments
No comments yet. Be the first to weigh in.