Motif Technologies debuts Motif 3 Beta, an MoE model
The Korean AI lab's preview release is a mixture-of-experts language model built for long-context, multilingual work.
Motif Technologies has posted Motif 3 Beta, a preview release of a mixture-of-experts (MoE) language model, to Hugging Face. As the "Beta" label suggests, this is an early look rather than a finished product, giving developers a chance to test the model before a stable version arrives.
The release is described as a long-context, multilingual text model. Its MoE architecture activates only a subset of parameters for any given token, a design choice that lets teams scale total model capacity while keeping inference costs more manageable than a comparably sized dense model.
Why it matters
Open previews like this one are how smaller and regional labs establish a foothold against better-known open-weights families. A few reasons the release is worth watching:
- MoE efficiency can make larger models practical to run without proportional compute increases.
- Multilingual and long-context framing signals ambitions beyond English-only, short-form tasks.
- A beta tag invites community feedback that can shape the eventual stable release.
Key details remain unconfirmed. The model card does not yet pin down a total or active parameter count, context-window length, or full licensing terms, all of which will matter for anyone weighing it for production use. Until those specifics are published, Motif 3 Beta is best treated as an experimental checkpoint to evaluate rather than deploy. Full details are available on the Hugging Face repository.
Sources
- Visit
Motif-Technologies/Motif-3-Beta
Hugging Face
More from Motif Technologies
All Motif Technologies releases →
Motif 3 brings a sparse MoE approach to reasoning
Motif Technologies debuts a mixture-of-experts language model built around grouped differential latent attention for long-context reasoning and code.
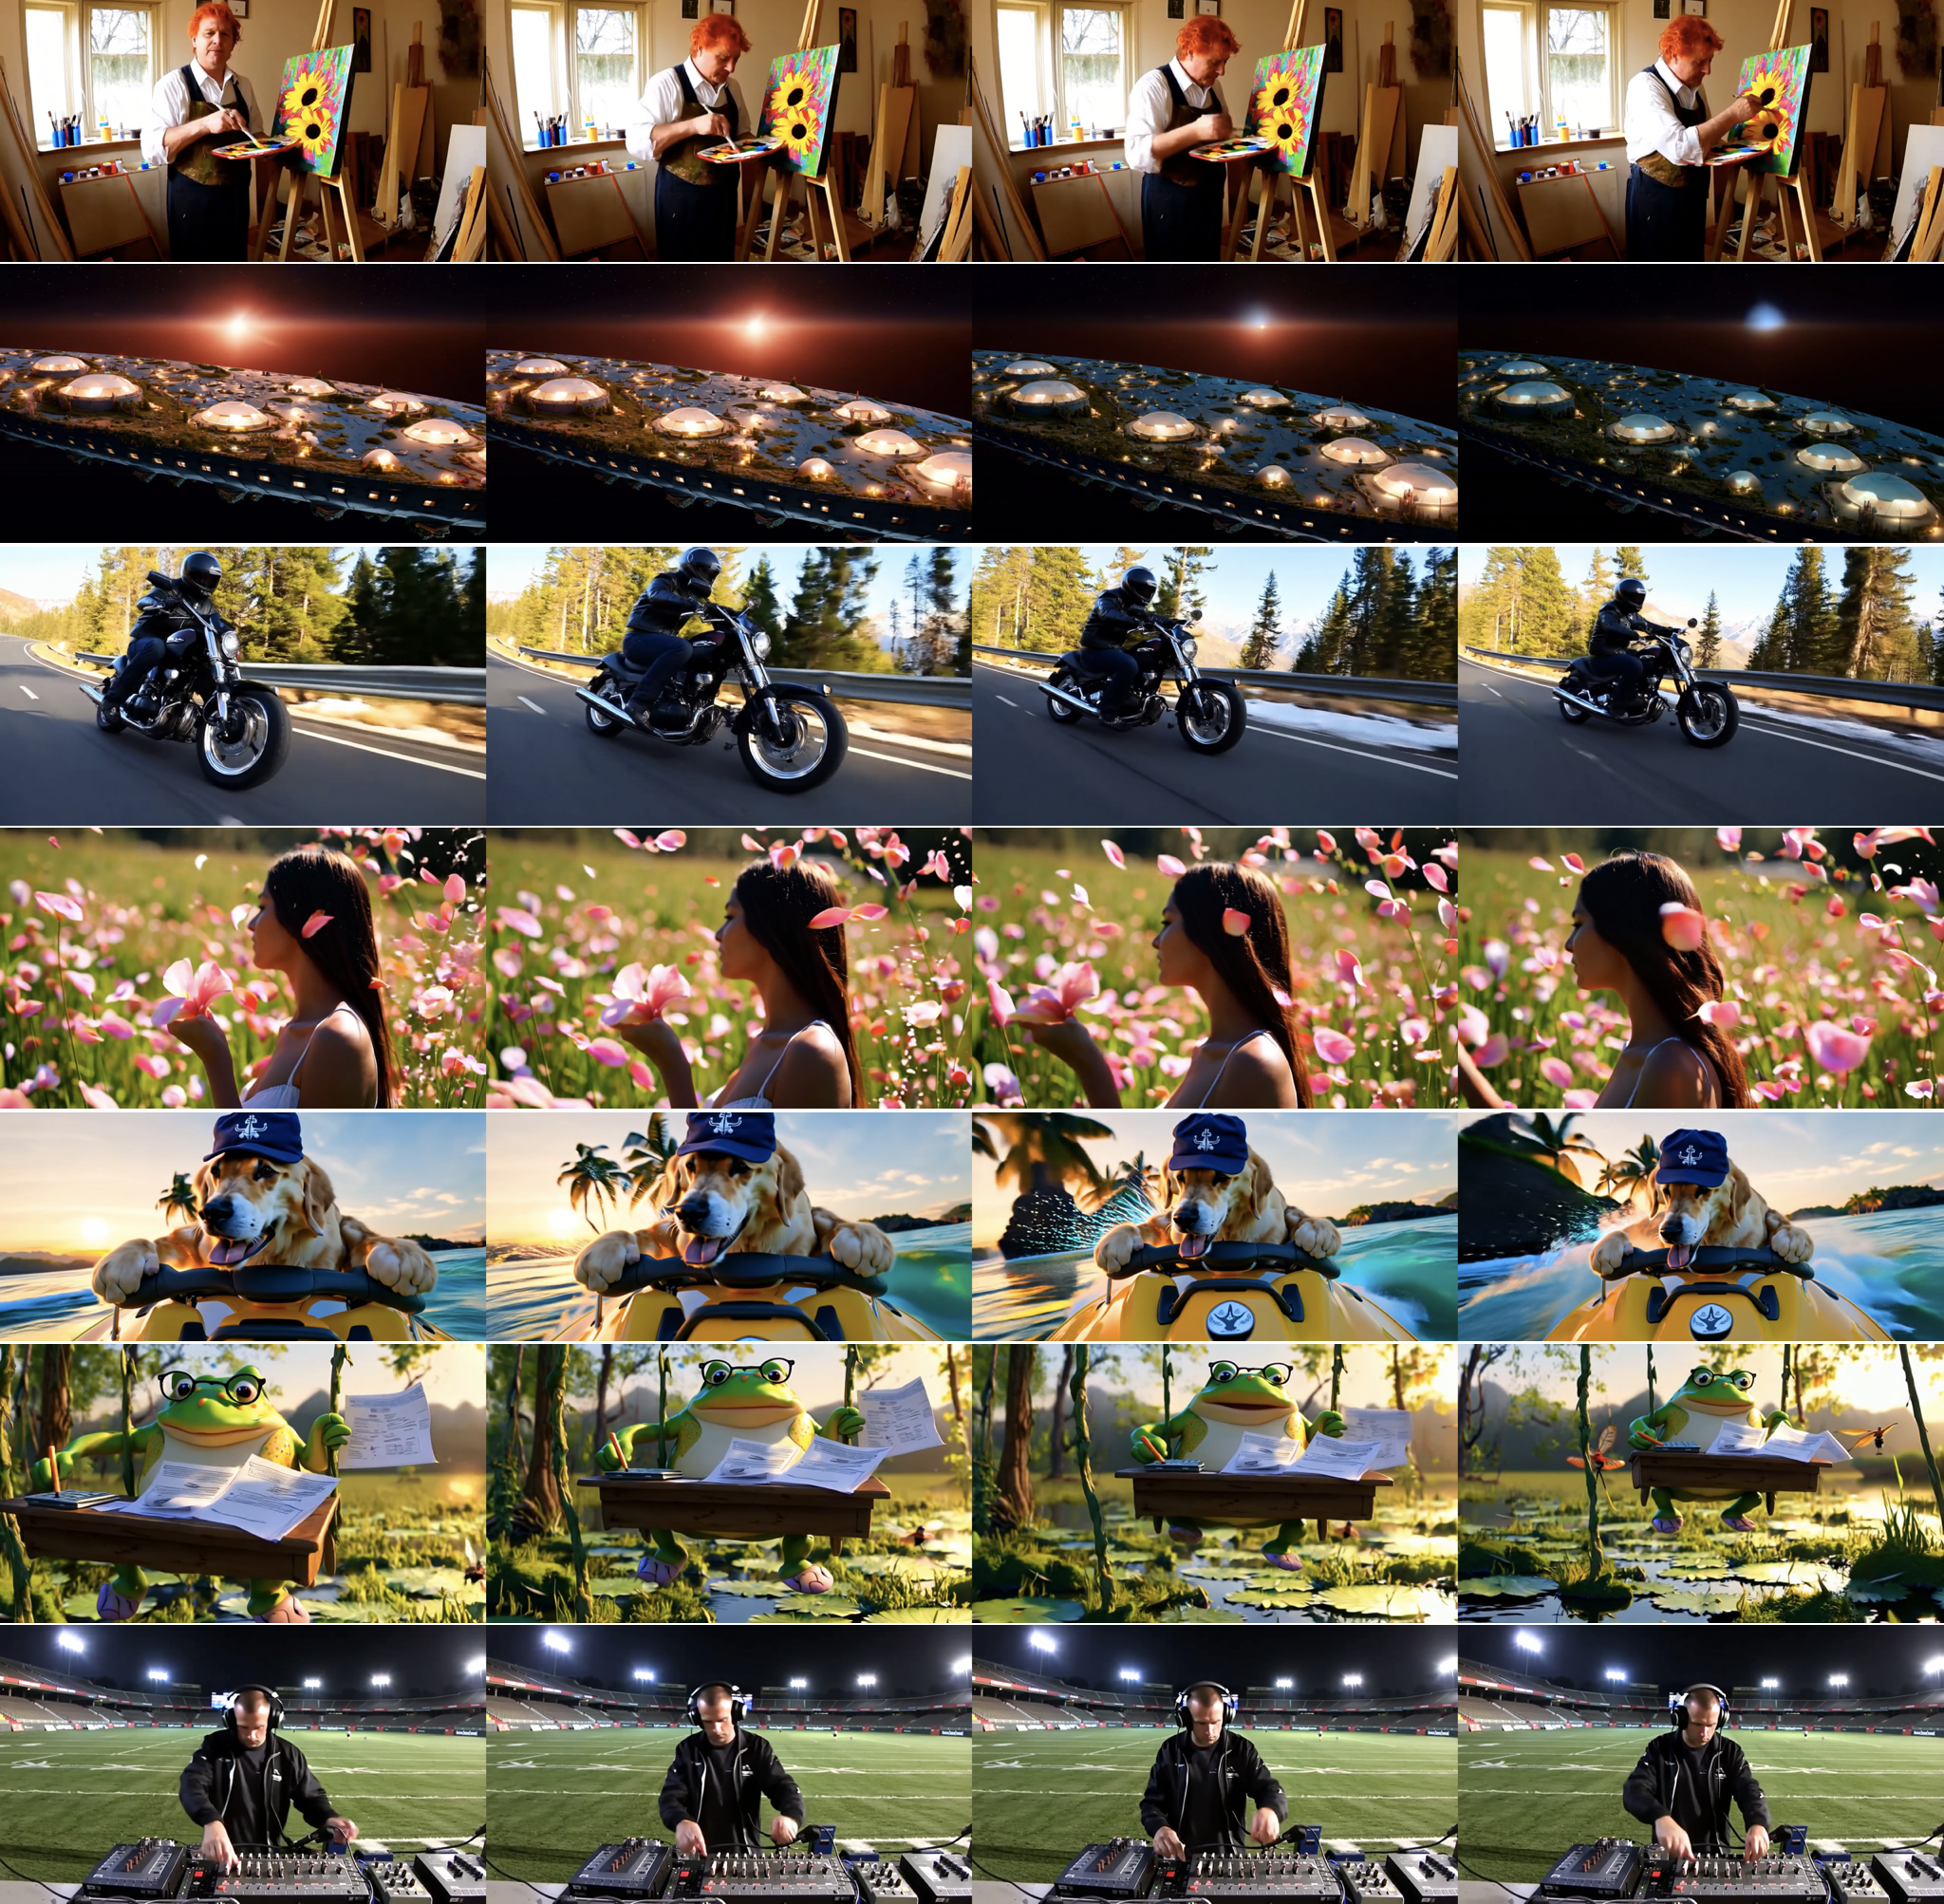
Motif Releases 2B Open-Source Text-to-Video Model
The new Apache 2.0 licensed model uses a diffusion transformer architecture to offer a new open alternative for video generation research.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.