Nanbeige 4.2 arrives as a compact 3B bilingual model
The new English-Chinese language model targets efficient deployment in a small parameter footprint.

Nanbeige has published Nanbeige4.2-3B, a compact 3-billion-parameter language model built for both English and Chinese text generation. It's a dense model — no mixture-of-experts routing here — which keeps the architecture straightforward and predictable to run.
The 3B size places it squarely in the small-model category, where the appeal is efficiency: models this size can run on modest hardware, including single consumer GPUs and, with quantization, even higher-end laptops. For teams that need bilingual capability without the cost of a frontier-scale model, that trade-off matters.
Why it matters
The steady stream of small bilingual models reflects a real demand outside the largest labs. Not every application needs a hundred-billion-parameter system, and English-Chinese coverage in a lightweight package is useful for:
- On-device or edge deployments where memory is tight
- Cost-sensitive inference at scale
- Fine-tuning experiments that benefit from fast iteration
Nanbeige has not published detailed benchmark figures or a stated context length alongside this release, so buyers will want to test it against their own workloads. The model is distributed under a custom license, so anyone planning production use should review the terms on the model card before committing.
Sources
- Visit
Nanbeige/Nanbeige4.2-3B
Hugging Face
More from Nanbeige
All Nanbeige releases →
Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.

Nanbeige Releases 3B Chinese-Enhanced Language Model
The new Llama-based model was trained from scratch on 3.5 trillion tokens of Chinese and English data to enhance its bilingual capabilities.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.
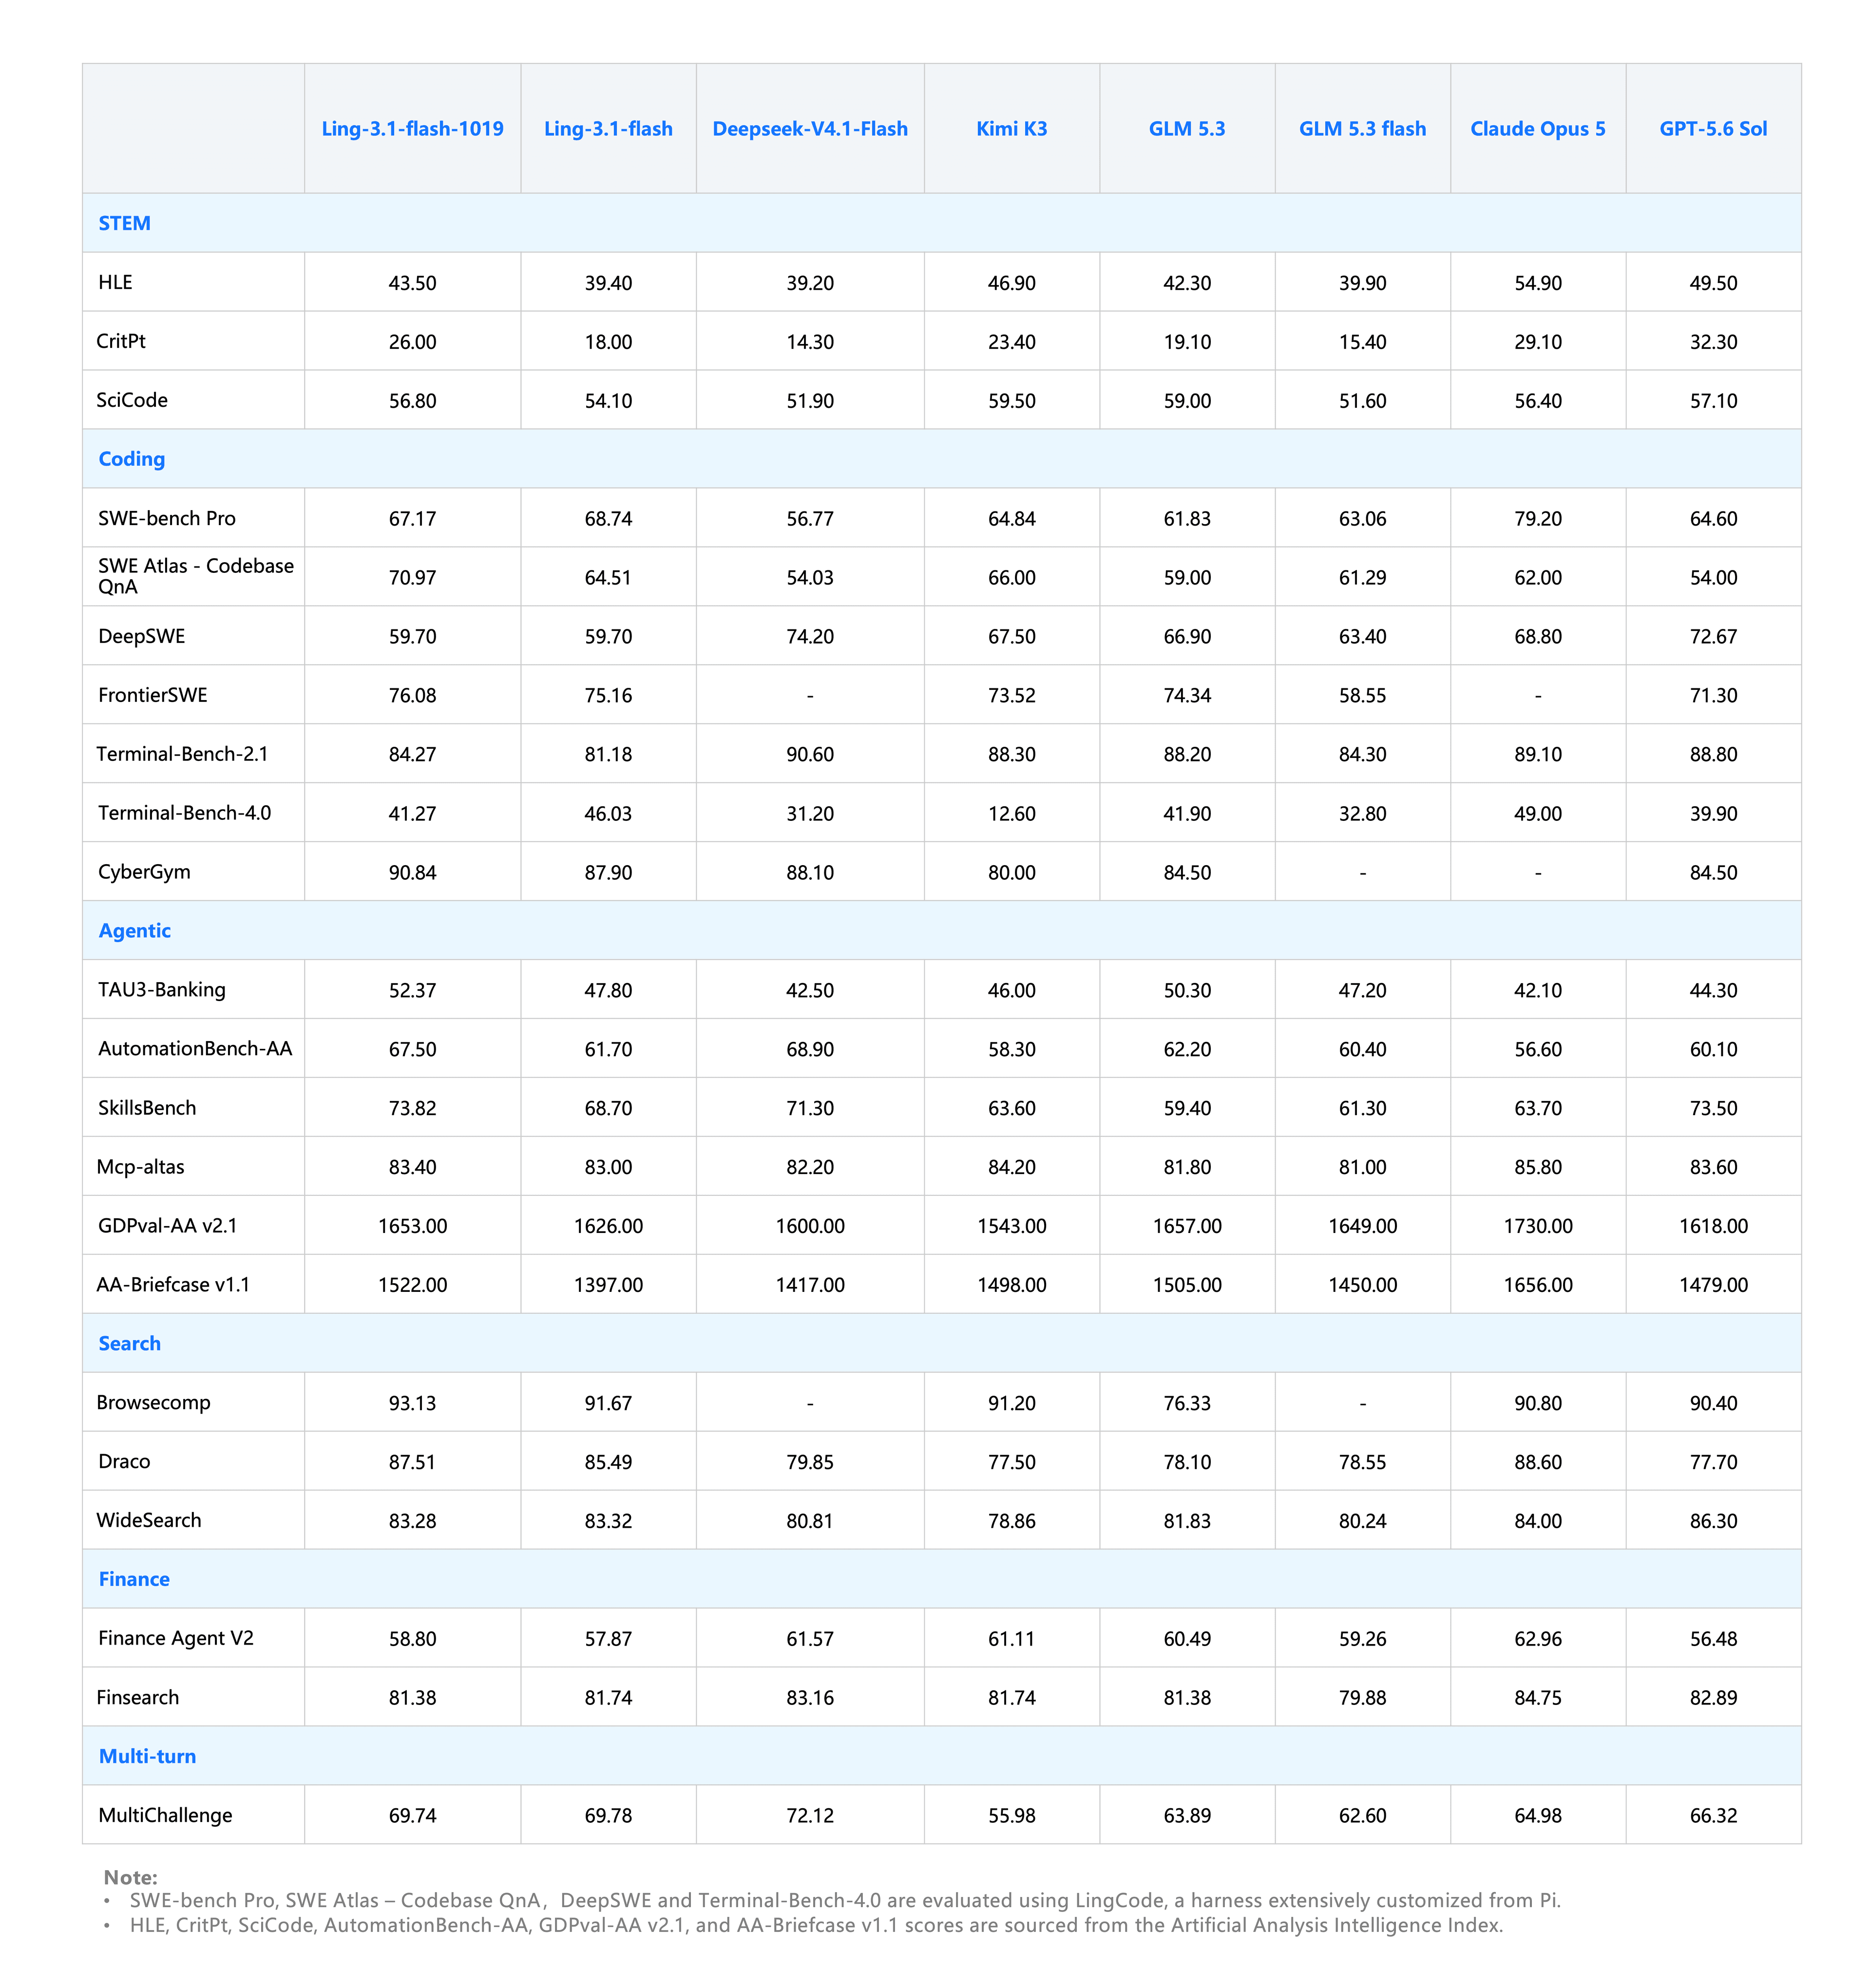
inclusionAI releases Ling-3.1-flash, an MIT MoE model
The new text model pairs a hybrid mixture-of-experts design with FP8 weights under a permissive license.
0 comments
No comments yet. Be the first to weigh in.