NVIDIA's Audex Unifies Audio Understanding and Speech
A new 30B mixture-of-experts model from NVIDIA handles both listening and speaking within a single audio-text architecture.
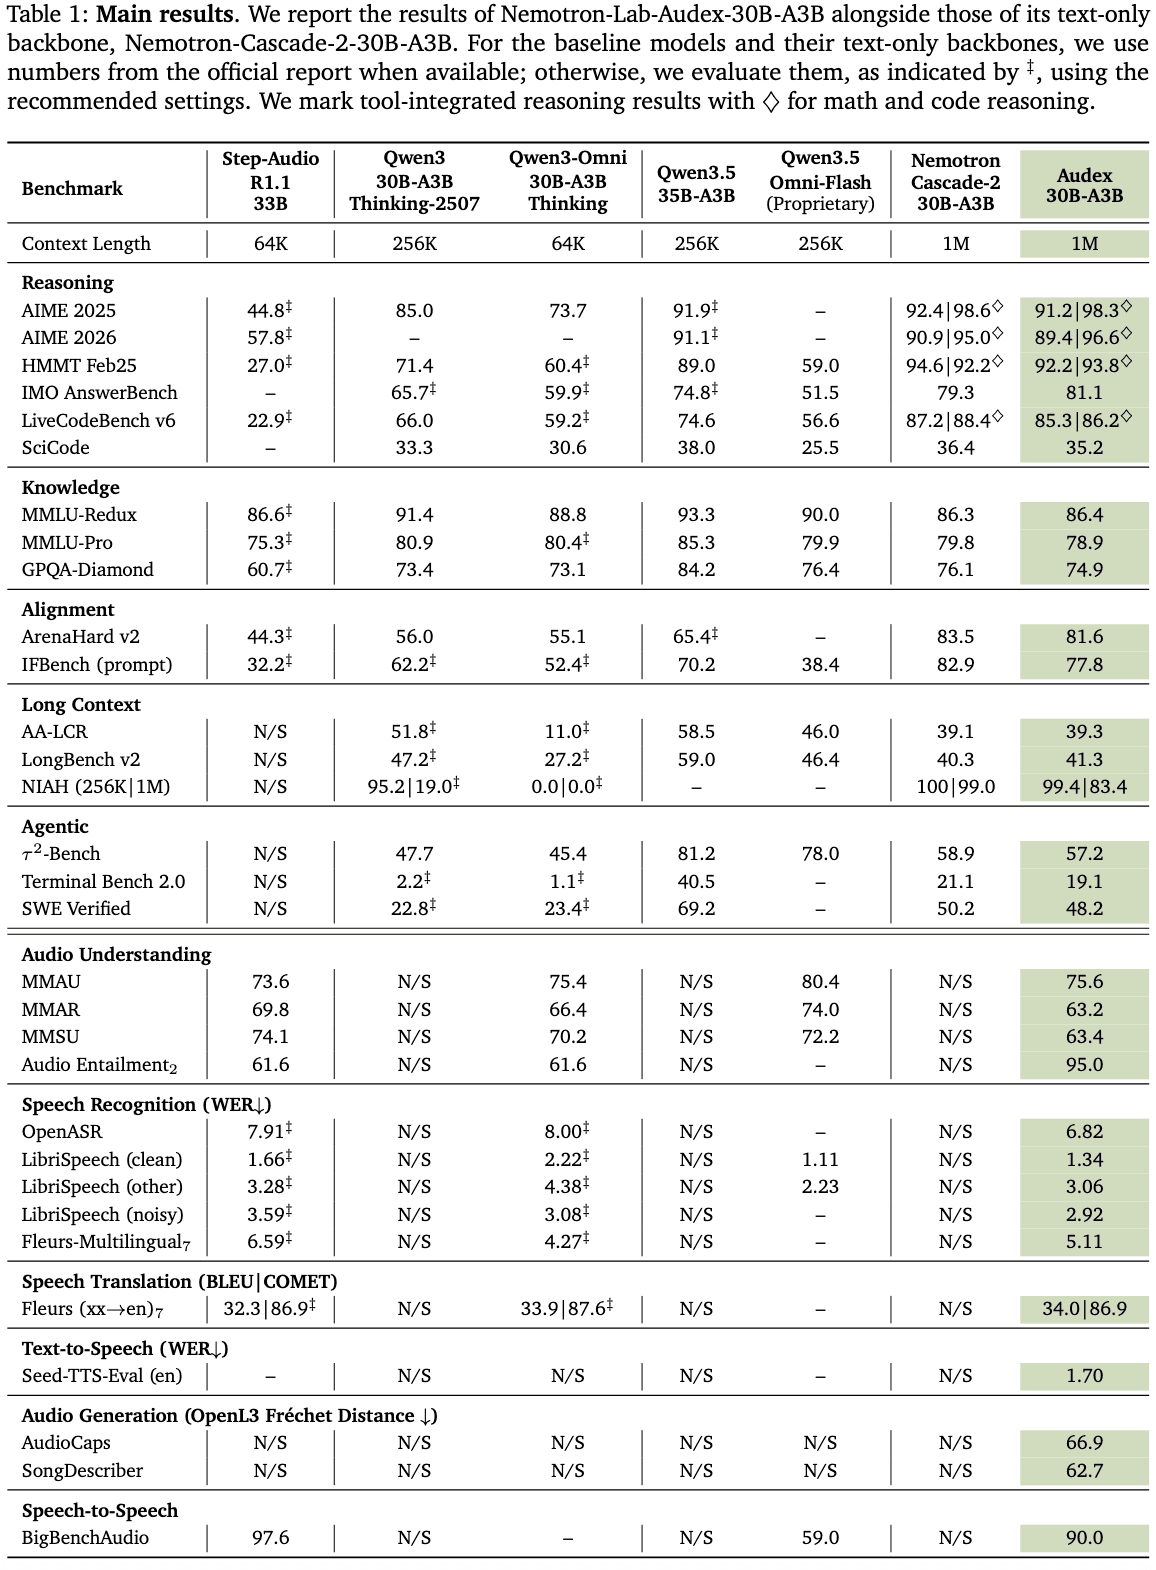
NVIDIA has released Nemotron-Labs-Audex-30B-A3B, a mixture-of-experts model that folds audio understanding and speech generation into a single system. According to the model's Hugging Face page, it is designed as a unified audio-text architecture — able to both interpret incoming audio and produce speech, rather than splitting those jobs across separate specialized models.
The model uses a mixture-of-experts design with roughly 30 billion total parameters but only about 3 billion active per token, the arrangement its "30B-A3B" name signals. That approach keeps inference costs closer to a small dense model while giving the network a larger pool of specialized capacity to draw from, a pattern NVIDIA and others have leaned on across recent Nemotron releases.
Why it matters
Most production audio stacks still chain together distinct components — a speech recognizer, a language model, and a separate text-to-speech engine. A single model spanning both comprehension and generation could simplify those pipelines and reduce the latency and error accumulation that comes from stitching parts together.
- Unified audio-text handling for both understanding and speech synthesis
- Mixture-of-experts efficiency: ~30B total, ~3B active parameters
- Reasoning listed among its capabilities alongside audio and TTS
The release ships under a custom NVIDIA license rather than a standard open-source one, so teams will want to check the terms before building on it. As an initial version, Audex sets a baseline for a family that NVIDIA appears positioned to iterate on.
Sources
- Visit
nvidia/Nemotron-Labs-Audex-30B-A3B
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
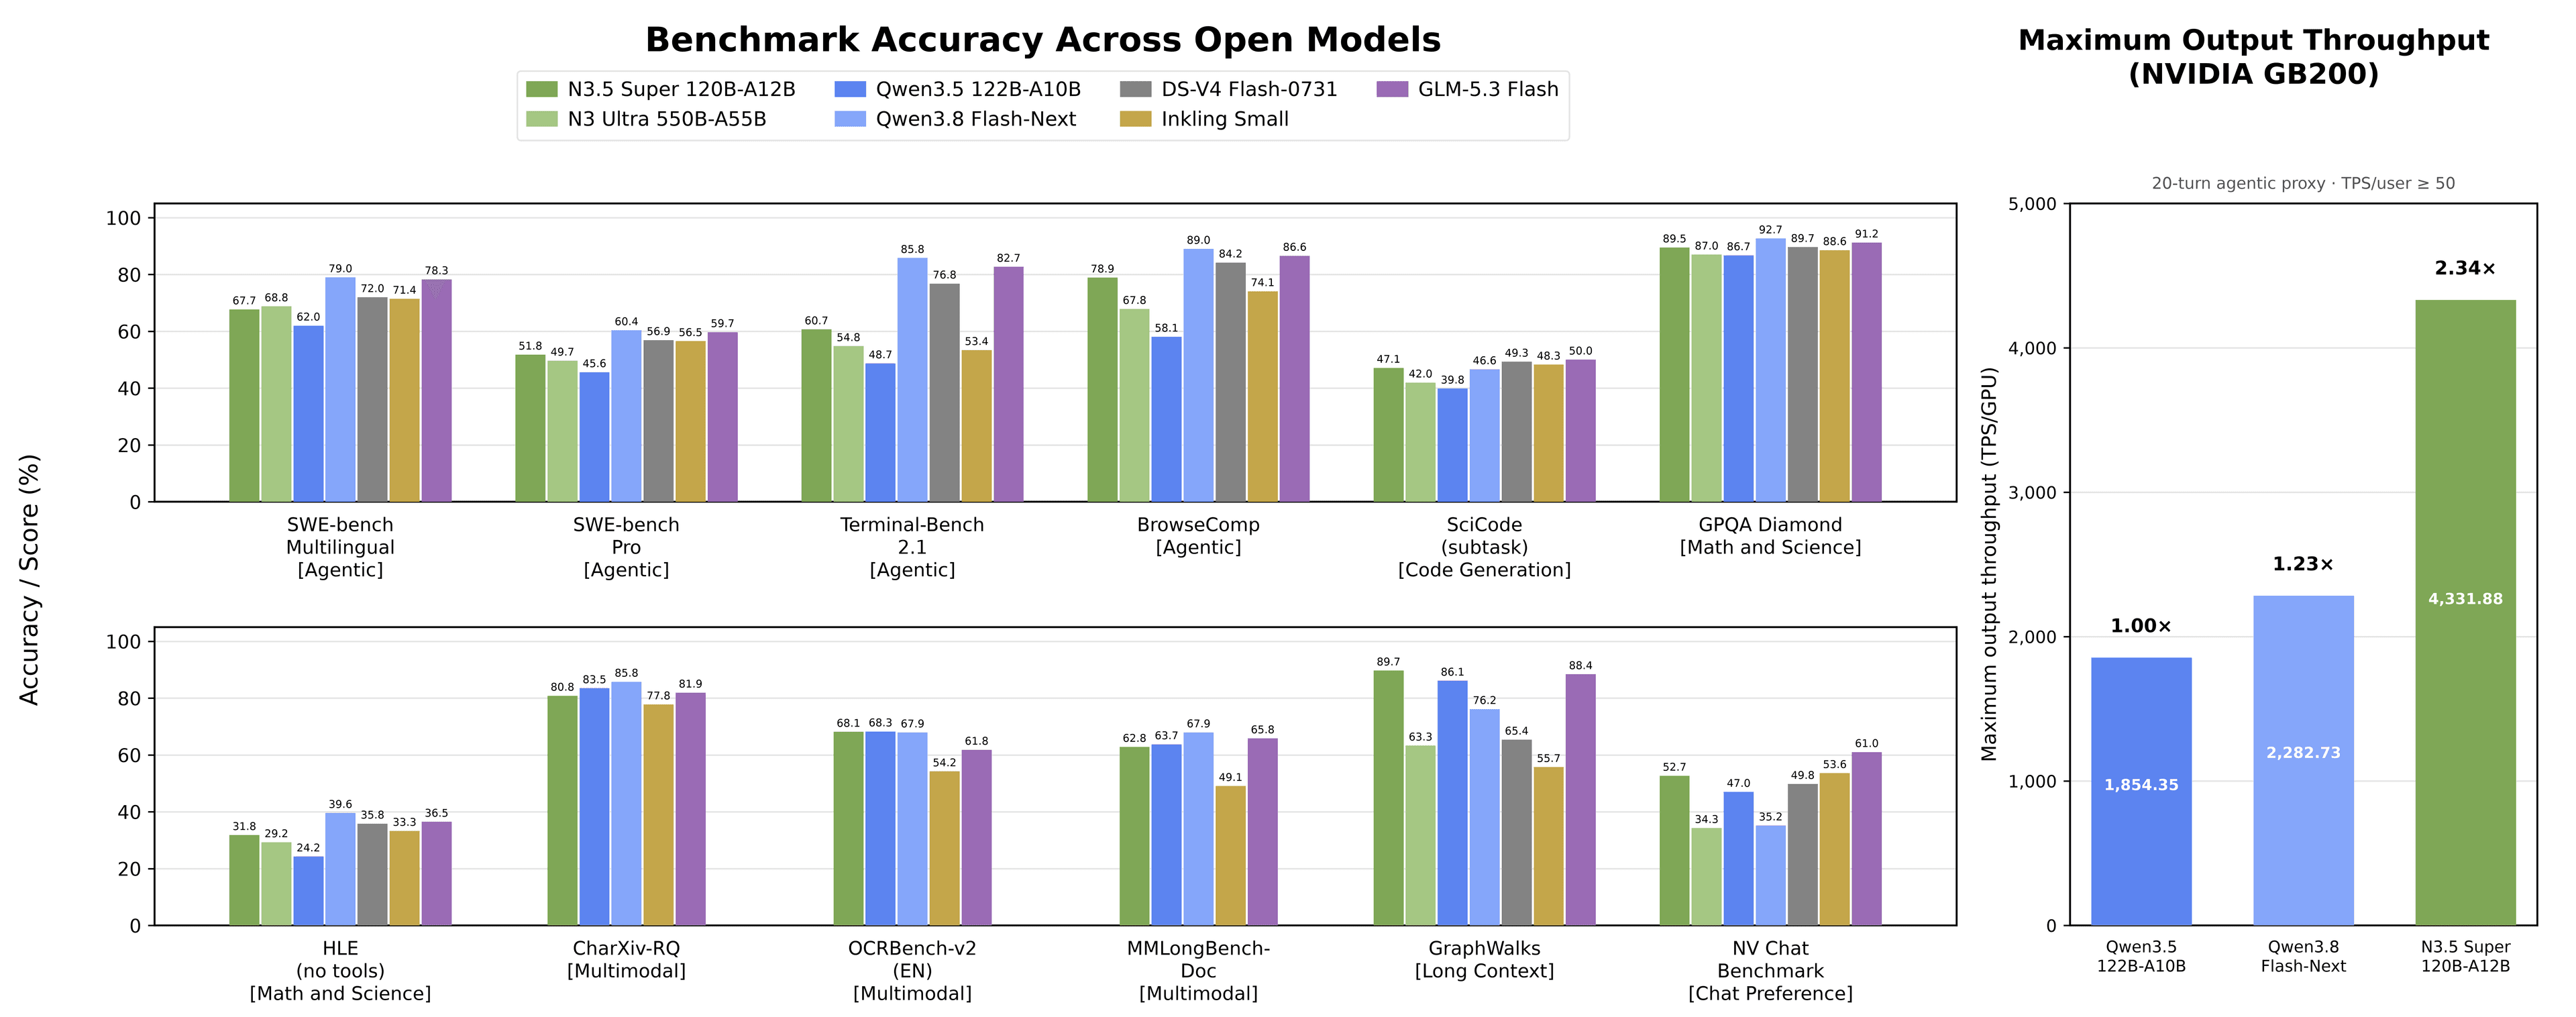
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
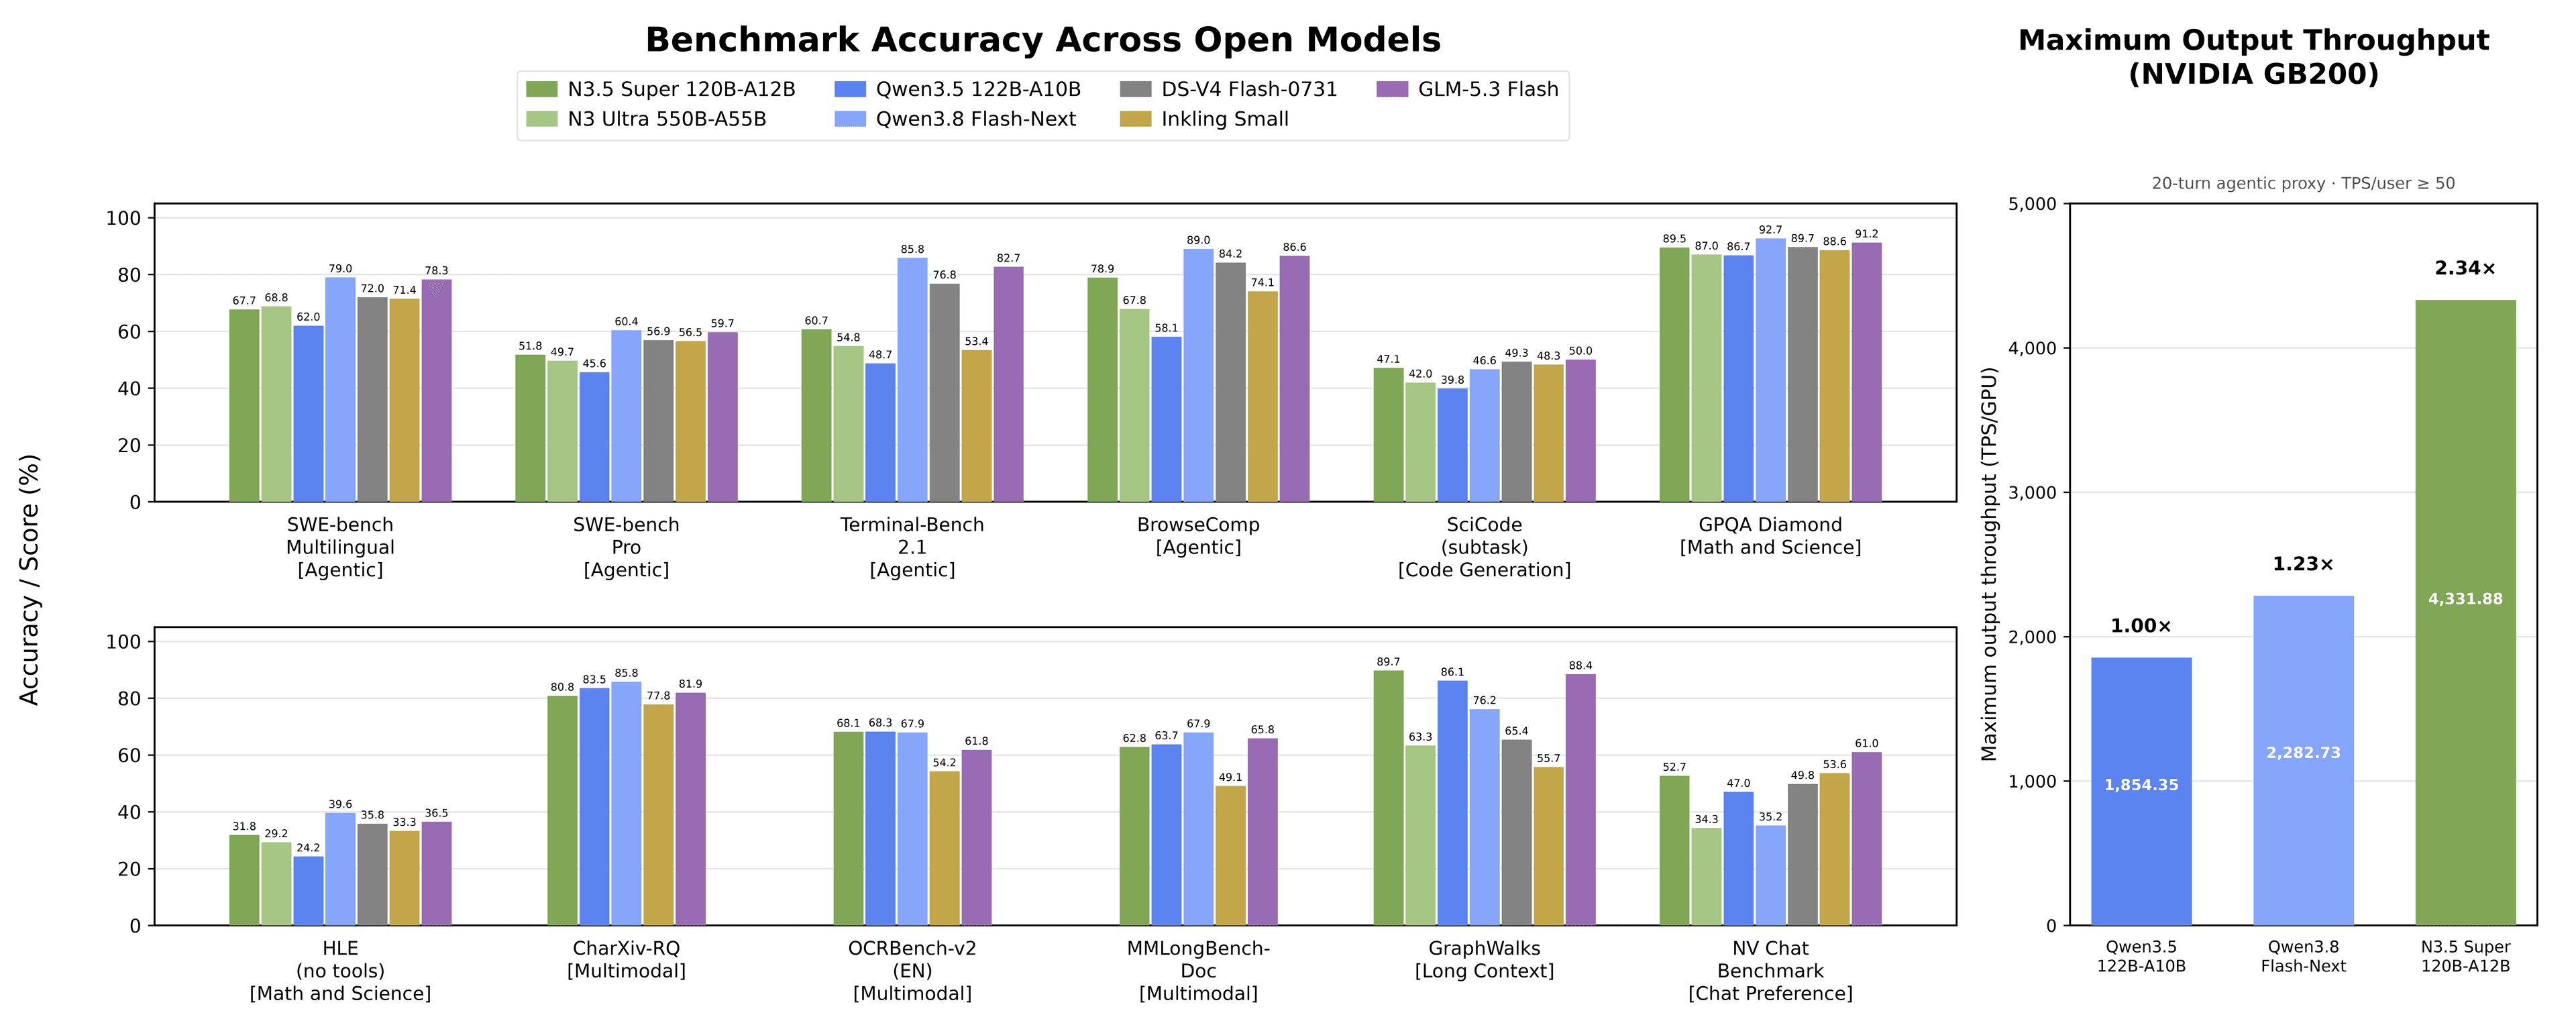
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.