NVIDIA's Parakeet ASR Tackles Multi-Speaker Audio
The 600-million-parameter model offers real-time speech-to-text with speaker diarization, built on the efficient FastConformer architecture.
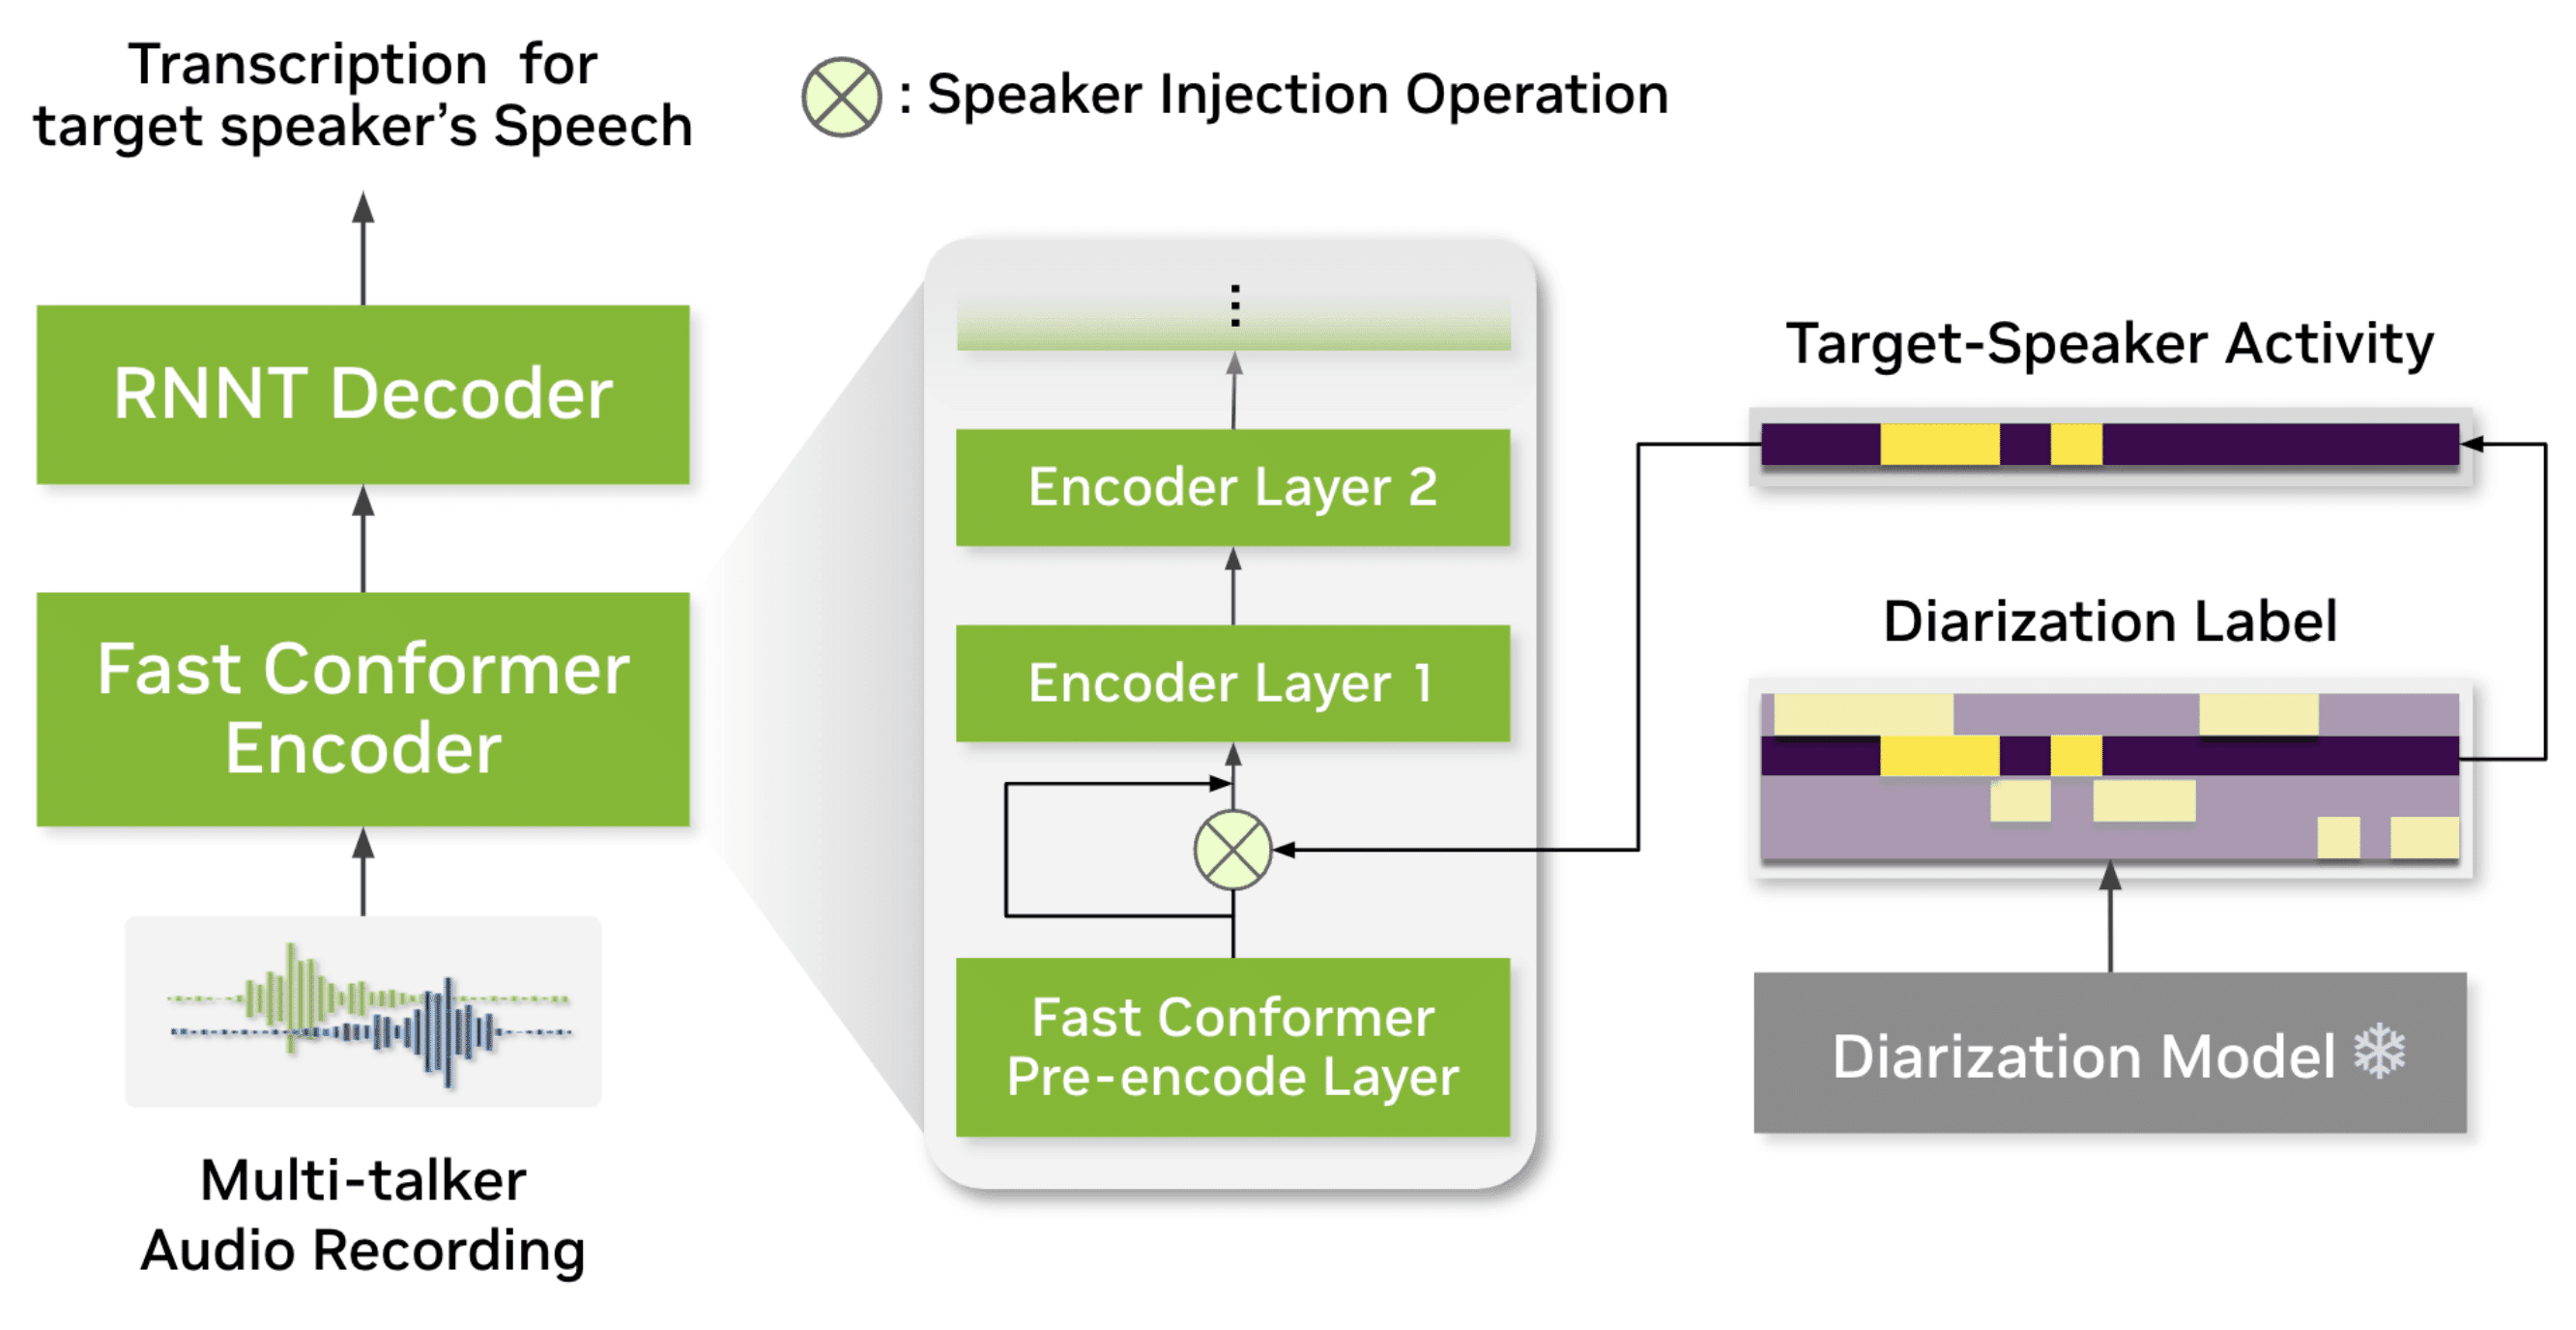
NVIDIA has released Multitalker Parakeet Streaming 0.6B, a new open model designed to transcribe conversations with multiple participants in real time. The 600-million-parameter model addresses a common challenge for automatic speech recognition (ASR) systems: accurately capturing dialogue when more than one person is speaking.
Real-Time Diarization
The model's key capability is speaker diarization—the process of determining "who spoke when." By integrating this directly into its architecture, Parakeet can attribute transcribed text to the correct speaker as the audio is being processed. This "streaming" functionality, built on the efficient FastConformer architecture, is essential for live applications where low latency is critical.
This approach is a notable step forward for creating more useful and accurate automated transcripts. Potential applications include:
- Live transcription and captioning for meetings and events.
- Analyzing multi-participant audio from call centers.
- Creating searchable records of interviews or panel discussions.
Available now on Hugging Face, the Multitalker Parakeet Streaming 0.6B model is released under the NVIDIA Open Model License Agreement. While not a traditional permissive open-source license, it allows for broad access and use of the model's weights. Its relatively compact size could enable deployment in a wide range of on-device or cloud environments.
Sources
- Visit
nvidia/multitalker-parakeet-streaming-0.6b-v1
Hugging Face
More from NVIDIA
All NVIDIA releases →NVIDIA's Cosmos 3 Brings Open Interactive World Models
The new open release pushes beyond passive video generation toward simulated worlds that respond to input.
NVIDIA Releases Cosmos 3 for World Simulation
The new open models push NVIDIA's world-foundation effort toward interactive, real-time video generation.
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
More in Speech → Text
All Speech → Text →
Haru-4B Brings Full-Duplex Speech to Six Languages
A compact 4-billion-parameter model handles real-time, two-way voice conversation across six languages in a single system.
ServiceNow Debuts Apriel Voice 27B, an Open Speech Model
The 27-billion-parameter preview unifies text-to-speech, transcription, and reasoning in a single open model.
IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
0 comments
No comments yet. Be the first to weigh in.