NVIDIA's Nemotron-3-Embed 8B tops RTEB retrieval test
The 8-billion-parameter text embedding model claims the number one overall spot on the RTEB benchmark, with an eye toward agentic retrieval.
NVIDIA has released Nemotron-3-Embed 8B, a text-embedding model that the company says ranks first overall on RTEB, a retrieval benchmark used to measure how well models turn text into vectors for search and reranking. The model is available on Hugging Face in a BF16 build at nvidia/Nemotron-3-Embed-8B-BF16.
Embedding models are the quiet workhorses behind modern retrieval systems. They convert documents and queries into numerical representations so that a system can find the most relevant passages by measuring similarity. Better embeddings mean fewer irrelevant hits and more grounded answers, which is why retrieval quality has become a competitive battleground.
Why it matters
NVIDIA frames the release around what it calls agentic retrieval — the idea that autonomous AI agents increasingly depend on fetching accurate context across many steps of a task. A strong embedding model is the foundation of retrieval-augmented generation (RAG) pipelines, and a top RTEB placement is a signal that Nemotron-3-Embed could slot in as a drop-in upgrade for teams building search and agent workflows.
A few practical notes from the announcement:
- The model carries 8 billion parameters and is offered in BF16 precision.
- NVIDIA reports a #1 overall standing on the RTEB retrieval benchmark.
- It is positioned specifically for agentic and RAG-style retrieval use cases.
As always, benchmark leadership is a snapshot rather than a guarantee, and rankings shift as new models arrive. The model is distributed under a custom NVIDIA license, so teams should review the terms before deploying it in production. Still, for developers already invested in NVIDIA's Nemotron ecosystem, a competitive embedding option rounds out the retrieval stack.
Sources
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
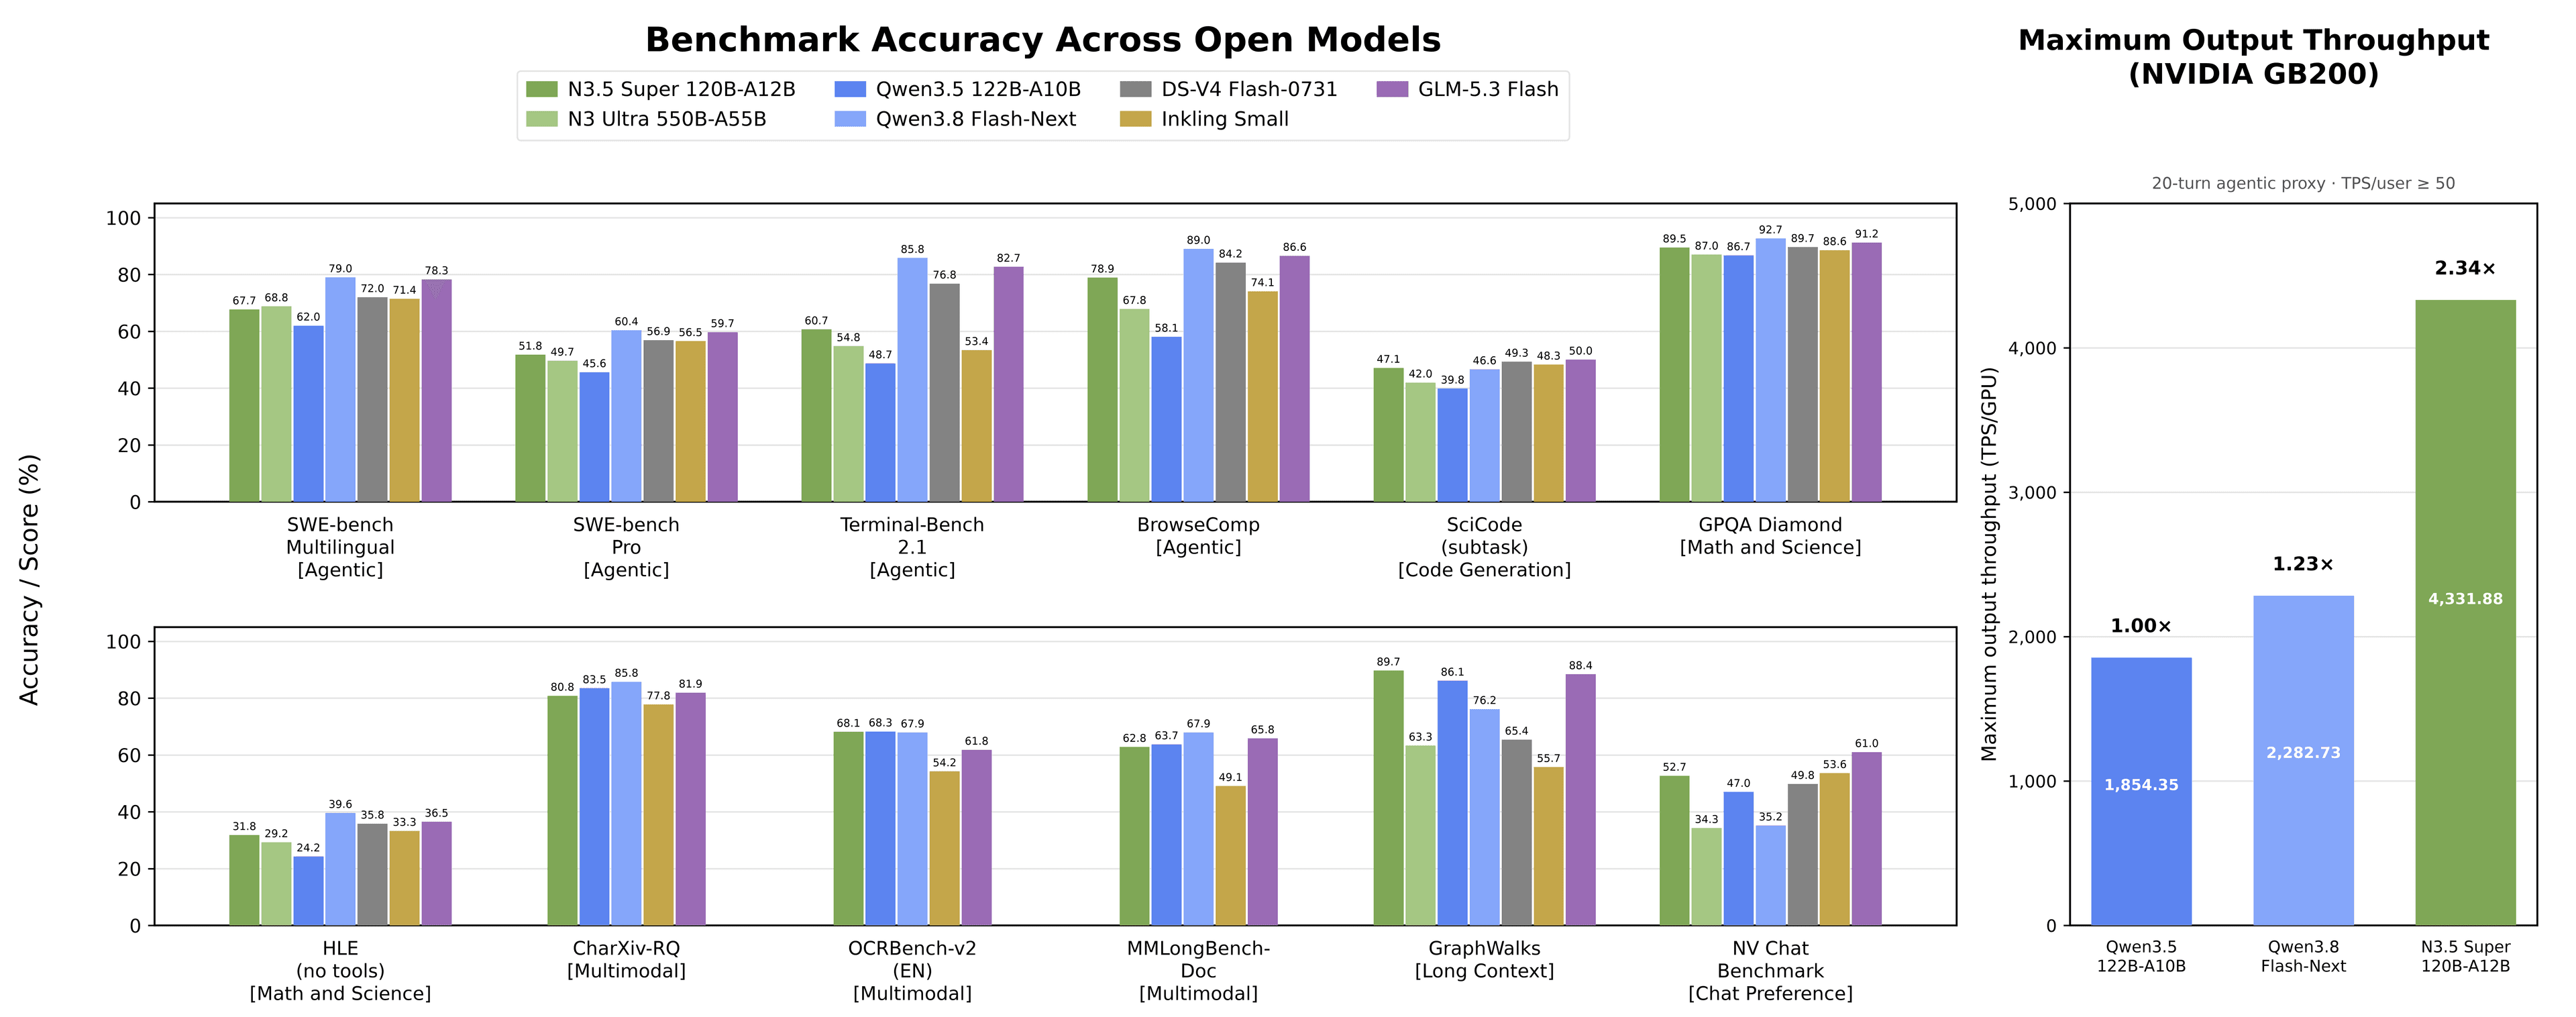
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
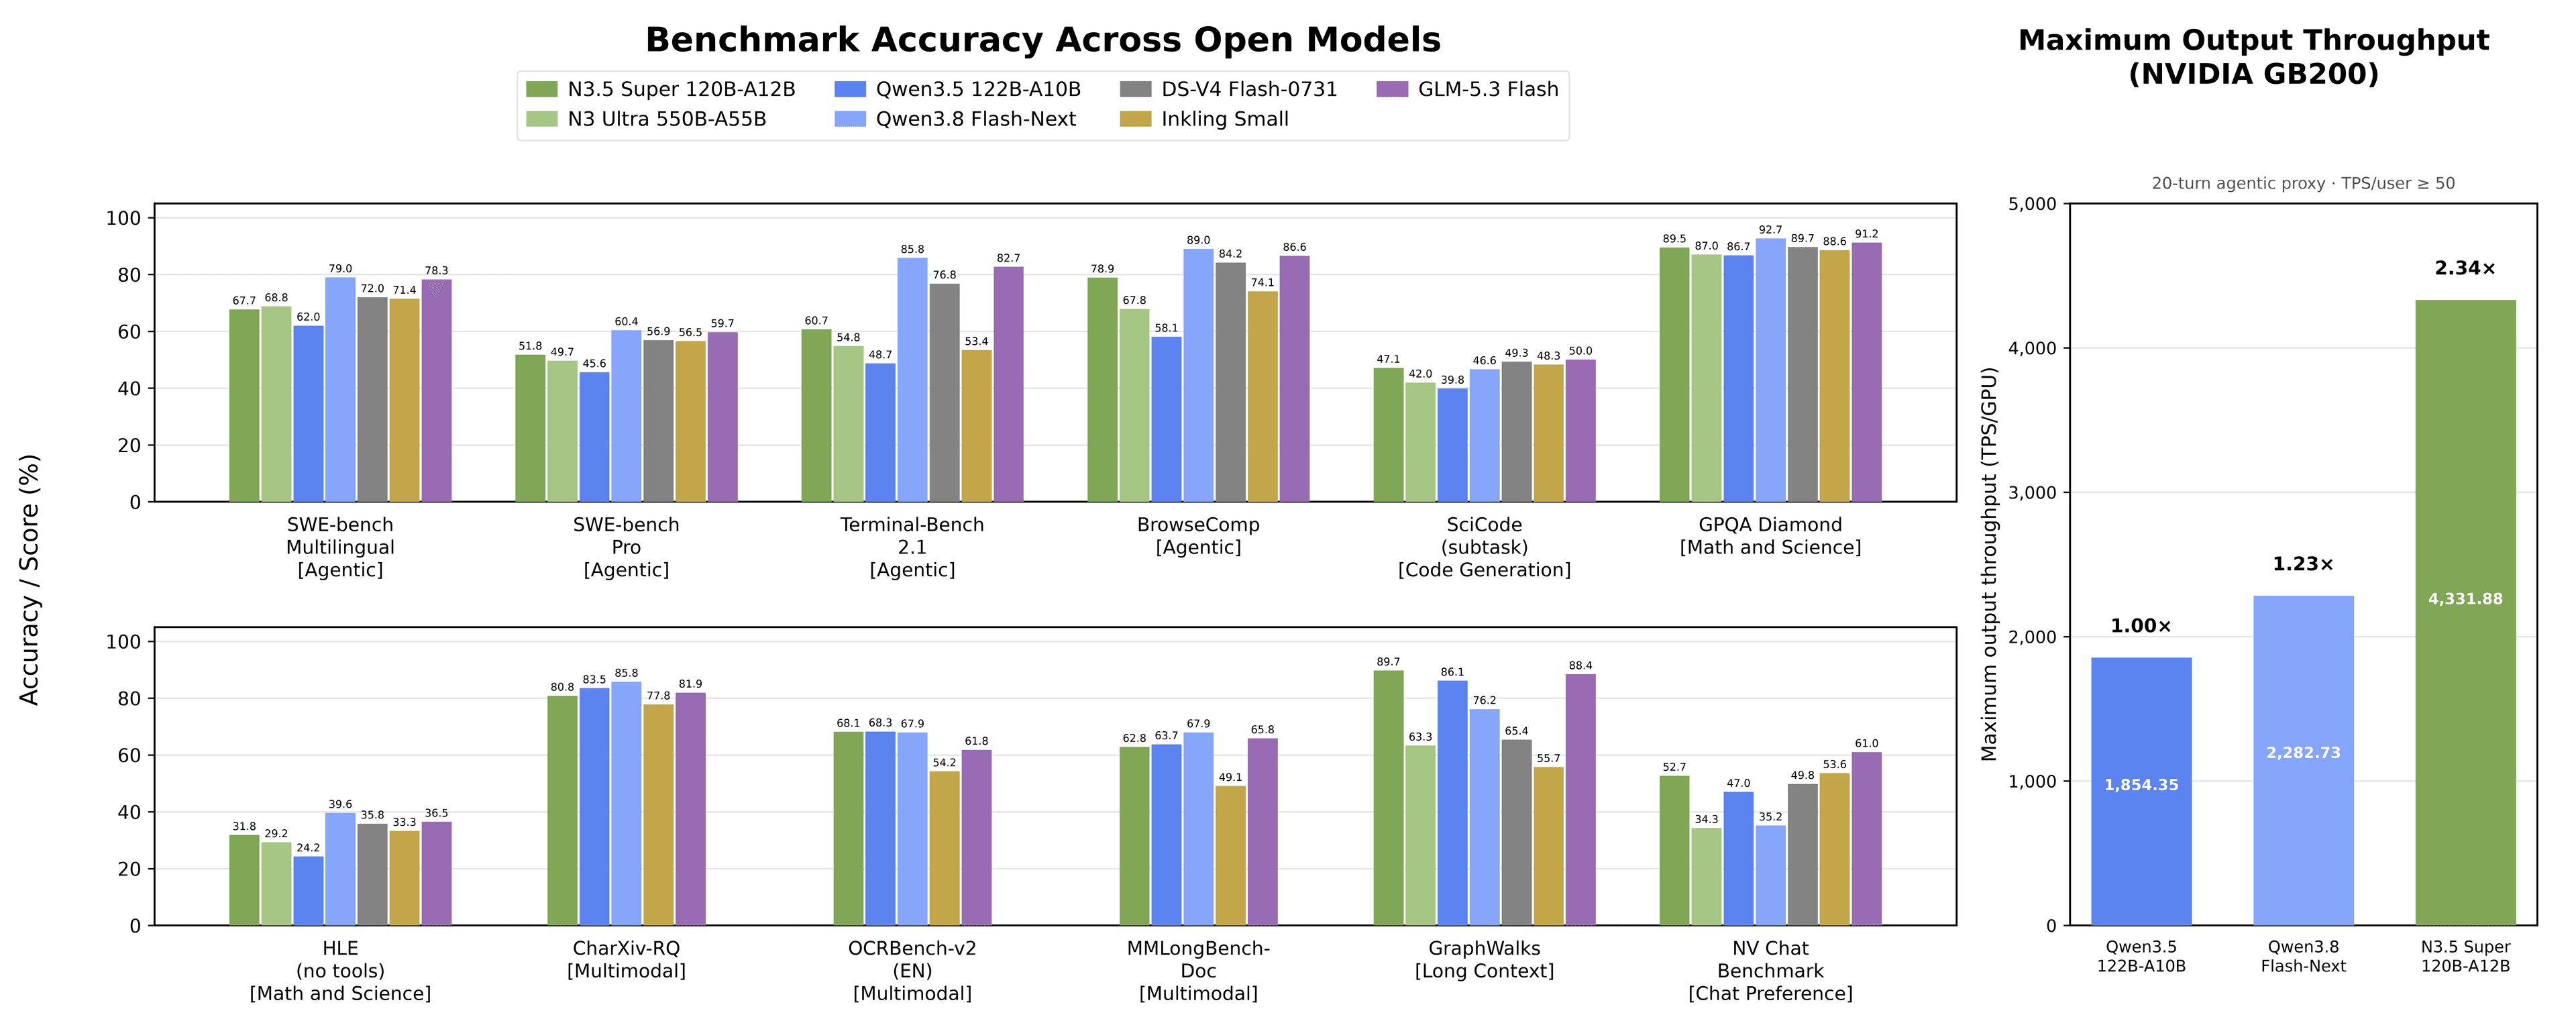
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Embeddings
All Embeddings →
EmbeddingGemma 2 Expands to Any Modality
Google DeepMind's compact embedding model now spans text, vision, audio, and video in a single vector space.
NeoMME: a single-tower multilingual multimodal encoder
A new open encoder aims to make document retrieval faster by treating text and images natively in one model.
H Company's NeoMME rethinks visual document retrieval
A single-tower multimodal encoder aims to make multilingual document search cheaper to fine-tune and run.
0 comments
No comments yet. Be the first to weigh in.