NeoMME: a single-tower multilingual multimodal encoder
A new open encoder aims to make document retrieval faster by treating text and images natively in one model.
A new open model called NeoMME has arrived, positioned as a "multimodal-native and multilingual encoder" designed for efficient document retrieval and general-purpose embeddings. The details are laid out in the team's Hugging Face blog post.
The headline design choice is a single-tower architecture. Rather than pairing separate encoders for text and images—the classic two-tower approach used by many retrieval systems—NeoMME processes modalities within one model. That can simplify deployment and, in principle, produce more unified representations across text and visual document content.
Why it matters
Document retrieval is one of the workhorse tasks behind retrieval-augmented generation, search, and enterprise knowledge tools. Two threads make NeoMME worth watching:
- Multimodal-native handling, which targets documents that mix text and imagery, such as scanned pages, slides, and screenshots.
- Multilingual coverage, which broadens usefulness beyond English-centric pipelines.
The release lands as embeddings and retrieval encoders become a competitive open-source category in their own right, distinct from the larger generative models that dominate headlines. Efficiency claims in this space matter because embedding models often run at scale, indexing large corpora where latency and cost add up quickly.
As with any initial release, the practical test will be independent benchmarking and real-world integration. For now, the model is available to explore, with full specifics—including licensing terms listed as "other"—documented in the announcement.
Sources
- Visit
NeoMME: an efficient Multimodal-native and Multilingual Encoder
Announcement
More from OpenBMB
All OpenBMB releases →
OpenBMB's MiniCPM-V 4.7 brings MoE to vision models
The new 35B-parameter vision-language model activates just 3B parameters per pass, aiming for efficiency without sacrificing capability.
MiniCPM-V 4.7 brings a 35B MoE vision model on-device
OpenBMB's latest multimodal release activates just 3B parameters per token, aiming to keep capable image understanding local.
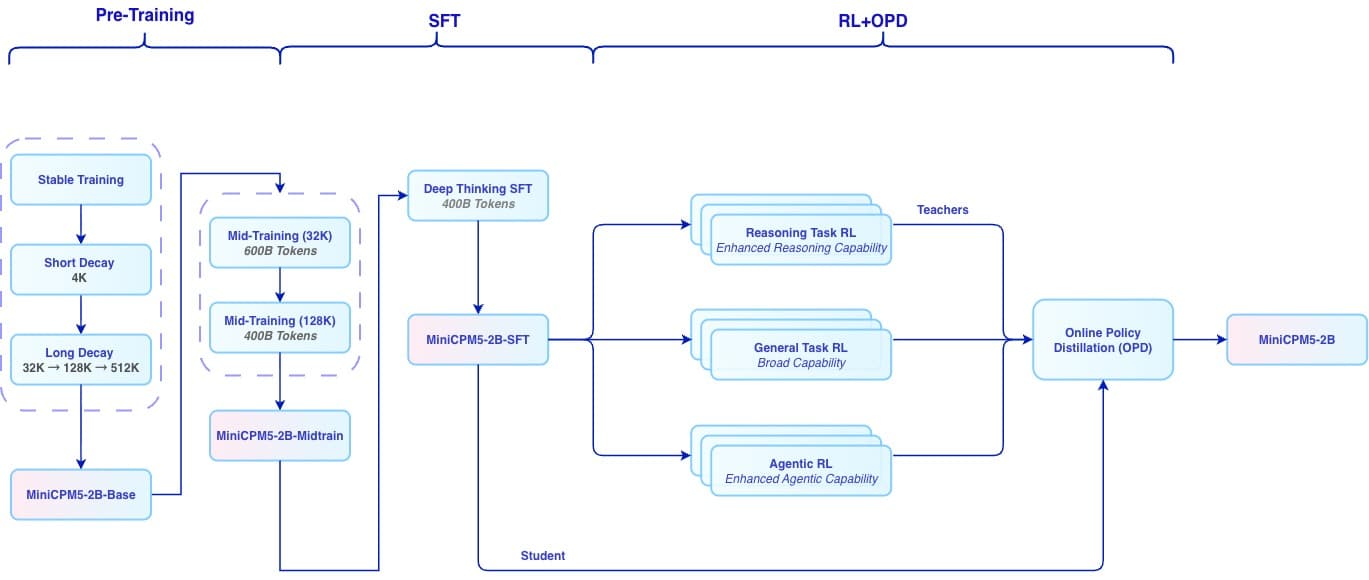
OpenBMB's MiniCPM5-2B targets on-device AI
The compact 2-billion-parameter model adds long-context handling and tool-calling in a footprint small enough to run locally.
More in Embeddings
All Embeddings →
EmbeddingGemma 2 Expands to Any Modality
Google DeepMind's compact embedding model now spans text, vision, audio, and video in a single vector space.
H Company's NeoMME rethinks visual document retrieval
A single-tower multimodal encoder aims to make multilingual document search cheaper to fine-tune and run.
Tencent's WeMM-Embedding-9B Unifies Text, Image and Video
The WeChat team releases a 9-billion-parameter multimodal embedding model that maps three modalities into one shared vector space.
0 comments
No comments yet. Be the first to weigh in.