inclusionAI Tunes Ling-3.0-flash for Finance
A finance-focused variant of the Ling-3.0-flash MoE model targets financial research and agentic tool use.
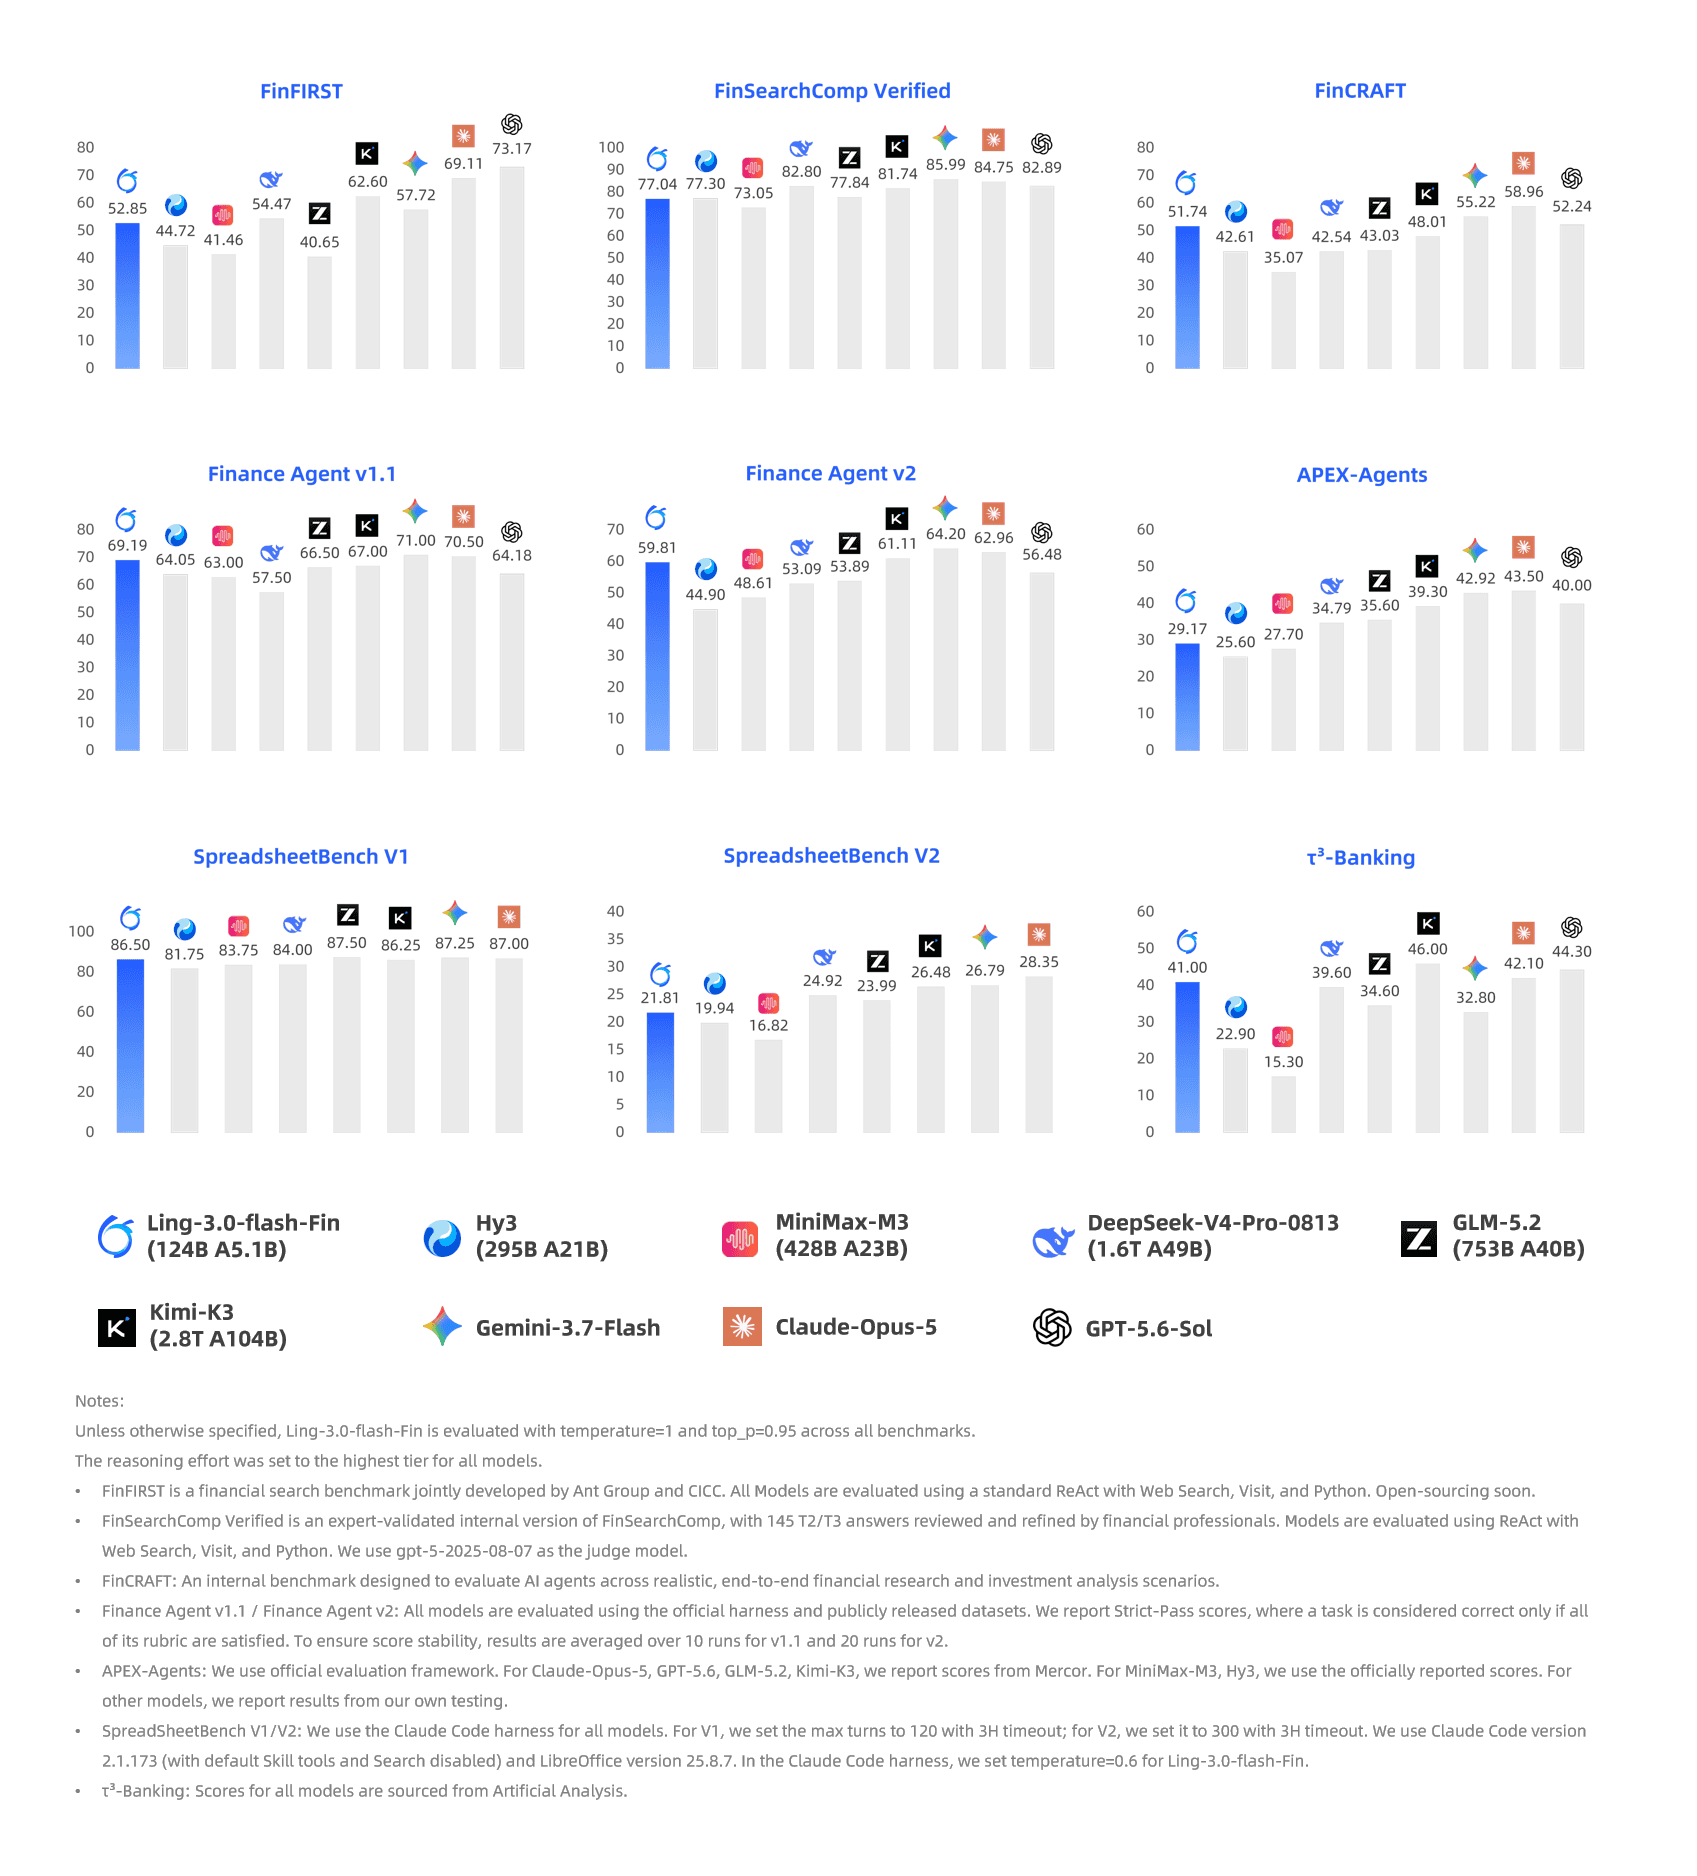
inclusionAI has released Ling-3.0-flash-Fin, a finance-focused variant of its Ling-3.0-flash language model. The new build is aimed squarely at financial research and agentic tool use, according to the model's Hugging Face page.
Like its base model, Ling-3.0-flash-Fin uses a mixture-of-experts (MoE) architecture, which activates only a subset of the network's parameters per query. That design lets developers pursue larger effective model capacity while keeping inference costs in check — a practical consideration for domain deployments where models may be run repeatedly across documents and data feeds.
Why it matters
Finance is one of the more demanding proving grounds for language models: the work rewards precise reasoning, structured document handling, and the ability to chain tools such as calculators, retrieval systems, and data APIs. A model explicitly tuned for these tasks signals inclusionAI's interest in vertical, workflow-oriented AI rather than general chat.
Key points from the release:
- Built on the Ling-3.0-flash family with an MoE design
- Oriented toward financial research and agentic tool use
- Distributed on Hugging Face under a custom ("other") license
The repository does not publish parameter counts, context length, or benchmark figures, so teams evaluating the model will want to test it against their own financial tasks. The custom license also warrants a close read before any commercial deployment.
Sources
- Visit
inclusionAI/Ling-3.0-flash-Fin
Hugging Face
More from inclusionAI
All inclusionAI releases →
inclusionAI releases Ling-3.1-flash under MIT license
A new hybrid mixture-of-experts text model arrives on Hugging Face with permissive licensing and a focus on fast inference.
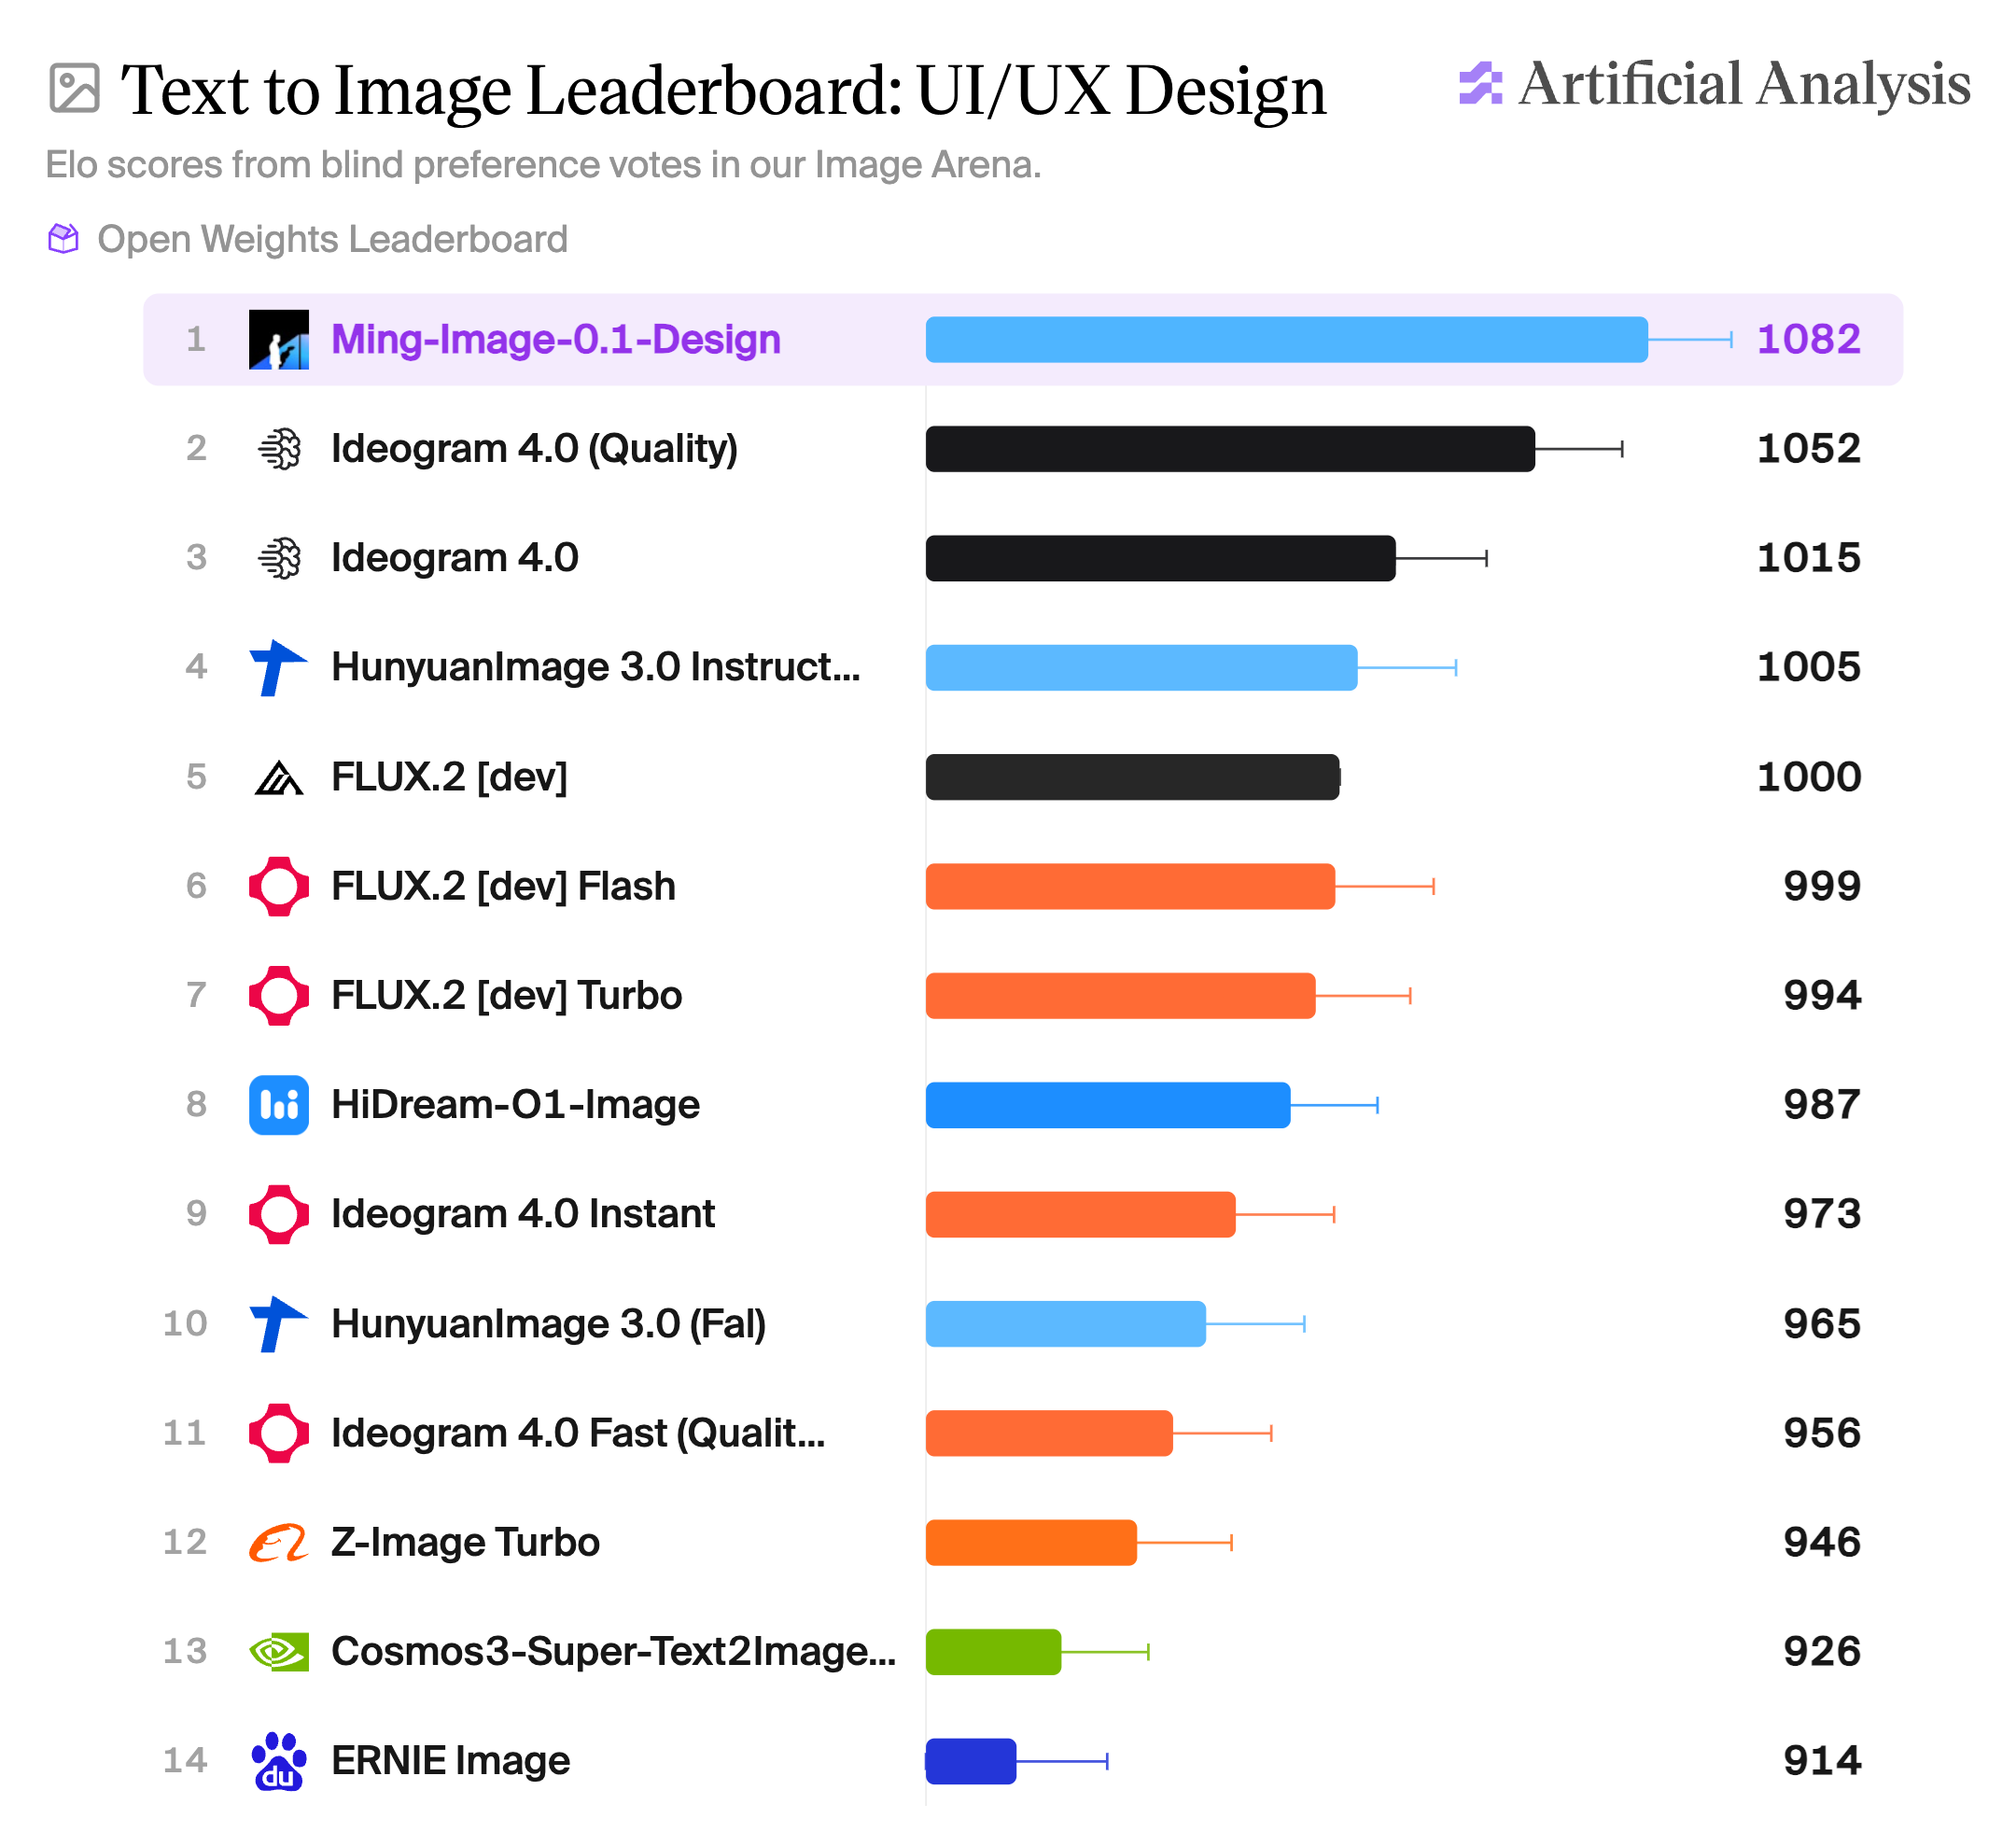
inclusionAI's Ming-Image targets graphic design
A new MIT-licensed text-to-image model leans into legible text rendering and transparent RGBA output for design work.
LLaDA-UI Brings Diffusion Decoding to GUI Agents
inclusionAI's 16.7B MoE vision-language model uses block-wise diffusion to drive graphical interface tasks.
More in Text / LLM
All Text / LLM →
DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
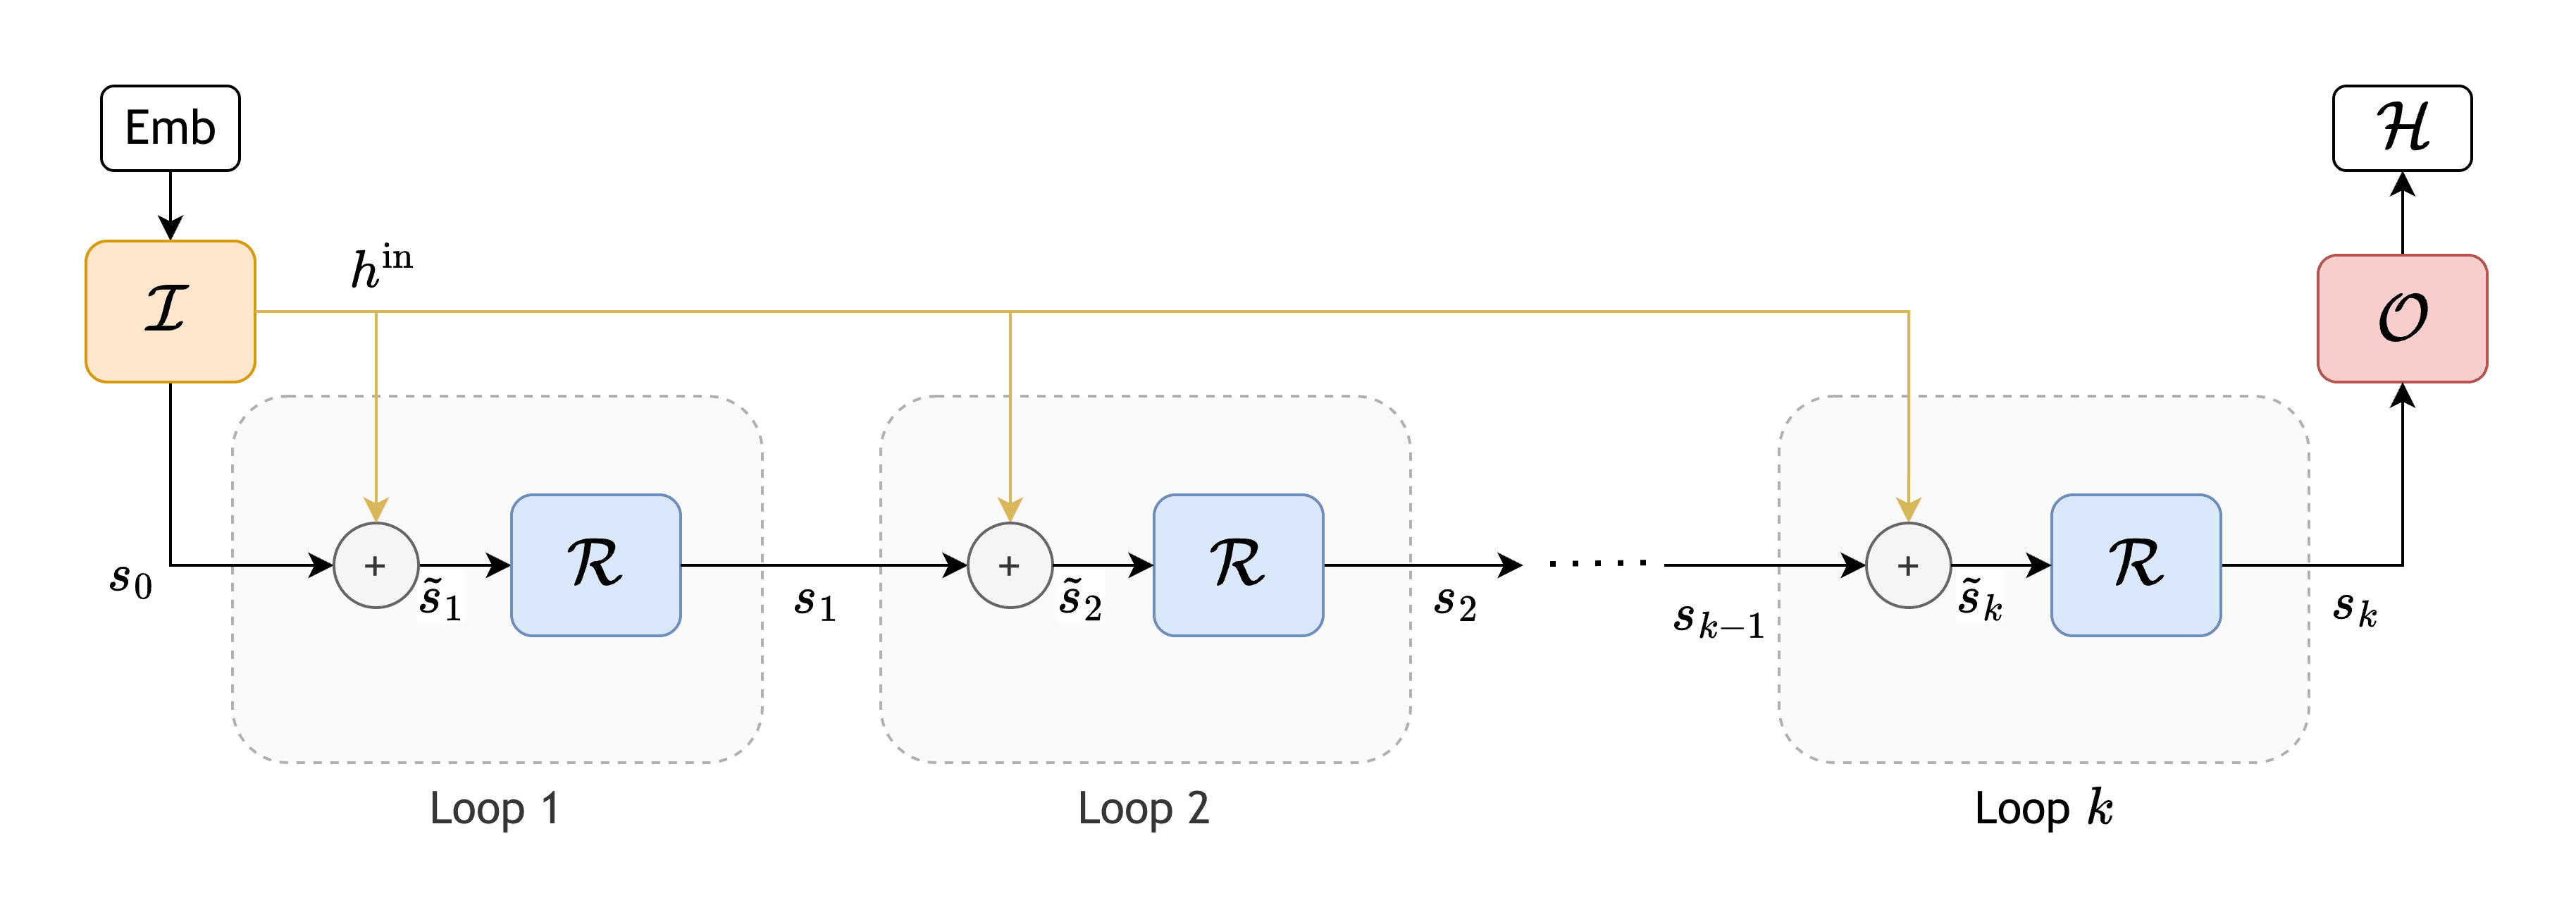
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.