NVIDIA's Nemotron 3.5 Parse Targets Document OCR
A new vision-language model from NVIDIA is tuned specifically for reading and structuring documents rather than general chat.
NVIDIA has published Nemotron 3.5 Parse, a vision-language model built for a focused job: reading documents and turning their visual layout into structured, machine-usable text. The model is available on Hugging Face under a custom NVIDIA license.
Unlike general-purpose multimodal chat models, this release is positioned squarely around optical character recognition and document parsing. That makes it a tool for extracting text, tables, and layout from scanned pages, PDFs, and images rather than for open-ended conversation.
Why it matters
Document understanding is one of the most practical and commercially valuable corners of the AI stack. Enterprises process invoices, forms, contracts, and reports at scale, and accurate parsing is often the bottleneck before any downstream automation can happen.
- Specialized for OCR and structured document extraction
- Vision-language architecture, so it reasons over page layout as well as text
- Distributed openly on Hugging Face for developers to test and integrate
By releasing a parsing-focused model under the Nemotron banner, NVIDIA is extending its family into a niche where precision matters more than breadth. Teams evaluating it should check the license terms and run their own benchmarks against existing OCR pipelines, since NVIDIA has not published detailed parameter counts or context specifications with this initial listing.
Sources
- Visit
nvidia/Nemotron-3.5-Parse
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
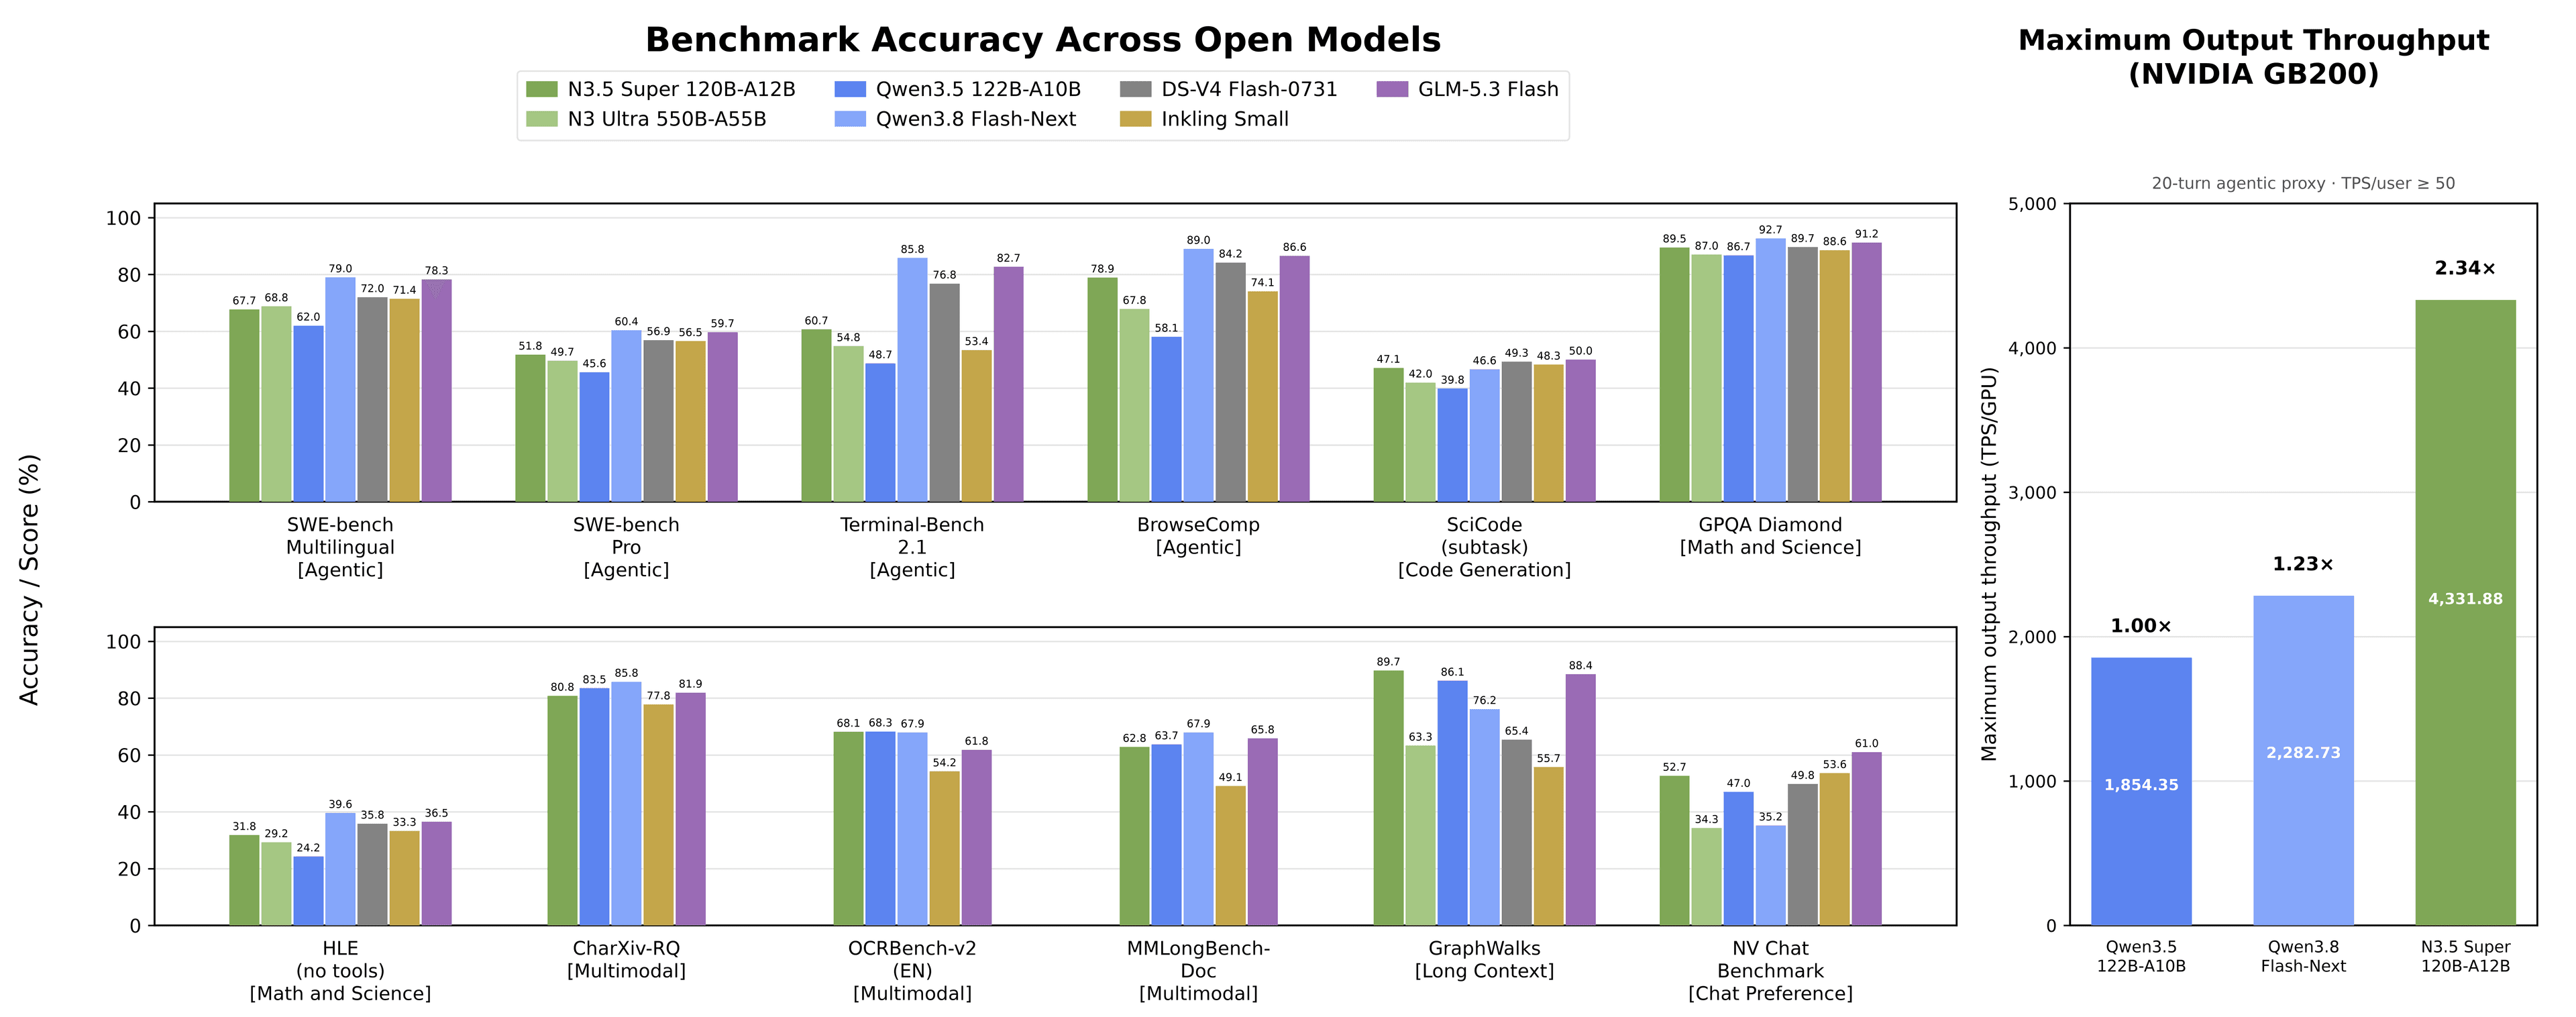
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
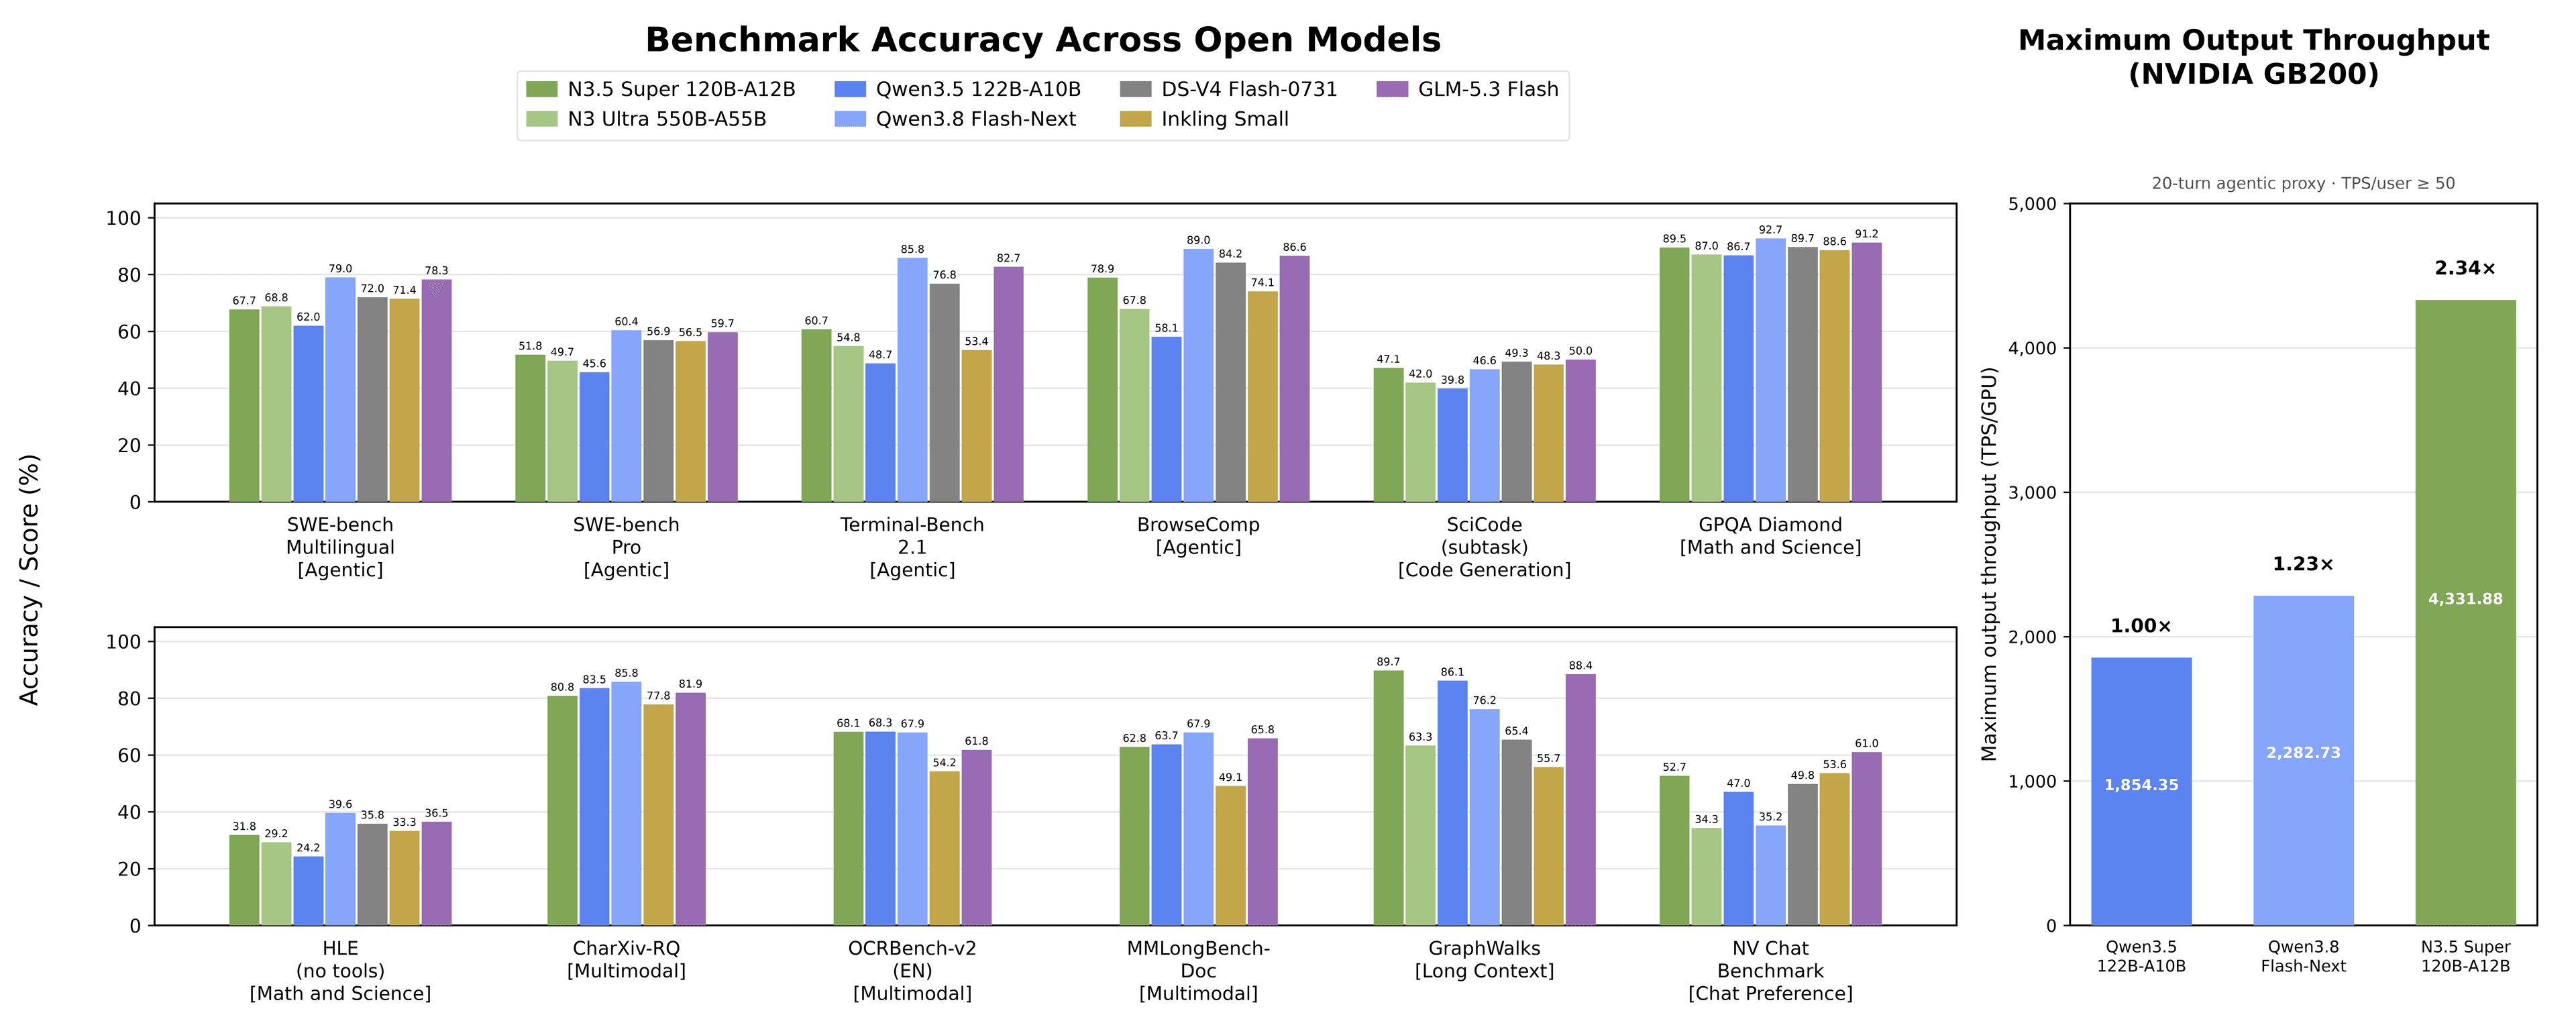
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Vision-Language
All Vision-Language →
MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.

DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
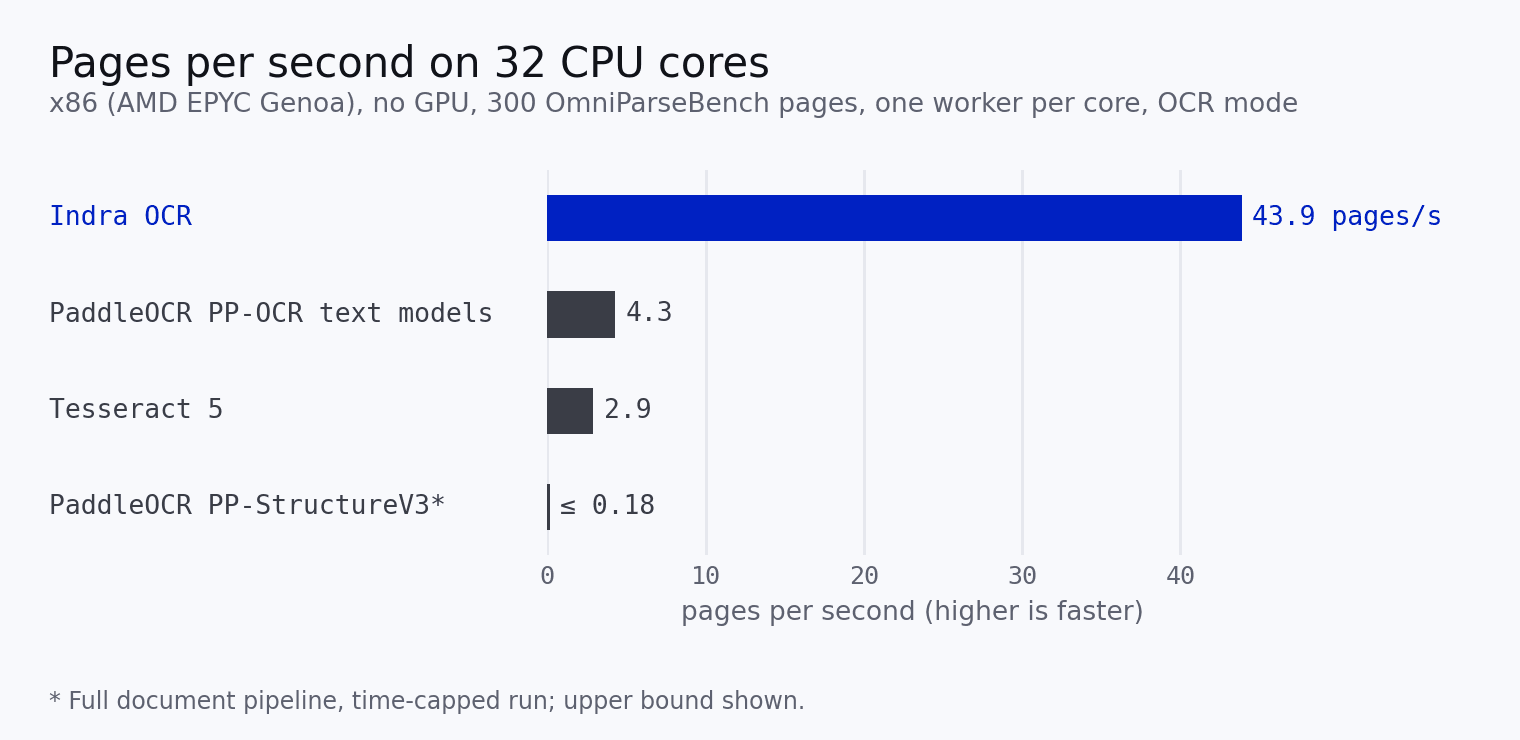
Indra OCR brings CPU-friendly document parsing
A new open vision-language model targets layout, handwriting and multilingual text extraction without a GPU.
0 comments
No comments yet. Be the first to weigh in.