inclusionAI/Text / LLMDatacenter
inclusionAI releases Ling-3.1-flash under MIT license
A new hybrid mixture-of-experts text model arrives on Hugging Face with permissive licensing and a focus on fast inference.

Company
Releases
A new hybrid mixture-of-experts text model arrives on Hugging Face with permissive licensing and a focus on fast inference.
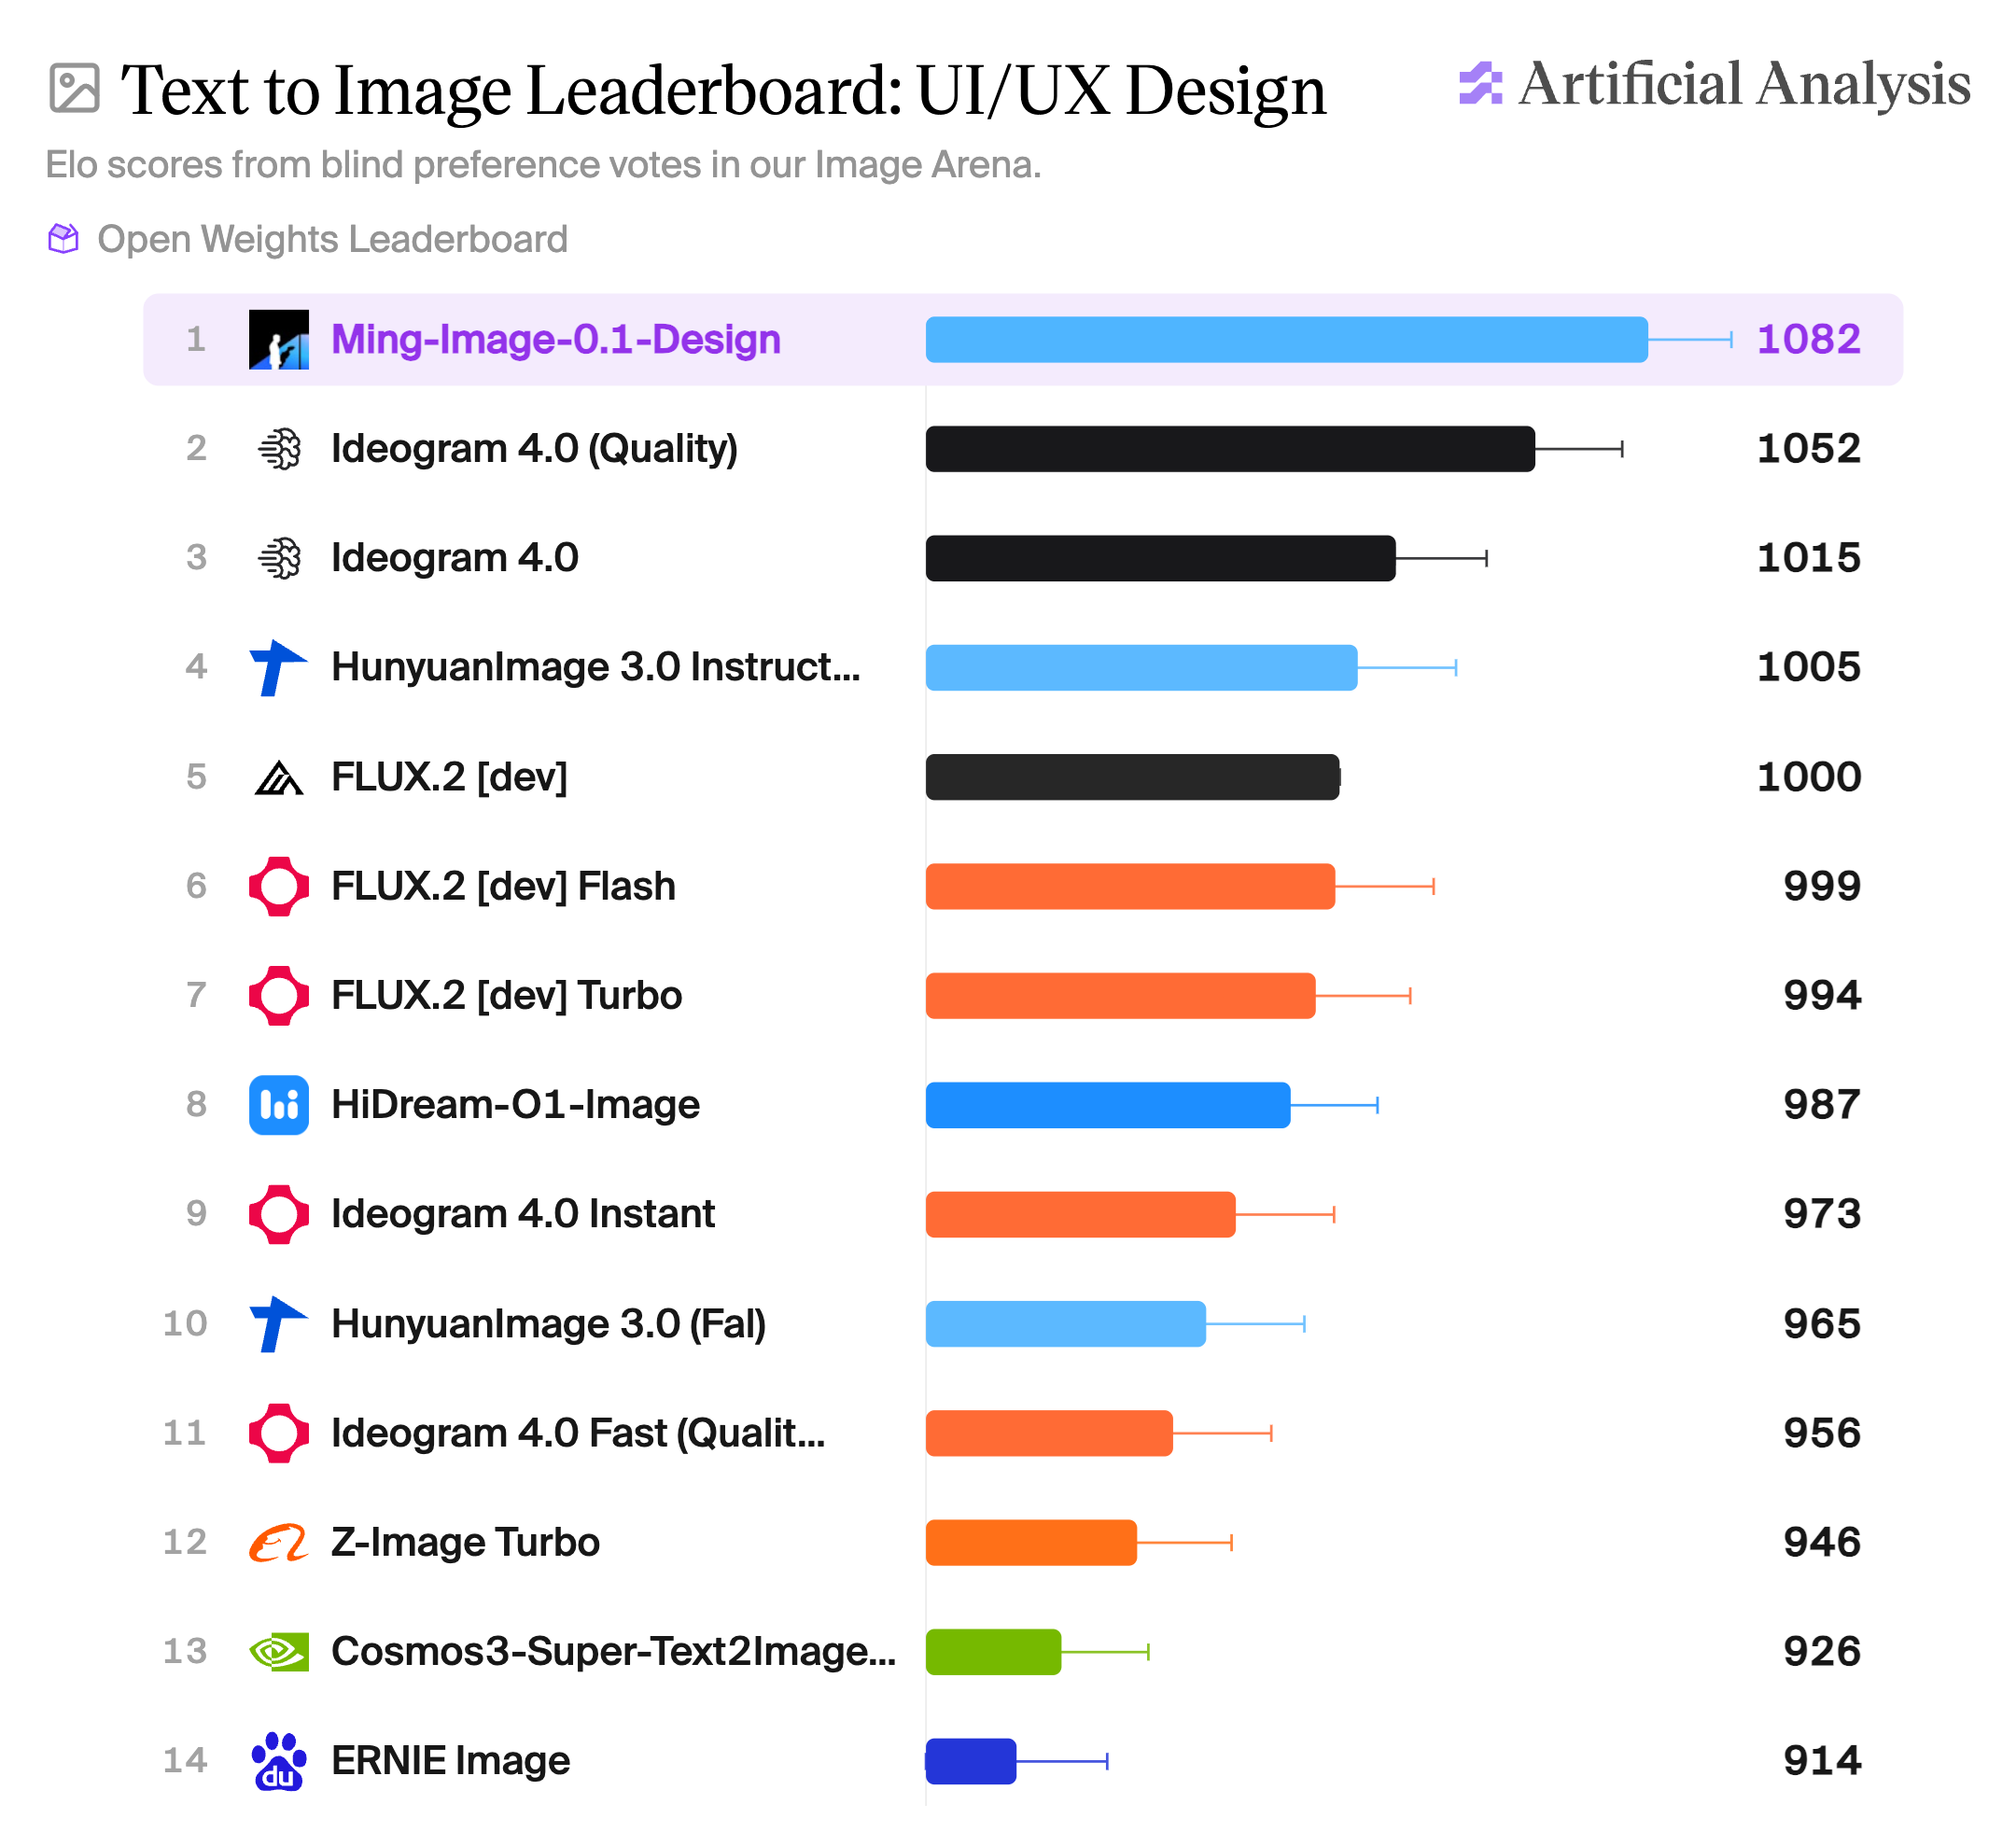
A new MIT-licensed text-to-image model leans into legible text rendering and transparent RGBA output for design work.
inclusionAI's 16.7B MoE vision-language model uses block-wise diffusion to drive graphical interface tasks.
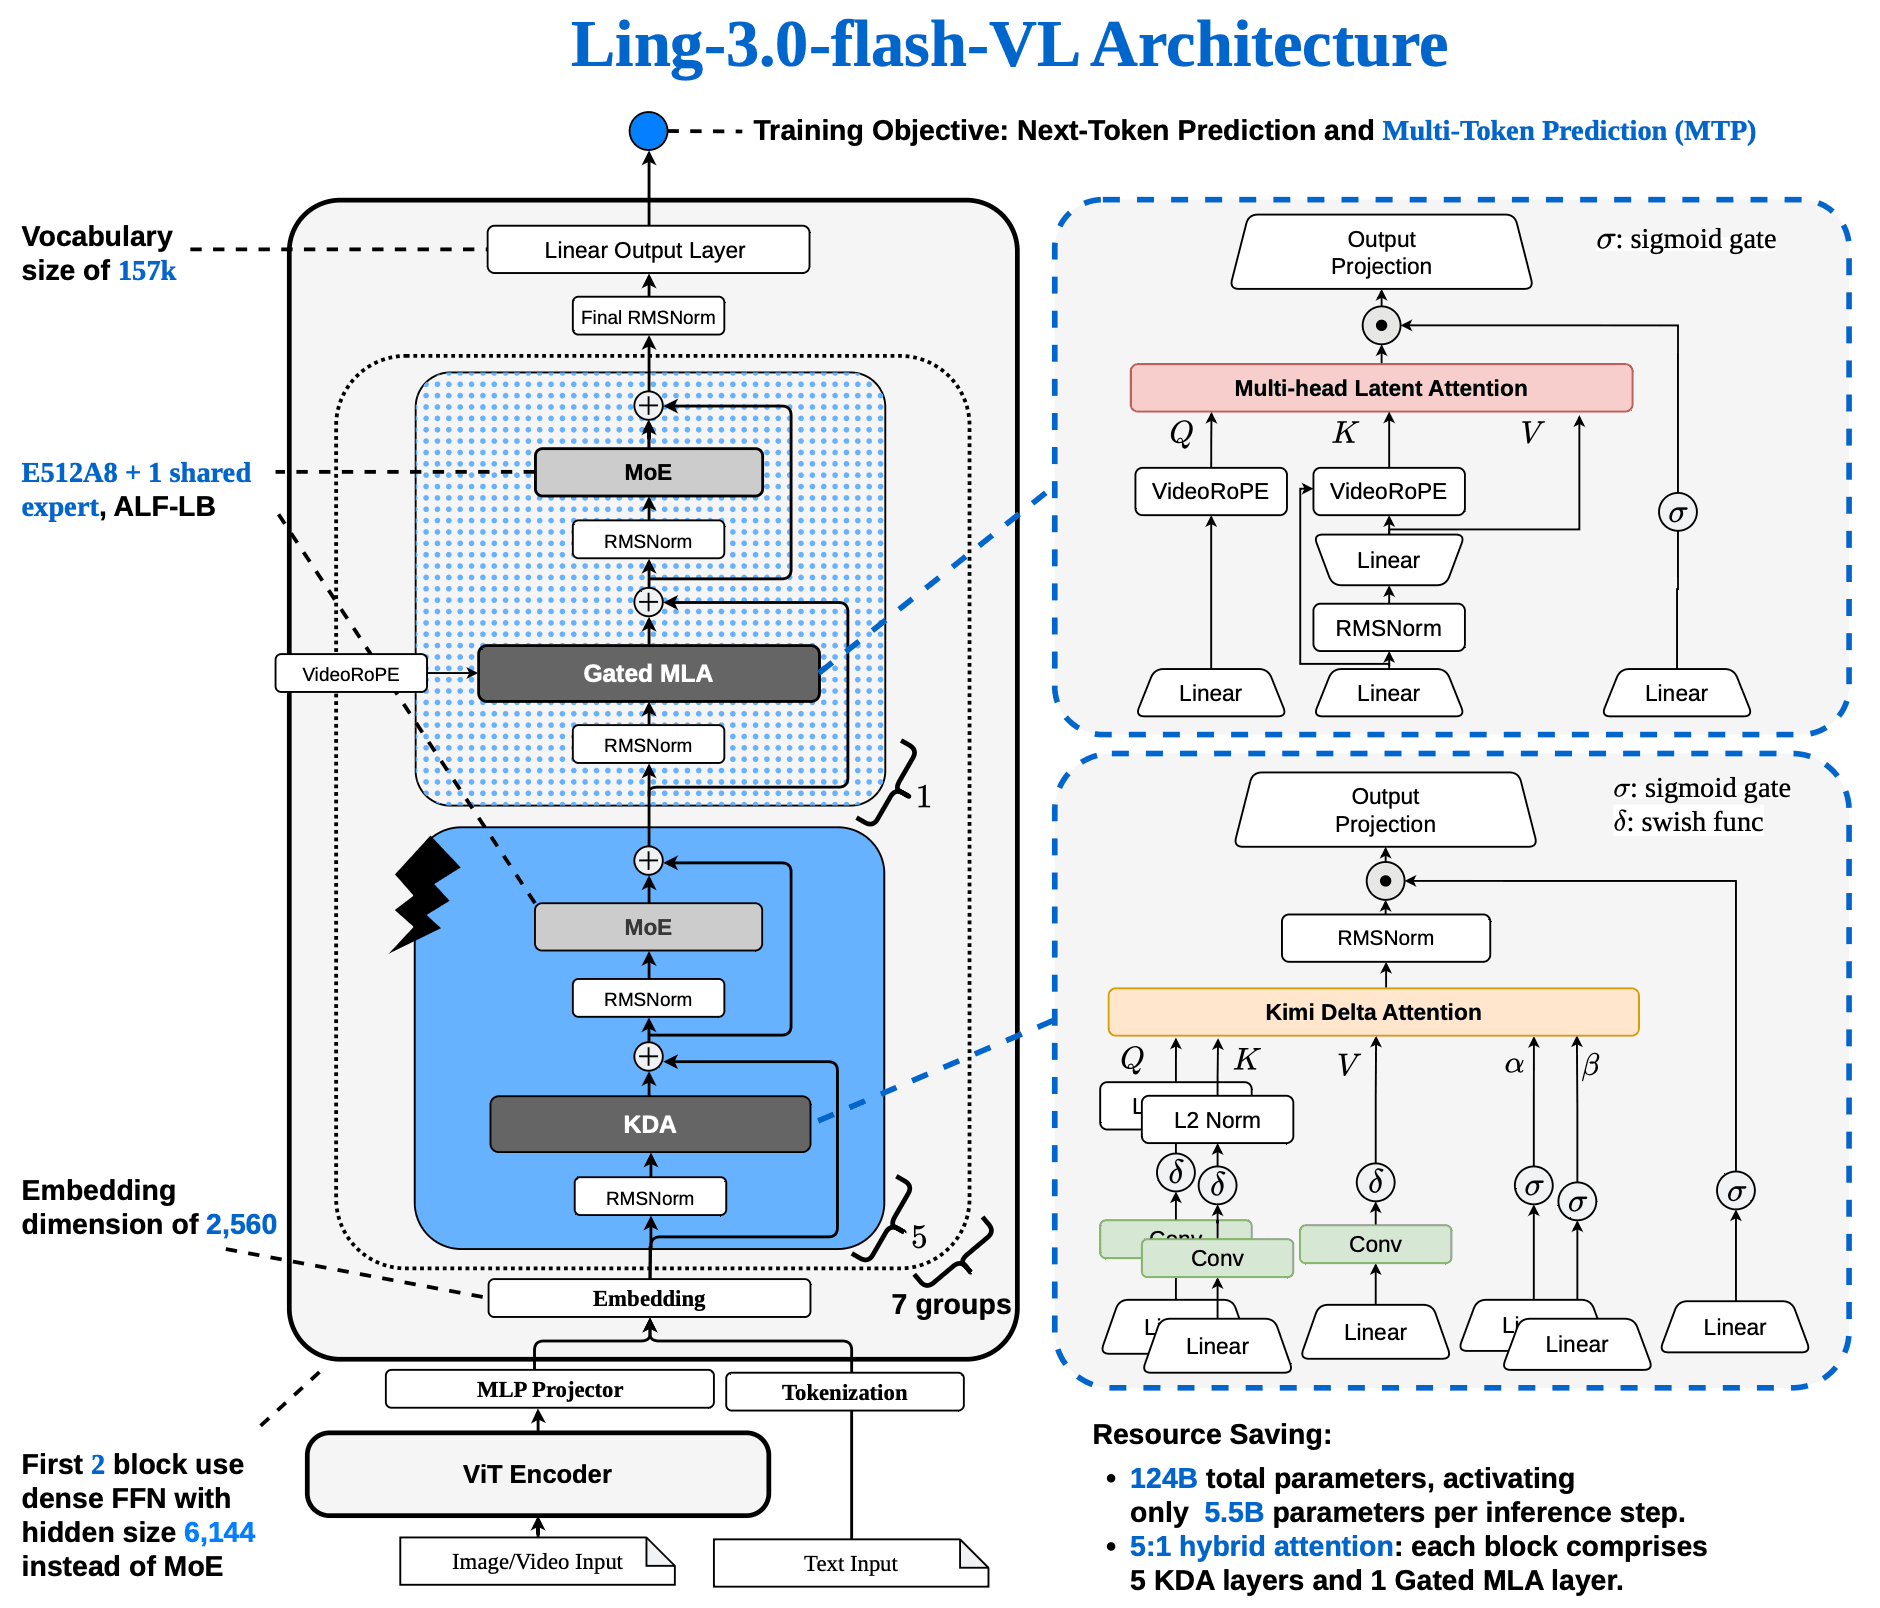
The new Ling-3.0-flash-VL brings a mixture-of-experts vision-language model to inclusionAI's open lineup under a permissive MIT license.
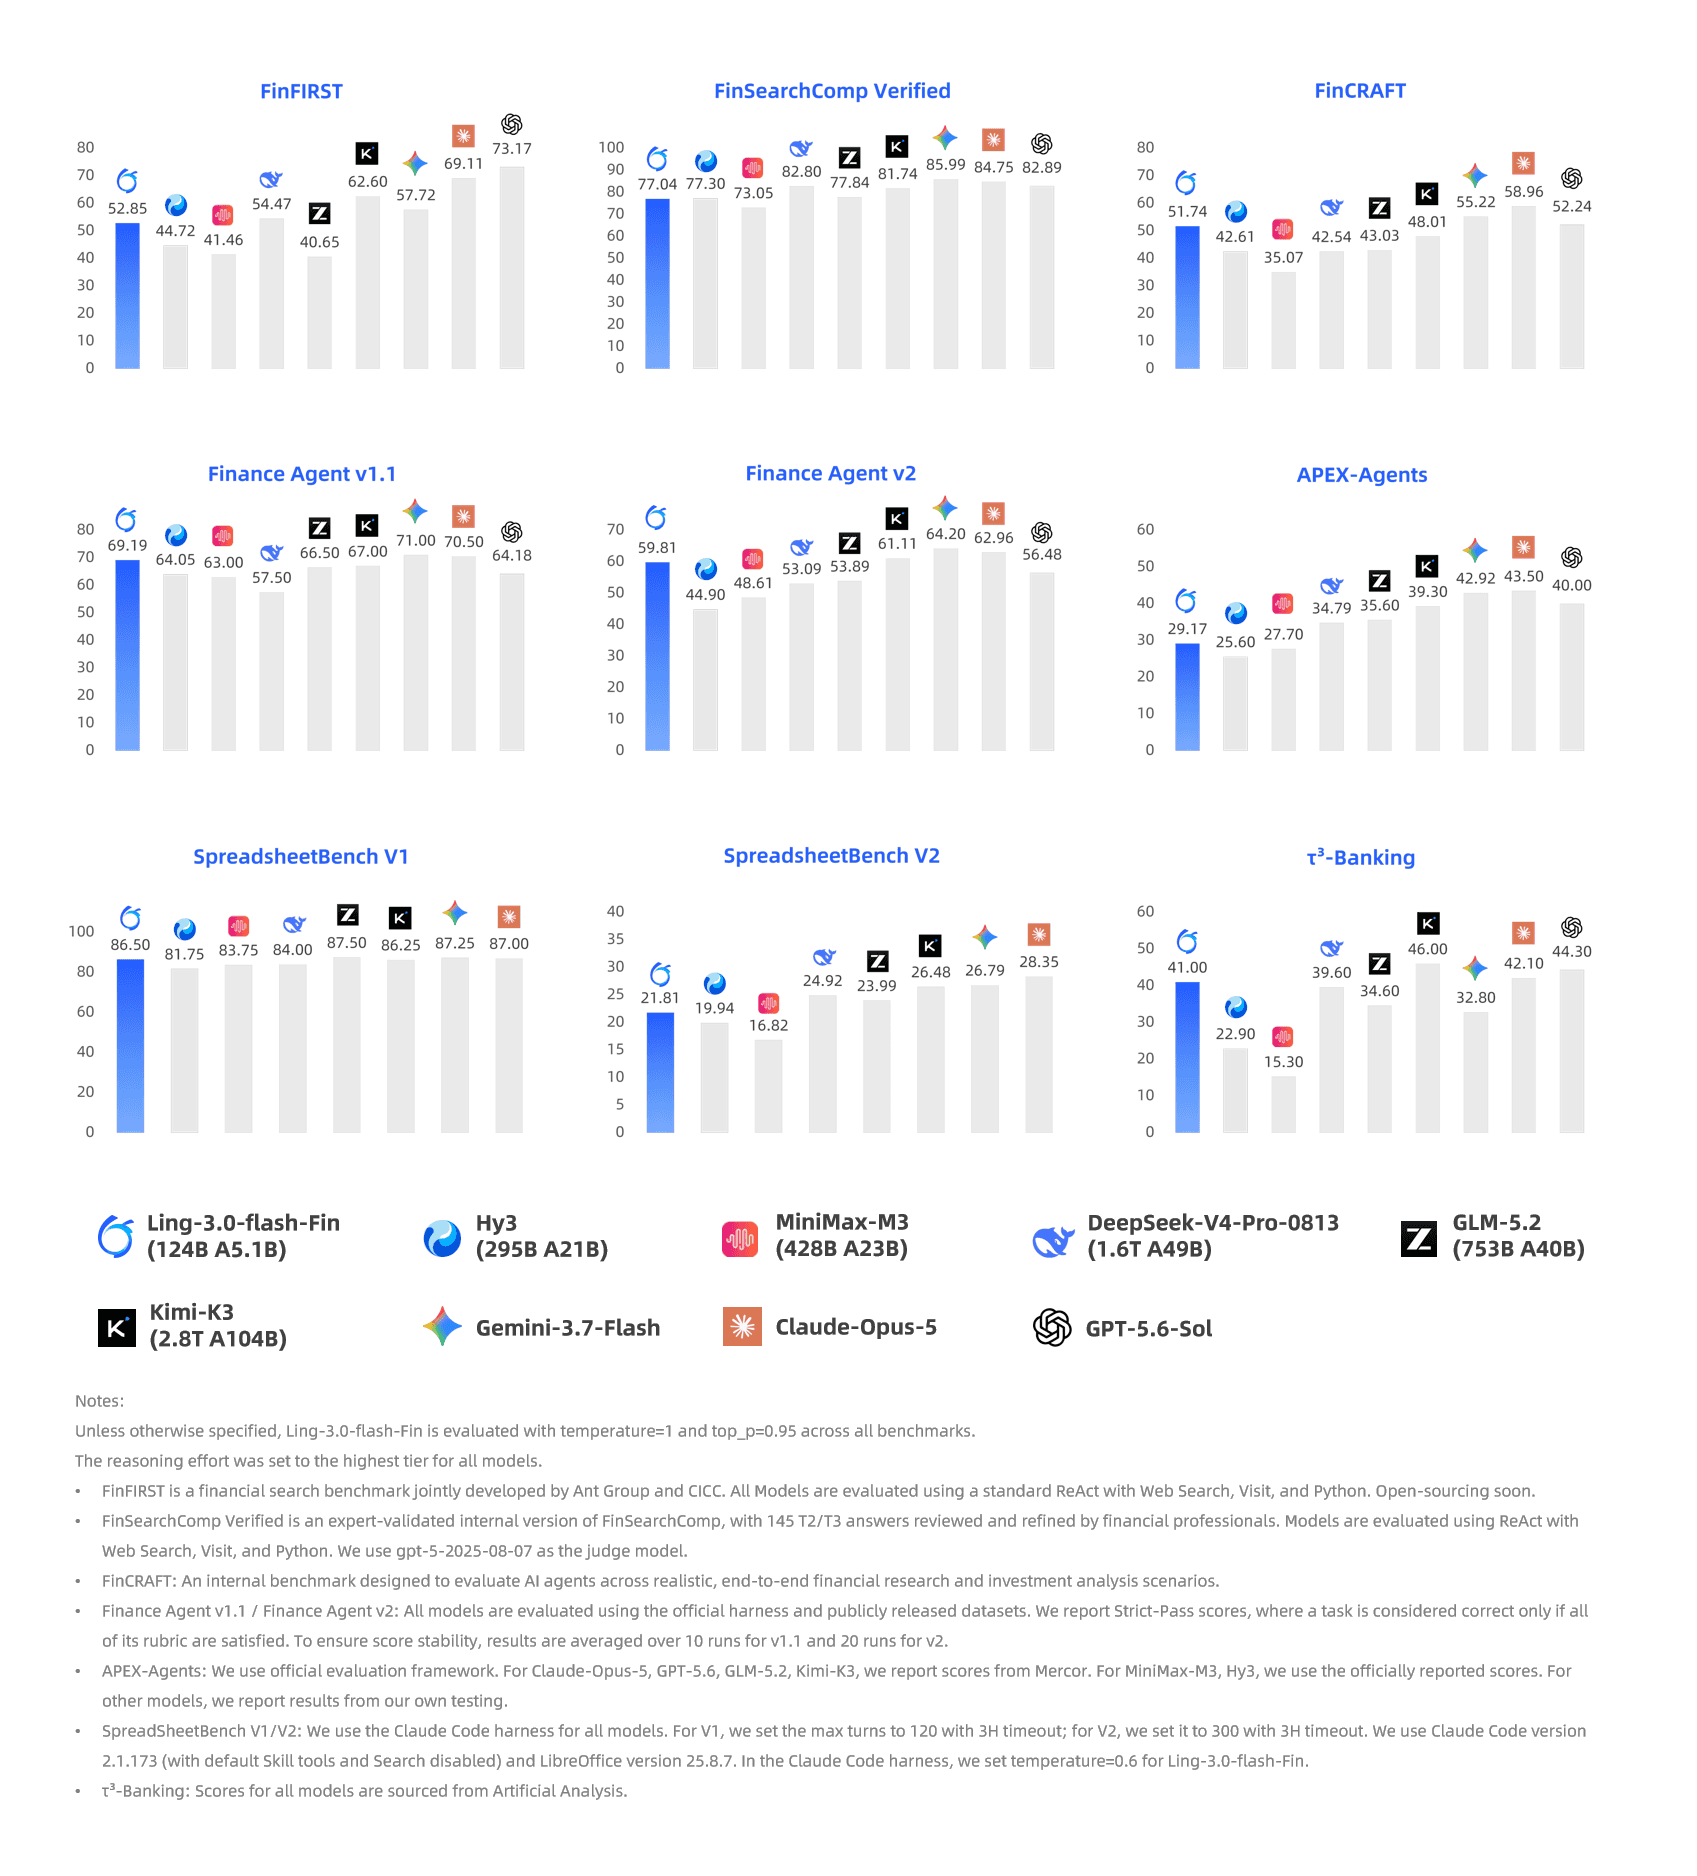
A finance-focused variant of the Ling-3.0-flash MoE model targets financial research and agentic tool use.
inclusionAI pairs a diffusion transformer with a frozen vision-language model and publishes the entire training recipe.
The new hybrid mixture-of-experts model targets efficient text generation under a permissive license.
The latest entry in the Bailing family pairs a hybrid mixture-of-experts design with a permissive license aimed at fast, low-cost text generation.
A new Apache-2.0 mixture-of-experts model that generates text through diffusion rather than left-to-right decoding.
A new mixture-of-experts model learns to reason through reinforcement learning alone, without human-annotated chains of thought.
The new open-source model from inclusionAI uses a Mixture-of-Experts architecture to handle multiple vision tasks in a single, diffusion-based system.
The new open-source Mixture-of-Experts model can process and generate content across text, images, and audio in any combination.
The new Ming-flash-omni-Preview aims to handle any combination of data modalities using an efficient Mixture of Experts architecture.
The new 16-billion-parameter model uses a sparse Mixture-of-Experts design to efficiently handle 'any-to-any' data combinations, from text to images.
A new 16-billion-parameter model from inclusionAI uses a Mixture-of-Experts architecture to handle a wide range of audio tasks efficiently.
The new MIT-licensed model from inclusionAI can process and generate a mix of text, images, audio, and video, pushing the boundaries of open multimodal AI.