inclusionAI Debuts 'Any-to-Any' Multimodal MoE Model
The new Ming-flash-omni-Preview aims to handle any combination of data modalities using an efficient Mixture of Experts architecture.

AI research group inclusionAI has released Ming-flash-omni-Preview, a new open-source model designed for true multimodal flexibility. Released under a permissive MIT license, the model pursues an "any-to-any" capability, meaning it's built to process and generate a wide combination of data types, not just text and images.
This approach, often called "omnimodal," represents a significant step beyond models that are limited to specific input-output pairs, like text-to-image or audio-to-text. An any-to-any system can theoretically accept a mix of inputs—say, an image, a line of text, and an audio clip—and generate a relevant output in a requested modality.
The model is built on a Mixture of Experts (MoE) architecture, a technique that improves computational efficiency by routing inputs to specialized subnetworks, or "experts," rather than engaging the entire model for every token. According to the release card, Ming-flash-omni is based on a previous model called Ling-flash-2.0.
As major labs pursue closed, highly capable omnimodal models, the release of an open alternative like Ming-flash-omni-Preview provides researchers and developers with a valuable tool for experimentation. While labeled as a preview, it offers a foundational component for building applications that require a more fluid and comprehensive understanding of diverse data streams.
Sources
- Visit
inclusionAI/Ming-flash-omni-Preview
Hugging Face
More from inclusionAI
All inclusionAI releases →
inclusionAI releases Ling-3.1-flash under MIT license
A new hybrid mixture-of-experts text model arrives on Hugging Face with permissive licensing and a focus on fast inference.
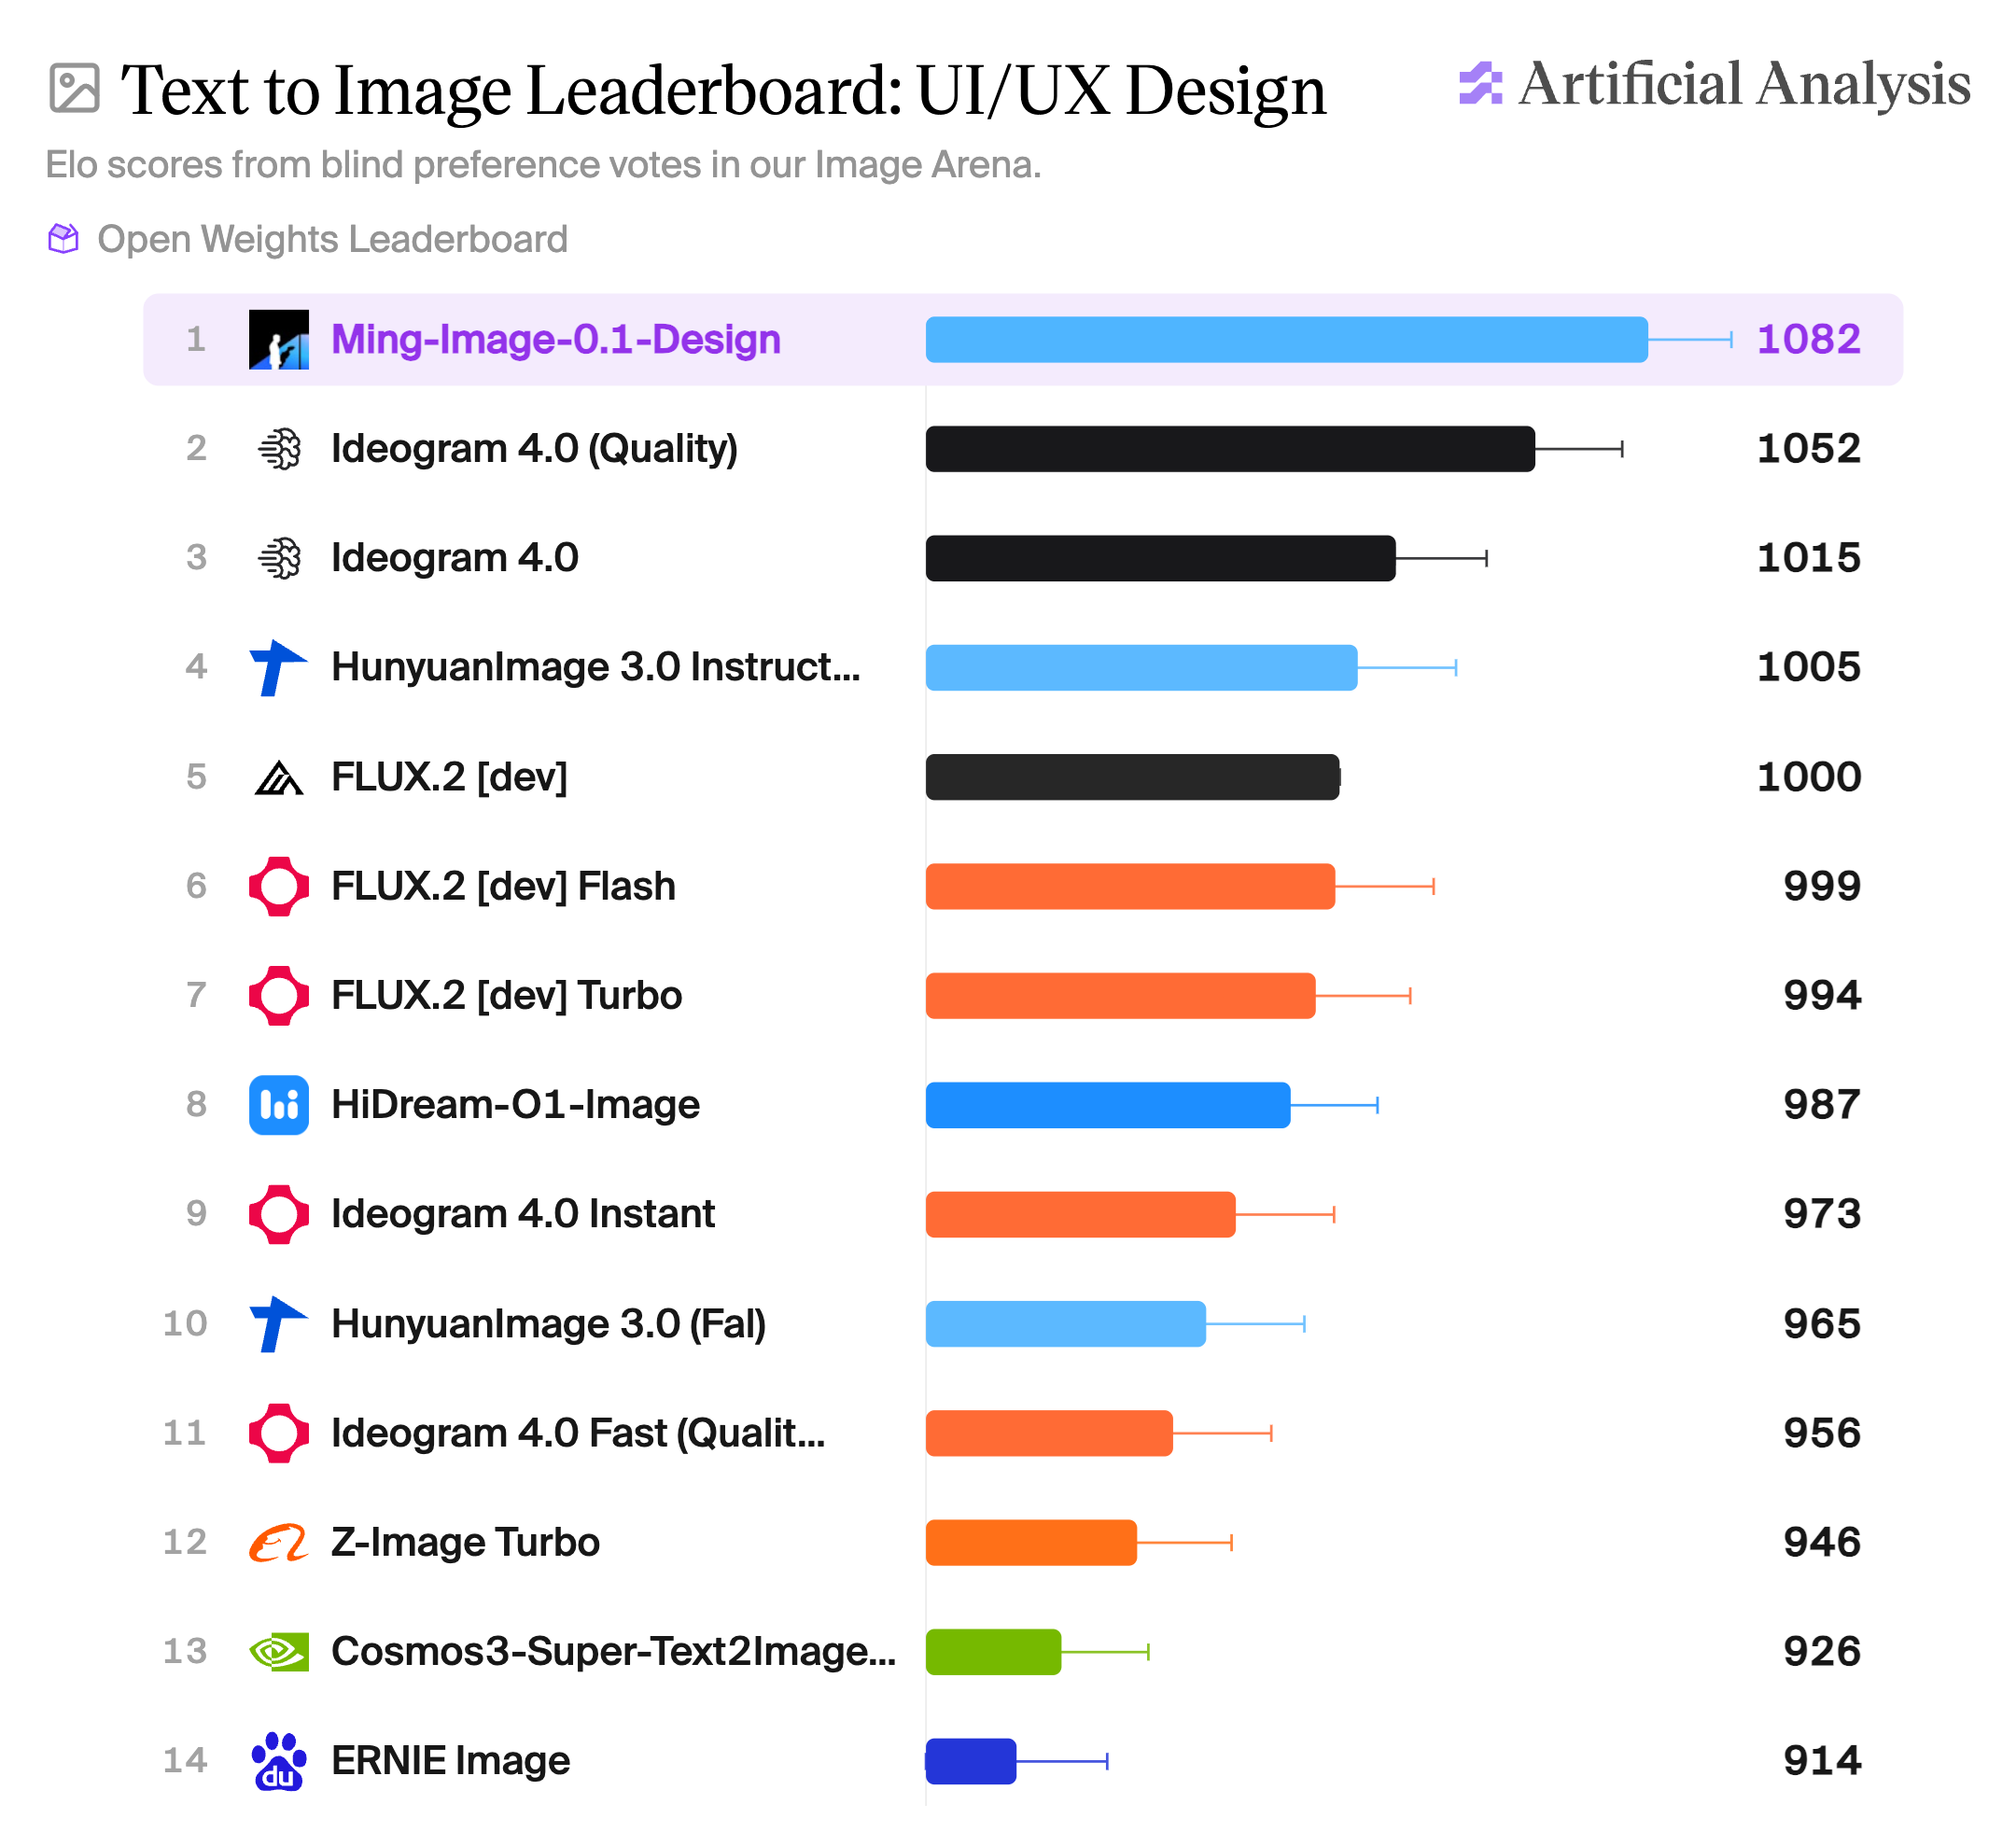
inclusionAI's Ming-Image targets graphic design
A new MIT-licensed text-to-image model leans into legible text rendering and transparent RGBA output for design work.
LLaDA-UI Brings Diffusion Decoding to GUI Agents
inclusionAI's 16.7B MoE vision-language model uses block-wise diffusion to drive graphical interface tasks.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.