inclusionAI releases Ling-3.1-flash under MIT license
A new hybrid mixture-of-experts text model arrives on Hugging Face with permissive licensing and a focus on fast inference.
inclusionAI has published Ling-3.1-flash, a text-focused language model built on a hybrid mixture-of-experts (MoE) architecture and released under the permissive MIT license. The model is now available on Hugging Face.
The "flash" naming signals a model tuned for efficiency, a common design goal for MoE systems that activate only a subset of parameters per token to keep inference costs down. inclusionAI has not published detailed specifications such as total or active parameter counts or context length alongside this release, so builders will want to inspect the repository configuration directly before committing to deployment.
Why it matters
The MIT license is the headline detail here. It places few restrictions on commercial use, modification, and redistribution, making Ling-3.1-flash notably more permissive than many open-weight releases that ship with custom or usage-restricted terms.
- Hybrid MoE design aimed at efficient inference
- Permissive MIT licensing for broad reuse
- Text-only modality, suitable for standard LLM workloads
As with any sparsely specified launch, the practical value will depend on independent testing and the community's evaluation of throughput and quality. For now, Ling-3.1-flash adds another openly licensed option to a crowded field of MoE language models, and its licensing alone makes it worth a look for teams wary of restrictive terms.
Sources
- Visit
inclusionAI/Ling-3.1-flash
Hugging Face
More from inclusionAI
All inclusionAI releases →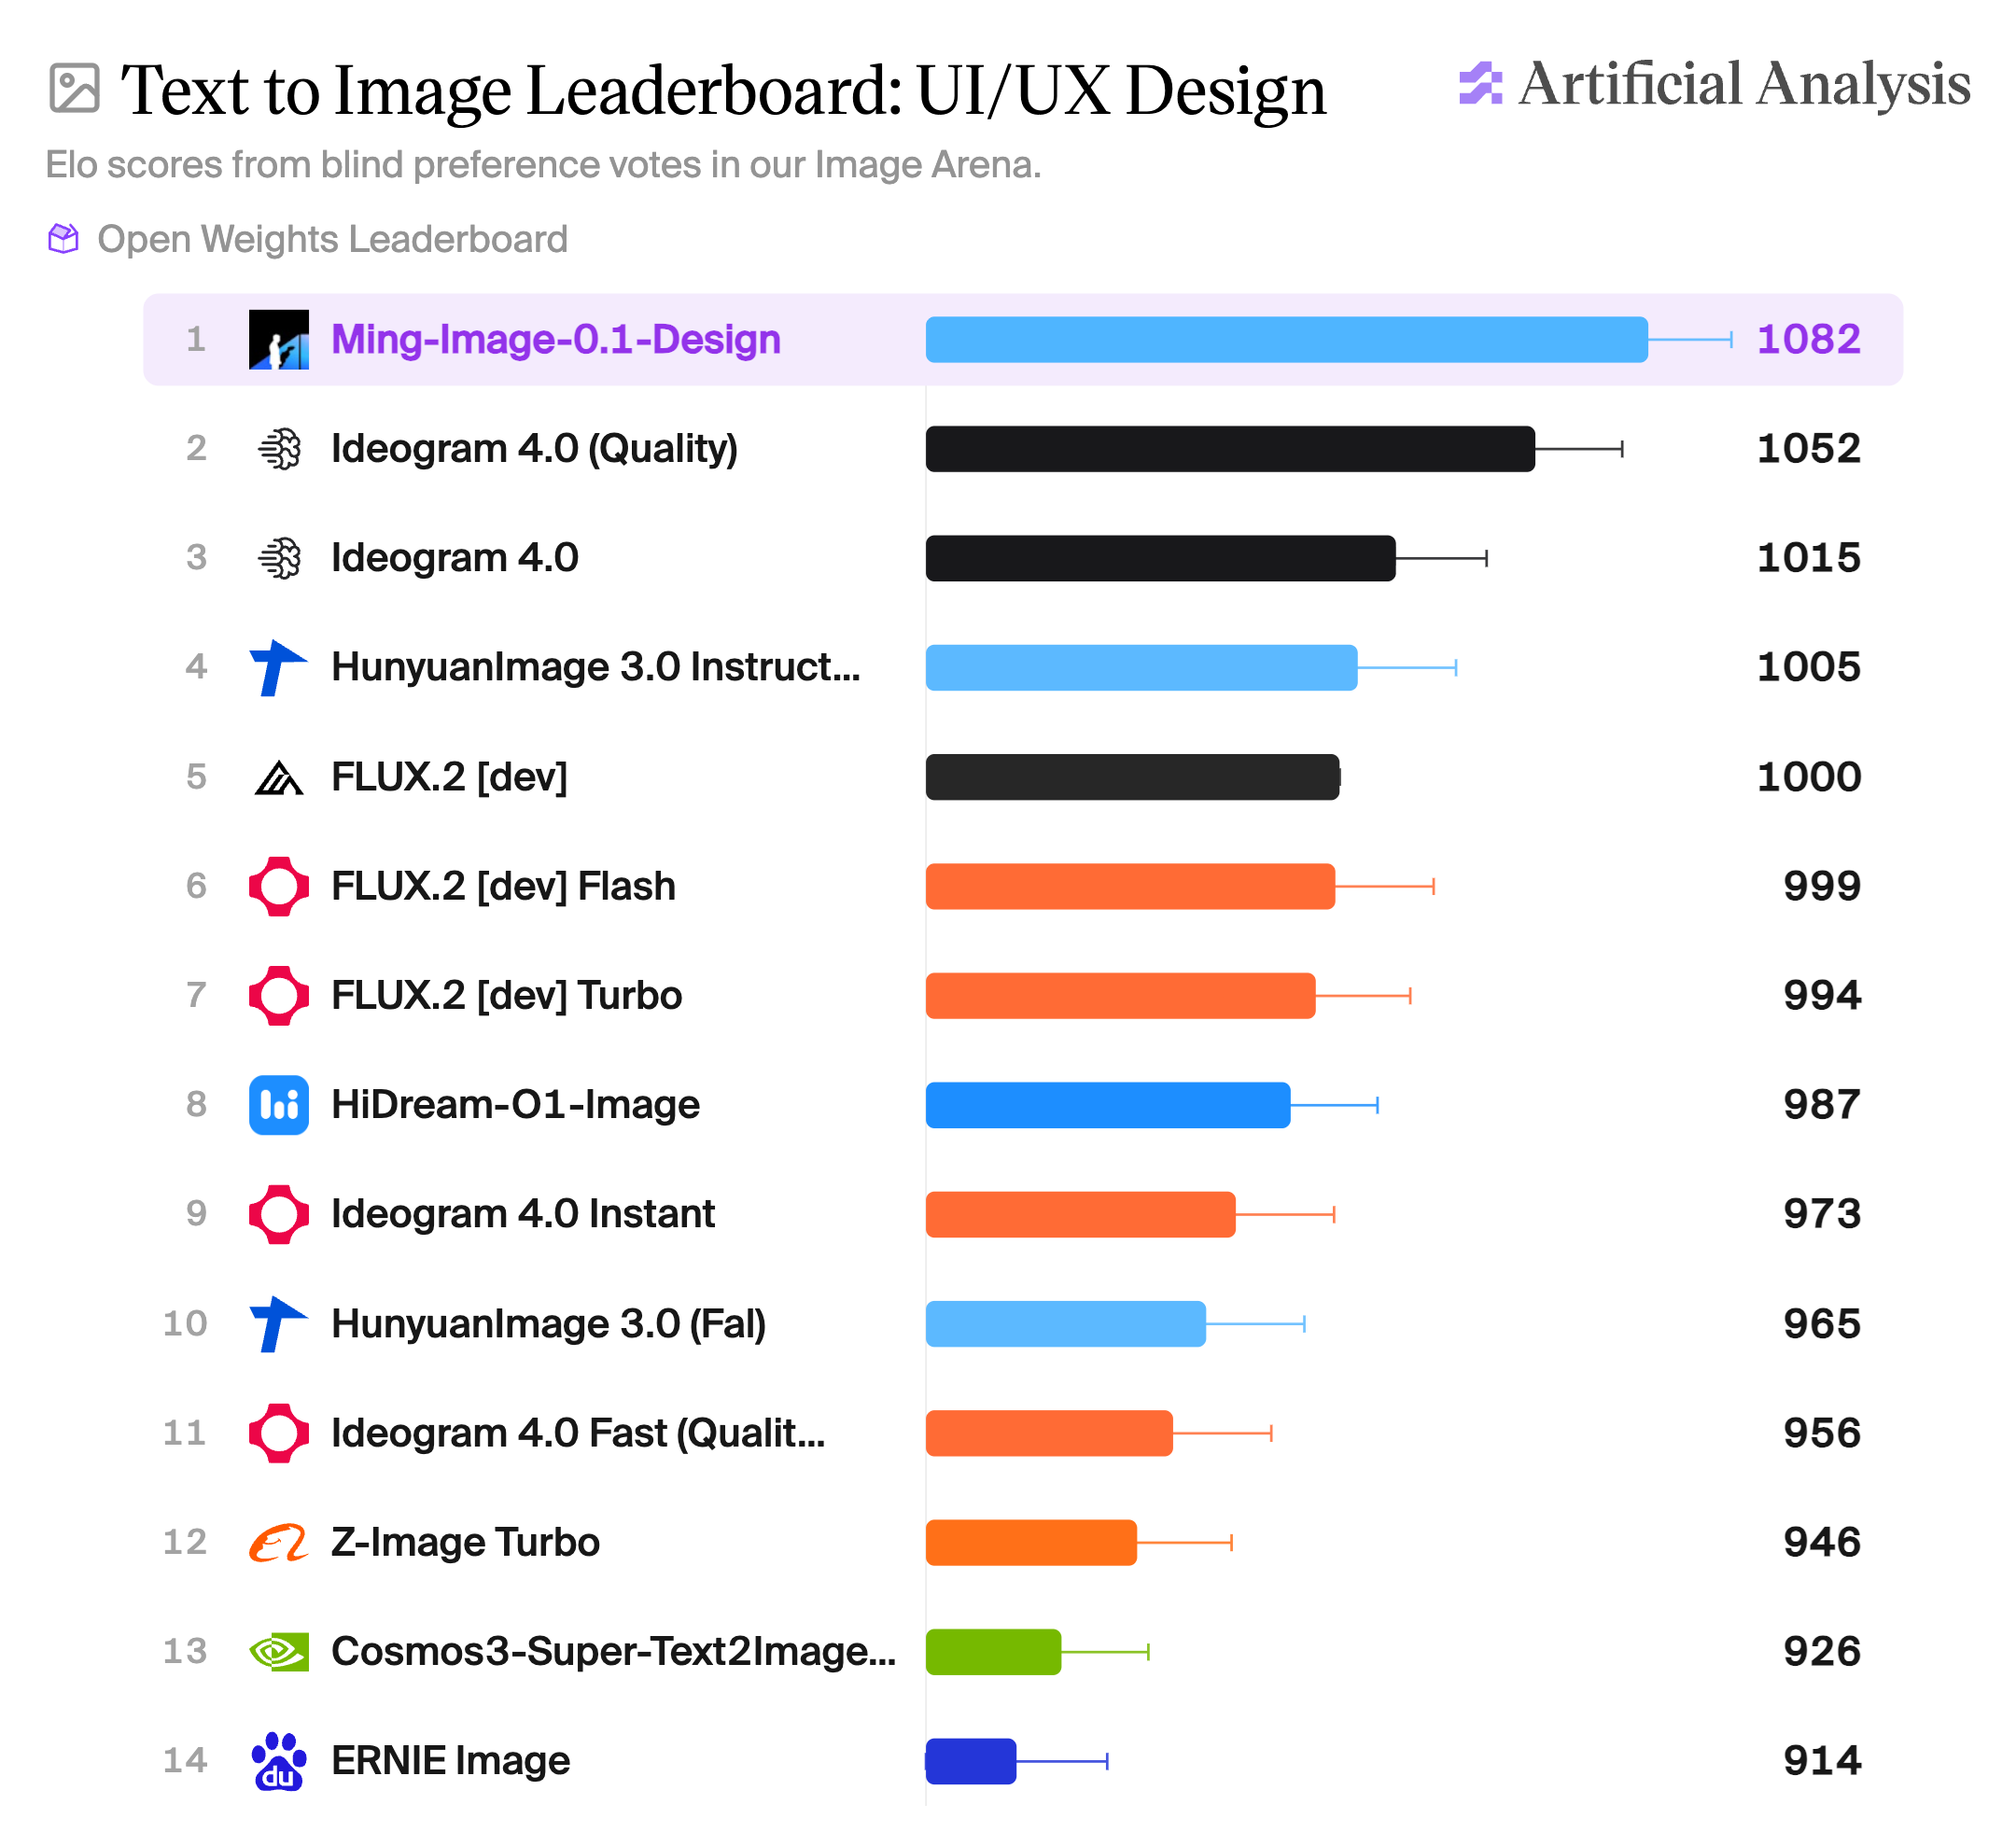
inclusionAI's Ming-Image targets graphic design
A new MIT-licensed text-to-image model leans into legible text rendering and transparent RGBA output for design work.
LLaDA-UI Brings Diffusion Decoding to GUI Agents
inclusionAI's 16.7B MoE vision-language model uses block-wise diffusion to drive graphical interface tasks.
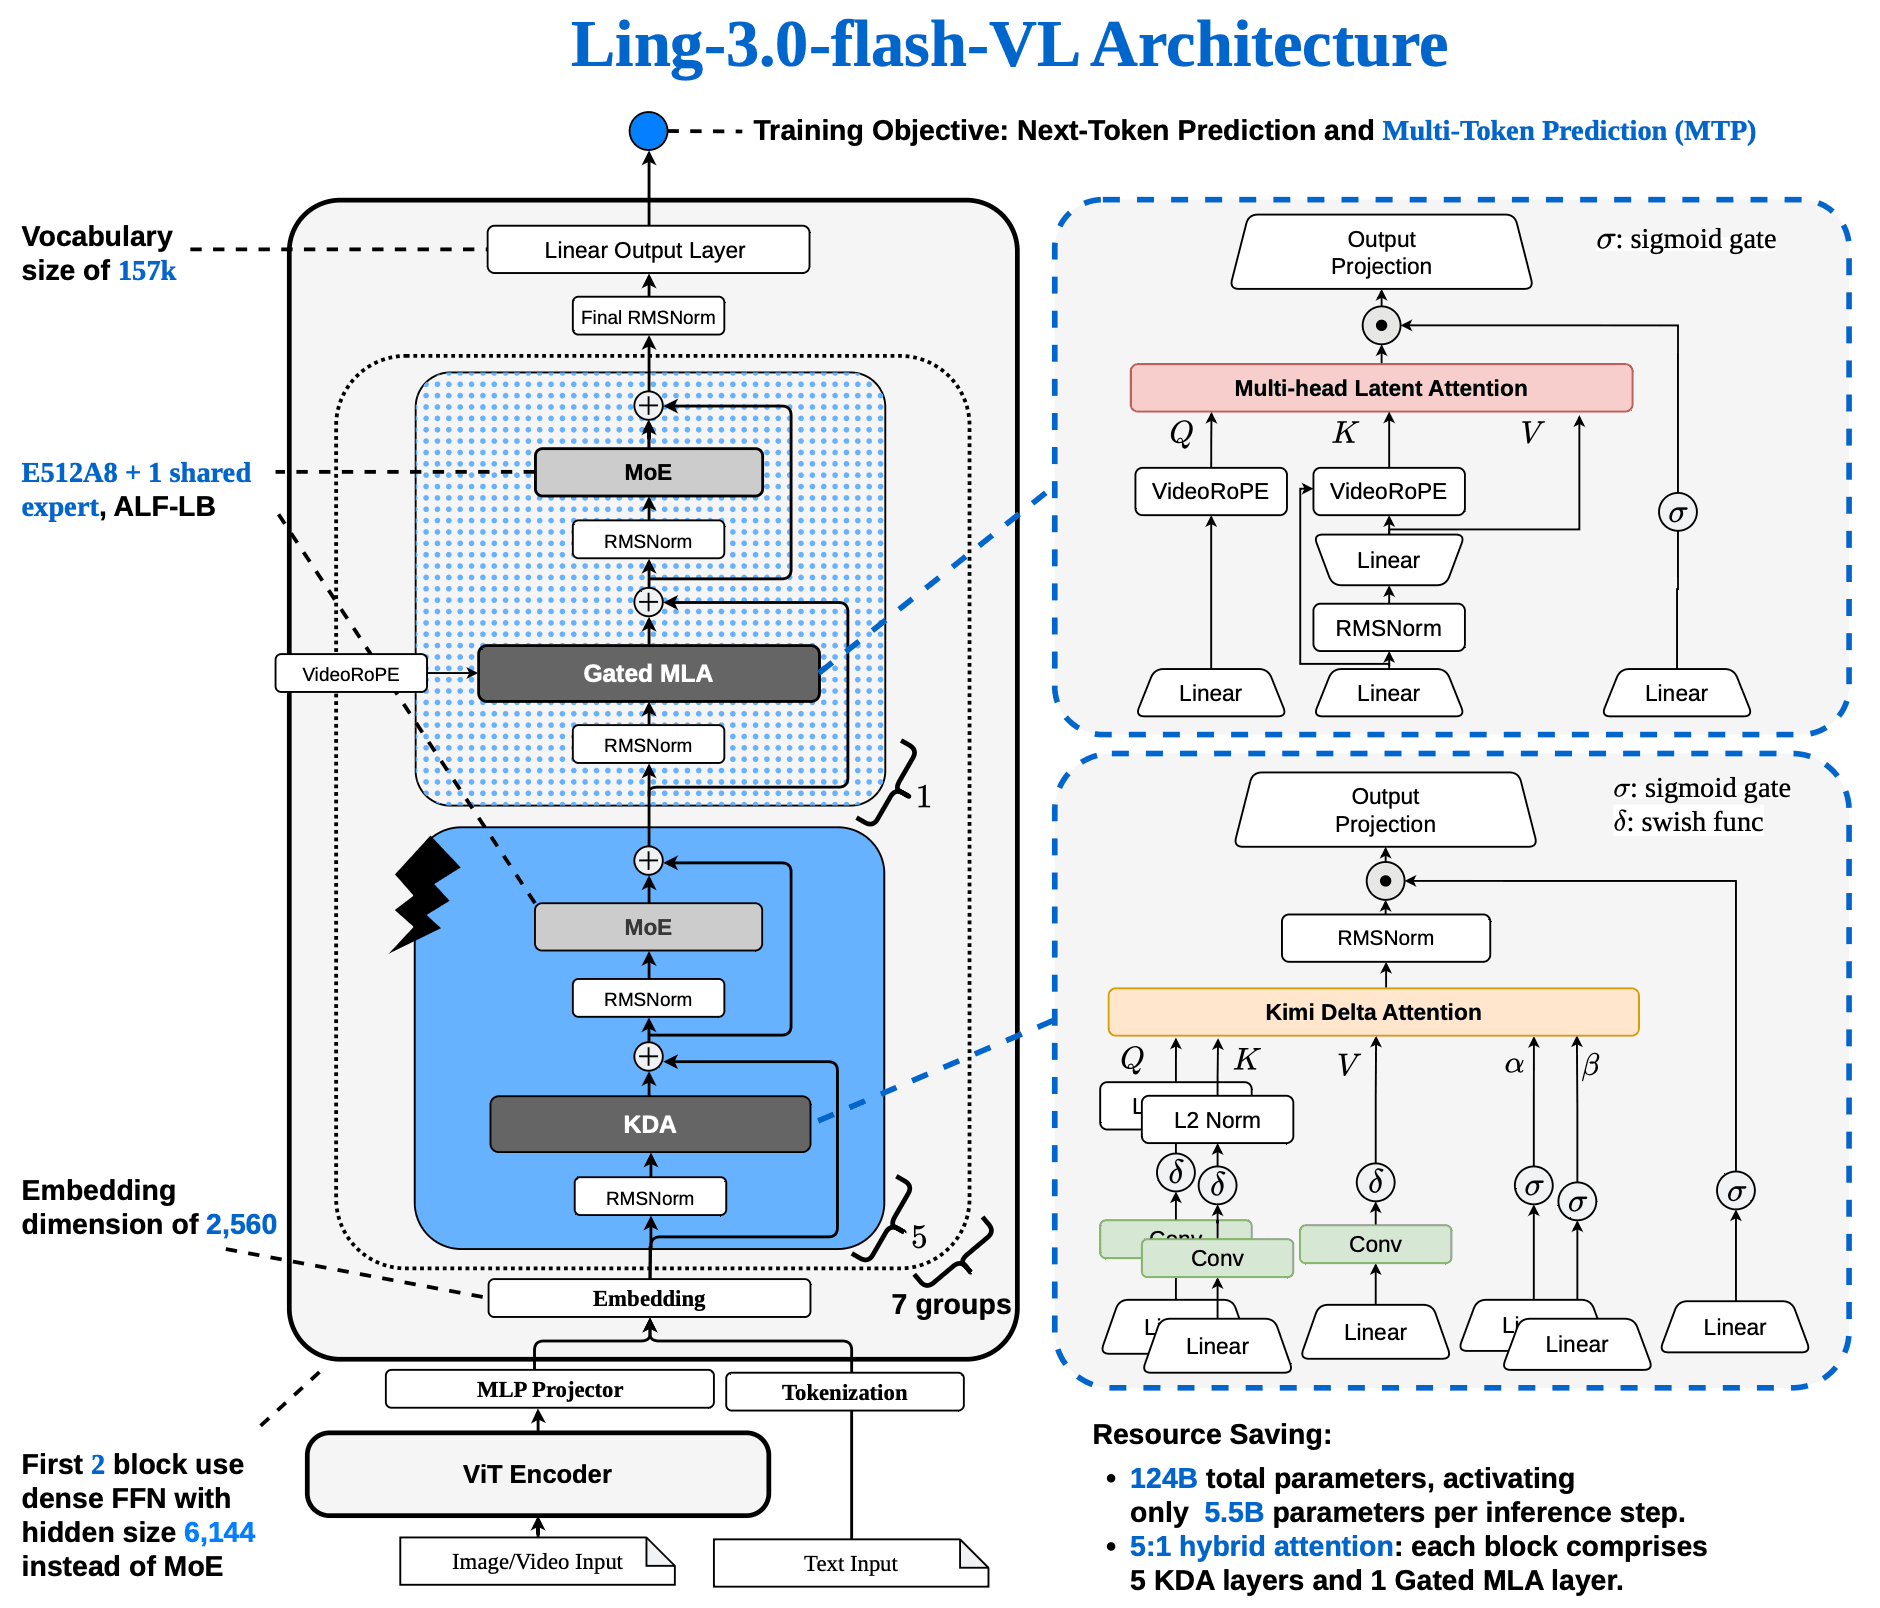
inclusionAI Adds Vision to Ling 3.0 Flash
The new Ling-3.0-flash-VL brings a mixture-of-experts vision-language model to inclusionAI's open lineup under a permissive MIT license.
More in Text / LLM
All Text / LLM →
Liquid AI's LFM2.5 Puts a 24B MoE on Your Device
The new mixture-of-experts model keeps total capacity high while activating only about 2B parameters per token for edge agents.
Mistral Large 4 arrives as a trillion-param MoE
The new flagship is a sparse mixture-of-experts model with roughly 49B active parameters per token.
Falcon-Emirati tunes an LLM for local dialect
TII's Falcon family gets a variant built around Emirati Arabic, aiming at culture and nuance rather than generic Gulf Arabic.
0 comments
No comments yet. Be the first to weigh in.