Audio8-TTS-Realistic-Air brings zero-shot voice cloning
A new multilingual text-to-speech model promises realistic speech synthesis across languages from short voice samples.
A developer going by Edge0 has published Audio8-TTS-Realistic-Air, a text-to-speech model built around zero-shot voice cloning. According to its Hugging Face listing, the model is multilingual and aims to reproduce a target voice from a short reference clip without additional fine-tuning.
Zero-shot cloning is the headline capability here. Rather than training a bespoke voice on hours of recordings, a user supplies a brief sample and the system generates new speech in that voice. That approach has become the dominant pattern in modern open TTS, lowering the barrier for dubbing, accessibility tools, and prototyping synthetic narration.
What we know
- It is released and downloadable on Hugging Face under the "Air" label.
- It targets multilingual output rather than a single language.
- The repository does not publish parameter counts, sample rates, or benchmark figures.
The gaps matter. Without stated model size, audio quality metrics, or a clear license beyond "other," teams evaluating it for production will need to test directly and scrutinize usage terms — especially given the legal and ethical sensitivities around voice cloning.
Why it matters: The steady arrival of small, open voice-cloning models keeps pushing realistic speech synthesis toward hobbyists and indie developers. Audio8-TTS-Realistic-Air is an early, lightly documented entry, but it reflects how quickly this capability is becoming commoditized.
Sources
- Visit
Edge0/Audio8-TTS-Realistic-Air
Hugging Face
More from Edge0
All Edge0 releases →
Audio8-ASR-Infinite brings streaming bilingual speech recognition
A new open model targets real-time transcription for Chinese and English audio.
Edge0's 35B MoE Aims for SSD-Backed Edge Inference
A preview mixture-of-experts model uses trained routing prediction to run on machines that can't hold it all in memory.
More in Text → Speech
All Text → Speech →OpenBMB's Phonon Brings High-Quality TTS On-Device
The new text-to-speech model promises benchmark-topping voice synthesis that runs locally rather than in the cloud.
ServiceNow Debuts Apriel Voice 27B, an Open Speech Model
The 27-billion-parameter preview unifies text-to-speech, transcription, and reasoning in a single open model.
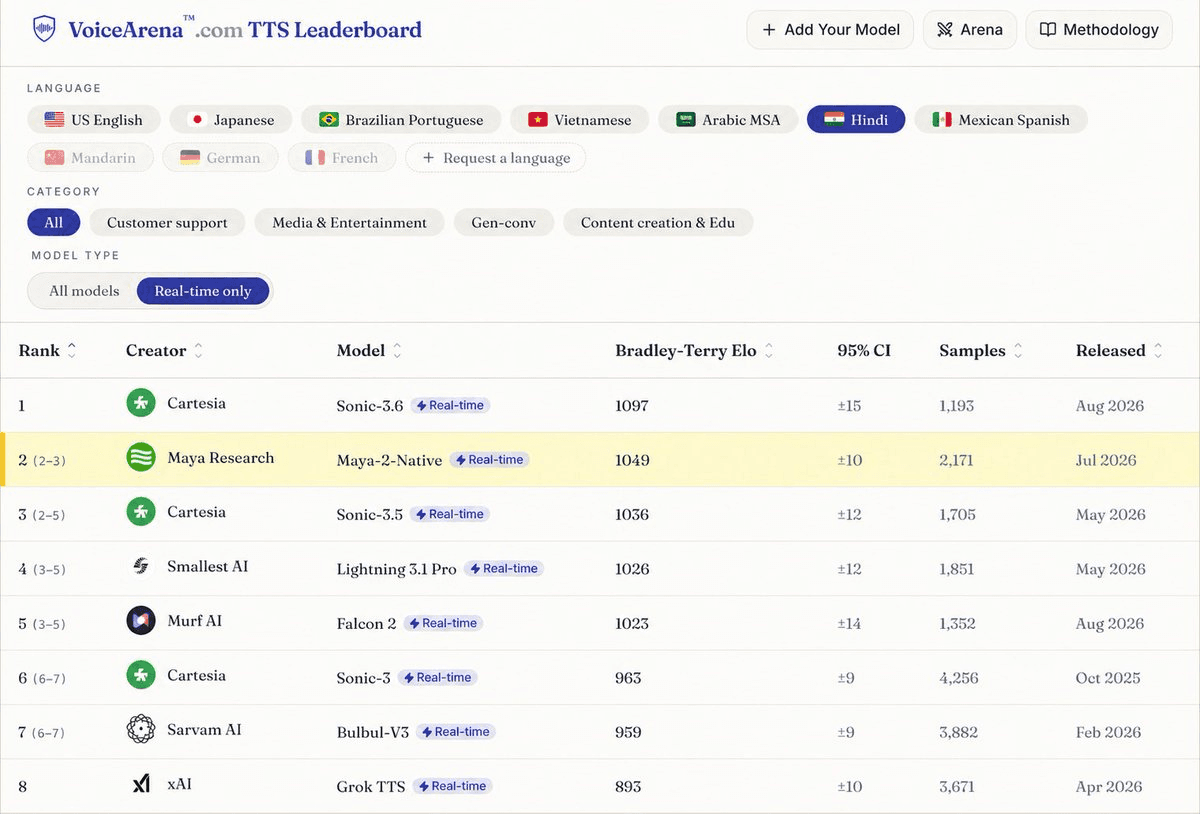
Maya2 Native brings streaming TTS to Indic languages
Maya Research's new open text-to-speech model targets Indian languages with voice cloning and real-time streaming output.
0 comments
No comments yet. Be the first to weigh in.