inclusionAI Releases Ming-UniVision MoE Multimodal Model
The new 16-billion-parameter model uses a sparse Mixture-of-Experts design to efficiently handle 'any-to-any' data combinations, from text to images.
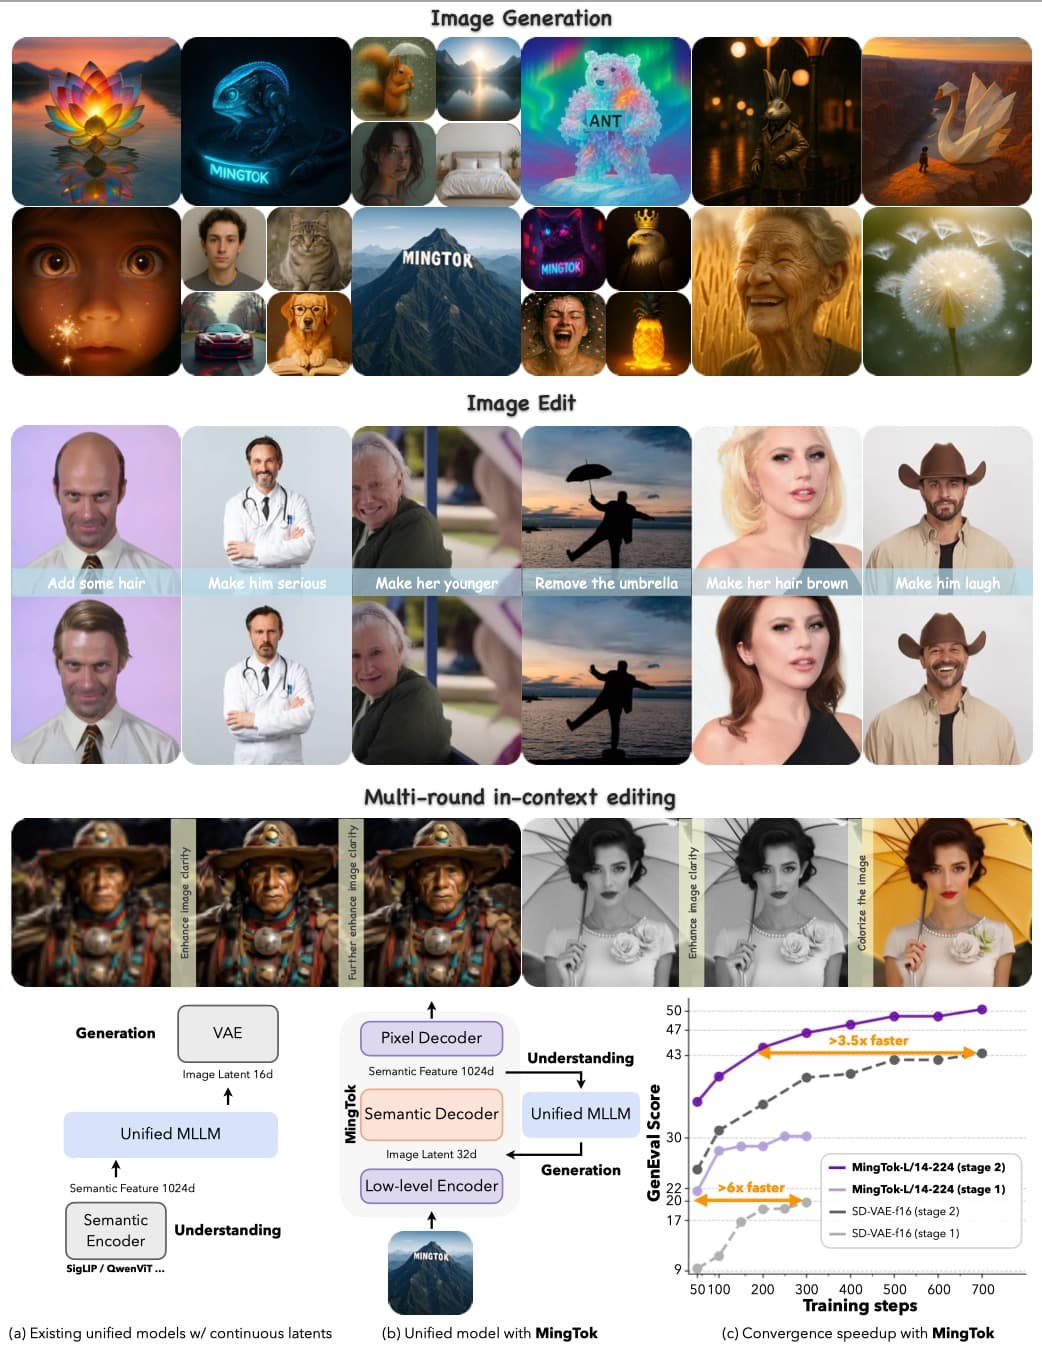
inclusionAI has released Ming-UniVision-16B-A3B, a new open-source model designed for flexible multimodal tasks. Released under the permissive Apache 2.0 license, it introduces an efficient architecture for handling diverse data types beyond simple text and image pairings.
The model employs a Mixture-of-Experts (MoE) design, with a total of 16 billion parameters. During inference, however, it only activates a fraction of those—just 3 billion, a detail likely referenced by the "A3B" in its name. This sparse activation approach aims to provide the power of a very large model while keeping computational costs relatively low.
What sets Ming-UniVision apart is its goal of being an "any-to-any" model. Unlike many vision-language models that are limited to specific input-output paths, like image-to-text, this architecture is built to process and generate a wider combination of data formats. This makes it a more versatile tool for complex, multi-faceted AI tasks.
Availability
The model and its weights are available for download on Hugging Face. Its open license encourages broad adoption for both academic research and commercial applications, paving the way for more sophisticated and efficient multimodal systems.
Sources
- Visit
inclusionAI/Ming-UniVision-16B-A3B
Hugging Face
More from inclusionAI
All inclusionAI releases →
inclusionAI releases Ling-3.1-flash under MIT license
A new hybrid mixture-of-experts text model arrives on Hugging Face with permissive licensing and a focus on fast inference.
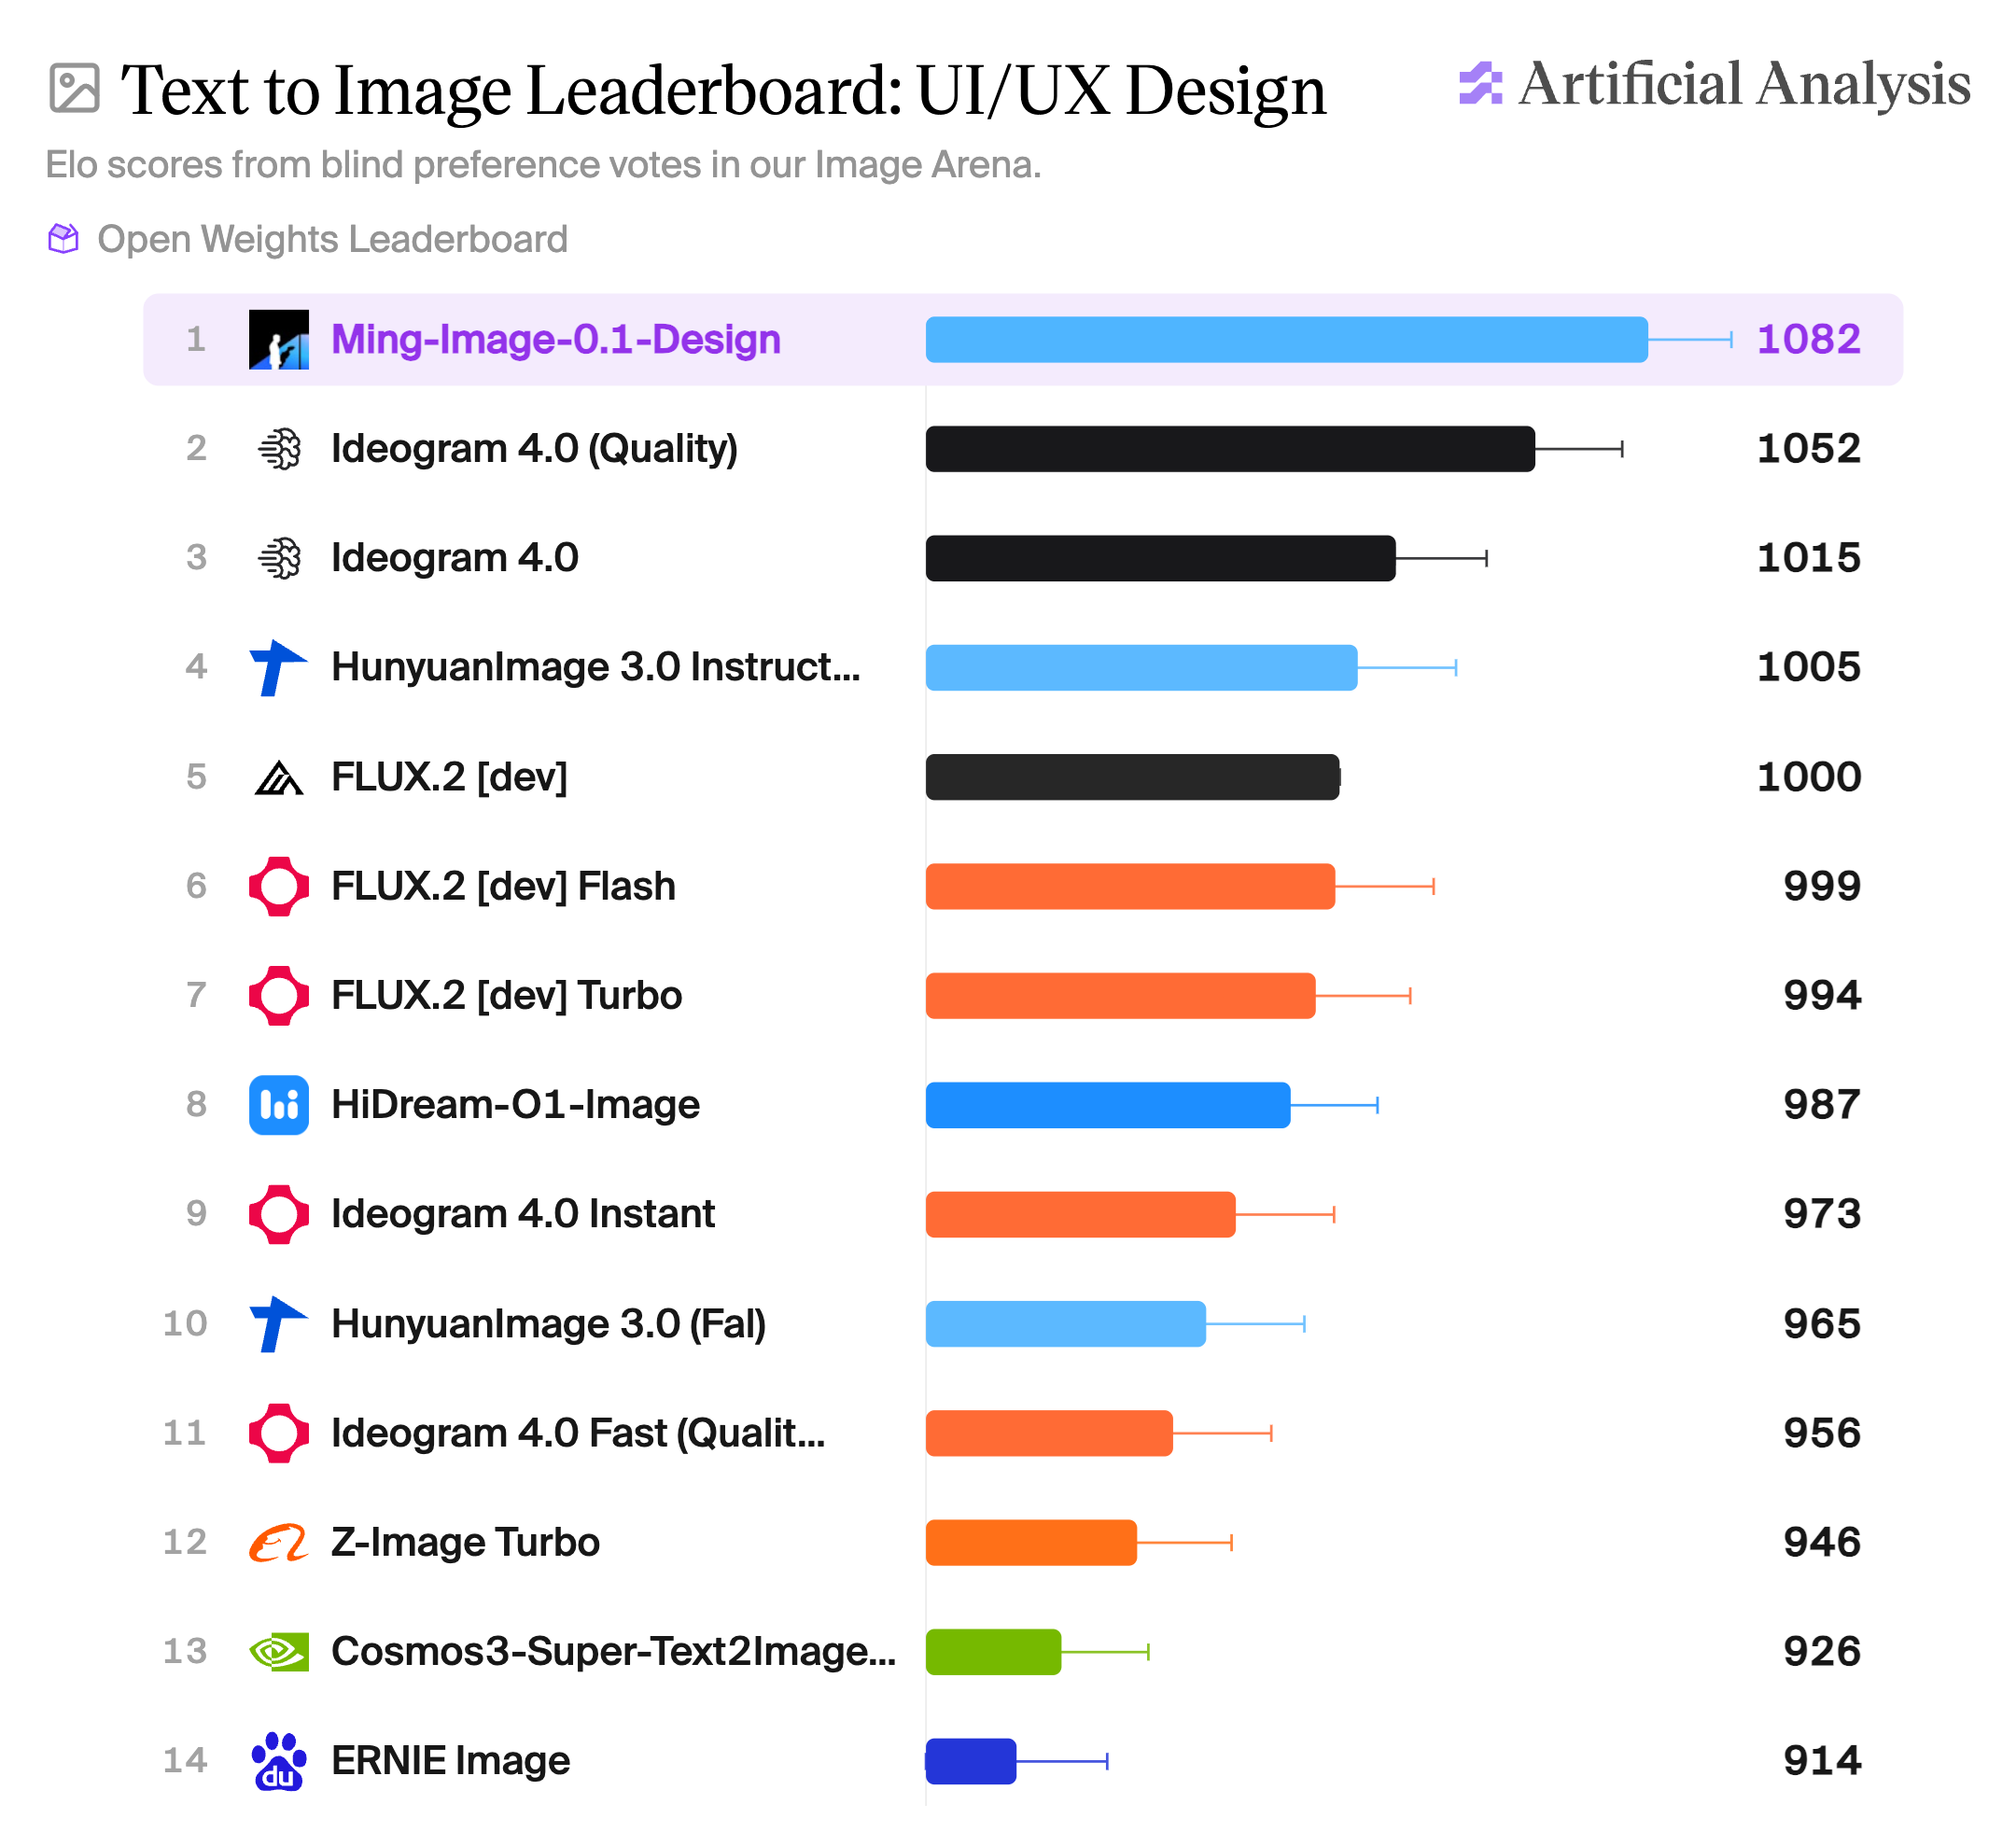
inclusionAI's Ming-Image targets graphic design
A new MIT-licensed text-to-image model leans into legible text rendering and transparent RGBA output for design work.
LLaDA-UI Brings Diffusion Decoding to GUI Agents
inclusionAI's 16.7B MoE vision-language model uses block-wise diffusion to drive graphical interface tasks.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.