inclusionAI's Ring-Zero Scales Zero-RL to a Trillion Parameters
A new mixture-of-experts model learns to reason through reinforcement learning alone, without human-annotated chains of thought.
inclusionAI has introduced Ring-Zero, a mixture-of-experts reasoning model that pushes the "zero-RL" training approach to a trillion-parameter scale. According to the accompanying paper on Hugging Face, the model develops chain-of-thought reasoning as an emergent behavior, without relying on human-annotated reasoning traces.
The zero-RL premise is straightforward but ambitious: rather than teaching a model to reason by fine-tuning it on carefully curated step-by-step examples, the approach lets reasoning behavior surface through reinforcement learning directly. Ring-Zero's contribution is demonstrating that this recipe holds up at extreme scale, where a sparse mixture-of-experts architecture activates only a fraction of its total parameters per token.
Why it matters
Human-annotated reasoning data is expensive and difficult to scale, and it can bake in the biases and limits of the annotators. If reasoning can emerge from reinforcement signals alone, the path to stronger reasoning models becomes cheaper and more repeatable.
- Released under the permissive Apache 2.0 license
- Built as a mixture-of-experts model claiming trillion-parameter total scale
- Focused on emergent chain-of-thought rather than supervised reasoning traces
Ring-Zero arrives as the open-weights community increasingly treats reinforcement learning as the primary lever for reasoning gains. The details that remain to be validated — activated parameter counts, context length, and independent benchmarks — will determine how the model stacks up against other open reasoning systems, but the framing alone signals where inclusionAI is placing its bets.
Sources
- Visit
Ring-Zero: Scaling Zero RL to a Trillion Parameters for Emergent Reasoning
HF Papers
More from inclusionAI
All inclusionAI releases →
inclusionAI releases Ling-3.1-flash under MIT license
A new hybrid mixture-of-experts text model arrives on Hugging Face with permissive licensing and a focus on fast inference.
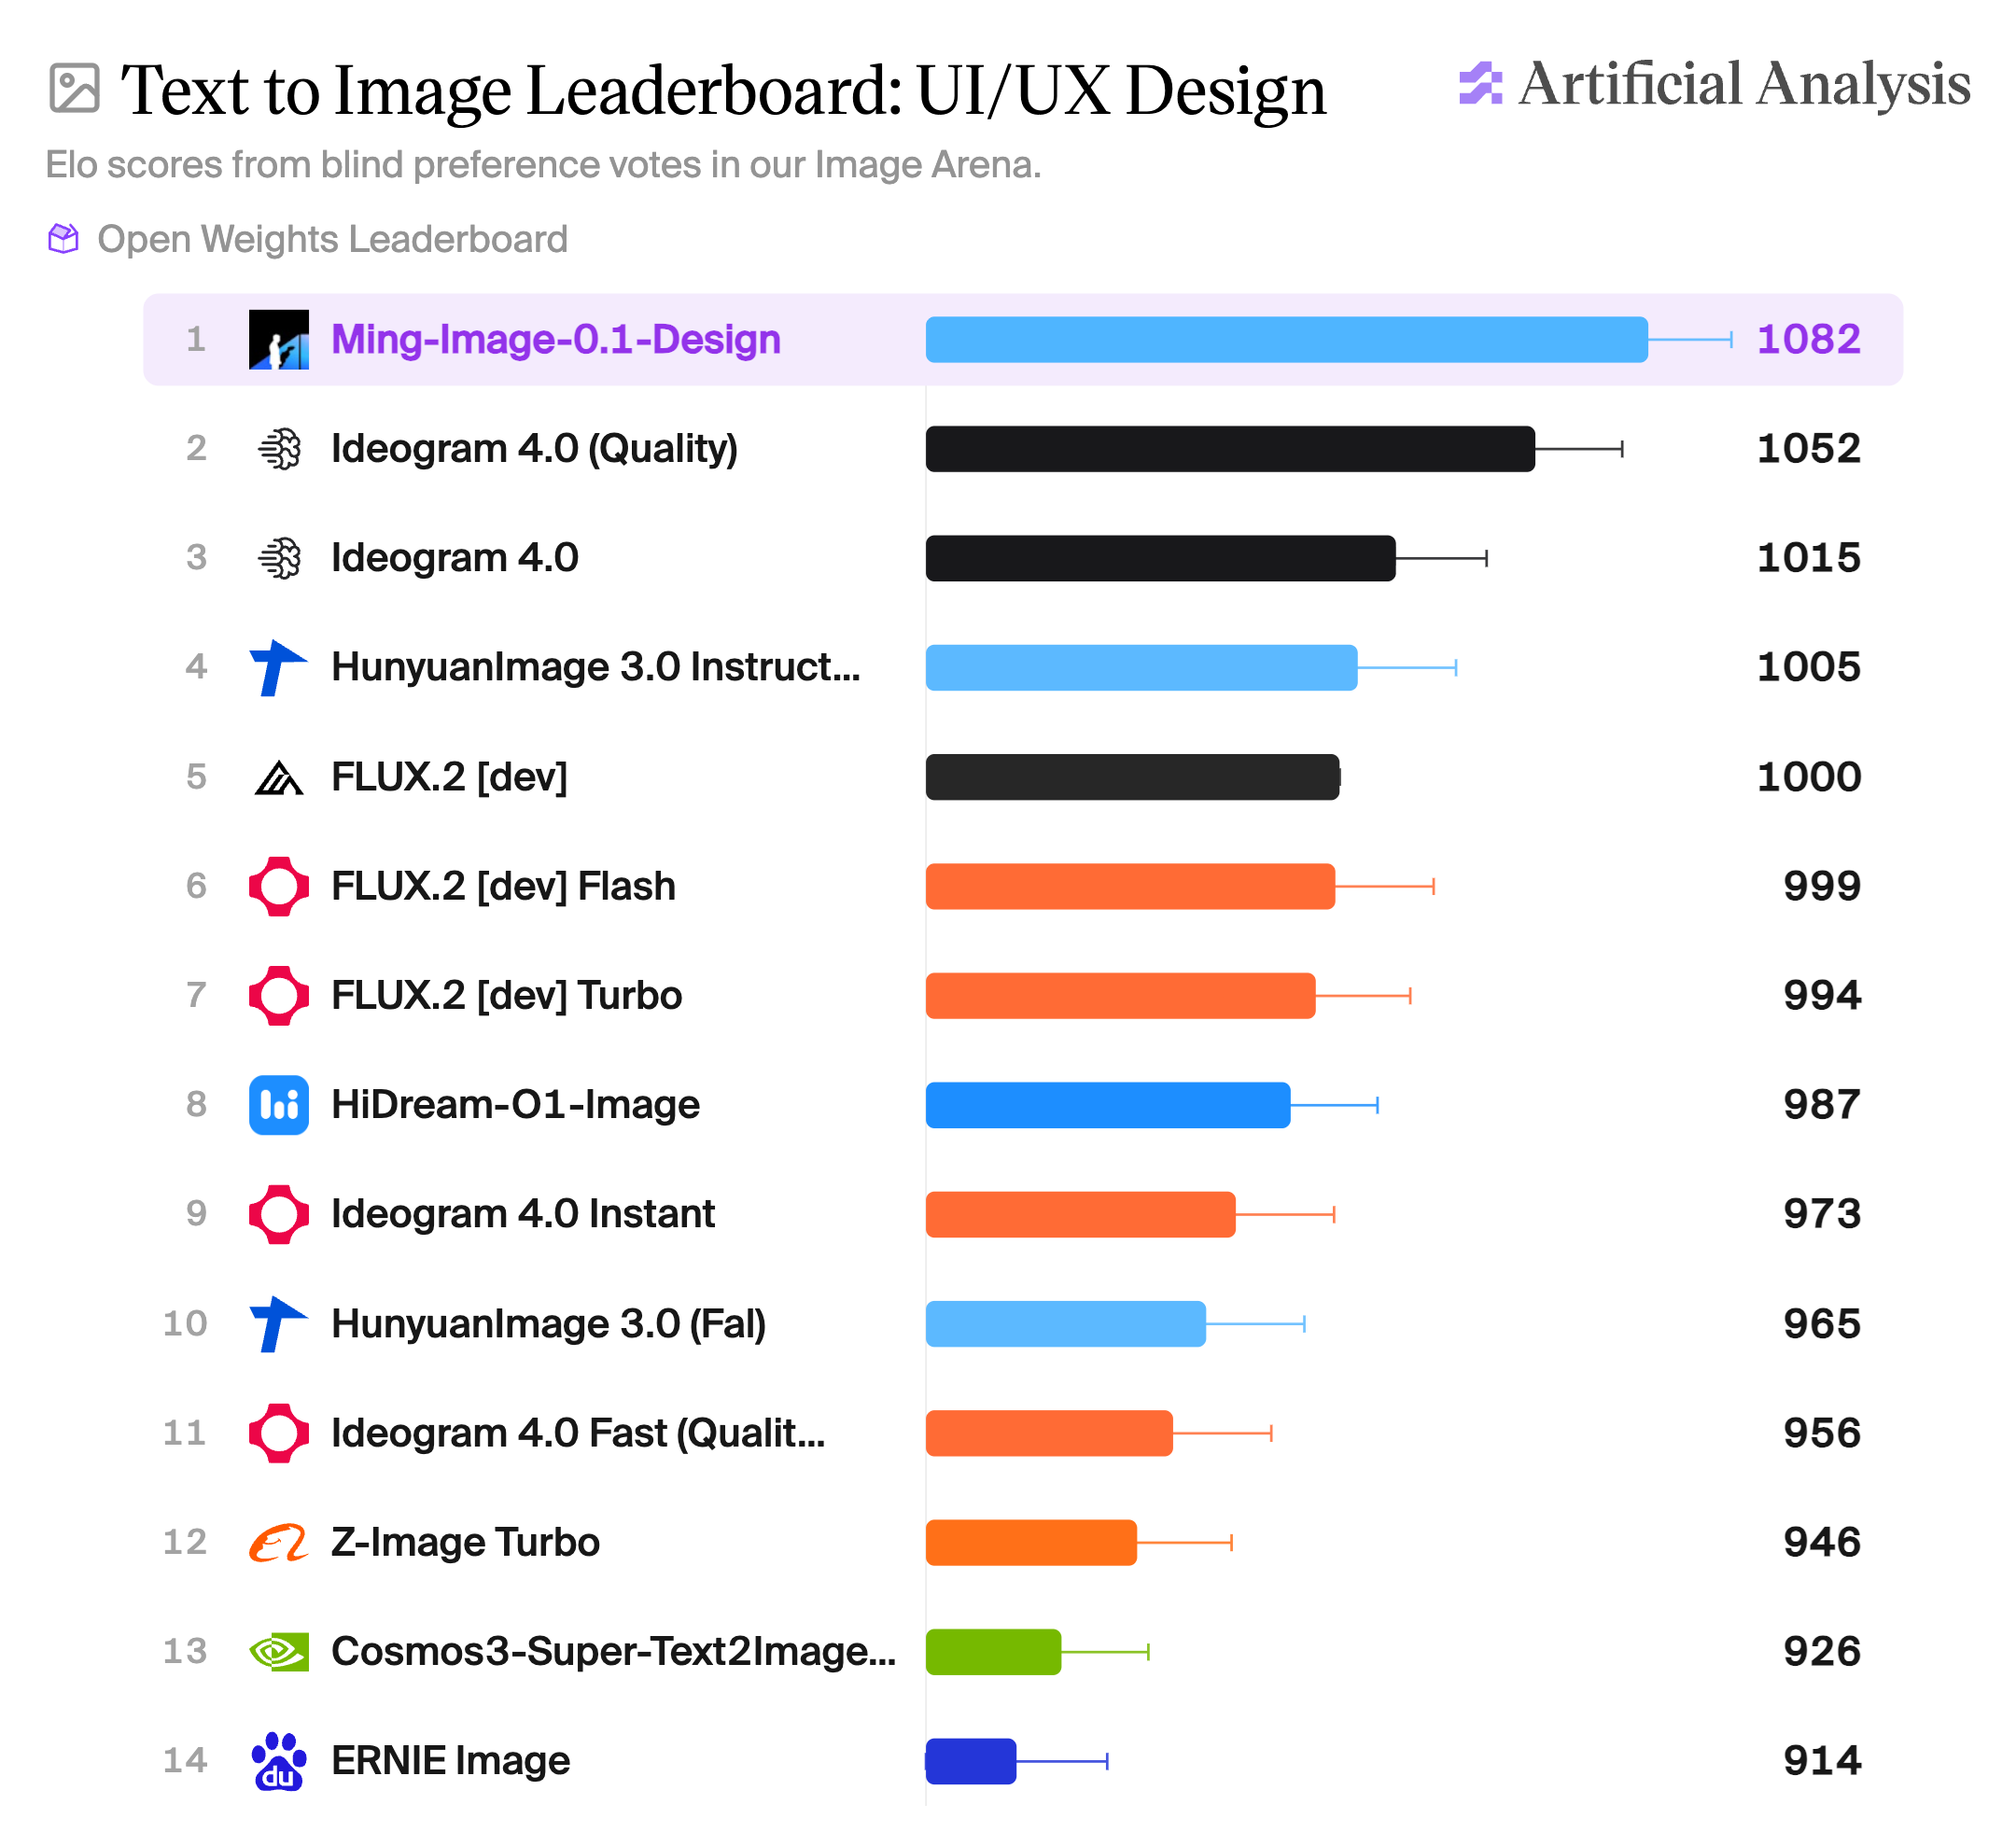
inclusionAI's Ming-Image targets graphic design
A new MIT-licensed text-to-image model leans into legible text rendering and transparent RGBA output for design work.
LLaDA-UI Brings Diffusion Decoding to GUI Agents
inclusionAI's 16.7B MoE vision-language model uses block-wise diffusion to drive graphical interface tasks.
More in Reasoning
All Reasoning →
DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
Meta's Muse Spark Open Targets Agentic Coding
The new open-weight model pairs a million-token context window with Meta's bet on long-horizon coding agents.
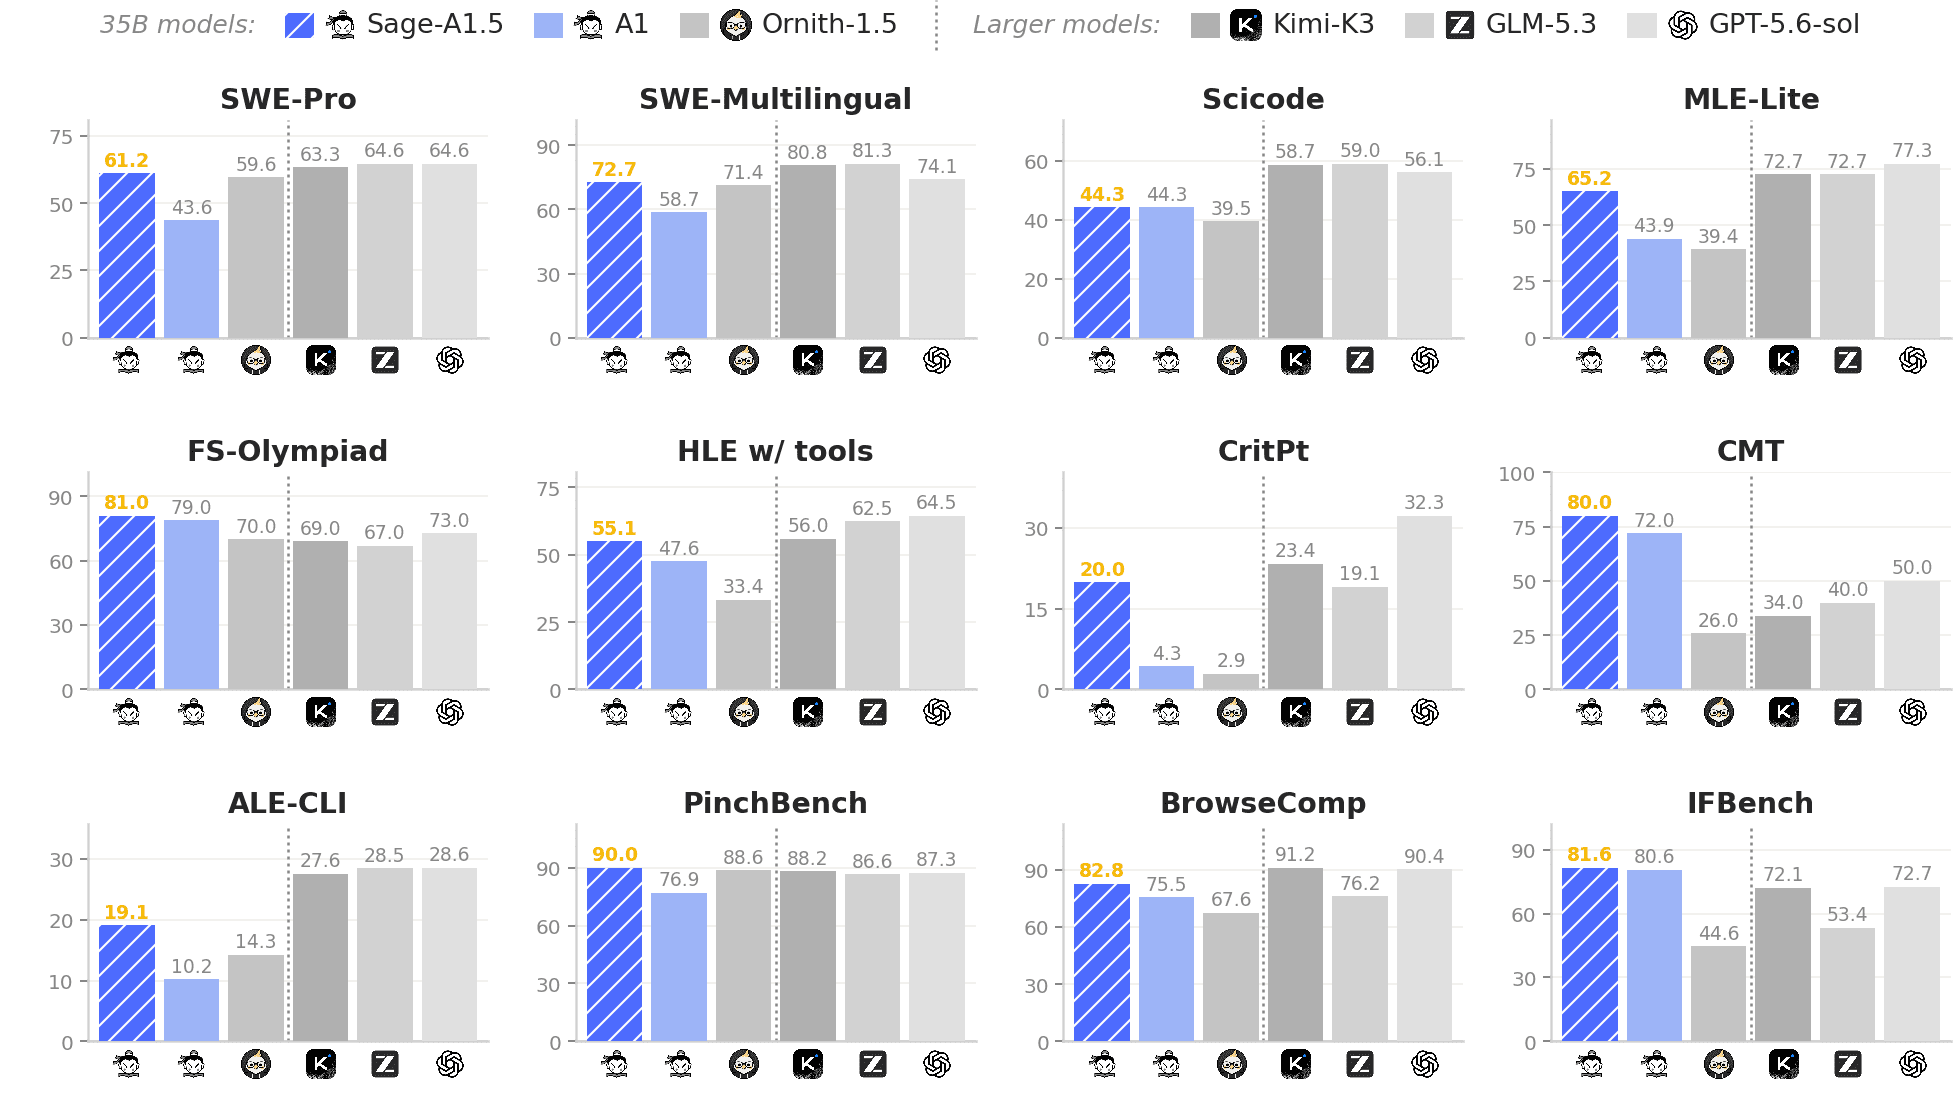
Sage-A1.5 Brings Agentic Vision to Open MoE Models
InclusionAI's new mixture-of-experts model pairs visual understanding with tool use and code, aiming at agentic workflows under an Apache 2.0 license.
0 comments
No comments yet. Be the first to weigh in.