inclusionAI ships LLaDA2.2-flash diffusion LLM
A new Apache-2.0 mixture-of-experts model that generates text through diffusion rather than left-to-right decoding.

inclusionAI has released LLaDA2.2-flash, a text language model that pairs two of the more interesting ideas in current open-weights research: a diffusion-style generation process and a mixture-of-experts (MoE) architecture. The model is available now on Hugging Face under a permissive Apache-2.0 license.
Most large language models generate text autoregressively, predicting one token after another from left to right. Diffusion language models like the LLaDA line take a different route, iteratively refining a full sequence from a noised state toward coherent output. In principle that approach can offer more parallel, controllable generation, and it has become a notable alternative thread of research alongside the dominant transformer-decoder recipe.
Why it matters
The combination here is what stands out:
- A diffusion-based generation process rather than standard autoregressive decoding
- A mixture-of-experts design, which routes tokens to a subset of parameters to keep inference costs down relative to raw model size
- An Apache-2.0 license, allowing broad commercial and research use
As a "flash" variant, the model is positioned toward faster, more efficient inference within the LLaDA2.2 family. inclusionAI has not published detailed parameter counts, context length, or benchmark figures alongside this drop, so builders will want to test it against their own workloads before drawing conclusions.
For teams tracking the open-weights space, LLaDA2.2-flash is worth a look precisely because it sits outside the mainstream. Diffusion approaches remain relatively rare in shipping open models, and a permissively licensed MoE take gives researchers and developers a concrete artifact to probe. Full details and weights are on the model's Hugging Face page.
Sources
- Visit
inclusionAI/LLaDA2.2-flash
Hugging Face
More from inclusionAI
All inclusionAI releases →
inclusionAI releases Ling-3.1-flash under MIT license
A new hybrid mixture-of-experts text model arrives on Hugging Face with permissive licensing and a focus on fast inference.
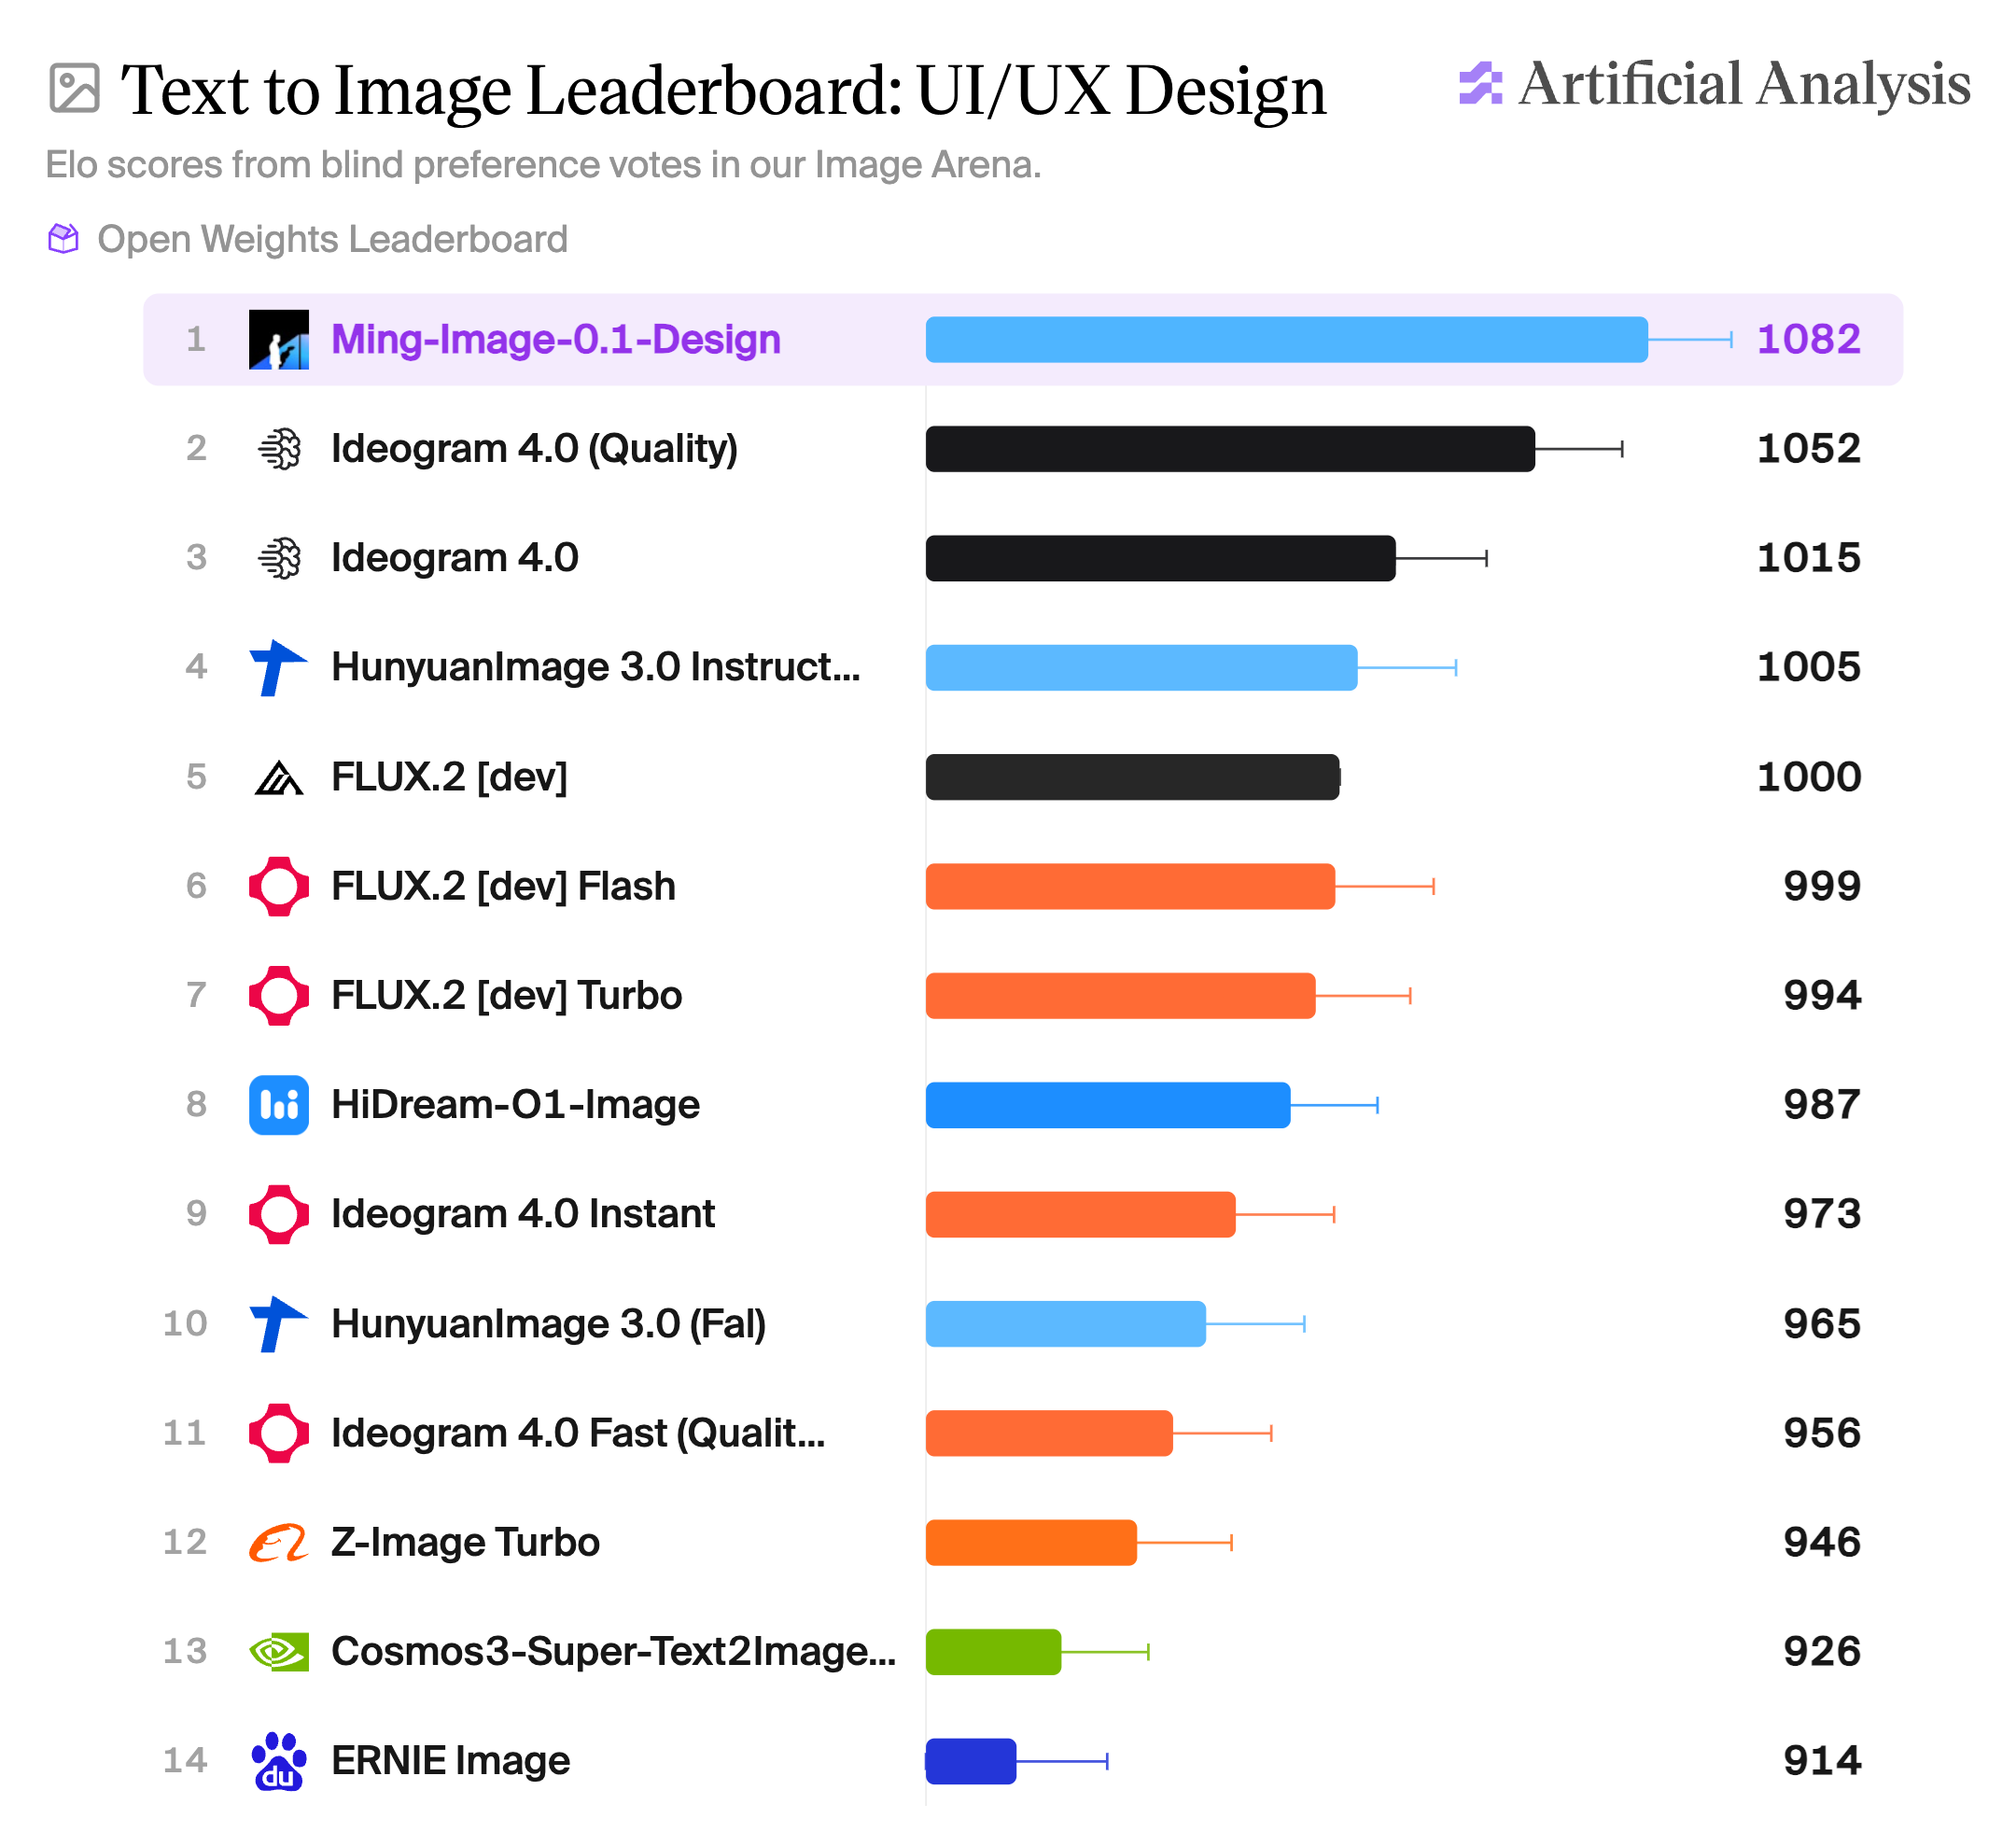
inclusionAI's Ming-Image targets graphic design
A new MIT-licensed text-to-image model leans into legible text rendering and transparent RGBA output for design work.
LLaDA-UI Brings Diffusion Decoding to GUI Agents
inclusionAI's 16.7B MoE vision-language model uses block-wise diffusion to drive graphical interface tasks.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.