LLaDA2.0-Uni: A Unified MoE for Vision Tasks
The new open-source model from inclusionAI uses a Mixture-of-Experts architecture to handle multiple vision tasks in a single, diffusion-based system.
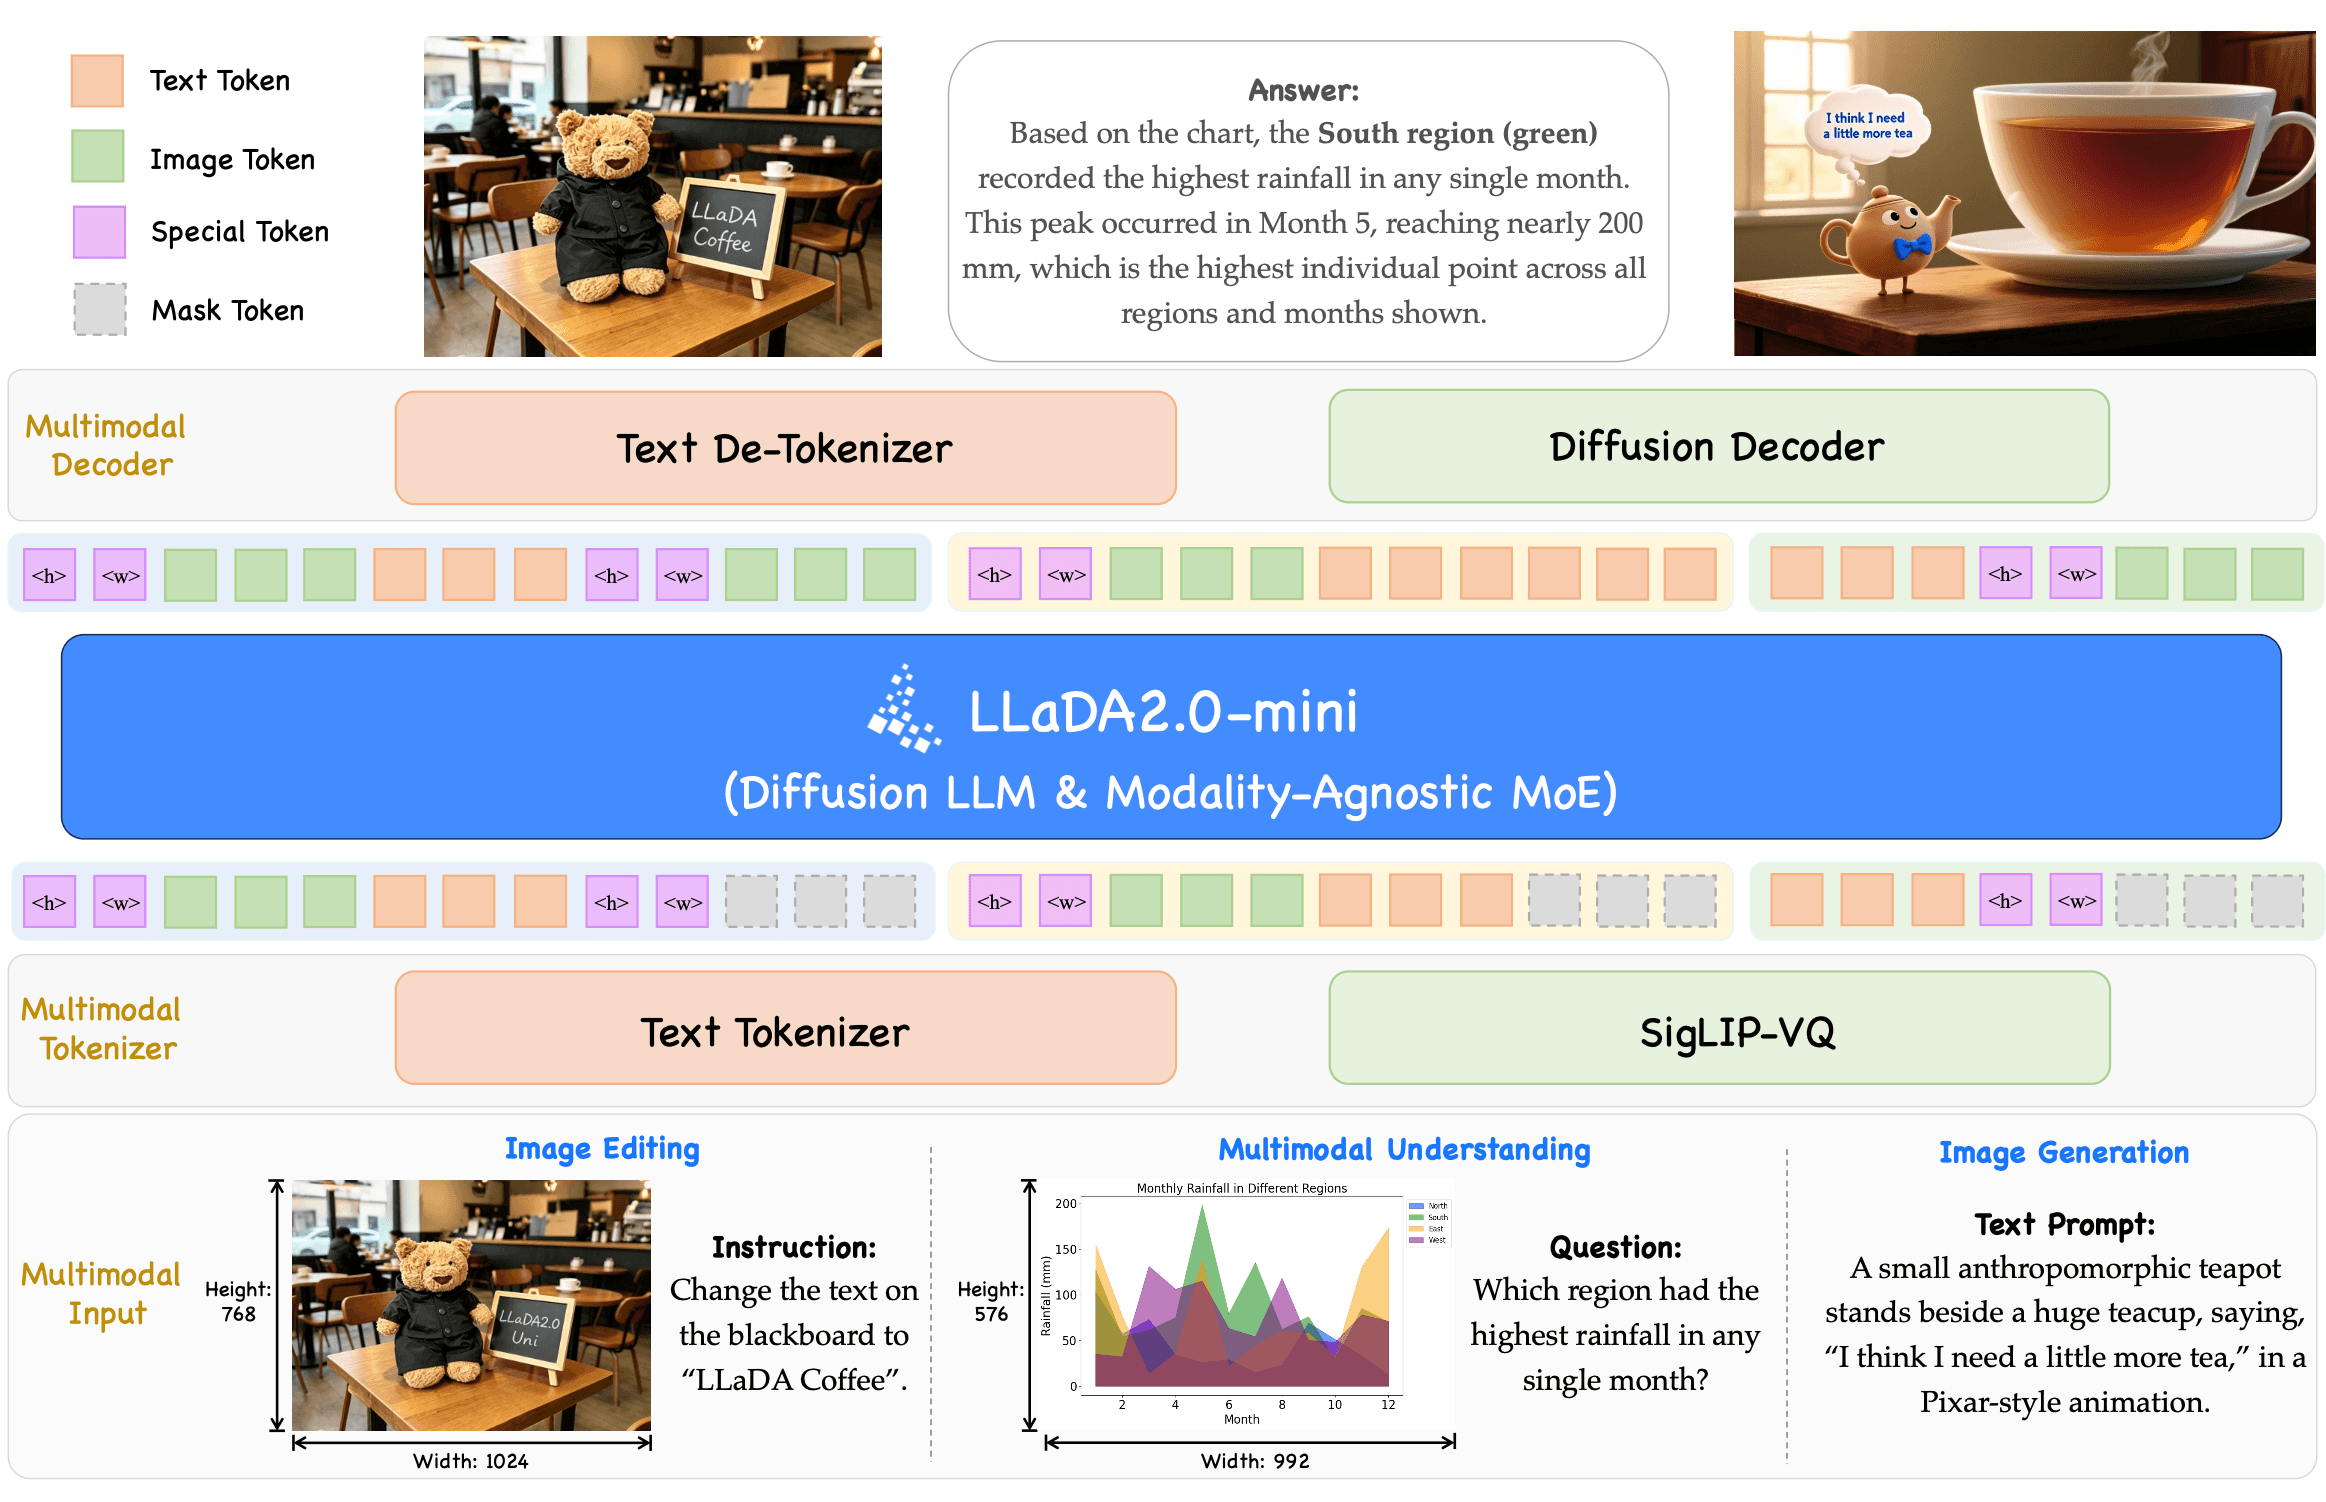
AI research group inclusionAI has released LLaDA2.0-Uni, a new open-source model aimed at unifying a range of visual AI tasks. Released under a permissive Apache 2.0 license, the model introduces a novel architecture for handling complex image-related operations within a single framework.
The core of LLaDA2.0-Uni is its use of a diffusion-based, Mixture of Experts (MoE) architecture. This design choice is significant because it allows the model to efficiently manage different tasks without needing to deploy separate, specialized models. Instead of chaining together distinct systems for understanding, creating, and modifying images, LLaDA2.0-Uni integrates these functions into one coherent system.
A Unified Approach
The model's key feature is its versatility. LLaDA2.0-Uni is designed to perform three primary categories of visual tasks:
- Image Understanding: Analyzing and interpreting the content of an image.
- Text-to-Image Generation: Creating new images from textual descriptions.
- Image Editing: Modifying existing images based on instructions.
This unified capability represents a step toward more consolidated and flexible multimodal systems. By combining these functions, developers can build more streamlined applications that require a mix of generative and analytical vision. The complete model is available on Hugging Face for researchers and developers to explore.
Sources
- Visit
inclusionAI/LLaDA2.0-Uni
Hugging Face
More from inclusionAI
All inclusionAI releases →
inclusionAI releases Ling-3.1-flash under MIT license
A new hybrid mixture-of-experts text model arrives on Hugging Face with permissive licensing and a focus on fast inference.
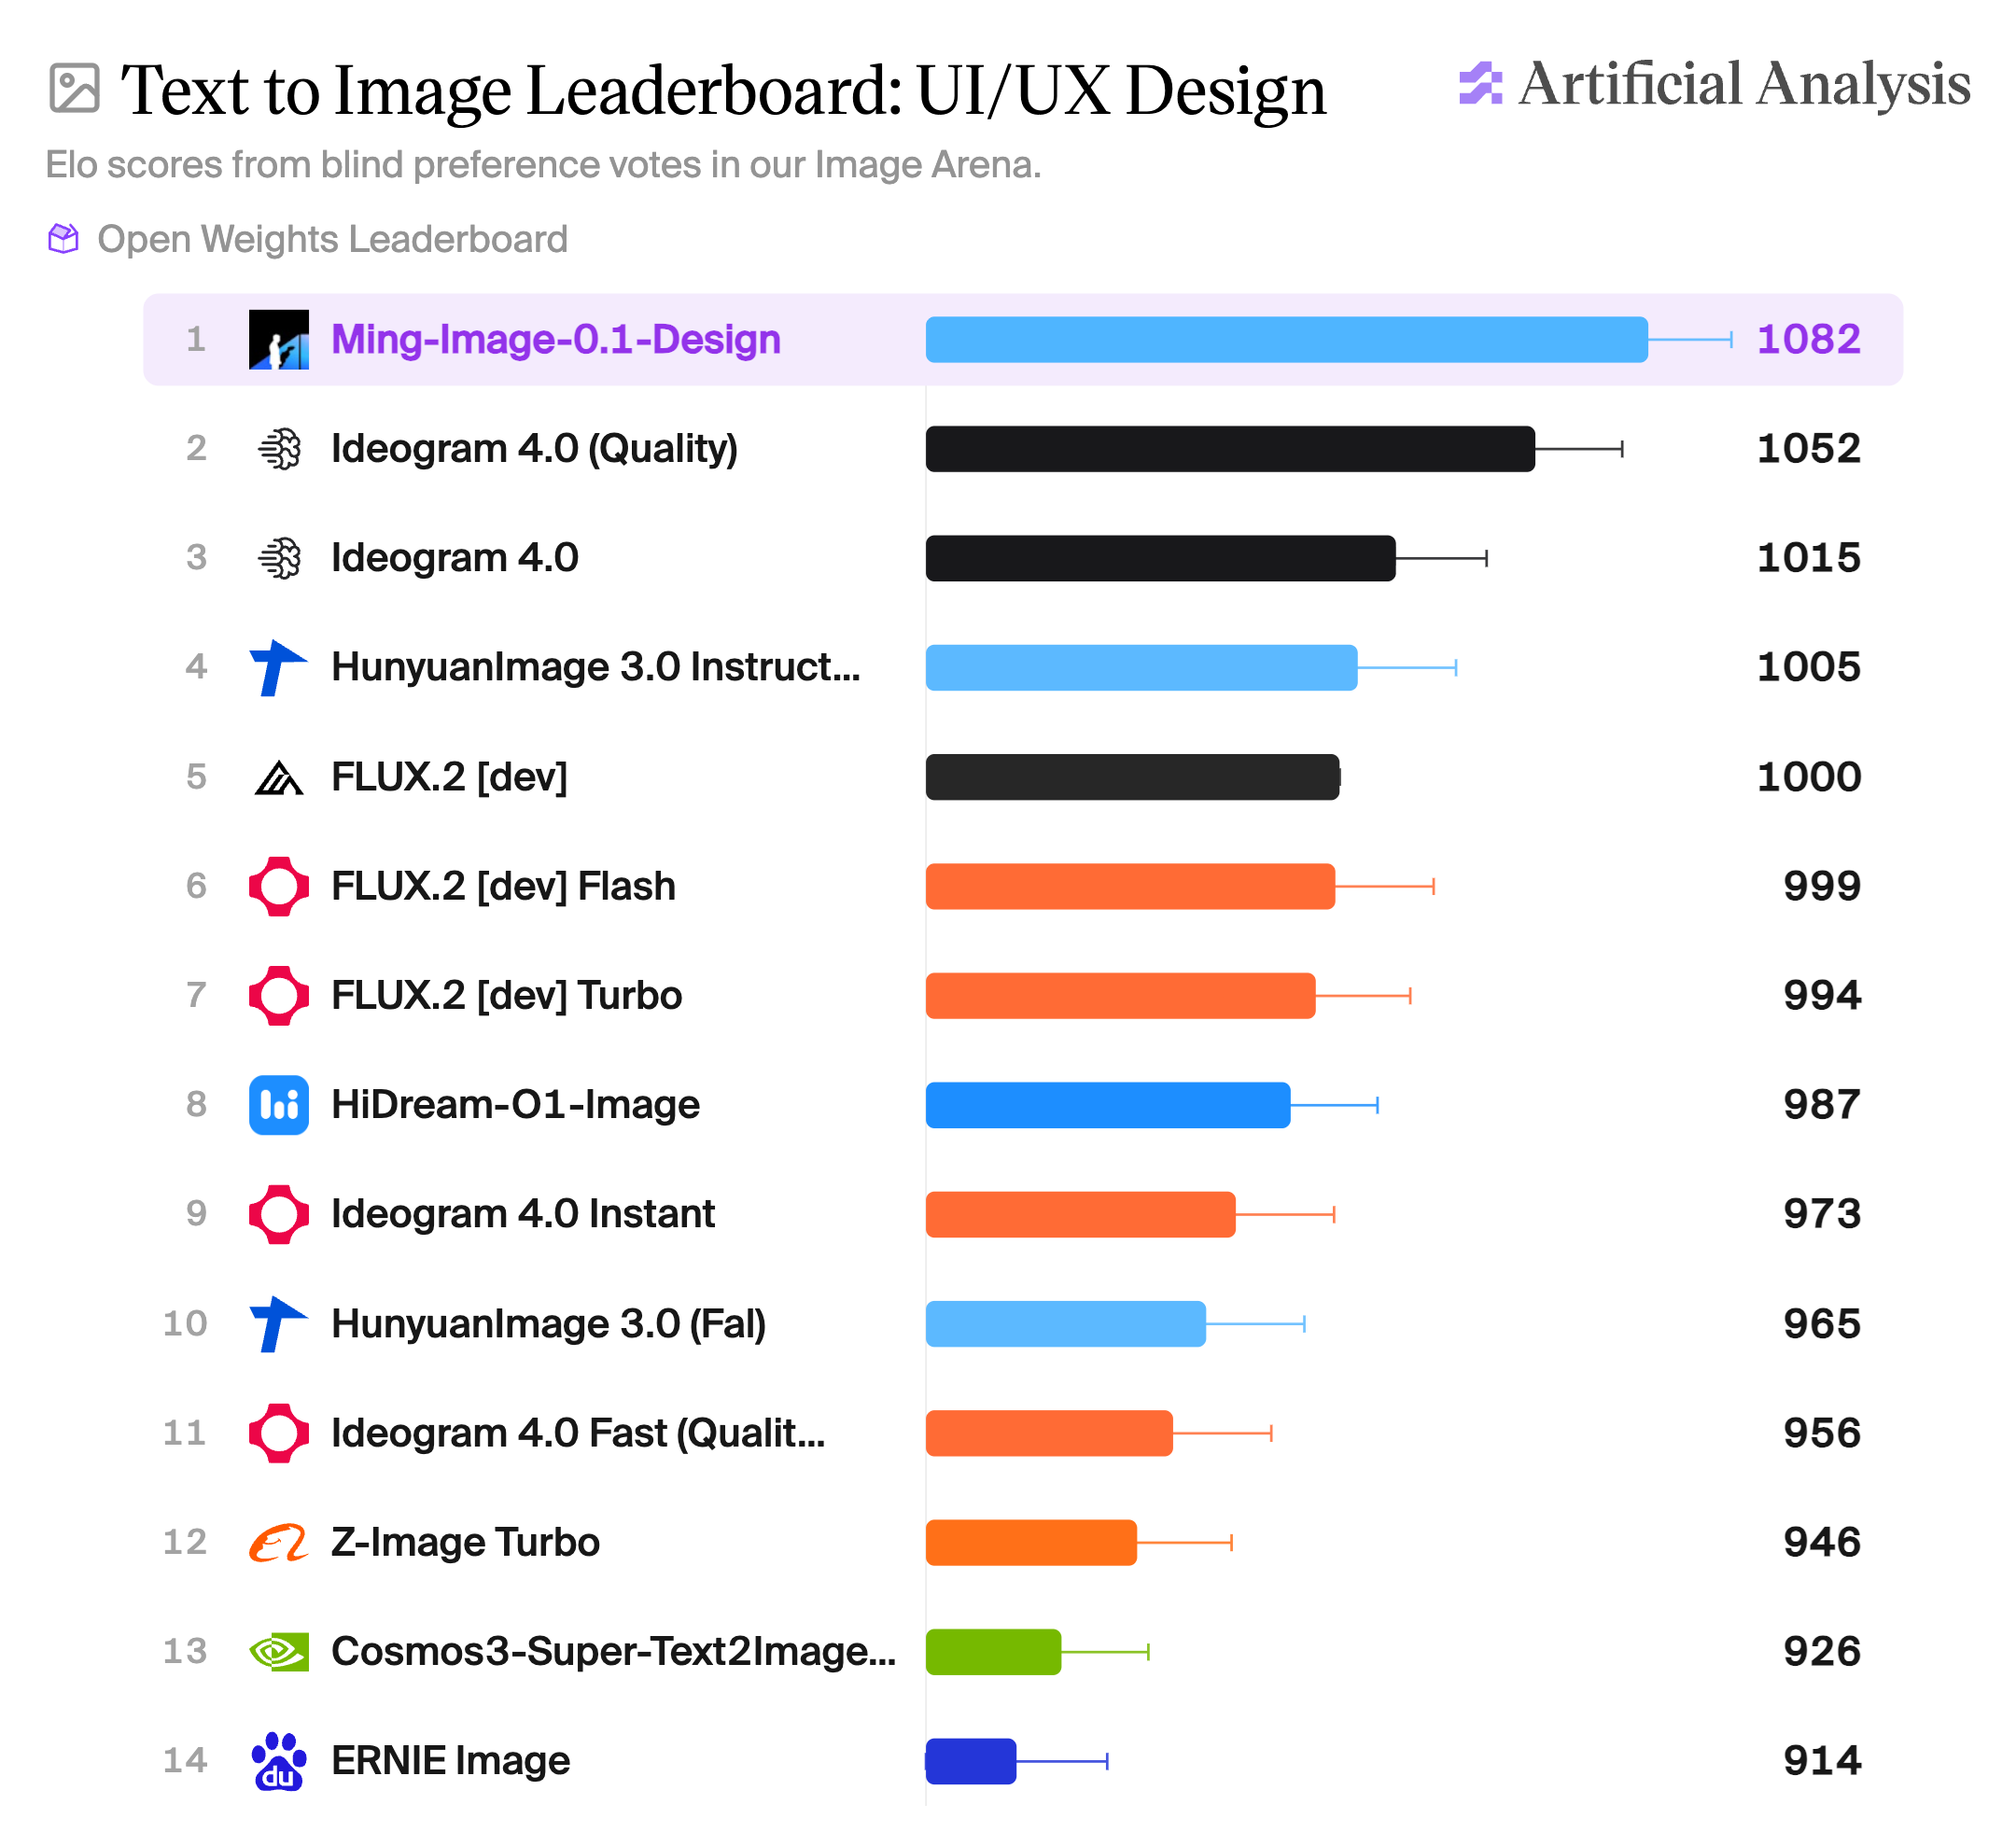
inclusionAI's Ming-Image targets graphic design
A new MIT-licensed text-to-image model leans into legible text rendering and transparent RGBA output for design work.
LLaDA-UI Brings Diffusion Decoding to GUI Agents
inclusionAI's 16.7B MoE vision-language model uses block-wise diffusion to drive graphical interface tasks.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.