Xiaomi Releases MiMo Model for Speech Recognition
The new open-source model from the Chinese tech giant offers automatic speech recognition for Mandarin, Cantonese, and English under a permissive MIT license.

Chinese technology company Xiaomi has released MiMo-V2.5-ASR, a new model for automatic speech recognition (ASR) available to the open-source community. The model is designed to perform speech-to-text tasks in three languages: Mandarin Chinese, English, and Cantonese.
While Xiaomi has not provided extensive details on the model's architecture or training dataset, its focused multilingual capability makes it a potentially valuable tool for developers building applications for these specific language markets. The inclusion of Cantonese is particularly notable, as it is often less supported than Mandarin in large-scale ASR systems.
Permissive and Practical
The release is significant as it comes from a major global electronics manufacturer, signaling a continued interest from large corporations in contributing to the open AI ecosystem. The model's utility is enhanced by its licensing terms.
Xiaomi has released MiMo-V2.5-ASR under the MIT license, one of the most permissive open-source licenses available. This allows for unrestricted use, modification, and distribution, including for commercial purposes, removing a common barrier to adoption for many businesses and independent developers. The model and its usage instructions are available on its Hugging Face repository.
Sources
- Visit
XiaomiMiMo/MiMo-V2.5-ASR
Hugging Face
More from Xiaomi
All Xiaomi releases →Xiaomi's MiMo-V2.6 bets on RL for self-improvement
The omni-modal model family leans on reinforcement learning to push reasoning without endless new supervised data.
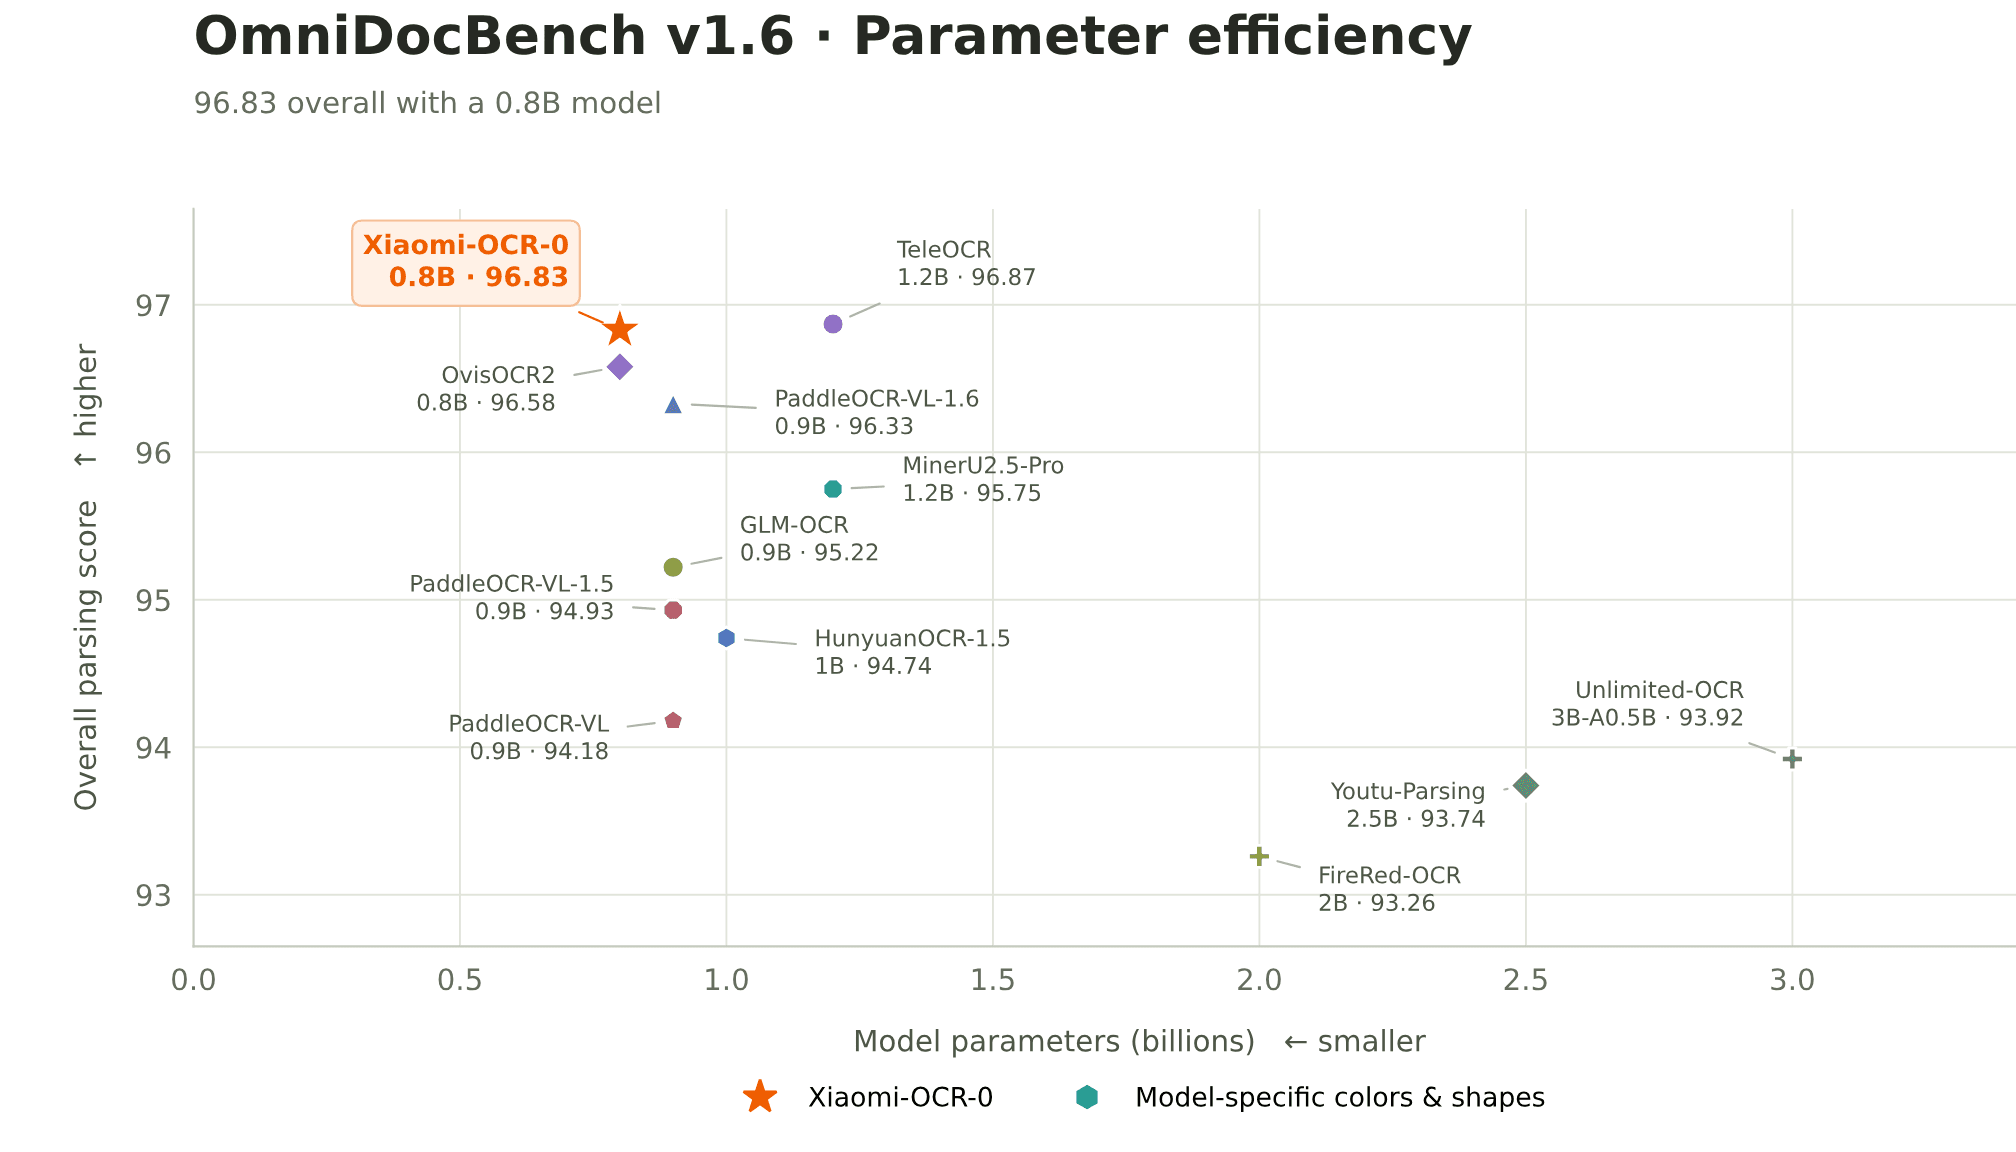
Xiaomi Enters Document OCR With New Vision Model
The company's research arm releases Xiaomi-OCR-0, a document-parsing vision-language model built on a Qwen3.5 backbone.

Xiaomi distills MiMo V2.6 into a 9B model
The new MiMo-V2.6-Distill-Qwen-9B targets agentic workloads, coding, and tool use in a size that fits on modest hardware.
More in Speech → Text
All Speech → Text →IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
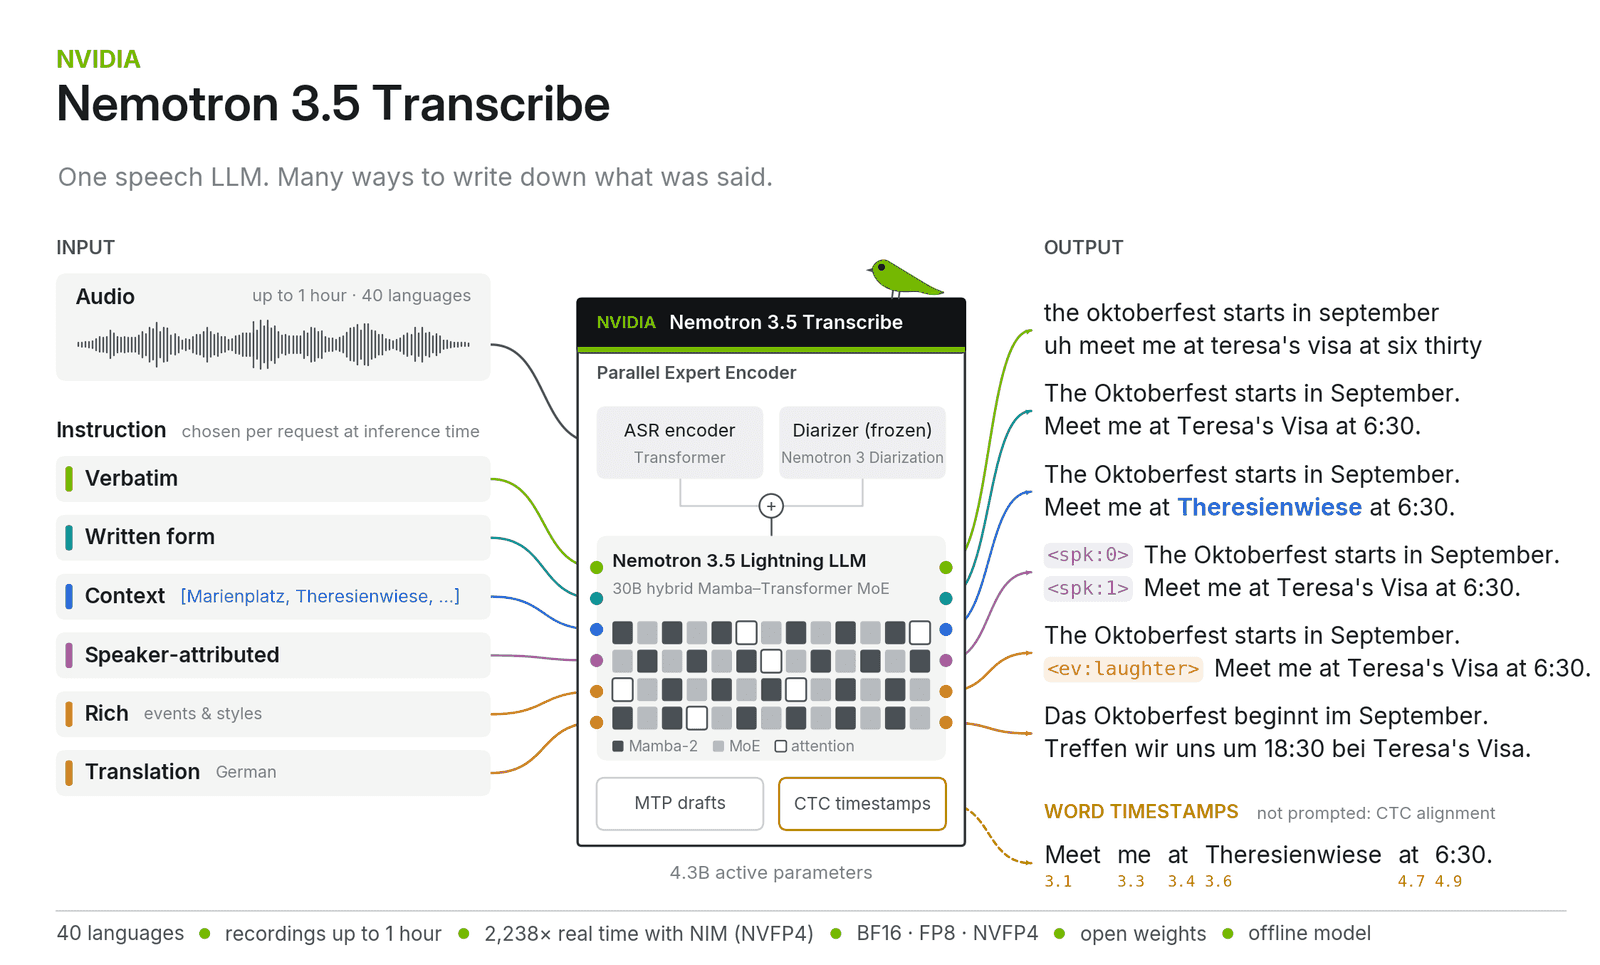
NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR
A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.
0 comments
No comments yet. Be the first to weigh in.